Many students often start to study as the exam is approaching. Time is very valuable to these students, and for them, one extra hour of study may mean 3 points more on the test score. If you are one of these students, then Databricks Certified Data Engineer Professional Exam exam tests are your best choice. Because students often purchase materials from the Internet, there is a problem that they need transport time, especially for those students who live in remote areas. When the materials arrive, they may just have a little time to read them before the exam. However, with Databricks-Certified-Data-Engineer-Professional Exam Questions, you will never encounter such problems, because our materials are distributed to customers through emails. After you have successfully paid, you can immediately receive Databricks-Certified-Data-Engineer-Professional test guide from our customer service staff, and then you can start learning immediately.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Set up alerts and notifications - Track data lineage and metrics |
| Topic 2: Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation - Manage cross-platform data access |
| Topic 3: Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules - Enforce data quality standards - Implement schema evolution and management |
| Topic 4: Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming - Ingest data from diverse sources - Handle incremental and batch data loads |
| Topic 5: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Use Databricks-specific libraries and APIs - Implement complex data processing logic |
| Topic 6: Ensuring Data Security and Compliance | 10% | - Implement access control and permissions - Ensure data privacy and compliance - Secure data at rest and in transit |
| Topic 7: Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Apply cost management best practices - Optimize compute and storage resources |
| Topic 8: Data Governance | 7% | - Manage data assets and metadata - Use Unity Catalog for governance - Enforce data policies and standards |
| Topic 9: Data Modelling | 6% | - Design Medallion Architecture - Implement dimensional and relational models - Optimize table design and partitioning |
| Topic 10: Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Implement CI/CD and DevOps practices - Deploy using Asset Bundles, CLI, and APIs |
>> Test Databricks Databricks-Certified-Data-Engineer-Professional Practice <<
Our Databricks-Certified-Data-Engineer-Professional exam torrent is compiled by first-rank experts with a good command of professional knowledge, and our experts adept at this exam practice materials area over ten years' long, so they are terrible clever about this thing. They exert great effort to boost the quality and accuracy of our Databricks-Certified-Data-Engineer-Professional study tools and is willing to work hard as well as willing to do their part in this area. Our Databricks-Certified-Data-Engineer-Professional study tools galvanize exam candidates into taking actions efficiently. We are sure you will be splendid and get your desirable outcomes by our Databricks-Certified-Data-Engineer-Professional exam guide. If your mind has made up then our Databricks-Certified-Data-Engineer-Professional study tools will not let you down.
NEW QUESTION # 141
A Data Engineer is building a fraud detection pipeline that calls out to Open AI, via a Python library, and needs to include an access token when using the API. Which Databricks CLI command should the Data Engineer use to create the secret?
Answer: A
Explanation:
The Databricks CLI command databricks secrets put-secret <scope> <key> is used to securely store sensitive values such as API access tokens in a secret scope. The secret can then be retrieved at runtime using dbutils.secrets.get(scope, key), ensuring credentials are not hard- coded and remain protected.
NEW QUESTION # 142
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity.
Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
Answer: C
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html
NEW QUESTION # 143
A Delta Lake table representing metadata about content from user has the following schema:
Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: D
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
NEW QUESTION # 144
A Delta Lake table was created with the below query:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from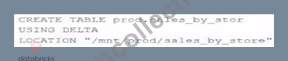
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: E
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 145
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from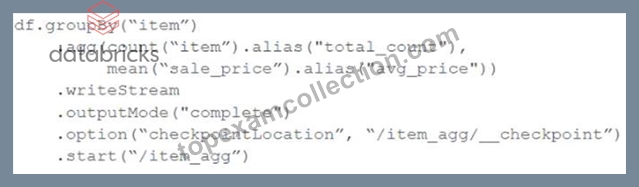
Proposed query: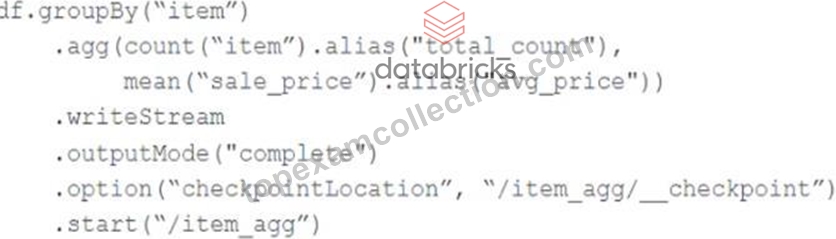
Proposed query:
.start("/item_agg")
Which step must also be completed to put the proposed query into production?
Answer: D
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 146
......
You can know what knowledge points you do not master. By the report from our Databricks-Certified-Data-Engineer-Professional study questions. Then it will be very easy for you to make your own learning plan. We believe that the learning plan based on the report of our Databricks-Certified-Data-Engineer-Professional preparation exam will be very useful for you. So if you buy our Databricks-Certified-Data-Engineer-Professional Practice Engine, it will help you pass your exam and get the certification in a short time, and you will find that our study materials are good value for money.
Databricks-Certified-Data-Engineer-Professional Practice Engine: https://www.topexamcollection.com/Databricks-Certified-Data-Engineer-Professional-vce-collection.html