Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung & Databricks-Certified-Professional-Data-Engineer Testengine

2026 Die neuesten It-Pruefung Databricks-Certified-Professional-Data-Engineer PDF-Versionen Prüfungsfragen und Databricks-Certified-Professional-Data-Engineer Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1wjtWm3TO6PSxdu6A_gB25Ohy1z2HI-t9
Viele IT-Leute sind sich einig, dass Databricks Databricks-Certified-Professional-Data-Engineer Zertifikat ein Sprungbrett zu dem Höhepunkt der IT-Branche ist. Deshalb kümmern sich viele IT-Experten um die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads
- Implement Unity Catalog governance and access control
- Cost optimization and performance tuning
|
| Topic 2: Data Ingestion and Transformation | - Handle batch and streaming data pipelines
- Ingest data using Apache Spark and Databricks
- Transform and clean datasets using Spark SQL and DataFrame APIs
|
| Topic 3: Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance
- Build and manage workflows using Databricks Jobs
- Automate ETL pipelines and scheduling
|
| Topic 4: Data Modeling and Storage | - Design scalable data lakehouse architectures
- Schema evolution and data partitioning strategies
- Delta Lake table design and optimization
|
>> Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung <<
Databricks-Certified-Professional-Data-Engineer Testengine & Databricks-Certified-Professional-Data-Engineer Examsfragen
Unser It-Pruefung bietet den Kandidaten nicht nur gute Produktem sondern auch vollständigen Service. Wenn Sie unsere Produkte benutzen, können Sie einen einjährigen kostenlosen Update-Service genießen. Wir benachrichtigen den Kandidaten in erster Zeit die neuen Prüfungsmaterialien zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierung mit dem besten Service.
Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Prüfungsfragen mit Lösungen (Q116-Q121):
116. Frage
Which of the following data workloads will utilize a Silver table as its source?
- A. A job that ingests raw data from a streaming source into the Lakehouse
- B. A job that cleans data by removing malformatted records
- C. A job that queries aggregated data that already feeds into a dashboard
- D. A job that aggregates cleaned data to create standard summary statistics
- E. A job that enriches data by parsing its timestamps into a human-readable format
Antwort: D
117. Frage
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
- A. dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date")
- B. date = dbutils.notebooks.getParam("date")
- C. date = spark.conf.get("date")
- D. import sys
date = sys.argv[1] - E. input_dict = input()
date= input_dict["date"]
Antwort: A
Begründung:
Explanation
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter1. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter. For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
The other options are not correct, because:
Option A is incorrect because spark.conf.get("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The spark.conf API is used to get or set Spark configuration properties, not notebook parameters2.
Option B is incorrect because input() is not a valid way to get a parameter passed through the Databricks Jobs API. The input() function is used to get user input from the standard input stream, not from the API request3.
Option C is incorrect because sys.argv1 is not a valid way to get a parameter passed through the Databricks Jobs API. The sys.argv list is used to get the command-line arguments passed to a Python script, not to a notebook4.
Option D is incorrect because dbutils.notebooks.getParam("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The dbutils.notebooks API is used to get or set notebook parameters when running a notebook as a job or as a subnotebook, not when passing parameters through the API5.
References: Widgets, Spark Configuration, input(), sys.argv, Notebooks
118. Frage
Which of the statements is correct when choosing between lakehouse and Datawarehouse?
- A. Traditional Data warehouses are the preferred choice if we need to support ACID, Lakehouse does not support ACID.
- B. Traditional Data warehouses can serve low query latency with high reliability for BI workloads
- C. Traditional Data warehouses have special indexes which are optimized for Machine learning
- D. Lakehouse replaces the current dependency on data lakes and data warehouses uses an open standard storage format and supports low latency BI workloads.
- E. SQL support is only available for Traditional Datawarehouse's, Lakehouses support Python and Scala
Antwort: D
Begründung:
Explanation
The lakehouse replaces the current dependency on data lakes and data warehouses for modern data companies that desire:
* Open, direct access to data stored in standard data formats.
* Indexing protocols optimized for machine learning and data science.
* Low query latency and high reliability for BI and advanced analytics.
119. Frage
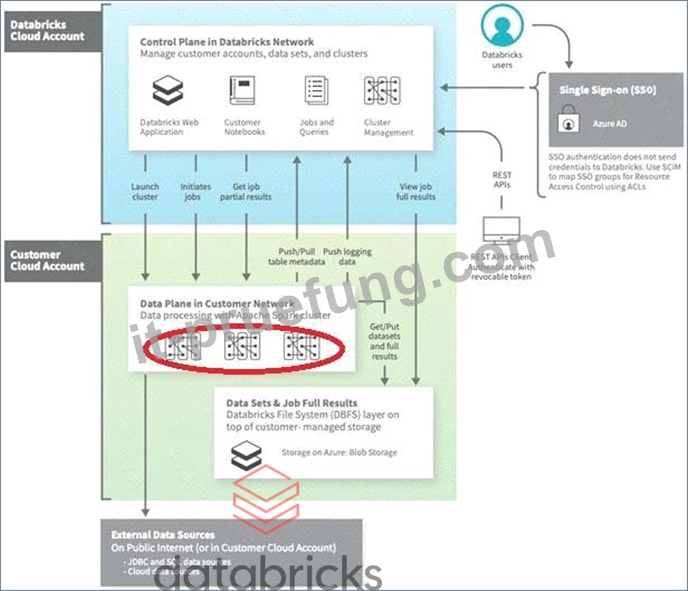
Which of the following locations hosts the driver and worker nodes of a Databricks-managed clus-ter?
- A. Databricks web application
- B. Control plane
- C. JDBC data source
- D. Databricks Filesystem
- E. Data plane
Antwort: E
Begründung:
Explanation
The answer is Data Plane, which is where compute(all-purpose, Job Cluster, DLT) are stored this is generally a customer cloud account, there is one exception SQL Warehouses, currently there are 3 types of SQL Warehouse compute available(classic, pro, serverless), in classic and pro compute is located in customer cloud account but serverless computed is located in Databricks cloud account.
Diagram, timeline Description automatically generated
120. Frage
The following code has been migrated to a Databricks notebook from a legacy workload:
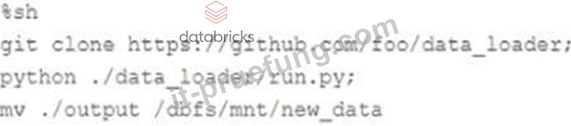
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- B. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- C. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- D. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- E. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
Antwort: B
Begründung:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
121. Frage
......
Die Prüfungsmaterialien von Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von unserem It-Pruefung existieren in der Form von PDF und Stimulationssoftware, in der alle Testaufgaben und Antworten von Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierung enthalten sind. Inhalte dieser Lehrbücher sind umfassend und zuversichtlich. Hoffentlich kann It-Pruefung Ihr bester Hilfer bei der Vorbereitung der Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung werden. Falls Sie leider die Databricks-Certified-Professional-Data-Engineer Prüfung nicht bestehen, bitte machen Sie keine Sorge, denn wir werden alle Ihre Einkaufsgebühren bedingungslos zurückgeben.
Databricks-Certified-Professional-Data-Engineer Testengine: https://www.it-pruefung.com/Databricks-Certified-Professional-Data-Engineer.html
- Aktuelle Databricks Databricks-Certified-Professional-Data-Engineer Prüfung pdf Torrent für Databricks-Certified-Professional-Data-Engineer Examen Erfolg prep ♣ Sie müssen nur zu ☀ www.deutschpruefung.com ️☀️ gehen um nach kostenloser Download von ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ zu suchen 🎼Databricks-Certified-Professional-Data-Engineer Quizfragen Und Antworten
- Databricks-Certified-Professional-Data-Engineer Prüfungs 🥟 Databricks-Certified-Professional-Data-Engineer Quizfragen Und Antworten 🔳 Databricks-Certified-Professional-Data-Engineer Prüfungsfrage 🎪 Sie müssen nur zu 「 www.itzert.com 」 gehen um nach kostenloser Download von ➤ Databricks-Certified-Professional-Data-Engineer ⮘ zu suchen 🌿Databricks-Certified-Professional-Data-Engineer Unterlage
- Databricks-Certified-Professional-Data-Engineer Prüfungsaufgaben 📁 Databricks-Certified-Professional-Data-Engineer Demotesten 🪕 Databricks-Certified-Professional-Data-Engineer Unterlage 🔄 Öffnen Sie die Website ➠ www.zertfragen.com 🠰 Suchen Sie ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ Kostenloser Download 😸Databricks-Certified-Professional-Data-Engineer Zertifikatsdemo
- Databricks-Certified-Professional-Data-Engineer Online Prüfung 📄 Databricks-Certified-Professional-Data-Engineer Demotesten 🔌 Databricks-Certified-Professional-Data-Engineer PDF Testsoftware 🍃 Sie müssen nur zu ▶ www.itzert.com ◀ gehen um nach kostenloser Download von ▶ Databricks-Certified-Professional-Data-Engineer ◀ zu suchen 😚Databricks-Certified-Professional-Data-Engineer Lernressourcen
- Aktuelle Databricks Databricks-Certified-Professional-Data-Engineer Prüfung pdf Torrent für Databricks-Certified-Professional-Data-Engineer Examen Erfolg prep ➖ Sie müssen nur zu ▷ www.pruefungfrage.de ◁ gehen um nach kostenloser Download von ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ zu suchen 🍈Databricks-Certified-Professional-Data-Engineer Lernressourcen
- Databricks Databricks-Certified-Professional-Data-Engineer Prüfung Übungen und Antworten ⏹ Suchen Sie jetzt auf ✔ www.itzert.com ️✔️ nach 「 Databricks-Certified-Professional-Data-Engineer 」 um den kostenlosen Download zu erhalten 🌃Databricks-Certified-Professional-Data-Engineer Prüfungsfrage
- Databricks-Certified-Professional-Data-Engineer Prüfungs-Guide ⌨ Databricks-Certified-Professional-Data-Engineer Lernhilfe ⚖ Databricks-Certified-Professional-Data-Engineer Online Praxisprüfung 👰 Öffnen Sie die Webseite ☀ www.zertpruefung.de ️☀️ und suchen Sie nach kostenloser Download von 「 Databricks-Certified-Professional-Data-Engineer 」 🕝Databricks-Certified-Professional-Data-Engineer Prüfungs-Guide
- Databricks-Certified-Professional-Data-Engineer Demotesten ❓ Databricks-Certified-Professional-Data-Engineer PDF Testsoftware 🧿 Databricks-Certified-Professional-Data-Engineer Testking 🛀 URL kopieren [ www.itzert.com ] Öffnen und suchen Sie 【 Databricks-Certified-Professional-Data-Engineer 】 Kostenloser Download 😐Databricks-Certified-Professional-Data-Engineer Quizfragen Und Antworten
- Databricks-Certified-Professional-Data-Engineer Unterlage 🧭 Databricks-Certified-Professional-Data-Engineer Prüfungsaufgaben 🤿 Databricks-Certified-Professional-Data-Engineer Prüfungsfrage 🧄 Suchen Sie jetzt auf “ www.zertpruefung.ch ” nach 《 Databricks-Certified-Professional-Data-Engineer 》 um den kostenlosen Download zu erhalten 🌉Databricks-Certified-Professional-Data-Engineer Prüfungs-Guide
- Databricks-Certified-Professional-Data-Engineer Prüfungsfrage 🪁 Databricks-Certified-Professional-Data-Engineer PDF Testsoftware 🐚 Databricks-Certified-Professional-Data-Engineer Unterlage ☁ Suchen Sie auf der Webseite ➡ www.itzert.com ️⬅️ nach ▶ Databricks-Certified-Professional-Data-Engineer ◀ und laden Sie es kostenlos herunter ↖Databricks-Certified-Professional-Data-Engineer Prüfungsfrage
- Databricks-Certified-Professional-Data-Engineer Prüfungsfragen, Databricks-Certified-Professional-Data-Engineer Fragen und Antworten, Databricks Certified Professional Data Engineer Exam 👣 Suchen Sie auf ➽ www.itzert.com 🢪 nach kostenlosem Download von 《 Databricks-Certified-Professional-Data-Engineer 》 🧔Databricks-Certified-Professional-Data-Engineer Demotesten
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
Außerdem sind jetzt einige Teile dieser It-Pruefung Databricks-Certified-Professional-Data-Engineer Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1wjtWm3TO6PSxdu6A_gB25Ohy1z2HI-t9