BTW, DOWNLOAD part of Pass4sureCert DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1JUaFXfdtgRbfAnAyQ4fzmO7VARsYj5PI
Pass4sureCert offers an extensive collection of DP-750 practice questions in PDF format. This Microsoft DP-750 Exam Questions pdf file format is simple to use and can be accessed on any device, including a desktop, tablet, laptop, Mac, or smartphone. No matter where you are, you can learn on the go. The PDF version of the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions is also easily printable, allowing you to keep physical copies of the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) questions dumps with you at all times.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 4: Prepare and process data | 30-35% | - Data transformation and modeling
|
Because our Microsoft DP-750 practice test is a web-based mock test, there is no need for software installation as it works with all of the popular web browsers, including Internet Explorer, MS Edge, Firefox, Chrome, Opera, and Safari. Your preparation for the DP-750 Certification Exam will go more smoothly because our Microsoft DP-750 online practice exam precisely replicates the environment of the actual exam.
NEW QUESTION # 49
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job! that processes data continuously and fails periodically due to transient errors You need to ensure that Job! meets the following requirements
* Resumes processing from the point that Job1 failed
* Minimizes how long it takes to restart Job!
* Minimizes the costs to restart Job!
What should you do?
Answer: A
Explanation:
The correct answer is B - implement checkpointing.
A checkpoint is a durable record of the streaming job's progress written to ADLS Gen2 or DBFS after each successfully committed micro-batch. When the job restarts after a transient failure, it reads the checkpoint to find the last committed offset and resumes from that exact point - no data is reprocessed, no data is lost.
This satisfies all three requirements directly: checkpointing enables resumption from the failure point (not from the beginning), restart is fast because there's no replay overhead, and costs are minimised because no compute is wasted reprocessing records already handled.
Option A (decrease retry interval) makes the job retry sooner but doesn't control where it resumes from.
Option C (alert and manual restart) adds human latency and doesn't prevent reprocessing without a checkpoint. Option D (increase minimum nodes) reduces the likelihood of resource-related failures but increases cost and doesn't address the recovery behaviour itself.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 50
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.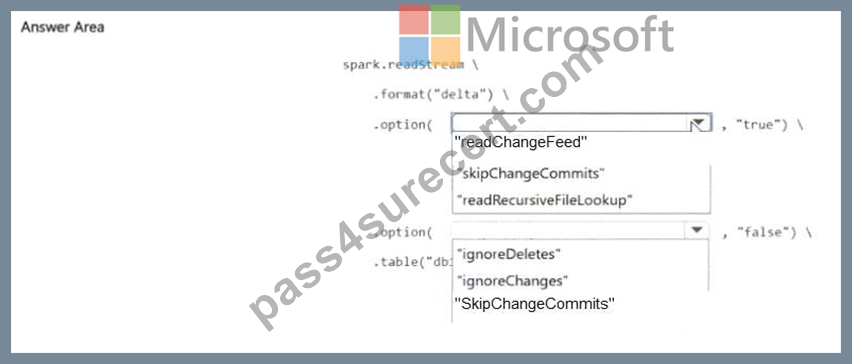
Answer:
Explanation: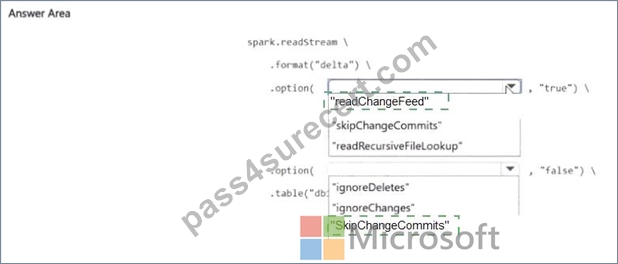
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
NEW QUESTION # 51
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: D
Explanation:
The correct answer is D - Continuous trigger.
A Continuous trigger keeps the job running as a perpetual loop. As soon as one micro-batch or iteration completes, the next begins. New records are picked up with the shortest possible latency - as close to real- time as a Lakeflow Jobs pipeline gets.
File Arrival (Option B) is event-driven but introduces per-file trigger overhead and is best suited for file-based ingestion rather than continuous streaming workloads. Scheduled (Option C) runs at fixed clock intervals - if new data arrives between runs, it waits until the next scheduled execution. Manual (Option A) requires a human to start each run.
The question specifies serverless compute, which pairs naturally with Continuous trigger because serverless handles cluster lifecycle automatically - the job stays active without managing a persistent cluster. 'New records must be processed as soon as they become available' is the exact use case the Continuous trigger is designed for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers
NEW QUESTION # 52
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
Hotspot Question
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.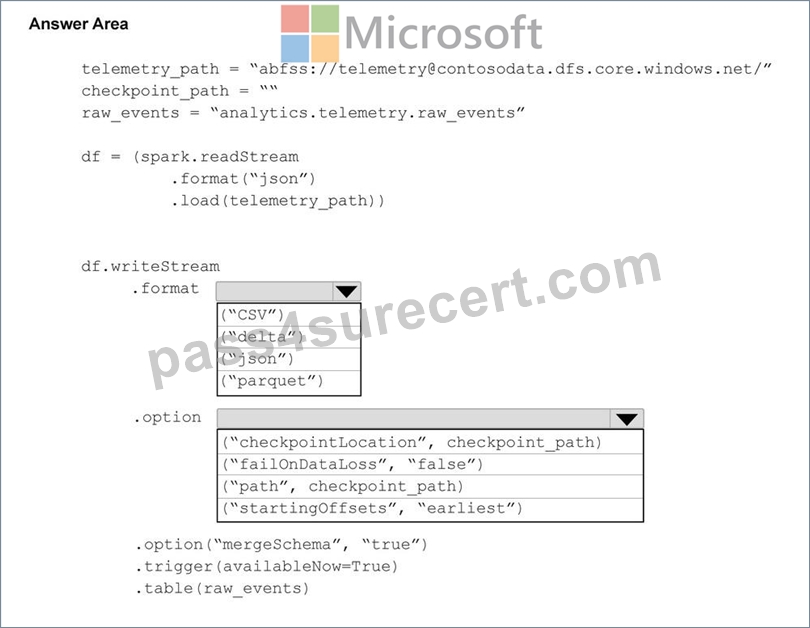
Answer:
Explanation: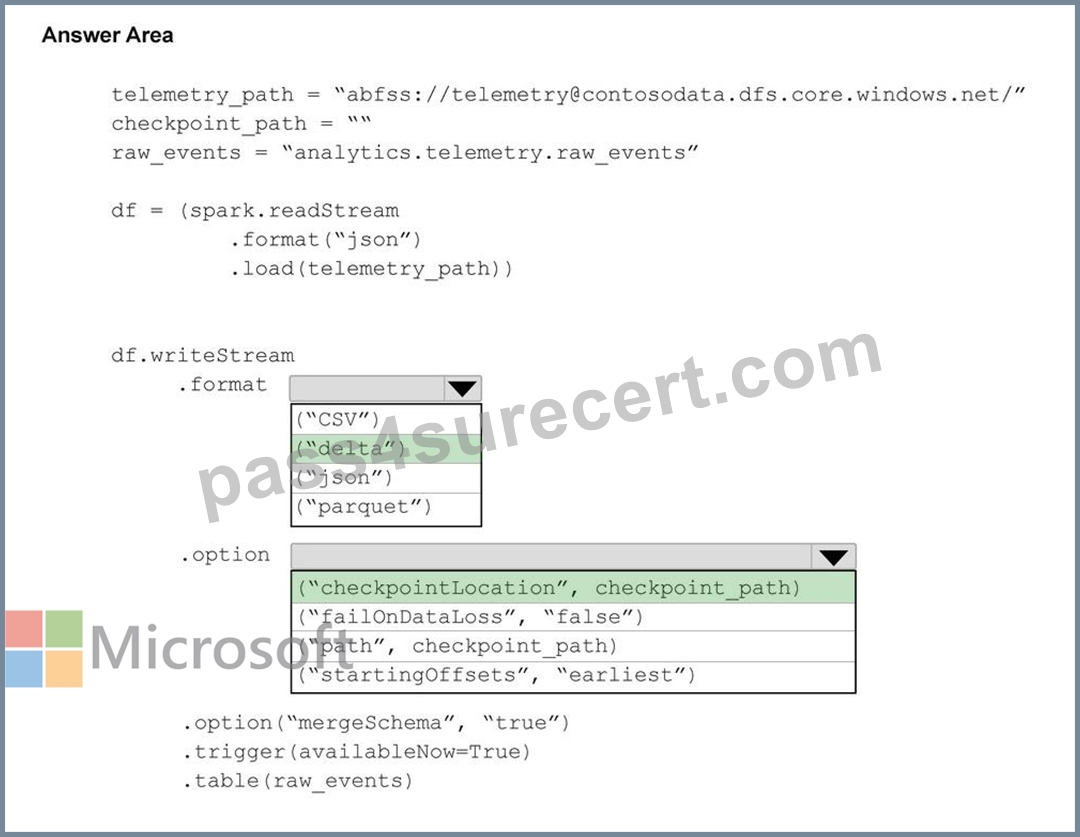
NEW QUESTION # 53
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 contains three tasks named Task1, Task2, and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.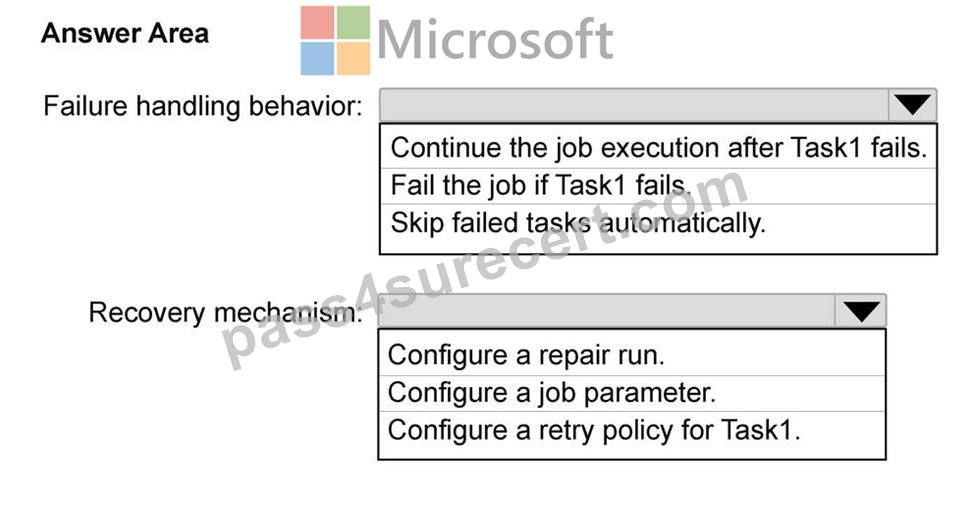
Answer:
Explanation: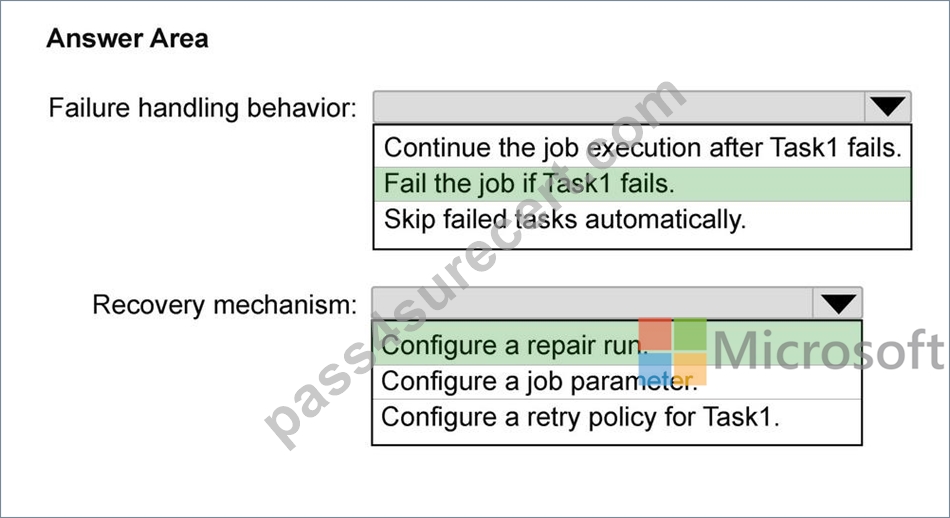
NEW QUESTION # 54
......
Here in this Desktop practice test software, the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice questions given are very relevant to the actual Microsoft DP-750 exam. It is compatible with Windows computers. Pass4sureCert provides its valued customers with customizable Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam sessions. The Microsoft DP-750 practice test software also keeps track of the previous Microsoft DP-750 practice exam attempts.
DP-750 Review Guide: https://www.pass4surecert.com/Microsoft/DP-750-practice-exam-dumps.html
P.S. Free & New DP-750 dumps are available on Google Drive shared by Pass4sureCert: https://drive.google.com/open?id=1JUaFXfdtgRbfAnAyQ4fzmO7VARsYj5PI