ExamPassdump는 우수한 IT인증시험 공부가이드를 제공하는 전문 사이트인데 업계에서 높은 인지도를 가지고 있습니다. ExamPassdump에서는 IT인증시험에 대비한 모든 덤프자료를 제공해드립니다. Microsoft인증 AI-200시험을 준비하고 계시는 분들은ExamPassdump의Microsoft인증 AI-200덤프로 시험준비를 해보세요. 놀라운 고득점으로 시험패스를 도와드릴것입니다.시험에서 불합격하면 덤프비용 전액환불을 약속드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
여러분은 먼저 우리 ExamPassdump사이트에서 제공되는Microsoft인증AI-200시험덤프의 일부분인 데모를 다운받으셔서 체험해보세요. ExamPassdump는 여러분이 한번에Microsoft인증AI-200시험을 패스하도록 하겠습니다. 만약Microsoft인증AI-200시험에서 떨어지셨다고 하면 우리는 덤프비용전액 환불입니다.
질문 # 43
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.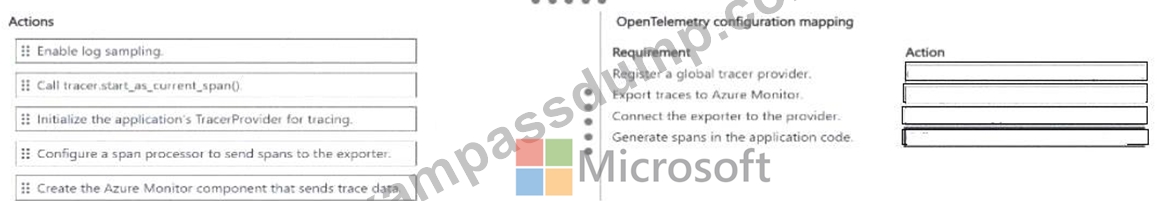
정답:
설명: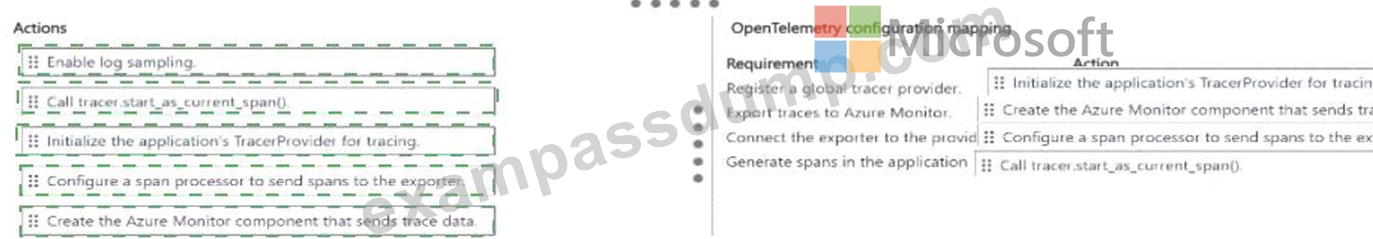
Explanation:
Verified Answer: Register a global trace provider # initialize the application TraceProvider. Export traces to Azure Monitor # create/configure AzureMonitorTraceExporter. Connect exporter to provider # add a span processor. Generate spans # use tracer.start_as_current_span(...).
Detailed Explanation: OpenTelemetry tracing is a pipeline: the application obtains a tracer from a configured provider, creates spans, passes ended spans through a span processor, and exports them using the Azure Monitor exporter. Creating spans alone is insufficient; without the provider/processor/exporter chain, no telemetry reaches Azure Monitor. Log sampling and legacy Application Insights TrackEvent calls are unrelated to the required OpenTelemetry trace-export path.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Enable Azure Monitor OpenTelemetry
질문 # 44
You have a newly provisioned Azure subscription. You are designing a custom Event Grid workflow for AI inference events.
You need to implement the Event Grid components to support routing of high-confidence events to a downstream processor.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.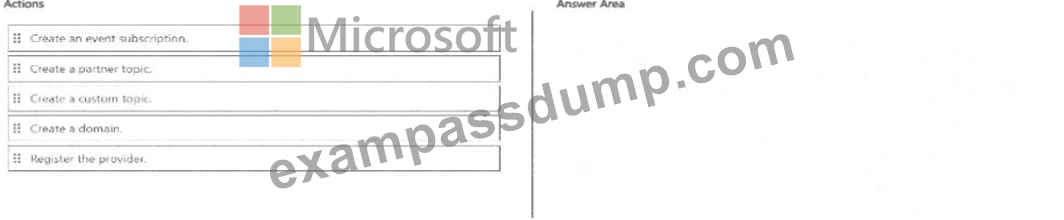
정답:
설명: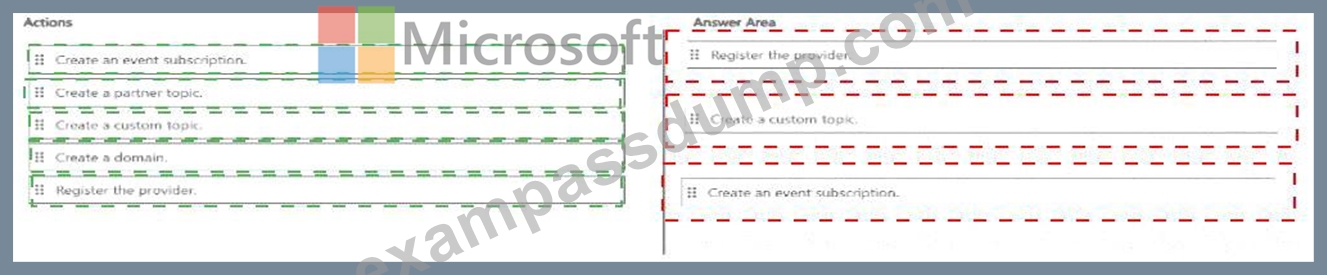
Explanation: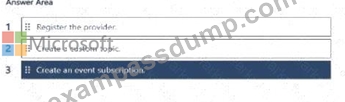
Verified answer: 1) Register the Event Grid resource provider; 2) create a custom topic; 3) create an event subscription.
Detailed Explanation: A newly provisioned subscription must have the Event Grid resource provider available before Event Grid resources can be created. The publisher needs a custom topic as the event-ingress resource, and routing to a downstream processor is then defined by an event subscription on that topic. The event subscription can include filters such as event type or data fields so that only high-confidence events reach the processor. Creating a partner topic or domain is unnecessary for the stated custom workflow.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Create an Event Grid custom topic or domain
질문 # 45
You deploy a production Azure Function app that connects to an Azure SQL Database.
The solution must provide the following functionality:
- Prevent secrets from being exposed in source control.
- Support secret rotation without redeploying the function app.
- Avoid downtime during credential updates.
You need to configure secure and maintainable secret management.
What should you configure?
정답:B
설명:
To meet all requirements, you should configure Application settings with Key Vault references.
Source Control Protection: The Function App source code and configuration files only store a reference URI (e.g., @Microsoft.KeyVault(SecretUri=...)) rather than the actual connection string, keeping secrets entirely out of source control.
Seamless Secret Rotation: Azure Key Vault handles secret rotation natively. When a database password changes, you simply update the secret in Key Vault.
Zero Downtime: By using versionless Key Vault references (omitting the specific version GUID from the URI), the Azure Function App will automatically fetch the latest secret version within 24 hours without requiring a code redeployment or app restart.
References:
https://oneuptime.com/blog/post/2026-02-16-how-to-configure-managed-identity-for-azure-app-service-to-access-key-vault-secrets-without-credentials/view
질문 # 46
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application?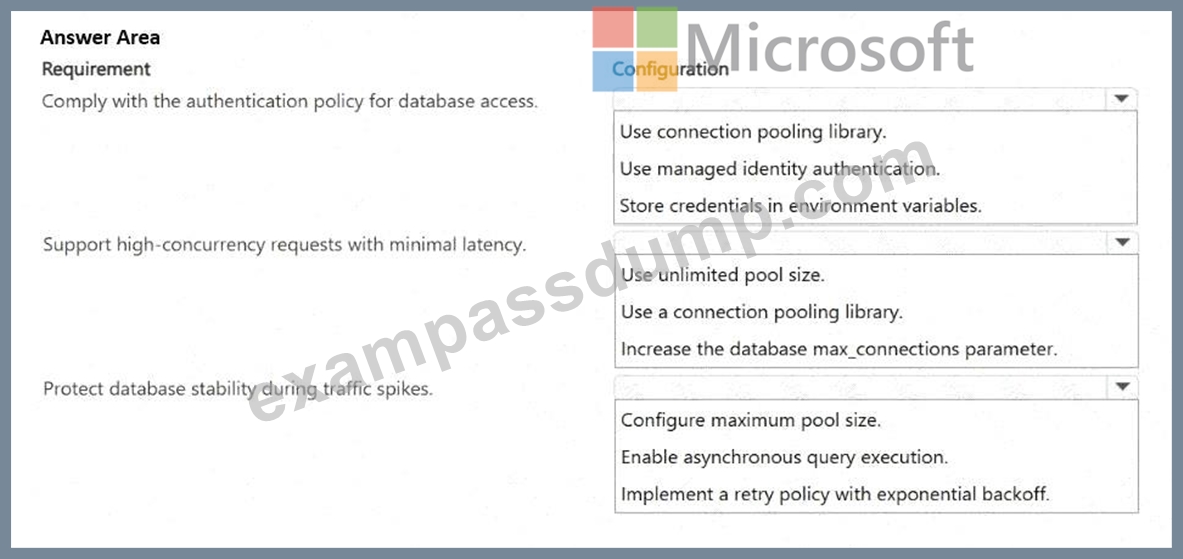
정답:
설명: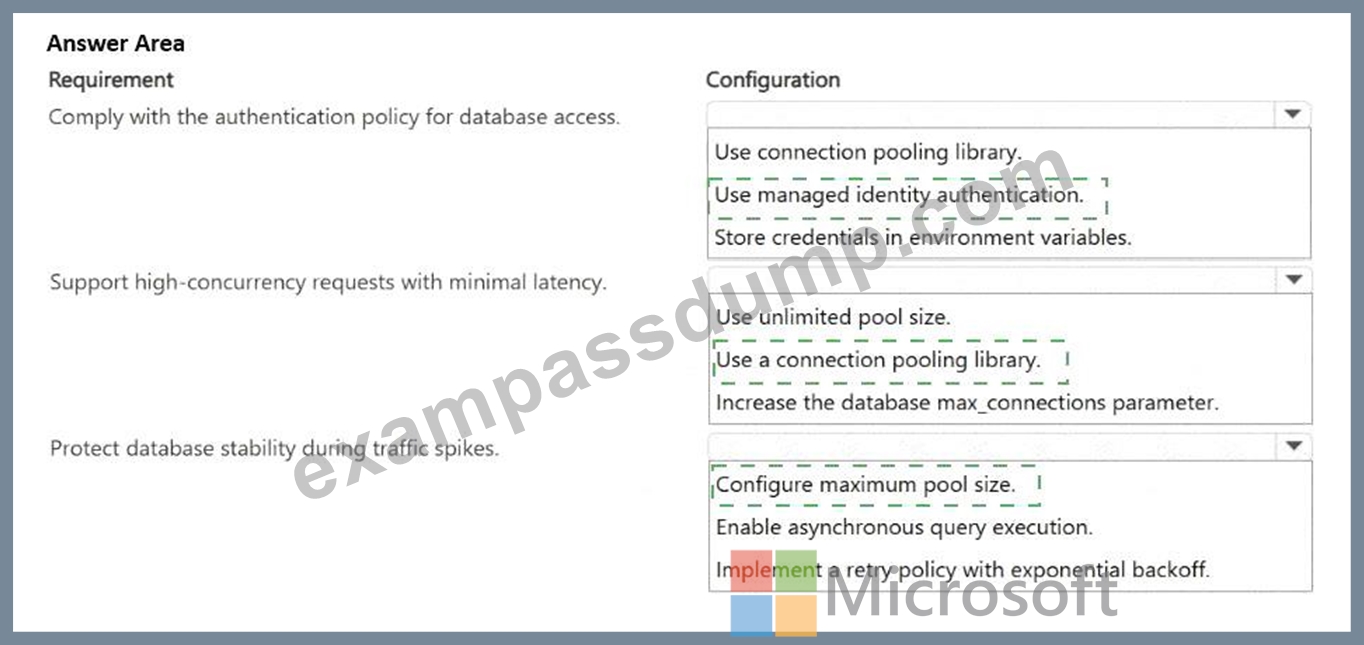
Explanation:
* Comply with the authentication policy for database access: Use managed identity authentication.
* Support high-concurrency requests with minimal latency: Use a connection pooling library.
* Protect database stability during traffic spikes: Configure maximum pool size.
The Recommendation API should use managed identity authentication because Fabrikam explicitly requires service-to-database authentication without long-lived credentials. Azure Container Apps managed identities allow applications to obtain Microsoft Entra tokens at runtime and access supported Azure resources without storing usernames, passwords, or connection secrets in application configuration.
For high-concurrency PostgreSQL access, implement a connection pooling library . Azure Database for PostgreSQL documentation recommends connection pooling because repeatedly opening new database connections creates backend processes and consumes CPU and memory. Reusing existing connections reduces connection-establishment overhead and improves latency and throughput. Azure also provides PgBouncer as a built-in pooling option for Flexible Server.
To protect PostgreSQL during sudden traffic spikes, configure a maximum pool size . An unlimited pool can allow application demand to create excessive concurrent connections, which can exhaust database memory and increase contention. Microsoft warns that increasing connection counts can cause significant performance degradation and recommends conservative connection limits combined with pooling.
Therefore, the optimal configuration combines managed identity + connection pooling + bounded pool size
.
Study Guide references: Azure Container Apps managed identities; Azure Database for PostgreSQL connection management; PgBouncer; connection-pool sizing and resource protection.
질문 # 47
You need to configure a connection string for the partner-facing service according to the technical requirements.
What should you use?
정답:A
설명:
Detailed Explanation: Azure Key Vault references in App Service settings satisfy the requirement to keep secrets out of container images, source control, and directly stored application configuration. App Service resolves the referenced secret at runtime by using the app identity, so the application can consume the value as a normal setting without embedding credentials in the image. GitHub secrets are build/deployment secrets rather than a runtime App Service secret-delivery mechanism. Dockerfile ENV instructions would place secret material in the image configuration and violate the case requirements.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Use Key Vault references for App Service and Functions | Managed identities for Azure resources
Topic 2, Fabrikam Inc
Background - Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure. The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security. The solution must meet strict performance, scalability, and security requirements. Current environment - Application architecture - The Recommendation engine is a customer- facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA). Embeddings are stored in Azure Database for PostgreSQL by using pgvector. Semantic retrieval uses metadata filtering combined with vector similarity search. Azure Managed Redis is used as a caching layer. Front-end and API workloads are deployed to Azure Container Apps (ACA). Batch model retraining workloads run in Azure Kubernetes Service (AKS). Container and CI/CD - Container images are stored in Azure Container Registry (ACR). CI/CD uses ACR Tasks to build images on commit. ACA environments support revision management. AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring - Logs are collected in Azure Monitor. Teams inspect container logs and Kubernetes events when troubleshooting. Developers write KQL queries to analyze latency spikes. Business requirements - Customer experience: Maintain a seamless, low-latency recommendation experience for end-users, even during unpredictable seasonal traffic spikes. Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs. Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction. Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets. Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers. Technical requirements - Performance: Semantic search latency must remain under 200 milliseconds at peak load. Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput.
Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints. Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization. Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates. Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited. Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy. Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero. CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits. Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
질문 # 48
......
ExamPassdump는 여러분의 꿈을 이루어줄 뿐만 아니라 일년무료 업뎃서비스도 따릅니다. ExamPassdump에서 제공하는 덤프로 여러분은 1000%시험을 패스하실수 있고Microsoft AI-200자격증을 취득하실 수 있습니다.지금 바로 사이트에서Microsoft AI-200덤프데모 즉 덤프의 일부 문제와 답을 다운 받으셔서 체험하실 수 있습니다.
AI-200시험패스 가능한 공부자료: https://www.exampassdump.com/AI-200_valid-braindumps.html