Real Databricks-Certified-Professional-Data-Engineer questions in our PDF document can be viewed at any time from any place using your smartphone, tablet, and laptop. If you are busy and don't have time to sit and study for the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer test, download and use Databricks Databricks-Certified-Professional-Data-Engineer PDF dumps on the go. To pass the Databricks Databricks-Certified-Professional-Data-Engineer exam, it is recommended that you simply use TrainingQuiz Databricks-Certified-Professional-Data-Engineer real dumps for a few days.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Data validation and quality checks - Handling missing or inconsistent data |
| Topic 2: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Data transformation and aggregation - Batch and incremental processing logic |
| Topic 3: Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
| Topic 4: Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Topic 5: Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Topic 6: Data Governance | 7% | - Policy enforcement - Data lineage and metadata tracking - Unity Catalog management |
| Topic 7: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Schema inference and evolution - Connecting to diverse data sources |
| Topic 8: Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Topic 9: Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
| Topic 10: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
>> Databricks-Certified-Professional-Data-Engineer Authorized Exam Dumps <<
If you are anxious about whether you can pass your exam and get the certificate, we think you need to buy our Databricks-Certified-Professional-Data-Engineer study materials as your study tool, our product will lend you a good helping hand. If you are willing to take our Databricks-Certified-Professional-Data-Engineer study materials into more consideration, it must be very easy for you to pass your exam in a short time. 99% people who have used our Databricks-Certified-Professional-Data-Engineer Study Materials passed their exam and got their certificate successfully, it is no doubt that it means our Databricks-Certified-Professional-Data-Engineer study materials have a 99% pass rate. So our product will be a very good choice for you.
NEW QUESTION # 135
A data engineer has three notebooks in an ELT pipeline. The notebooks need to be executed in a specific order
for the pipeline to complete successfully. The data engineer would like to use Delta Live Tables to manage this
process.
Which of the following steps must the data engineer take as part of implementing this pipeline using Delta
Live Tables?
Answer: D
NEW QUESTION # 136
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic: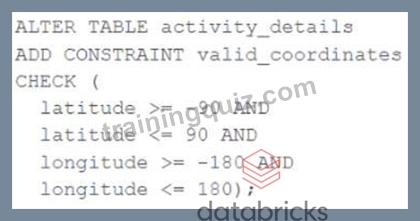
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
Answer: C
Explanation:
Explanation
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
Constraints: https://docs.delta.io/latest/delta-constraints.html
ACID Transactions: https://docs.delta.io/latest/delta-intro.html#acid-transactions
NEW QUESTION # 137
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
Answer: E
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Create an external table" section.
NEW QUESTION # 138
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline.
Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
Answer: C
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
Reference:
Databricks Documentation on CLI for Pipelines: Databricks CLI - Pipelines
NEW QUESTION # 139
Which statement describes integration testing?
Answer: E
Explanation:
This is the correct answer because it describes integration testing. Integration testing is a type of testing that validates interactions between subsystems of your application, such as modules, components, or services.
Integration testing ensures that the subsystems work together as expected and produce the correct outputs or results. Integration testing can be done at different levels of granularity, such as component integration testing, system integration testing, or end-to-end testing. Integration testing can help detect errors or bugs that may not be found by unit testing, which only validates behavior of individual elements of your application.
Verified References: [Databricks Certified Data Engineer Professional], under "Testing" section; Databricks Documentation, under "Integration testing" section.
NEW QUESTION # 140
......
Our company has employed a lot of leading experts in the field to compile the Databricks Certified Professional Data Engineer Exam exam question. Our system of team-based working is designed to bring out the best in our people in whose minds and hands the next generation of the best Databricks-Certified-Professional-Data-Engineer exam torrent will ultimately take shape. Our company has a proven track record in delivering outstanding after sale services and bringing innovation to the guide torrent. I believe that you already have a general idea about the advantages of our Databricks Certified Professional Data Engineer Exam exam question, but now I would like to show you the greatest strength of our Databricks-Certified-Professional-Data-Engineer Guide Torrent --the highest pass rate. According to the statistics, the pass rate among our customers who prepared the exam under the guidance of our Databricks-Certified-Professional-Data-Engineer guide torrent has reached as high as 98% to 100% with only practicing our Databricks-Certified-Professional-Data-Engineer exam torrent for 20 to 30 hours.
New Databricks-Certified-Professional-Data-Engineer Braindumps Free: https://www.trainingquiz.com/Databricks-Certified-Professional-Data-Engineer-practice-quiz.html