2026年PassTestの最新DA0-001 PDFダンプおよびDA0-001試験エンジンの無料共有:https://drive.google.com/open?id=1FI5F6ncHtvzXZqgp1udko4ryFCm744Lz
競争力が激しい社会に当たり、我々PassTestは多くの受験生の中で大人気があるのは受験生の立場からCompTIA DA0-001試験資料をリリースすることです。たとえば、ベストセラーのCompTIA DA0-001問題集は過去のデータを分析して作成ます。ほんとんどお客様は我々PassTestのCompTIA DA0-001問題集を使用してから試験にうまく合格しましたのは弊社の試験資料の有効性と信頼性を説明できます。
| Section | Weight | Objectives |
|---|---|---|
| Data Governance, Quality and Controls | 14% | - Data privacy, security, and compliance - Data governance frameworks and policies - Data lifecycle management and controls - Data quality standards and measurement |
| Data Mining | 25% | - Data acquisition and integration methods - Data profiling, cleansing, and validation - Querying and retrieving data - Data transformation, manipulation, and enrichment |
| Data Analysis | 23% | - Interpreting results and identifying patterns/anomalies - Analytical techniques: trend, performance, exploratory, comparative - Descriptive and inferential statistics - Statistical methods: correlation, regression, hypothesis testing |
| Visualization and Reporting | 23% | - Design principles and best practices - Selecting appropriate visualizations and charts - Communicating insights and recommendations - Building dashboards and reports |
| Data Concepts and Environments | 15% | - Data schemas, dimensions, and attributes - Data storage systems: databases, data marts, warehouses, data lakes - Data types, structures, and formats - Structured, semi-structured, and unstructured data |
これらすべてのDA0-001学習教材で、あなたの成功は100%保証されます。さらに、無料のデモがあります。無料のデモでは、練習資料の内容について証明された経験に基づいた推測を提供します。 DA0-001試験の知識を、あなたのように成功することに熱心な熱心な試験受験者に伝えることで、彼らはそれを助けを提供する責任として扱います。あなたの情報の次の特徴を備えたDA0-001学習ガイドを入手できる場合は、驚くべき進歩を遂げる準備をしてください。
質問 # 27
Which of the following is concatenate typically used to combine?
正解:B
解説:
Concatenation is primarily used to combine columns of data. It is a function commonly used in data manipulation to merge strings or numerical values from two or more columns into a single column. This is especially useful in data cleaning and transformation tasks where information from multiple fields needs to be represented together in a single field, such as merging first names and last names into a full name.
Reference: CompTIA Data+ DA0-001 Official Guide
質問 # 28
A cereal manufacturer wants to determine whether the sugar content of its cereal has increased over the years. Which of the following is the appropriate descriptive statistic to use?
正解:A
解説:
This is because percent change is a type of descriptive statistic that measures the relative change or difference of a variable over time, such as the sugar content of cereal over years in this case. Percent change can be used to determine whether the sugar content of cereal has increased over years by comparing the initial and final values of the sugar content, as well as calculating the ratio or proportion of the change. For example, percent change can be used to determine whether the sugar content of cereal has increased over years by finding out how much more (or less) sugar there is in cereal now than before, as well as expressing it as a fraction or a percentage of the original sugar content. The other descriptive statistics are not appropriate to use to determine whether the sugar content of cereal has increased over years. Here is why:
Frequency is a type of descriptive statistic that measures how often or how likely a value or an event occurs in a data set, such as how many times a certain sugar content appears in cereal in this case. Frequency does not measure the relative change or difference of a variable over time, but rather measures the occurrence or chance of a variable at a given time.
Variance is a type of descriptive statistic that measures how much the values in a data set vary or deviate from the mean or average of the data set, such as how much variation there is in sugar content among different cereals in this case. Variance does not measure the relative change or difference of a variable over time, but rather measures the dispersion or spread of a variable at a given time.
Mean is a type of descriptive statistic that measures the average value or central tendency of a data set, such as what is the typical sugar content of cereal in this case. Mean does not measure the relative change or difference of a variable over time, but rather measures the summary or representation of a variable at a given time.
質問 # 29
Given the following data table: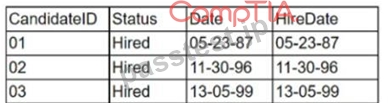
Which of the following are appropriate reasons to undertake data cleansing? (Select two).
正解:B、C
解説:
Data cleansing is a critical process in data analytics to ensure the accuracy and quality of data. The reasons to undertake data cleansing include:
* Missing Data (B): Missing data can lead to incomplete analysis and biased results. It is essential to identify and address gaps in the dataset to maintain the integrity of the analysis1.
* Invalid Data (D): Invalid data includes entries that are out of range, improperly formatted, or illogical (e.g., a negative age). Such data can corrupt analysis and lead to incorrect conclusions1.
Other options, such as non-parametric data (A), are not inherently errors but refer to a type of data that doesn' t assume a normal distribution. Duplicate data and redundant data (E) could also be reasons for data cleansing, but they are not listed as options to select from in the provided image details. Normalized data (F) refers to data that has been processed to fit into a certain range or format and is typically not a reason for data cleansing.
References:
* Understanding the importance of data quality and the impacts of missing and invalid data on research outcomes1.
* Best practices in data cleansing2.
Data cleansing is required for various reasons, two of which are missing data (B) and invalid data (D). From the table provided, we can infer the necessity of cleansing in the context of ensuring data integrity and consistency. Missing data refers to the absence of data where it is expected, which can hinder analysis due to incomplete information. Invalid data refers to data that is incorrect, out of range, or in an inappropriate format, which can lead to inaccuracies in any analysis or report. Both these issues can significantly affect the outcomes of any data-related operations and thus need to be rectified through the data cleansing process.
質問 # 30
Given the following tables: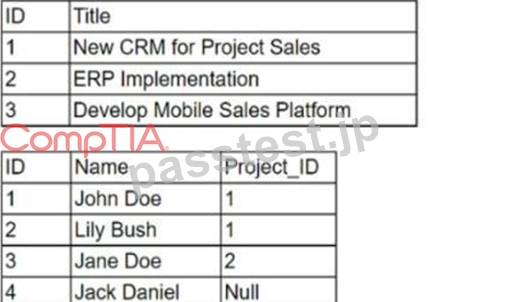
Which of the following will be the dimensions from a FULL JOIN of the tables above?
正解:A
解説:
A FULL JOIN in SQL combines all rows from two or more tables, regardless of whether a match exists. The result includes all records when there is a match in the joined tables and fills in NULLs for missing matches on either side. Given the two tables in the image, the first table has three rows, and the second table has four rows. The FULL JOIN of these tables will include all rows from both tables, resulting in four rows. Since there are three unique columns in the first table (ID, Title) and three unique columns in the second table (ID, Name, Project_ID), with the common column being ID, the resulting table will have four columns (ID, Title, Name, Project_ID).
References:
* SQL documentation on FULL JOIN operations.
質問 # 31
A JSON file is an example of:
正解:C
質問 # 32
......
競争力が激しい社会に当たり、我々PassTestは多くの受験生の中で大人気があるのは受験生の立場からCompTIA DA0-001試験資料をリリースすることです。たとえば、ベストセラーのCompTIA DA0-001問題集は過去のデータを分析して作成ます。ほんとんどお客様は我々PassTestのCompTIA DA0-001問題集を使用してから試験にうまく合格しましたのは弊社の試験資料の有効性と信頼性を説明できます。
DA0-001認定試験: https://www.passtest.jp/CompTIA/DA0-001-shiken.html
2026年PassTestの最新DA0-001 PDFダンプおよびDA0-001試験エンジンの無料共有:https://drive.google.com/open?id=1FI5F6ncHtvzXZqgp1udko4ryFCm744Lz