Our Databricks-Generative-AI-Engineer-Associate study materials are the best choice in terms of time and money. And all contents of Databricks-Generative-AI-Engineer-Associate training prep are made by elites in this area. Furthermore, Databricks-Generative-AI-Engineer-Associate Quiz Guide gives you 100 guaranteed success and free demos. To fit in this amazing and highly accepted Databricks-Generative-AI-Engineer-Associate Exam, you must prepare for it with high-rank practice materials like our Databricks-Generative-AI-Engineer-Associate study materials. We can ensure your success on the coming exam and you will pass the Databricks-Generative-AI-Engineer-Associate exam just like the others.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Real Exam Qty: | 45 |
| Certificate Validity Period: | 2 years |
| Available Languages: | Portuguese (Brazil), Korean, English, Japanese |
| Passing Score: | Scaled Score (approx. 70%) |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Exam Duration: | 90 minutes |
| Exam Price: | $200 USD |
| Exam Format: | Multiple Choice, Multiple Select |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks Databricks-Generative-AI-Engineer-Associate Real Brain Dumps <<
The learning material is open in three excellent formats, PDF, a desktop practice test, and a web-based practice test. Databricks Databricks-Generative-AI-Engineer-Associate Dumps is organized by experts while saving the furthest down-the-line plan to them for the Databricks Databricks-Generative-AI-Engineer-Associate Exam. The sans bug plans have been given to you all to drift through the Databricks Databricks-Generative-AI-Engineer-Associate certification exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 50
A Generative Al Engineer is building a system which will answer questions on latest stock news articles.
Which will NOT help with ensuring the outputs are relevant to financial news?
Answer: B
Explanation:
In the context of ensuring that outputs are relevant to financial news, increasing compute power (option B) does not directly improve therelevanceof the LLM-generated outputs. Here's why:
* Compute Power and Relevancy:Increasing compute power can help the model process inputs faster, but it does not inherentlyimprove therelevanceof the answers. Relevancy depends on the data sources, the retrieval method, and the filtering mechanisms in place, not on how quickly the model processes the query.
* What Actually Helps with Relevance:Other methods, like content filtering, guardrails, or manual review, can directly impact the relevance of the model's responses by ensuring the model focuses on pertinent financial content. These methods help tailor the LLM's responses to the financial domain and avoid irrelevant or harmful outputs.
* Why Other Options Are More Relevant:
* A (Comprehensive Guardrail Framework): This will ensure that the model avoids generating content that is irrelevant or inappropriate in the finance sector.
* C (Profanity Filter): While not directly related to financial relevancy, ensuring the output is clean and professional is still important in maintaining the quality of responses.
* D (Manual Review): Incorporating human oversight to catch and correct issues with the LLM's output ensures the final answers are aligned with financial content expectations.
Thus, increasing compute power does not help with ensuring the outputs are more relevant to financial news, making option B the correct answer.
NEW QUESTION # 51
A Generative AI Engineer just deployed an LLM application at a digital marketing company that assists with answering customer service inquiries.
Which metric should they monitor for their customer service LLM application in production?
Answer: A
Explanation:
When deploying an LLM application for customer service inquiries, the primary focus is on measuring the operational efficiency and quality of the responses. Here's whyAis the correct metric:
* Number of customer inquiries processed per unit of time: This metric tracks the throughput of the customer service system, reflecting how many customer inquiries the LLM application can handle in a given time period (e.g., per minute or hour). High throughput is crucial in customer service applications where quick response times are essential to user satisfaction and business efficiency.
* Real-time performance monitoring: Monitoring the number of queries processed is an important part of ensuring that the model is performing well under load, especially during peak traffic times. It also helps ensure the system scales properly to meet demand.
Why other options are not ideal:
* B. Energy usage per query: While energy efficiency is a consideration, it is not the primary concern for a customer-facing application where user experience (i.e., fast and accurate responses) is critical.
* C. Final perplexity scores for the training of the model: Perplexity is a metric for model training, but it doesn't reflect the real-time operational performance of an LLM in production.
* D. HuggingFace Leaderboard values for the base LLM: The HuggingFace Leaderboard is more relevant during model selection and benchmarking. However, it is not a direct measure of the model's performance in a specific customer service application in production.
Focusing on throughput (inquiries processed per unit time) ensures that the LLM application is meeting business needs for fast and efficient customer service responses.
NEW QUESTION # 52
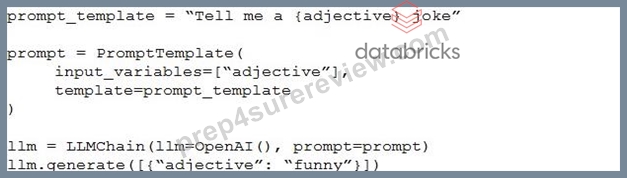
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.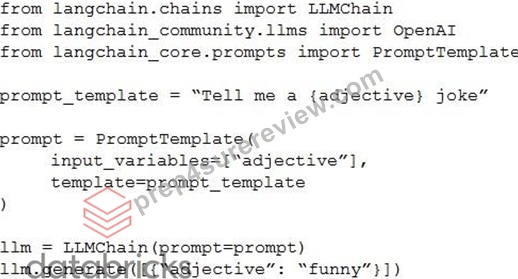
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
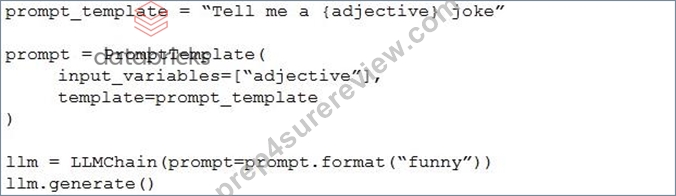
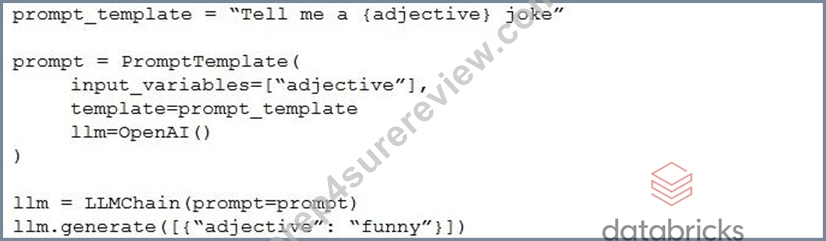
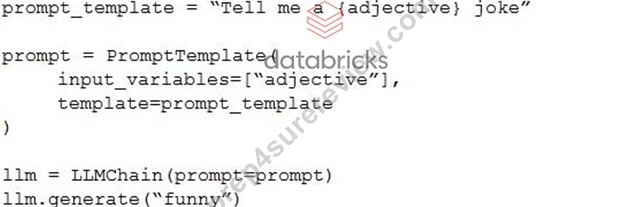
Answer: B
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 53
What is the most suitable library for building a multi-step LLM-based workflow?
Answer: B
Explanation:
* Problem Context: The Generative AI Engineer needs a tool to build amulti-step LLM-based workflow. This type of workflow often involves chaining multiple steps together, such as query generation, retrieval of information, response generation, and post-processing, with LLMs integrated at several points.
* Explanation of Options:
* Option A: Pandas: Pandas is a powerful data manipulation library for structured data analysis, but it is not designed for managing or orchestrating multi-step workflows, especially those involving LLMs.
* Option B: TensorFlow: TensorFlow is primarily used for training and deploying machine learning models, especially deep learning models. It is not designed for orchestrating multi-step tasks in LLM-based workflows.
* Option C: PySpark: PySpark is a distributed computing framework used for large-scale data processing. While useful for handling big data, it is not specialized for chaining LLM-based operations.
* Option D: LangChain: LangChain is a purpose-built framework designed specifically for orchestrating multi-step workflowswith large language models (LLMs). It enables developers to easily chain different tasks, such as retrieving documents, summarizing information, and generating responses, all in a structured flow. This makes it the best tool for building complex LLM-based workflows.
Thus,LangChainis the most suitable library for creating multi-step LLM-based workflows.
NEW QUESTION # 54
A generative AI engineer is deploying an AI agent authored with MLflow's ChatAgent interface for a retail company ' s customer support system on Databricks. The agent must handle thousands of inquiries daily, and the engineer needs to track its performance and quality in real-time to ensure it meets service-level agreements. Which metrics are automatically captured by default and made available for monitoring when the agent is deployed using the Mosaic AI Agent Framework?
Answer: B
Explanation:
When deploying an agent via the Mosaic AI Agent Framework (which leverages Databricks Model Serving), operational metrics are captured automatically by default. These include system-level telemetry such as the number of requests per second (volume), the time taken for the model to respond (latency), and the rate of 4xx
/5xx HTTP errors. These are essential for monitoring Service Level Agreements (SLAs). However, Quality metrics (B), such as correctness, groundedness, or adherence to custom guidelines, cannot be determined " automatically " by the serving infrastructure because they require either human feedback or an LLM-as-a- judge evaluation (using Databricks Agent Evaluation). While Databricks makes it easy to generate quality metrics using the mlflow.evaluate API or the inference table, they are not " default operational metrics " that appear without additional evaluation configuration.
NEW QUESTION # 55
......
Databricks-Generative-AI-Engineer-Associate Dumps Reviews: https://www.prep4surereview.com/Databricks-Generative-AI-Engineer-Associate-latest-braindumps.html