BTW, DOWNLOAD part of Pass4cram AI-200 dumps from Cloud Storage: https://drive.google.com/open?id=1PBi6DE1k2PIXCtxRg-Iz_WYcGL5-gdv7
Pass4cram is a leading platform in this area by offering the most accurate AI-200 exam questions to help our customers to pass the exam. And we are grimly determined and confident in helping you. With professional experts and brilliant teamwork, our AI-200 practice materials have helped exam candidates succeed since the beginning. To make our AI-200 simulating exam more precise, we do not mind splurge heavy money and effort to invite the most professional teams into our group.
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
At present, our AI-200 study guide gains popularity in the market. The quality of our training material is excellent. After all, we have undergone about ten years’ development. Never has our AI-200 practice test let customers down. Although we also face many challenges and troubles, our company get over them successfully. If you are determined to learn some useful skills, our AI-200 practice material will be your good assistant. Then you will seize the good chance rather than others. Time and tide wait for no man. You cannot depend on others to change your destiny.
NEW QUESTION # 45
Drag and Drop Question
A recommendation system stores 3 million embeddings in Azure Database for PostgreSQL.
During peak hours, P95 similarity-query latency increases, and the cache hit ratio drops significantly.
You suspect that the vector index working set no longer fits in memory, resulting in more disk reads.
You need to scale server resources and validate the outcome.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.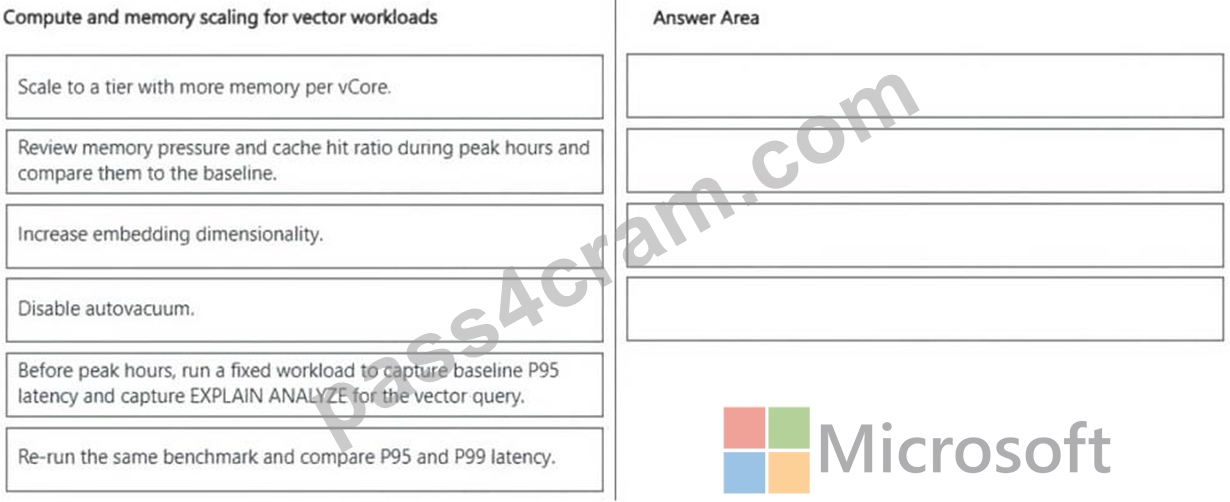
Answer:
Explanation: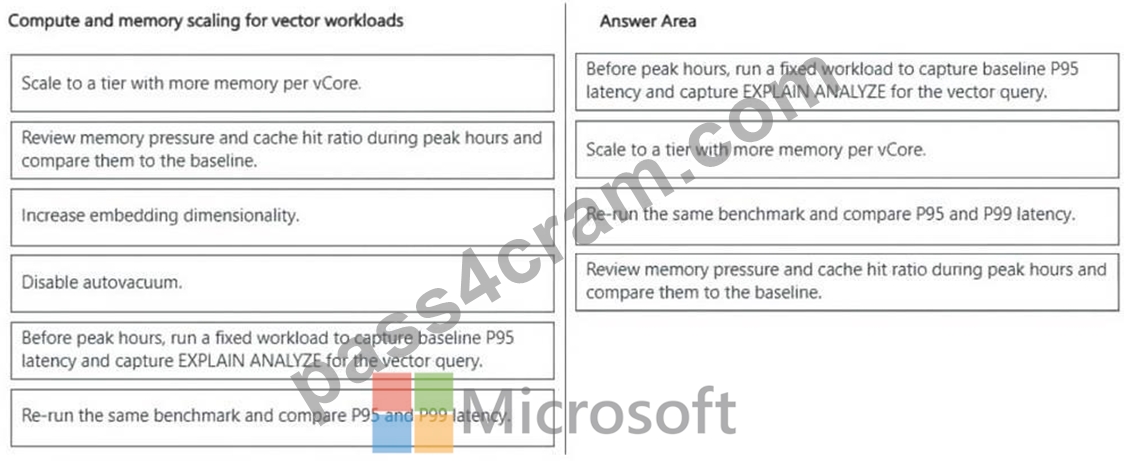
Explanation:
Step 1: Before peak hours, run a fixed workload to capture baseline P95 latency and capture EXPLAIN ANALYZE for the vector query Establishing a baseline is crucial for performance tuning. Running EXPLAIN ANALYZE provides deep insight into whether the query is actually using the vector index (like HNSW or IVFFlat) or falling back to a slow sequential scan.
Step 2: Scale to a tier with more memory per vCore
Since the problem states that the vector index working set no longer fits in memory, scaling to a tier with higher memory (such as Memory-Optimized tiers) directly solves the root cause by allowing the RAM to fully cache the vector index, eliminating slow disk reads.
Step 3: Re-run the same benchmark and compare P95 and P99 latency
To validate the outcome of your scaling operations, you must run the identical benchmark workload and compare high-percentile latencies (P95, P99) against your baseline to prove the bottleneck was resolved.
Step 4: Review memory pressure and cache hit ratio during peak hours and compare them to the baseline This step confirms the success of the resource scaling. A successful remediation will show a significantly increased cache hit ratio and reduced memory pressure/disk I/O compared to the baseline metrics.
Reference:
https://www.pgedge.com/blog/ai-features-in-pgadmin-ai-insights-for-explain-plans
NEW QUESTION # 46
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are preparing a production deployment for an Azure Function app. The app will run across multiple environments.
The solution must support environment-specific configuration and prevent secrets from being stored in source control.
You need to develop the solution.
Solution: Store production secrets in environment variables set by the Dockerfile.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Use App Configuration with Key Vault references to store environment-specific settings and secrets, accessed from the function app by using a managed identity.
This is an industry-standard best practice architectural pattern.
Using Azure App Configuration combined with Azure Key Vault references completely satisfies your compliance requirements. It centralizes feature flags and non-sensitive configurations, keeps sensitive data safely out of source control, handles multi-environment deployments cleanly, and eliminates credentials via a passwordless Managed Identity.
Incorrect:
* Store connection strings in the Function app application settings configured in the Azure Portal.
* Store production secrets in environment variables set by the Dockerfile.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
NEW QUESTION # 47
You are developing several microservices to run on Azure Container Apps.
The microservices must allow HTTPS access by using a custom domain.
You need to configure the custom domain in Azure Container Apps.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.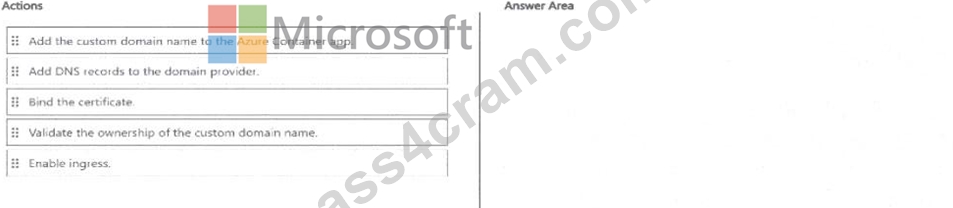
Answer:
Explanation: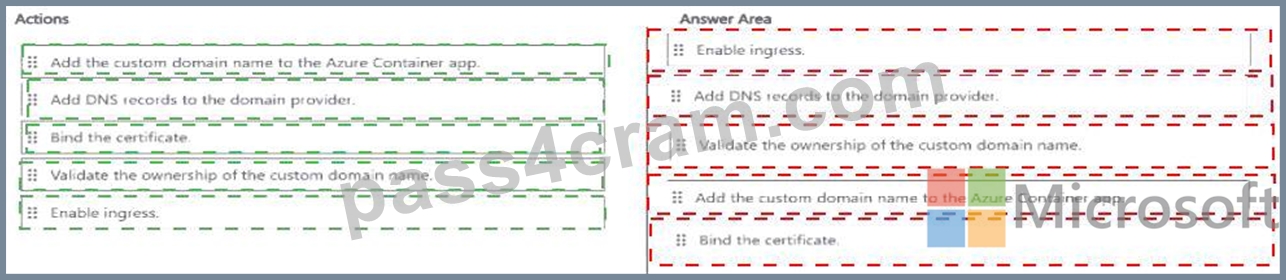
Explanation: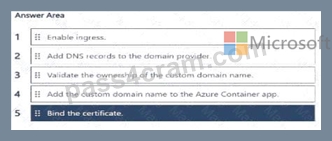
Verified answer: 1) Enable ingress; 2) add the required DNS records; 3) validate ownership of the custom domain; 4) add the custom domain to the Container App; 5) bind the certificate.
Detailed Explanation: A custom HTTPS hostname requires an ingress endpoint, DNS proof that the requester controls the hostname, the hostname association itself, and a TLS certificate bound to that hostname.
DNS records must exist before ownership validation can succeed. Once ownership is validated, the domain can be associated with the Container App and the certificate can be bound to provide HTTPS. Skipping ingress or DNS validation would prevent the hostname from being correctly routed and secured.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Custom domains and certificates in Container Apps
Topic 1, Proseware Inc. Case Study
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers. The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring:
* Telemetry generated by Azure resources is sent to Azure Monitor.
* A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
* Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version- controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known issues
RU consumption spikes during vector similarity queries.
NEW QUESTION # 48
An application performs similarity search across 5 million embeddings stored in Azure Database for PostgreSQL with pgvector. Queries often filter by department before ranking by cosine distance.
P95 latency for vector similarity queries exceeds the SLA target. Monitoring shows sustained high CPU use during query execution.
You need to reduce P95 latency for filtered vector similarity queries.
What should you do?
Answer: A
NEW QUESTION # 49
An application deployed to AKS depends on an internal API hosted in the same cluster. All pods are healthy and report Ready status, but requests between the services time out.
You need to determine whether the issue is related to Kubernetes service configuration or application code.
What should you do first?
Answer: C
Explanation:
Inspect Service and Endpoints objects is the best step to start with.
The symptoms describe pods that are healthy and passing their readiness probes (meaning they are Ready), but traffic is failing to reach them and timing out. In Kubernetes, a Service routes traffic to pods by matching labels to create an Endpoints object.
Checking these objects immediately verifies if the Kubernetes network routing layer is intact.If the Endpoints object is empty or missing, the Service selector does not match the Pod labels. Traffic has nowhere to go, causing a timeout.
If the Endpoints list correctly displays the Pod IP addresses, the Kubernetes routing layer is working, shifting the blame toward the application code (e.g., misconfigured listening ports) or network policies.
Reference:
https://www.xtivia.com/blog/kubernetes-container-health-checks/
NEW QUESTION # 50
......
How can you quickly change your present situation and be competent for the new life, for jobs, in particular? The answer is using AI-200 practice materials. From my perspective, our free demo is possessed with high quality which is second to none. This is no exaggeration at all. Just as what have been reflected in the statistics, the pass rate for those who have chosen our AI-200 Exam Guide is as high as 99%, which in turn serves as the proof for the high quality of our AI-200 study engine.
Latest AI-200 Test Prep: https://www.pass4cram.com/AI-200_free-download.html
2026 Latest Pass4cram AI-200 PDF Dumps and AI-200 Exam Engine Free Share: https://drive.google.com/open?id=1PBi6DE1k2PIXCtxRg-Iz_WYcGL5-gdv7