BONUS!!! Download part of ExamsTorrent DP-800 dumps for free: https://drive.google.com/open?id=1YDO_D3_uLf0LFINNECI1WPawueWBUnJB
Many don't find real Developing AI-Enabled Database Solutions exam questions and face loss of money and time. ExamsTorrent made an absolute gem of study material which carries actual Developing AI-Enabled Database Solutions (DP-800) Exam Questions for the students so that they don't get confused in order to prepare for Developing AI-Enabled Database Solutions (DP-800) exam and pass it with a good score. The DP-800 practice test questions are made by examination after consulting with a lot of professionals and receiving positive feedback from them.
| Section | Objectives |
|---|---|
| Topic 1: Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
| Topic 2: Integrate AI capabilities with database systems | - Implement AI-assisted data processing - Use Azure AI services with database workloads |
| Topic 3: Monitor, troubleshoot, and maintain solutions | - Monitoring database health and performance - Troubleshooting data pipeline issues |
| Topic 4: Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
>> DP-800 Practice Exams Free <<
We decided to research because we felt the pressure from competition. We must also pay attention to the social dynamics in the process of preparing for the DP-800 exam. Experts at our DP-800 simulating exam have been supplementing and adjusting the content of our products. So our DP-800 Exam Questions are always the most accurate and authoritative. At the same time, our professional experts keep a close eye on the updating the DP-800 study materials. That is why our DP-800 training prep is the best seller on the market.
NEW QUESTION # 15
Your company has an ecommerce catalog in a Microsoft SQL Server 202b database named SalesDB SalesDB contains a table named products, products contains the following columns:
* product.id (int)
* product_name (nvarchar(200))
* description (nvarchar(max))
* category (nvarchar(50))
* brand (nvarchar(W))
* price (decimal)
* sku (nvarchar(40))
The description fields ate updated dairy by a content pipeline, and price can change multiple times per day.
You want customers to be able to submit natural language queries and apply structured filters for brand and price. You plan to store embeddings in a new VECTOR(1536) column and use VECTOR_SEARCH(...
METRIC=' cosine ' ...).
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.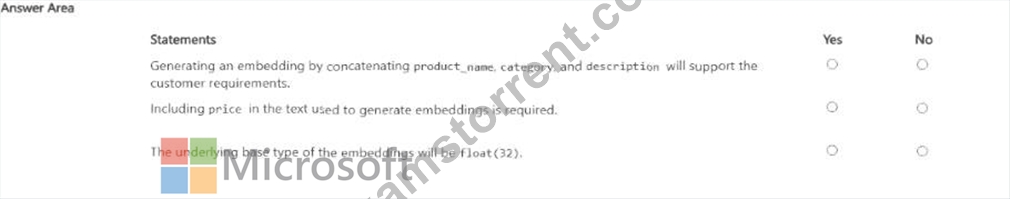
Answer:
Explanation: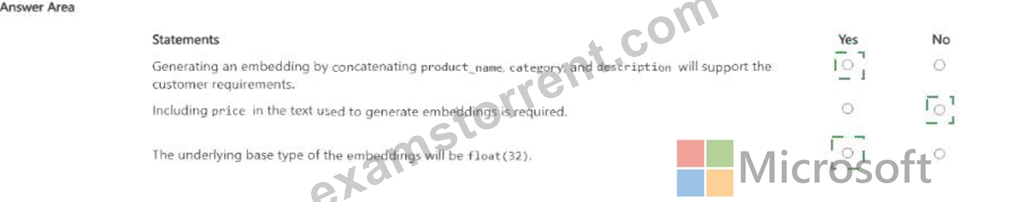
Explanation: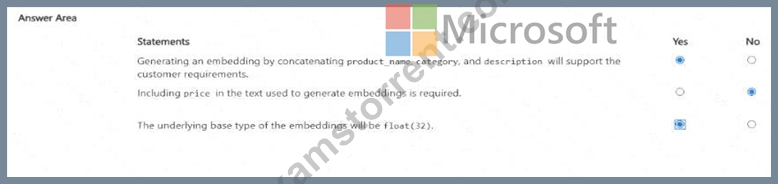
The first statement is Yes . Embeddings are used to represent the semantic meaning of content, and vector search is for conceptually similar matches over that content. Here, the semantically meaningful fields are product_name, category, and description. Using those together supports natural-language search, while brand and price can be handled as structured filters outside the embedding itself. This is an inference from Microsoft's guidance that vector search works over embeddings representing content meaning, while filters remain part of the nonvector query pipeline.
The second statement is No . price changes multiple times per day and is a structured numeric attribute, not stable semantic content. Since the requirement already says customers can apply structured filters for brand and price , price does not need to be embedded into the text. Embedding volatile numeric values would also make embeddings stale faster without improving the semantic-search objective. This is again an inference grounded in Microsoft's distinction between vector similarity over content and filtering/sorting over nonvector fields.
The third statement is Yes . In SQL Server's vector type, the default underlying base type is float32 unless float16 is specified explicitly.
NEW QUESTION # 16
You have an Azure SQL database that contains a table named stores, stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
* Uses full-text search on description for the keyword portion
* Returns the top 20 results based on a combined score that uses a weighted formula of 60% vector distance and 40% full-text rank How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.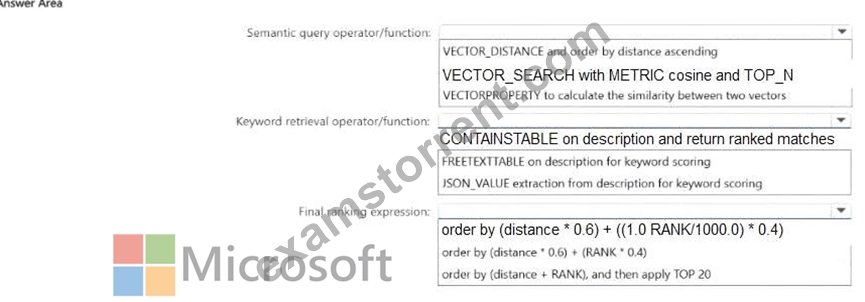
Answer:
Explanation: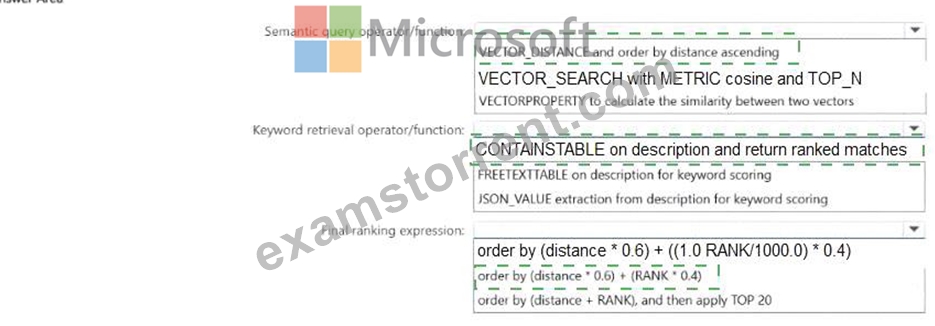
Explanation: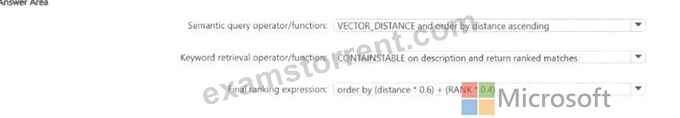
For the vector portion, the correct choice is VECTOR_DISTANCE and order by distance ascending . The requirement is to build a combined weighted formula using the actual vector distance. Microsoft documents that VECTOR_DISTANCE returns the exact distance between two vectors. Since lower distance means greater similarity, ascending distance is the right direction for ranking. VECTOR_SEARCH is for ANN retrieval, but this hotspot specifically asks for a weighted formula based on distance , so VECTOR_DISTANCE is the appropriate operator.
For the keyword portion, the correct choice is CONTAINSTABLE on description and return ranked matches . Microsoft documents that CONTAINSTABLE returns a RANK column from 0 through 1000 , which is exactly what is needed for weighted scoring in a hybrid formula.
For the final ranking expression, the best choice is order by (distance * 0.6) + ((1.0 - RANK/1000.0) * 0.4) .
This works because vector distance is a lower-is-better metric, while full-text RANK is a higher-is-better metric. Dividing RANK by 1000 normalizes it to the documented range, and subtracting from 1.0 converts it into a lower-is-better term so both components can be combined consistently in one ascending score. This final step is a sound inference based on Microsoft's documented distance semantics and full-text rank range.
NEW QUESTION # 17
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
Answer: C
Explanation:
The correct column to use for generating embeddings is incidentDescrlption because embeddings are intended to represent the semantic meaning of rich textual content , not simple categorical, numeric, or location-only values. Microsoft's DP-800 study guide explicitly includes skills such as identifying which columns to include in embeddings , generating embeddings , and implementing semantic vector search for scenarios where users need to find similar records based on meaning rather than exact matches.
In this scenario, analysts report that it is difficult to find similar incidents based on details such as weather, traffic conditions, and location . Those are descriptive context elements that are typically captured in a free- text incident description field. An embedding generated from incidentDescrlption can encode the semantic relationships among these narrative details, making it suitable for similarity search , semantic search , and RAG retrieval . Microsoft documentation on vectors and embeddings explains that embeddings are generated from text data and then stored for vector search to find semantically related items.
The other options are weaker choices:
* vehicleLocation is too narrow and usually better handled with geospatial filtering , not embeddings.
* incidentType is likely categorical and too low in semantic richness.
* SeverityScore is numeric and not appropriate as the primary source for semantic embeddings.
Microsoft also notes that when multiple useful attributes exist, you can either embed each text column separately or concatenate relevant text fields into one textual representation before generating the embedding.
But among the options given, the best and most exam-aligned answer is the textual narrative column :
incidentDescrlption .
NEW QUESTION # 18
You have a GitHub Codespaces environment that has GitHub Copilot Chat installed and is connected to a SQL database in Microsoft Fabric named DB1. DB1 contains tables named Sales.Orders and Sales.Customers.
You use GitHub Copilot Chat in the context of DB1.
A company policy prohibits sharing customer Personally Identifiable Information (PII), secrets, and query result sets with any AI service.
You need to use GitHub Copilot Chat to write and review Transact-SQL code for a new stored procedure that will join Sales.Orders to Sales.Customers and return customer names and email addresses. The solution must NOT share the actual data in the tables with GitHub Copilot Chat.
What should you do?
Answer: B
Explanation:
To use GitHub Copilot Chat effectively in this environment without exposing sensitive data, you should focus your prompts entirely on the schema and logic rather than the data itself.
Since Copilot Chat can "see" your open files, the best approach is to provide the table structures as DDL (Data Definition Language) statements or a simplified description.
Steps to generate the stored procedure:
Define the Schema: Open a new SQL file in your Codespace. Paste the CREATE TABLE scripts (without any data) for your two tables.
Prompt Copilot: Use the Chat view to request the procedure.
Example Prompt: "Based on the table definitions in my open file, write a T-SQL stored procedure that joins TableA and TableB on [Join Column]. Include logic to filter by [Parameter] and ensure no PII columns are included in the SELECT statement." Review for PII/Secrets: Before executing, manually verify that the generated code doesn't include hardcoded secrets or call PII columns you intended to omit.
Security Check: Because you are in a Codespace, ensure your .env files or connection strings are in your .gitignore so they aren't indexed by Copilot.
Reference:
https://github.com/orgs/community/discussions/141924
NEW QUESTION # 19
You have a database that contains production data. The schema is stored in a Git repository as an SDK-style SQL database project and contains the following reference data.
Name
Data type
RefID
int, identity
Code
nvarchar(10)
CreatedDate
datetime2
Description
nvarchar(255)
A deployment pipeline can be rerun automatically when a transient failure occurs.
You need to deploy the reference data as part of the same CI/CD process. Rerunning the pipeline must produce the same outcome and must NOT create duplicate rows.
What should you do?
Answer: B
NEW QUESTION # 20
......
The passing rate of our DP-800 exam materials are very high and about 99% and so usually the client will pass the exam successfully. But in case the client fails in the exam unfortunately we will refund the client immediately in full at one time. The refund procedures are very simple if you provide the DP-800 exam proof of the failure marks we will refund you immediately. Clients always wish that they can get immediate use after they buy our DP-800 Test Questions because their time to get prepared for the exam is limited. Our DP-800 test torrent won’t let the client wait for too much time and the client will receive the mails in 5-10 minutes sent by our system. Then the client can log in and use our software to learn immediately. It saves the client’s time.
Practice DP-800 Questions: https://www.examstorrent.com/DP-800-exam-dumps-torrent.html
2026 Latest ExamsTorrent DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1YDO_D3_uLf0LFINNECI1WPawueWBUnJB