We have free demo for AI-200 study guide for you to have a try, so that you can have a deeper understanding of what you are going to buy. The free domo will show you what the complete version for AI-200 exam dumps is like. Furthermore, with the outstanding experts to verify and examine the AI-200 Study Guide, the correctness and quality can be guaranteed. You can pass the exam by using the AI-200 exam dumps of us. You give us trust, we will ensure you to pass the exam.
| Section | Weight | Objectives |
|---|---|---|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
>> AI-200 Trustworthy Exam Content <<
Prep4away offers a free demo of the AI-200 exam dumps for customers to try out before purchasing. This allows individuals to examine the AI-200 exam prep material and make decisions. Customers will receive free updates to the AI-200 exam questions for three months if any changes are made to the Developing AI Cloud Solutions on Azure (AI-200) exam content after the purchase of the AI-200 Practice Questions. Prep4away has helped thousands of individuals worldwide in obtaining their AI-200 certification through their real AI-200 pdf dumps and practice tests. Passing the Developing AI Cloud Solutions on Azure (AI-200) exam on the first attempt can save individuals both time and money.
NEW QUESTION # 77
You deploy a production Azure Function app that connects to an Azure SQL Database.
The solution must provide the following functionality:
* Prevent secrets from being exposed in source control.
* Support secret rotation without redeploying the function app.
* Avoid downtime during credential updates.
You need to configure secure and maintainable secret management. What should you configure?
Answer: B
Explanation:
Detailed Explanation: Key Vault references in Function/App Service application settings keep the connection secret outside source control while allowing the platform to resolve it at runtime by identity. When a referenced secret version is not fixed, rotation can be picked up without rebuilding or redeploying the function code. `local.settings.json` is intended for local development and must not be used as a production secret store. A source-controlled parameter file or hard-coded connection string directly violates the security requirement.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Use Key Vault references for App Service and Functions
NEW QUESTION # 78
You store embeddings in a property named embedding in an Azure Cosmos DB for NoSQL container.
You must construct a vector similarity query that orders documents by similarity to the input embedding and returns only the top five results.
You need to construct the similarity query.
What should you do?
Answer: A
Explanation:
The query should limit the number of returned results by using TOP 5 together with ORDER BY VectorDistance(...) . Azure Cosmos DB for NoSQL provides the VectorDistance() system function for comparing a stored vector with an input query vector. Microsoft documents that a vector similarity query should order the results by VectorDistance so that the nearest matches are returned first.
A representative query is:
SELECT TOP 5
c.id,
VectorDistance(c.embedding, @embedding) AS SimilarityScore
FROM c
ORDER BY VectorDistance(c.embedding, @embedding)
Microsoft specifically recommends using a TOP N clause for vector search queries because returning more results than necessary increases RU consumption and latency. In this scenario, TOP 5 directly satisfies the requirement to return only the five most similar documents.
GROUP BY is used for aggregation and does not rank vectors by similarity. DISTINCT removes duplicate projected values but does not restrict results to the five nearest vectors. Offset pagination is unnecessary and can introduce additional query cost when only the highest-ranked five results are required.
Therefore, the correct action is to limit the number of results .
Study Guide references: Azure Cosmos DB for NoSQL # VectorDistance() ; vector search; ORDER BY ; TOP N ; RU and latency optimization.
NEW QUESTION # 79
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The query lists every individual request along with its result code.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
NEW QUESTION # 80
Drag and Drop Question
You plan to deploy a web application to AKS.
The solution must:
- Scale out the application by adding more pods during peak CPU usage.
- Expose the application internally within the cluster only.
You need to configure a Kubernetes resource for each requirement.
Which resources should you configure? To answer, move the appropriate resources to the correct requirements. You may use each resource once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.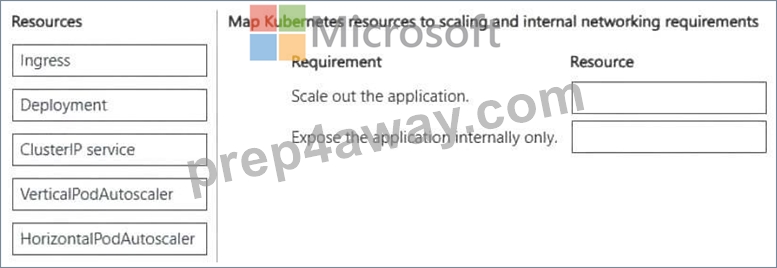
Answer:
Explanation: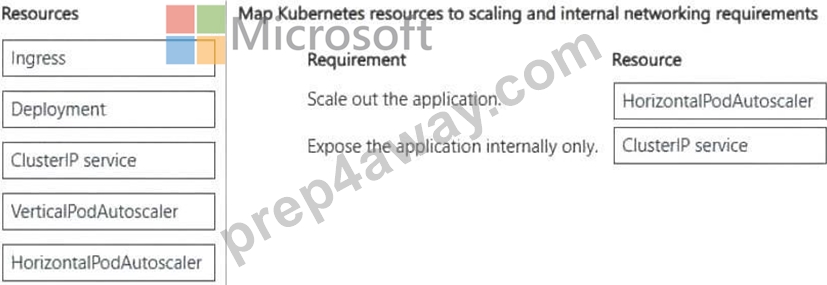
Explanation:
Box 1: HorizontalPodAutoscaler
Horizontal Pod Autoscaler (HPA) is the AKS feature to use. It automatically scales the number of pods in a deployment based on observed CPU utilization or other metrics.
Box 2: ClusterIP service
Use a ClusterIP service or internal LoadBalancer with annotations to expose your web application internally within an Azure Kubernetes Service (AKS) cluster only.
Reference:
https://learn.microsoft.com/en-us/azure/aks/optimize-aks-costs
https://learn.microsoft.com/en-us/azure/aks/concepts-network-services
NEW QUESTION # 81
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.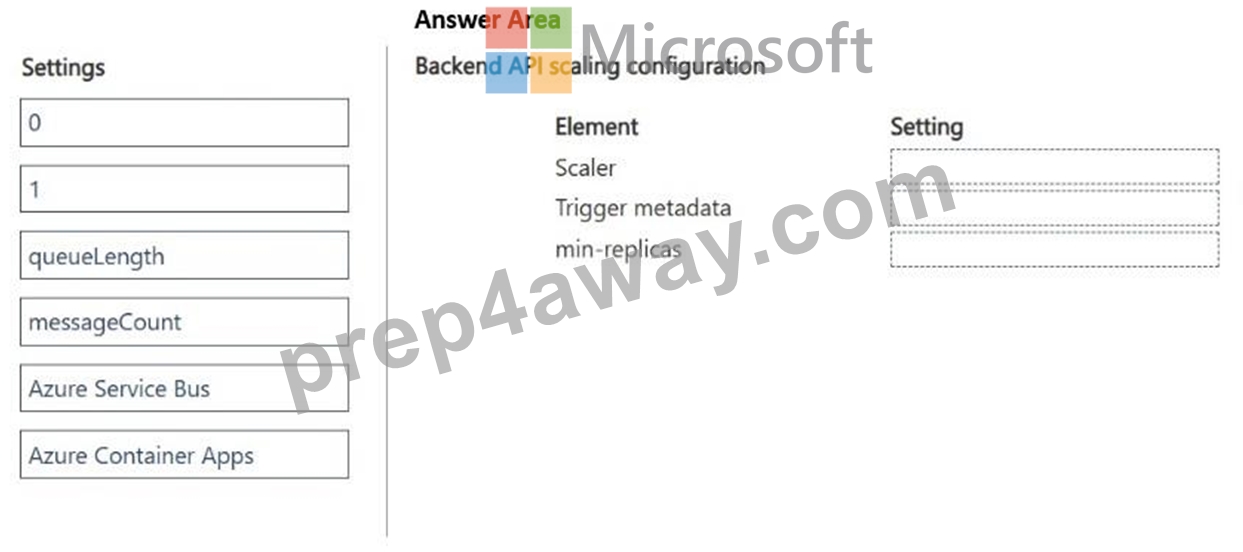
Answer:
Explanation: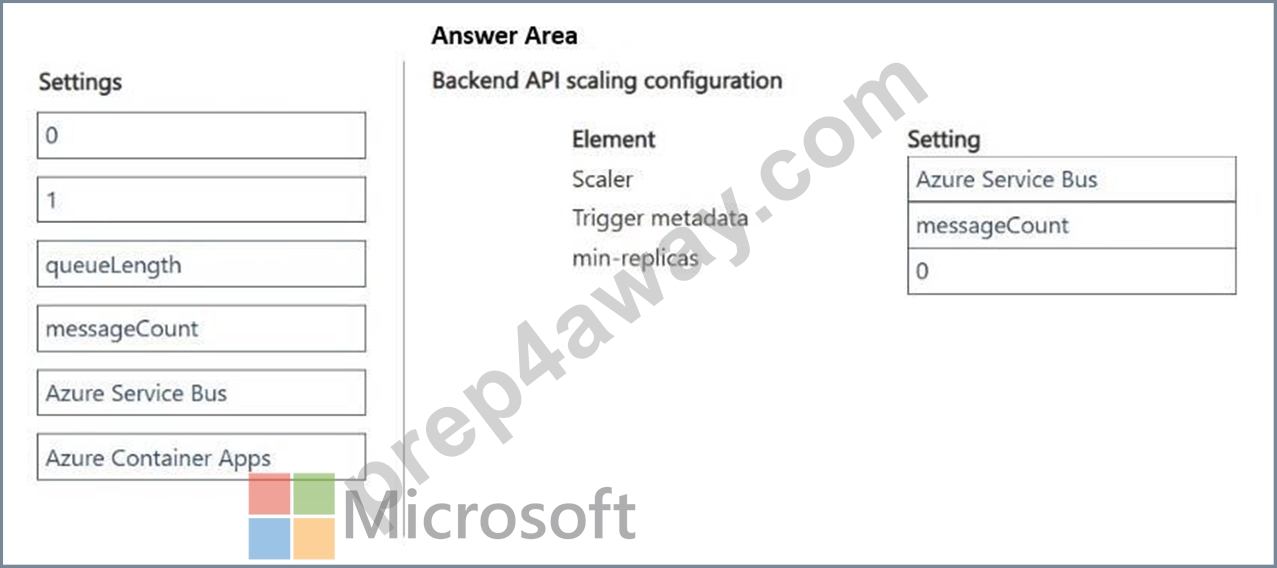
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 82
......
The 24/7 support team is just an e-mail away for our customers so that they can contact us anytime. Our team will solve all of their issues as quickly as possible. Free demos and up to 1 year of free updates of our Sitecore Exams are also available at Prep4away. Buy updated and Real AI-200 Exam Questions now and earn your dream AI-200 certification with Prep4away!
Valid AI-200 Exam Format: https://www.prep4away.com/Microsoft-certification/braindumps.AI-200.ete.file.html