試験の準備方法-効率的なCertified-Data-Engineer-Professional資格試験試験-信頼できるCertified-Data-Engineer-Professional対応内容

若者はより大きな雇用圧力に直面しています。競争力を高めることが不可欠です。私たちのCertified-Data-Engineer-Professional試験資料を選択することで、日々の仕事であなたの問題を解決できます。より実用的なスキルを得ることもできます。私たちのCertified-Data-Engineer-Professional試験資料には最新の知識と情報が含まれています。さらに、最も権威があるCertified-Data-Engineer-Professional認定試験資格証明書を取得することができます。だから、多くの人を引きつけます。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics
- Implement reliable streaming pipelines
|
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables
- Diagnose common pipeline and job failures
|
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data
- Apply advanced Spark transformations
|
| Security and Governance | ~10% | - Implement row-level security, column masking, and compliance
- Manage Unity Catalog permissions and ACLs
|
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs
- Implement scalable Python/SQL code and project structures
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
>> Certified-Data-Engineer-Professional資格試験 <<
Certified-Data-Engineer-Professional対応内容、Certified-Data-Engineer-Professional復習資料
安全かつ最も信頼性の高いDatabricks Certified-Data-Engineer-Professional問題集販売サイトとして、我々はお客様の個人情報を内緒し、支払いの安全性を保証しています。だから、我々社のDatabricks Certified-Data-Engineer-Professional問題集のさまざまなバージョンを安心に購買できます。弊社は量豊かのIT試験資料を所有するから、あなたは別のDatabricks Certified-Data-Engineer-Professional試験に関心を寄せるなら、ShikenPASSでは需要したい資料を尋ねたり、弊社の職員に問い合わせたりしています。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q178-Q183):
質問 # 178
A data engineer is performing a join operation to combine values from a static userlookup table with a streaming DataFrame streamingDF.
Which code block attempts to perform an invalid stream-static join?
- A. streamingDF.join(userLookup, ["user_id"], how="outer")
- B. userLookup.join(streamingDF, ["userid"], how="inner")
- C. streamingDF.join(userLookup, ["user_id"], how="left")
- D. streamingDF.join(userLookup, ["userid"], how="inner")
- E. userLookup.join(streamingDF, ["user_id"], how="right")
正解:A
解説:
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#support-matrix-for-joins-in-streaming-queries
質問 # 179
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete. Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
- A. Use the DESCRIBE TABLE command to extract existing schema information and manually write descriptions based on column names and data types.
- B. Write custom PySpark code using df.describe() and df.schema to programmatically generate basic statistical descriptions for each column.
- C. Navigate to the table in Databricks Catalog Explorer, select the table schema view, and use the AI Generate option which leverages artificial intelligence to automatically create meaningful column descriptions based on column names, data types, sample values, and data patterns.
- D. Use Delta Lake's DESCRIBE HISTORY command to analyze table evolution and infer column purposes from historical changes.
正解:C
解説:
The Catalog Explorer provides an AI-powered "AI Generate" capability that automatically creates intelligent column descriptions by analyzing column names, data types, sample values, and observed data patterns. This approach enables rapid, scalable documentation of existing tables, significantly improving data discoverability and compliance without manual effort.
質問 # 180
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema. Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
- A. GRANT USE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- B. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- C. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- D. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
正解:D
解説:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
質問 # 181
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
- B. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- C. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
- D. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date. - E. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
正解:B
解説:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
質問 # 182
A view is registered with the following code:
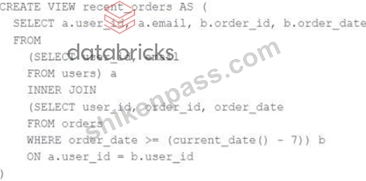
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. Results will be computed and cached when the view is defined; these cached results will incrementally update as new records are inserted into source tables.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- D. All logic will execute when the view is defined and store the result of joining tables to the DBFS; this stored data will be returned when the view is queried.
正解:C
質問 # 183
......
ユーザーのオフライン読書を促進するために、Certified-Data-Engineer-Professionalスタディブレインダンプは、特にユーザー向けのPDFモードを開発するために、破片の時間をより有効に活用して学習できます。このモードでは、ユーザーは学習教材内のCertified-Data-Engineer-Professional準備ガイドをダウンロードして印刷することができ、紙にメモを取るのが簡単で、記憶の弱いリンクがあり、すべてのユーザーが無制限の数の学習をダウンロードして大幅に改善できますCertified-Data-Engineer-Professional試験問題を使用したユーザーの効率。 Certified-Data-Engineer-Professional準備ガイドは、この点でユーザーの需要を満たすのに非常に役立ち、ユーザーが学習した内容を継続的に統合して良い環境で読み書きできるようにします。
Certified-Data-Engineer-Professional対応内容: https://www.shikenpass.com/Certified-Data-Engineer-Professional-shiken.html
- Certified-Data-Engineer-Professional資格認定 💎 Certified-Data-Engineer-Professional的中率 🪐 Certified-Data-Engineer-Professional的中関連問題 😳 今すぐ[ www.goshiken.com ]で⏩ Certified-Data-Engineer-Professional ⏪を検索して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional学習資料
- Certified-Data-Engineer-Professionalソフトウエア 🟦 Certified-Data-Engineer-Professionalソフトウエア ⛵ Certified-Data-Engineer-Professional復習教材 🏬 ✔ www.goshiken.com ️✔️で➥ Certified-Data-Engineer-Professional 🡄を検索して、無料で簡単にダウンロードできますCertified-Data-Engineer-Professional対策学習
- 効果的Databricks Certified-Data-Engineer-Professional|100%合格率のCertified-Data-Engineer-Professional資格試験試験|試験の準備方法Databricks Certified Data Engineer Professional対応内容 🎅 ➡ www.mogiexam.com ️⬅️で使える無料オンライン版⏩ Certified-Data-Engineer-Professional ⏪ の試験問題Certified-Data-Engineer-Professional学習資料
- はじめての Databricks 超入門 Certified-Data-Engineer-Professional 試験問題 ⛪ ⮆ www.goshiken.com ⮄は、「 Certified-Data-Engineer-Professional 」を無料でダウンロードするのに最適なサイトですCertified-Data-Engineer-Professionalソフトウエア
- ユニーク-便利なCertified-Data-Engineer-Professional資格試験試験-試験の準備方法Certified-Data-Engineer-Professional対応内容 🥄 ➡ www.xhs1991.com ️⬅️で《 Certified-Data-Engineer-Professional 》を検索して、無料で簡単にダウンロードできますCertified-Data-Engineer-Professional関連試験
- 試験の準備方法-最高のCertified-Data-Engineer-Professional資格試験試験-信頼できるCertified-Data-Engineer-Professional対応内容 🍝 サイト{ www.goshiken.com }で( Certified-Data-Engineer-Professional )問題集をダウンロードCertified-Data-Engineer-Professional資格取得講座
- Certified-Data-Engineer-Professional対策学習 🌠 Certified-Data-Engineer-Professional全真問題集 🪂 Certified-Data-Engineer-Professional問題集 😸 ⮆ Certified-Data-Engineer-Professional ⮄を無料でダウンロード【 www.mogiexam.com 】ウェブサイトを入力するだけCertified-Data-Engineer-Professionalトレーニング資料
- はじめての Databricks 超入門 Certified-Data-Engineer-Professional 試験問題 ✋ [ www.goshiken.com ]の無料ダウンロード▷ Certified-Data-Engineer-Professional ◁ページが開きますCertified-Data-Engineer-Professional問題集
- Certified-Data-Engineer-Professional日本語復習赤本 🩸 Certified-Data-Engineer-Professional全真問題集 🥽 Certified-Data-Engineer-Professional日本語復習赤本 🤧 ▶ Certified-Data-Engineer-Professional ◀を無料でダウンロード➤ www.xhs1991.com ⮘で検索するだけCertified-Data-Engineer-Professional問題集
- Certified-Data-Engineer-Professional無料問題 🚙 Certified-Data-Engineer-Professional資格認定 ❗ Certified-Data-Engineer-Professional無料問題 😅 { www.goshiken.com }には無料の[ Certified-Data-Engineer-Professional ]問題集がありますCertified-Data-Engineer-Professional問題集
- 効果的Databricks Certified-Data-Engineer-Professional|100%合格率のCertified-Data-Engineer-Professional資格試験試験|試験の準備方法Databricks Certified Data Engineer Professional対応内容 🔖 “ www.passtest.jp ”に移動し、➤ Certified-Data-Engineer-Professional ⮘を検索して、無料でダウンロード可能な試験資料を探しますCertified-Data-Engineer-Professionalソフトウエア
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, everlink.tools, fortunetelleroracle.com, www.stes.tyc.edu.tw, poi-australia.com.au, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes