Die Microsoft AI-200 Dumps von It-Pruefung können Ihnen helfen, diese Prüfung sehr einfach zu bestehen. Außerdem, wenn Sie zum ersten Mal die Microsoft AI-200 Prüfung teilnehmen, können Sie diese Dumps von Software-Version benutzen, weil es ist eine Software, die für Sie die Inhalte und die Forme der aktuellen Prüfung simulieren. Sie können sich die aktuelle Prüfung zuvor fühlen. Danach können Sie sich nicht nervös fühlen bei der aktuellen Prüfung. Sie können auch sehr sorglos an dieser Microsoft AI-200 Prüfung teilnehmen. Und es ist auch wichtig für Sie, Ihr normales Niveau in der AI-200 Prüfung zu entfalten.
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
>> AI-200 Zertifizierungsprüfung <<
Wir hoffen, dass sich alle Ihrer in der Microsoft AI-200 Prüfungssoftware gesetzten Erwartungen erfüllen können. Die Vollständigkeit und Autorität der Test-Bank, Vielfältigkeit der Versionen von Unterlagen---- Es gibt 3 Versionen, nämlich PDF, Online Test Engine und Practice Testing Engine, und auch die kostenlose Demo und einjährige Aktualisierung der Microsoft AI-200 Software, alles enthält unsere herzlichste Anstrengungen!
44. Frage
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to configure image builds for a new service to meet the technical requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Antwort: A,E
Begründung:
Technical requirements, CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
The two best actions to meet the requirements are to create and configure an ACR Task with a source repository context and then push updated code to the source repository.
The core constraint explicitly dictates using ACR Tasks to automate image builds triggered by source code commits.
[D] Create and configure an ACR Task with a source repository context: This step directly establishes the automation hook. By defining the repository context (such as GitHub or Azure Repos) during task creation, Azure Container Registry is instructed exactly where to watch for code modifications.
[F] Push updated code to the source repository: Once the ACR Task is configured with the source repository context, pushing new commits acts as the native trigger. ACR automatically intercepts the commit webhook, spins up a transient cloud agent, builds the Python container image via the Dockerfile, and pushes it directly into your registry.
Reference:
https://learn.microsoft.com/en-us/azure/container-registry/container-registry-tasks-overview
45. Frage
You are implementing the expiration requirement for AI-generated summaries in the Redis cache.
You need to purge the AI summaries five minutes after creation, regardless of how often they are accessed.
What should you do?
Antwort: C
Begründung:
TTL (Time-To-Live) with a fixed duration of five minutes is the exact Redis feature you need to purge AI-generated summaries regardless of access frequency.
Redis TTL and Expiration Features
Core Expiration Feature
EXPIRE command: Sets a timeout in seconds on a key. Use EXPIRE key 300 to remove the summary after 300 seconds (five minutes).
PX command: Sets a timeout in milliseconds. Use PX key 300000 for precise millisecond control.
EXPIREAT / PEXPIREAT: Sets an absolute Unix timestamp for expiration instead of a relative duration.
Reference:
https://dev.to/truongpx396/30-common-redis-interview-questions-1ai
46. Frage
Drag and Drop Question
You have a newly provisioned Azure subscription. You are designing a custom Event Grid workflow for AI inference events.
You need to implement the Event Grid components to support routing of high-confidence events to a downstream processor.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.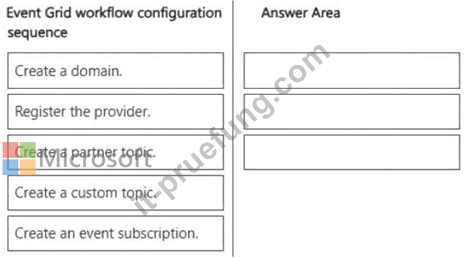
Antwort:
Begründung: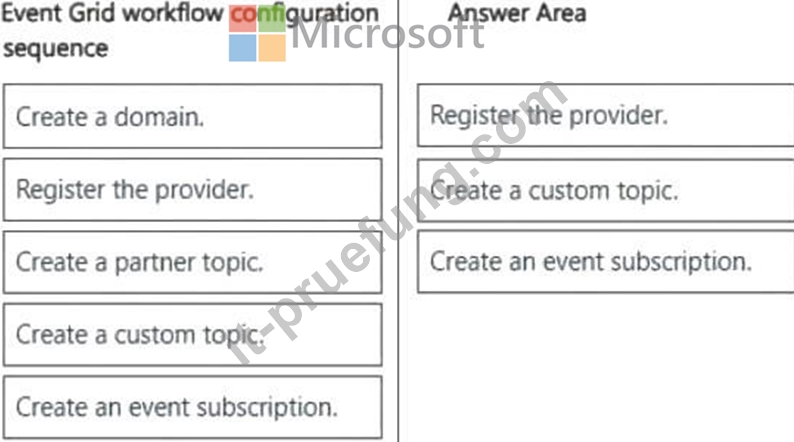
Explanation:
Step 1: Register a provider
Because this is a newly provisioned Azure subscription, you must register the Microsoft.EventGrid resource provider before you can deploy any Event Grid components.
Step 2: Create a custom topic
Since you are routing AI inference events originating from your application, you need to create a custom topic to act as the endpoint where these events are sent.
Step 3: Create an event subscription
You must create an event subscription to define the routing rules. This is where you configure filtering to ensure only high-confidence events are directed to your downstream processor.
Reference:
https://www.c-sharpcorner.com/article/building-event-driven-ai-workflows-with-azure-event-grid-and-net/
47. Frage
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.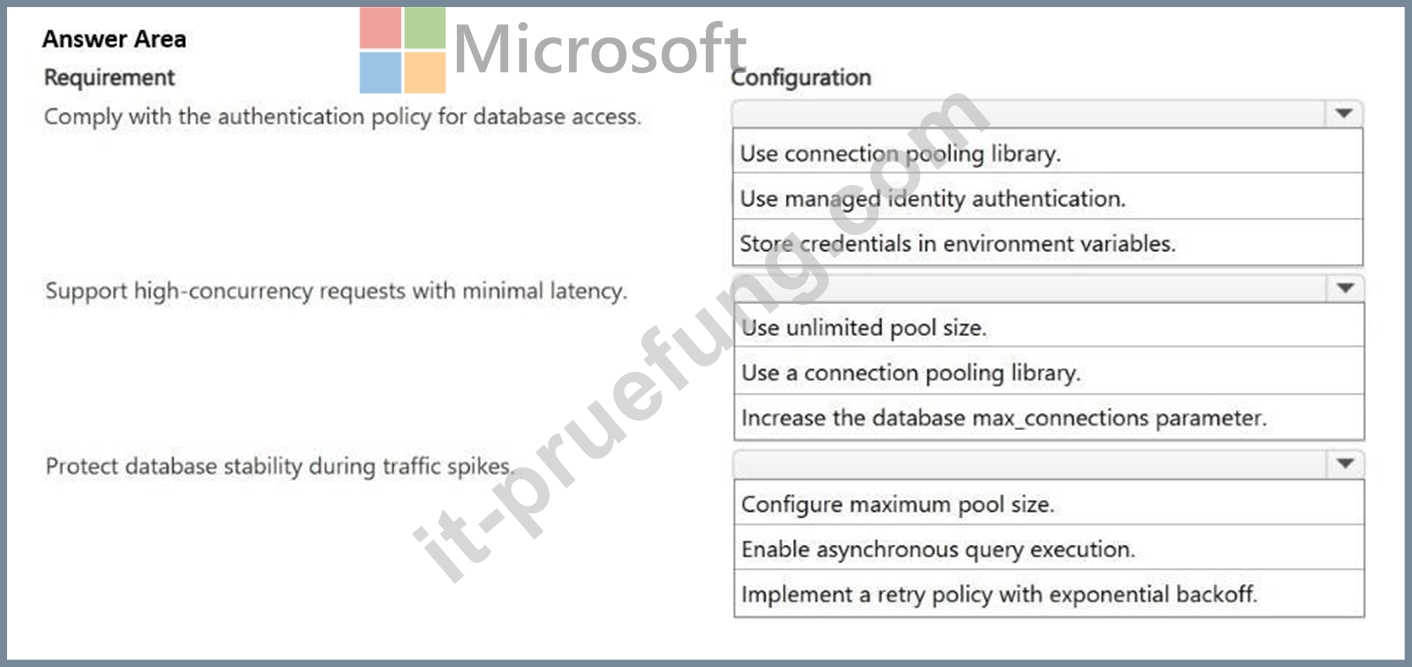
Antwort:
Begründung: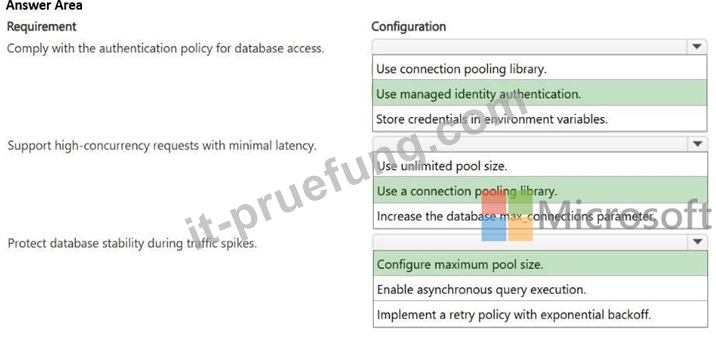
Explanation:
Box 1: Use managed identity authentication.
Scenario: Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited.' Box 2: Use a connection pooling library Scenario: Environment: Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
To support high-concurrency requests with minimal latency on Azure Database for PostgreSQL, the best action is to use a connection pooling library (or leverage Azure's built-in PgBouncer feature).
Eliminates Connection Overhead:
PostgreSQL utilizes a process-per-connection model. Forking a new backend process for every incoming request introduces substantial CPU and memory overhead, severely degrading latency under high concurrency. A connection pool keeps a warm set of reusable database sessions active.
Optimized for Azure: Microsoft provides a built-in managed PgBouncer integration for Azure Database for PostgreSQL. Enabling it in transaction mode allows the database to accept thousands of concurrent client connections while keeping actual backend processes lean and stable Box 3: Configure a maximum pool size Configure a maximum pool size is the best action to directly protect database stability during sudden traffic spikes.
Prevents Resource Exhaustion: Traffic spikes naturally lead to a surge in connection requests.
Unchecked connections consume substantial RAM and CPU overhead, which can crash the database or trigger severe latency. Limiting the pool size stops the "thundering herd" problem Acts as a Shock Absorber: When the pool hits its maximum limit, extra client requests are safely queued at the application or connection pooling layer (like Azure's built-in PgBouncer proxy) rather than overwhelming the database backend Reference:
https://docs.azure.cn/en-us/postgresql/connectivity/concepts-pgbouncer
https://learn.microsoft.com/en-au/answers/questions/5884412/best-practise-azure-postgresql-flexible-server-max
48. Frage
A customer support bot built with Azure AI Foundry Agent Service must ground its answers strictly in an internal knowledge base and avoid hallucinating unsupported facts.
What should you implement?
Antwort: D
Begründung:
Connect the agent to an Azure AI Search knowledge source and explicitly constrain its instructions to answer from retrieved evidence. Microsoft Foundry Agent Service can use Azure AI Search to retrieve proprietary organizational content and ground model responses in that content. Retrieved documents provide the factual context from which the model generates its answer, and Azure AI Search can return source references for attribution.
Microsoft ' s RAG guidance also specifically recommends using clear system instructions that require the model to stay within retrieved content when hallucination risk must be reduced. If the available evidence does not support an answer, the instructions should direct the agent to state that the information is unavailable rather than inventing facts. Retrieval grounding substantially reduces unsupported generation, although production systems should still evaluate outputs because grounding alone does not mathematically guarantee zero hallucinations.
Increasing temperature would generally increase output variability and is contrary to the objective. A larger context window without retrieval does not give the model access to the organization ' s internal knowledge base. Disabling content filtering weakens safety controls and has no role in factual grounding.
Study Guide references: Microsoft Foundry Agent Service # Azure AI Search tool; RAG grounding; knowledge sources; source attribution; grounding instructions.
49. Frage
......
Wenn Sie Ihre Position in der konkurrenzfähigen Gesellschaft durch die Microsoft AI-200 Zertifizierungsprüfung festigen und Ihre fachliche Fähigkeiten verbessern wollen, müssen Sie gute Fachkenntnisse besitzen und sich viel Mühe für die Prüfung geben. Aber es ist nicht so einfach, die Microsoft AI-200 Zertifizierungsprüfung zu bestehen. Vielleicht durch die Microsoft AI-200 Zertifizierungsprüfung können Sie Ihnen der IT-Branche vorstellen. Aber man braucht nicht unbedingt viel Zeit und Energie, die Fachkenntnisse kennenzulernen. Sie können die Schulungsunterlagen zur Microsoft AI-200 Zertifizierungsprüfung von It-Pruefung wählen. Sie werden zielgerichtet nach den IT-Zertifizierungsprüfungen entwickelt. Mit ihr können Sie mühelos die schwierige Microsoft AI-200 Zertifizierungsprüfung bestehen.
AI-200 Unterlage: https://www.it-pruefung.com/AI-200.html