Pass4sures SPS-C01 test questions materials will guide you and help you to pass the certification exams in one shot. If you want to know our SPS-C01 test questions materials, you can download our free demo now. Our demo is a small part of the complete charged version. Also you can ask us any questions about Snowflake SPS-C01 Exam any time as you like.
| Section | Objectives |
|---|---|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
It's not easy for most people to get the SPS-C01 guide torrent, but I believe that you can easily and efficiently obtain qualification certificates as long as you choose our products. After you choose our study materials, you can master the examination point from the SPS-C01 Guide question. Then, you will have enough confidence to pass your exam. As for the safe environment and effective product, why don’t you have a try for our SPS-C01 question torrent, never let you down!
NEW QUESTION # 226
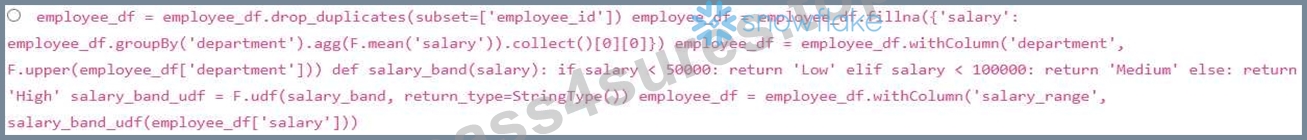
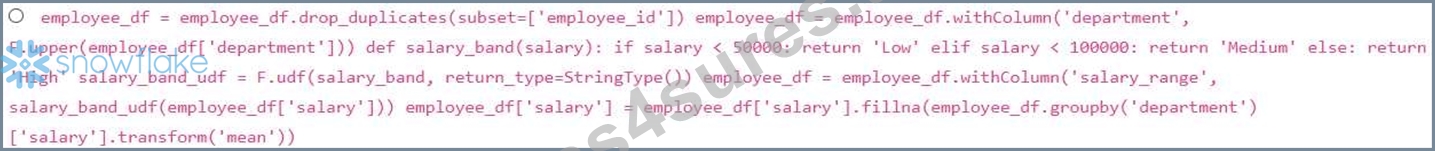
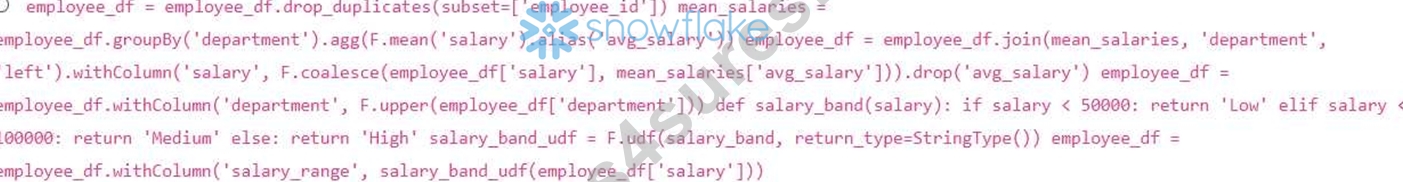
You are using Snowpark to process a DataFrame 'employee df containing employee data, including 'employee_id', 'name' , 'department' , and 'salary'. You need to implement a complex data cleaning and transformation pipeline that involves the following steps: 1. Remove duplicate rows based on 'employee id'. 2. Fill missing 'salary' values with the average salary for the employee's department. 3. Standardize department names by converting them to uppercase. 4. Create a new column 'salary_range' based on the salary. if Salary less than 50k 'Low', greater than 50k and less than 100k 'Medium', greater than 100k 'High'. Which of the following code snippets MOST effectively combines these transformations into a single, readable, and efficient Snowpark pipeline? Assume you have a session object available named 'session' and import necessary modules from 'snowflake.snowpark.functions as F'


Answer: B
Explanation:
Option E is the most efficient and recommended solution for the following reasons: Window Function for Filling Missing Salaries : It uses a window function ('Window.partitionBy('department')') to calculate the average salary for each department efficiently. This is more performant than joining with an aggregated DataFrame or collecting data to the client. No Client-Side Data Handling : All transformations are performed within Snowflake using Snowpark DataFrame operations. This avoids bringing data to the client, which is crucial for performance. Concise 'salary_range' Logic : It uses 'F.when' to define the 'salary_range' column in a concise and readable manner. The chained 'when' calls are a standard way to define conditional column values. Avoids UDF when not Necessary : It avoids using a UDF for calculating 'salary_range' , which generally has overhead compared to built-in functions. Option A computes the average salaries for each department and join again to the original dataframe, which requires more resources. Using UDF is also less performant when there is function available. Option B does not fill nulls before creating salary ranges. Option C collect data on Client side and is inefficient. Option D fillna method is not available and again, the UDF is less performant as it is not necessary.
NEW QUESTION # 227
You are developing a Snowpark Python application to process streaming data from a Kafka topic, enrich it with data from a Snowflake table, and store the results in another Snowflake table. The enrichment process involves joining the streaming data with a large dimension table in Snowflake. Which of the following Snowpark features would be most efficient and scalable for this use case, considering the continuous nature of the streaming data and the size of the dimension table?
Answer: C
Explanation:
Dynamic tables are designed for incremental data transformations, which is ideal for continuous streaming data processing and joining with a large dimension table. They automatically manage data refreshes and optimize performance for incremental updates, making them the most efficient and scalable option. Option A might work for small datasets, but it doesn't scale well with larger dimension tables or sustained streaming. Option B is generally inefficient for large-scale joins. Option C adds unnecessary complexity and latency due to the periodic refresh. Option D is not well-suited for true streaming as it relies on landing data into a static table first.
NEW QUESTION # 228
You are tasked with optimizing a Snowpark Python application that performs complex data transformations on a large dataset. The application is running slower than expected, and you suspect that data serialization and transfer between the Snowpark client and the Snowflake engine are bottlenecks. Which of the following strategies could you implement to improve performance? (Select all that apply.)
Answer: A,B,D
Explanation:
Options A, B, and C are correct strategies. Pushing down computation (A) reduces data transfer. Using smaller batch sizes (B) can reduce memory pressure, especially for large datasets. Using temporary tables (C) allows intermediate results to be stored and processed entirely within Snowflake, avoiding unnecessary data transfer. Option D is incorrect because converting to Pandas DataFrames brings the data to the client, negating the benefits of Snowpark's distributed processing. Option E is dangerous since it could cause bottleneck if the resources are not managed correctly.
NEW QUESTION # 229
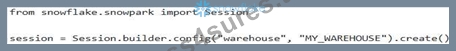
You are tasked with creating a Snowpark session that utilizes a specific Snowflake warehouse for all operations. Which of the following code snippets BEST demonstrates how to correctly specify the 'warehouse' parameter when creating a session using snowpark.Session.builder.configs'?


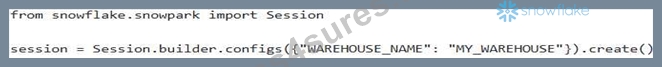
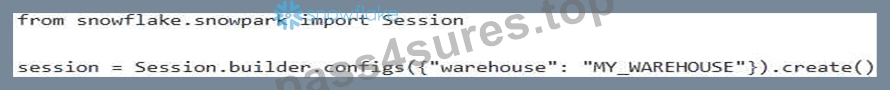
Answer: E
Explanation:
The correct parameter name for specifying the warehouse in the 'configs' dictionary is 'warehouse'. The other options either use incorrect key names (SNOWFLAKE_WAREHOUSE, snowflake.warehouse, WAREHOUSE_NAME) or an incorrect method call (.config instead of .configs). The code snippets provided demonstrate the correct and incorrect methods for specifying the warehouse parameter during Snowpark session creation. Option A correctly utilizes the 'warehouse' parameter within the 'configs' dictionary passed to the Session builder.
NEW QUESTION # 230
You are working with a Snowpark DataFrame 'transactions df that contains customer transaction data'. This data includes a 'transaction amount' column and a 'transaction date' column. You need to create a new feature called 'is weekend transaction' that indicates whether a transaction occurred on a weekend (Saturday or Sunday). Furthermore, some 'transaction_date' values are missing. You want to impute the missing dates with the mode (most frequent date) before determining if the transaction occurred on a weekend. Which of the following steps, when combined, provide the correct and most efficient approach to achieve this?
Answer: B
Explanation:
Option B is the most efficient and utilizes Snowpark's built-in capabilities. It calculates the mode using Snowpark's aggregation functions, fills missing values using and leverages the function to determine weekend status without the need for a UDF. Option A creates a UDF which is less efficient than using a built-in function. Option C replaces with an arbitary string which is bad as its hardcoding and not efficient, after filling the value a UDF is made which is not efficient as well, Also after that the data has to converted back, thus option C is not correct. Options D is more complex as it utilizes temporary table which is not efficient. Option E create a UDF when snowpark provides readily available functions. so its less efficient.
NEW QUESTION # 231
......
If you are the first time to buy the SPS-C01 learning material online, or you have bought them for many times, there may be some problem that puzzle you, if you have any questions about the SPS-C01 exam dumps, you can ask our service stuff for help. They have the professional knowledge of SPS-C01 Training Materials, and they will be very helpful for solving your problem. In addition, we have free demo for you to try before buying the product, and you can have a try before purchasing.
SPS-C01 Test Collection: https://www.pass4sures.top/Snowflake-Certification/SPS-C01-testking-braindumps.html