Certified-Data-Engineer-Professional Practice Exam Fee - Exam Certified-Data-Engineer-Professional PDF

2026 Latest PracticeMaterial Certified-Data-Engineer-Professional PDF Dumps and Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=1Cg8g2QXXT3lV_nfAYUOYcz3LPDLlomFO
In this social-cultural environment, the Certified-Data-Engineer-Professional certificates mean a lot especially for exam candidates like you. To some extent, these Certified-Data-Engineer-Professional certificates may determine your future. With respect to your worries about the practice exam, we recommend our Certified-Data-Engineer-Professional Preparation materials which have a strong bearing on the outcomes dramatically. For a better understanding of their features, please follow our website and try on them.
| Section | Objectives |
|---|
| Topic 1: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Topic 2: Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Topic 3: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 4: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 2. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 3. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
|
| Topic 5: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 8: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 9: Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Topic 10: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
>> Certified-Data-Engineer-Professional Practice Exam Fee <<
Exam Certified-Data-Engineer-Professional PDF, Certified-Data-Engineer-Professional Exam Tutorials
We will definitely not live up to the trust of users in our Certified-Data-Engineer-Professional study materials. As you know, the users of our Certified-Data-Engineer-Professional exam questions are all over the world. We have also been demanding ourselves with the highest international standards to support our Certified-Data-Engineer-Professional training guide in every aspect. First of all, our system is very advanced and will not let your information leak out. It is totally safe to visit our website and buy our Certified-Data-Engineer-Professional learning prep. You won't worry anything with our services.
Databricks Certified Data Engineer Professional Sample Questions (Q203-Q208):
NEW QUESTION # 203
A data engineer is optimizing a MERGE operation on an 800GB UC-managed table that experiences frequent updates and deletions. Which two actions should the engineer prioritize to improve MERGE performance? (Choose two.)
- A. Overwrite the table instead of Merge.
- B. Use ZORDER on high-cardinality columns.
- C. Partition the table by date.
- D. Enable deletion vectors on the table if not already enabled.
- E. Apply liquid clustering using the merge join keys.
Answer: D,E
Explanation:
Liquid clustering on the merge join keys improves data locality and reduces the amount of data scanned during MERGE operations, which is especially effective for large, frequently updated tables. Enabling deletion vectors avoids rewriting entire Parquet files for updates and deletes, significantly reducing I/O and improving MERGE performance on Unity Catalog-managed tables.
NEW QUESTION # 204
A data engineer is configuring Delta Sharing for a Databricks-to-Databricks scenario to optimize read performance. The recipient needs to perform time travel queries and streaming reads on shared sales data. Which configuration will provide the optimal performance while enabling these capabilities?
- A. Use the open sharing protocol instead of Databricks-to-Databricks sharing for better performance.
- B. Share tables WITH HISTORY, ensure tables don't have partitioning enabled, and enable CDF before sharing.
- C. Share the entire schema WITHOUT HISTORY and rely on recipient-side caching for performance.
- D. Share tables WITHOUT HISTORY and enable partitioning for better query performance.
Answer: B
Explanation:
The official Delta Sharing guidance specifies that in order for recipients to use time travel queries and streaming reads, providers must share Delta tables WITH HISTORY. Sharing history ensures the Delta log is included, which enables efficient access to table snapshots and incremental data streams.
Additionally, Change Data Feed (CDF) must be enabled prior to sharing if downstream consumers require streaming CDC queries. Without history, recipients cannot perform time travel or streaming queries. Open sharing supports static Delta tables but lacks streaming support.
Therefore, sharing tables WITH HISTORY and enabling CDF is the required configuration for both performance and functionality.
NEW QUESTION # 205
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
- B. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
- C. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
- D. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
Answer: C
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 206
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
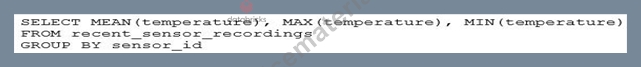
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
- A. The source query failed to update properly for three consecutive minutes and then restarted
- B. The maximum temperature recording for at least one sensor exceeded 120 on three consecutive executions of the query
- C. The average temperature recordings for at least one sensor exceeded 120 on three consecutive executions of the query
- D. The total average temperature across all sensors exceeded 120 on three consecutive executions of the query
- E. The recent_sensor_recordingstable was unresponsive for three consecutive runs of the query
Answer: C
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120.
NEW QUESTION # 207
A data engineer is designing a secure data sharing strategy for their organization. The company needs to share sensitive customer analytics data with two different partners. Partner A uses Databricks with Unity Catalog enabled, while Partner B uses Apache Spark on AWS without Databricks. How should the company implement secure data sharing for these scenarios?
- A. Both partners should use the same Delta Sharing approach since security requirements are identical. You should create bearer tokens for both partners and use the open sharing protocol (D2O) for maximum compatibility.
- B. For Partner A, implement Databricks-to-Databricks sharing (D2D) with Unit Catalog integration and no-token exchange system. For Partner B, use open sharing protocol (D2O) with either bearer tokens or OIDC federation for authentication, ensuring both approaches maintain robust security and governance.
- C. Databricks-to-Databricks sharing (D2D) can only be used within the same cloud provider, so you must use open sharing (D2O) for any cross-cloud scenarios. Unit Catalog governance is not available when sharing with external platforms.
- D. Open sharing protocol (D2O) should be used for both partners because it provides better security than D2D sharing. The bearer token approach is always more secure than Unity Catalog's native authentication.
Answer: B
Explanation:
Databricks-to-Databricks sharing with Unity Catalog provides the most seamless and secure option for Partner A by enabling native governance, fine-grained access controls, and a no-token exchange model. For Partner B, which does not use Databricks, the open sharing protocol enables secure access from external Spark environments using standard authentication mechanisms such as bearer tokens or OIDC federation, while still enforcing sharing policies and protecting sensitive data.
NEW QUESTION # 208
......
That is the reason PracticeMaterial has compiled a triple-formatted Certified-Data-Engineer-Professional exam study material that fulfills almost all of your preparation needs. The Databricks Certified-Data-Engineer-Professional Practice Testis compiled under the supervision of 90,000 Databricks professionals that assure the passing of the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam on your first attempt. The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exam consists of a Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) PDF dumps format, Desktop-based Certified-Data-Engineer-Professional practice test software and a Web-based Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exam.
Exam Certified-Data-Engineer-Professional PDF: https://www.practicematerial.com/Certified-Data-Engineer-Professional-exam-materials.html
- Authoritative Certified-Data-Engineer-Professional Practice Exam Fee - Find Shortcut to Pass Certified-Data-Engineer-Professional Exam 🙉 Go to website ➤ www.torrentvce.com ⮘ open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 🍴Certified-Data-Engineer-Professional Exam Dumps
- Authoritative Certified-Data-Engineer-Professional Practice Exam Fee - Find Shortcut to Pass Certified-Data-Engineer-Professional Exam 🏈 Easily obtain ➤ Certified-Data-Engineer-Professional ⮘ for free download through ☀ www.pdfvce.com ️☀️ 😍Certified-Data-Engineer-Professional Valid Mock Exam
- Trusting Reliable Certified-Data-Engineer-Professional Practice Exam Fee Is The Quickest Way to Pass Databricks Certified Data Engineer Professional 🍁 Enter ▷ www.prepawayexam.com ◁ and search for ▷ Certified-Data-Engineer-Professional ◁ to download for free 🥕Exam Certified-Data-Engineer-Professional Course
- Reliable Certified-Data-Engineer-Professional Test Prep 🦱 Certified-Data-Engineer-Professional Practice Exam Pdf 🧵 Exam Certified-Data-Engineer-Professional Course ❇ ( www.pdfvce.com ) is best website to obtain 【 Certified-Data-Engineer-Professional 】 for free download 🐜Latest Certified-Data-Engineer-Professional Test Pass4sure
- Test Certified-Data-Engineer-Professional Questions Fee ⏳ Valid Dumps Certified-Data-Engineer-Professional Ppt 🐈 Certified-Data-Engineer-Professional Study Tool 👟 Simply search for “ Certified-Data-Engineer-Professional ” for free download on ⏩ www.practicevce.com ⏪ 🦧Latest Certified-Data-Engineer-Professional Test Pass4sure
- 100% Pass Quiz 2026 Databricks Fantastic Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Practice Exam Fee 🎼 Search on ▶ www.pdfvce.com ◀ for 「 Certified-Data-Engineer-Professional 」 to obtain exam materials for free download 🐁Reliable Certified-Data-Engineer-Professional Test Prep
- Vce Certified-Data-Engineer-Professional Format 📂 Certified-Data-Engineer-Professional Study Tool 📄 Certified-Data-Engineer-Professional Best Practice 🧷 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download exam materials for free through 【 www.dumpsmaterials.com 】 🍼Test Certified-Data-Engineer-Professional Questions Fee
- Trusting Reliable Certified-Data-Engineer-Professional Practice Exam Fee Is The Quickest Way to Pass Databricks Certified Data Engineer Professional 🛂 Search on ⇛ www.pdfvce.com ⇚ for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain exam materials for free download 🎅Reliable Certified-Data-Engineer-Professional Exam Materials
- Certified-Data-Engineer-Professional Exam Sims ❎ Certified-Data-Engineer-Professional Certificate Exam 🕔 Valid Dumps Certified-Data-Engineer-Professional Ppt 📦 Easily obtain free download of ⇛ Certified-Data-Engineer-Professional ⇚ by searching on { www.prepawayexam.com } 🗯Reliable Certified-Data-Engineer-Professional Exam Materials
- Free PDF Databricks - Certified-Data-Engineer-Professional - Professional Databricks Certified Data Engineer Professional Practice Exam Fee 🚔 Easily obtain free download of ⮆ Certified-Data-Engineer-Professional ⮄ by searching on ➥ www.pdfvce.com 🡄 🥓Certified-Data-Engineer-Professional Exam Sims
- Certified-Data-Engineer-Professional Exam Dumps Pdf 🍽 Certified-Data-Engineer-Professional Exam Sims 🌻 Exam Certified-Data-Engineer-Professional Course 🚔 Copy URL ➥ www.practicevce.com 🡄 open and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 👝Certified-Data-Engineer-Professional Practice Questions
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, github.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PracticeMaterial: https://drive.google.com/open?id=1Cg8g2QXXT3lV_nfAYUOYcz3LPDLlomFO