P.S. Fast2test在Google Drive上分享了免費的2026 Nutanix NCM-MCI考試題庫:https://drive.google.com/open?id=1V79W_dNQfW8pdm0weQsLPKF060Sl7gu-
想要通過Nutanix的NCM-MCI考試並取得NCM-MCI的認證資格嗎?Fast2test可以保證你的成功。準備考試的時候學習與考試相關的知識是很有必要的。但是,更重要的是,要選擇適合自己的高效率的工具。Fast2test的NCM-MCI考古題就是適合你的最好的學習方法。這個高品質的考古題可以讓你看到不可思議的效果。如果你擔心自己不能通過考試,快點擊Fast2test的網站瞭解更多的資訊吧。
| Certification Vendor: | Nutanix |
|---|---|
| Exam Name: | Nutanix Certified Master - Multicloud Infrastructure v6.10 |
| Exam Number: | NCM-MCI-6.10 |
| Passing Score: | 3000 (scale 1000–6000) |
| Available Languages: | English |
| Real Exam Qty: | 16–20 scenarios |
| Exam Duration: | 180 minutes |
| Exam Format: | Live lab environment, Performance-based scenarios |
| Related Certifications: | Nutanix Certified Master - Multicloud Storage (NCM-MCS) Nutanix Certified Master - Multicloud Networking (NCM-MCN) Nutanix Certified Professional - Multicloud Infrastructure (NCP-MCI) |
| Exam Price: | $300 USD |
| Certificate Validity Period: | 3 years |
| Recommended Training: | Advanced Administration & Performance Management (AAPM) |
| Exam Registration: | PSI Exam Scheduling Nutanix Certification Portal |
| Sample Questions: | Nutanix NCM-MCI Sample Questions |
| Exam Way: | Remote proctored online or onsite at PSI test centers |
| Pre Condition: | Hold any active, non-expired Nutanix Certified Professional (NCP) or Nutanix Certified Master (NCM) level certification; 3–5 years IT infrastructure experience; 2–3 years Nutanix administration experience |
| Official Syllabus URL: | https://www.nutanix.com/support-services/training-certification/certifications/certification-details-ncm-mci |
通過擁有技術含量的Nutanix NCM-MCI認證資格,您可以使自己在一家新公司獲得不錯的工作機會,來提升你的IT技能,有一個更好的職業發展道路。我們的NCM-MCI考古題是可靠,經濟實惠,品質最高的題庫資料,以幫助考生解決如何通過Nutanix NCM-MCI考試的問題。我們還會不定期的更新所有考試的考古題,想獲得最新的NCM-MCI考古題就在我們的網站,確保你成功通過NCM-MCI考試,實現夢想!
| 主題 | 簡介 |
|---|---|
| 主題 1 |
|
| 主題 2 |
|
| 主題 3 |
|
| 主題 4 |
|
| 主題 5 |
|
問題 #11
Task 5
An administrator has been informed that a new workload requires a logically segmented network to meet security requirements.
Network configuration:
VLAN: 667
Network: 192.168.0.0
Subnet Mask: 255.255.255.0
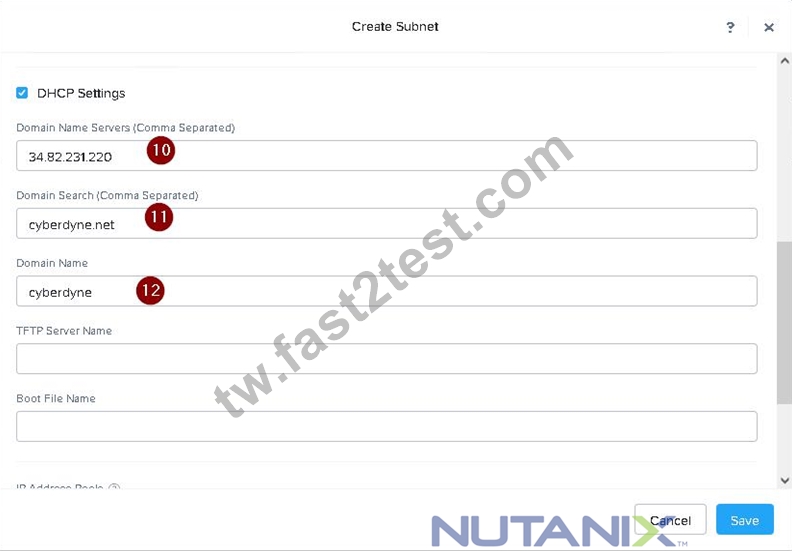
DNS server: 34.82.231.220
Default Gateway: 192.168.0.1
Domain: cyberdyne.net
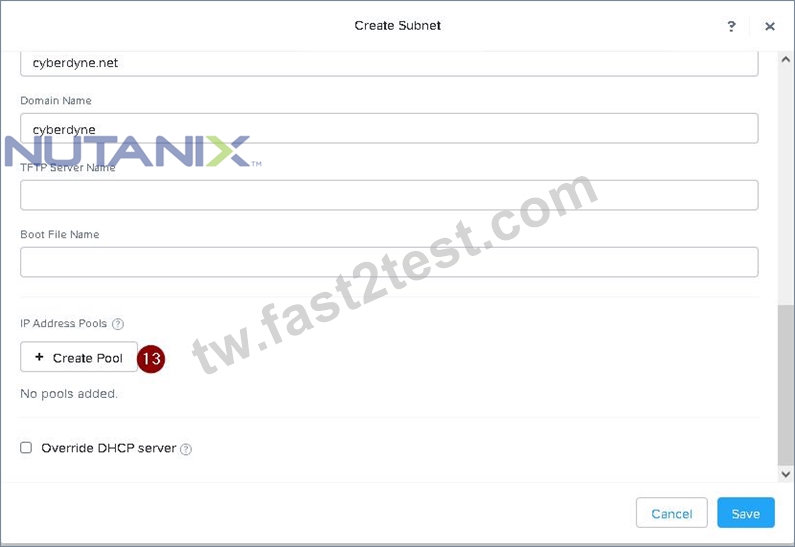
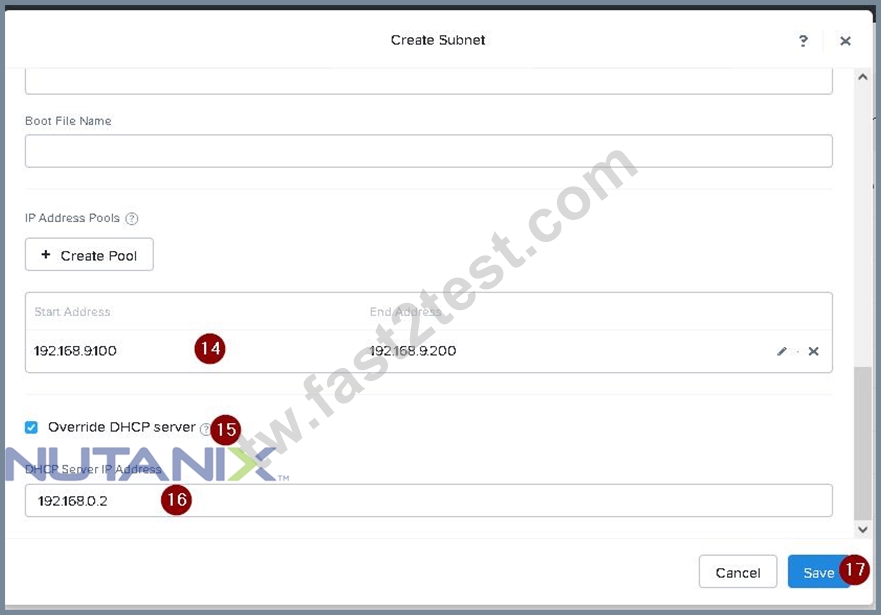
IP Pool: 192.168.9.100-200
DHCP Server IP: 192.168.0.2
Configure the cluster to meet the requirements for the new workload if new objects are required, start the name with 667.
答案:
解題說明:
See the Explanation for step by step solution
Explanation:
To configure the cluster to meet the requirements for the new workload, you need to do the following steps:
Create a new VLAN with ID 667 on the cluster. You can do this by logging in to Prism Element and going to Network Configuration > VLANs > Create VLAN. Enter 667 as the VLAN ID and a name for the VLAN, such as 667_VLAN.
Create a new network segment with the network details provided. You can do this by logging in to Prism Central and going to Network > Network Segments > Create Network Segment. Enter a name for the network segment, such as 667_Network_Segment, and select 667_VLAN as the VLAN. Enter 192.168.0.0 as the Network Address and 255.255.255.0 as the Subnet Mask. Enter 192.168.0.1 as the Default Gateway and 34.82.231.220 as the DNS Server. Enter cyberdyne.net as the Domain Name.
Create a new IP pool with the IP range provided. You can do this by logging in to Prism Central and going to Network > IP Pools > Create IP Pool. Enter a name for the IP pool, such as 667_IP_Pool, and select 667_Network_Segment as the Network Segment. Enter 192.168.9.100 as the Starting IP Address and 192.168.9.200 as the Ending IP Address.
Configure the DHCP server with the IP address provided. You can do this by logging in to Prism Central and going to Network > DHCP Servers > Create DHCP Server. Enter a name for the DHCP server, such as 667_DHCP_Server, and select 667_Network_Segment as the Network Segment. Enter 192.168.0.2 as the IP Address and select 667_IP_Pool as the IP Pool.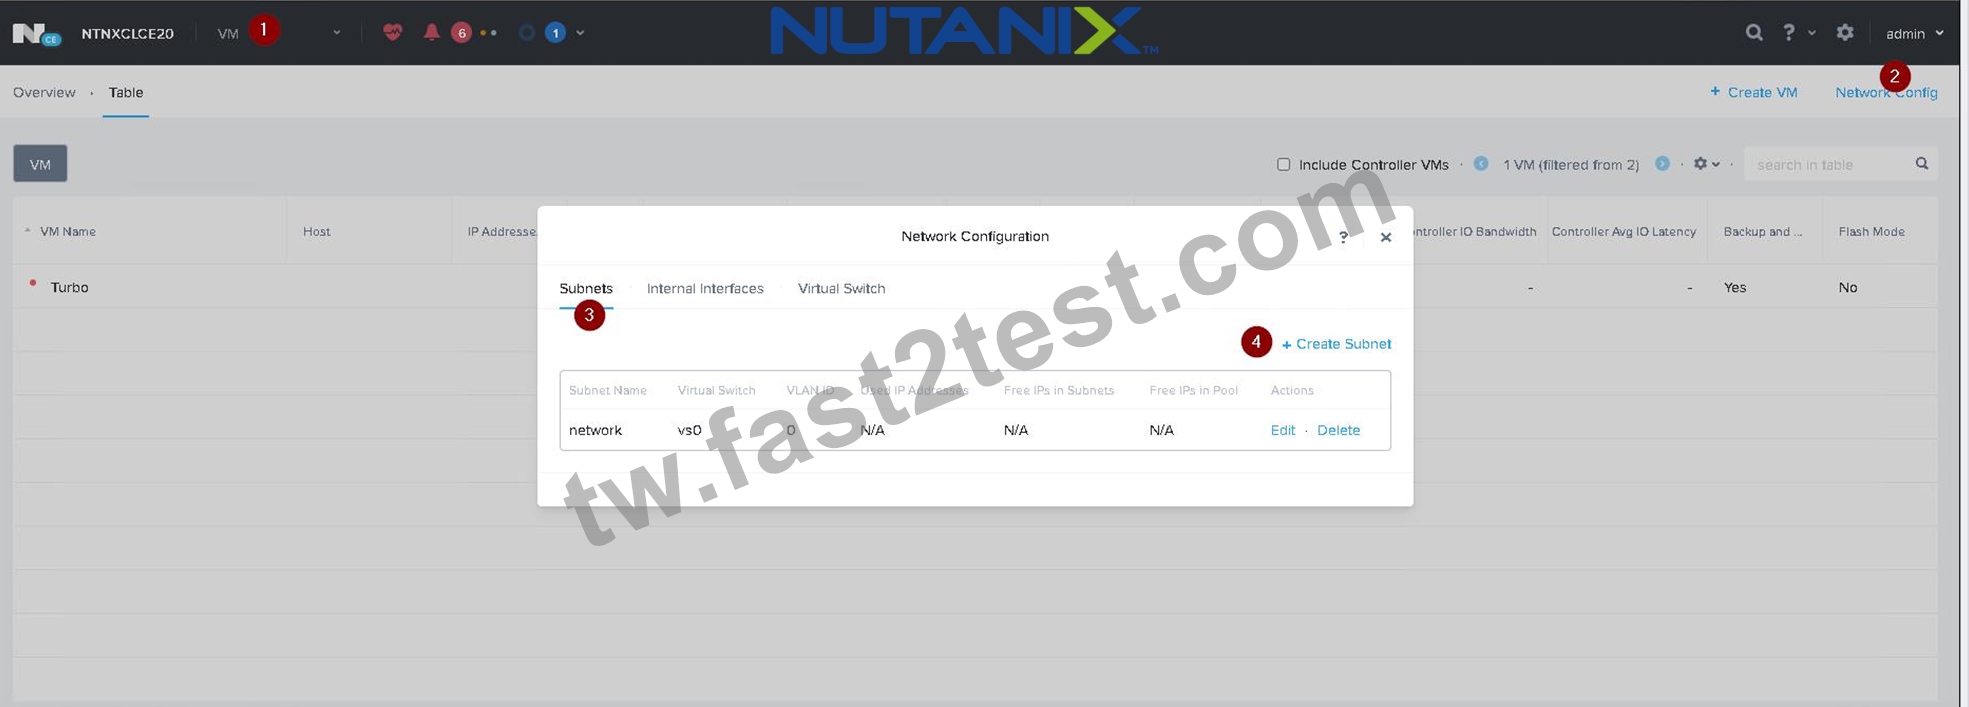
問題 #12
Task 2
An administrator needs to configure storage for a Citrix-based Virtual Desktop infrastructure.
Two VDI pools will be created
Non-persistent pool names MCS_Pool for tasks users using MCS Microsoft Windows 10 virtual Delivery Agents (VDAs) Persistent pool named Persist_Pool with full-clone Microsoft Windows 10 VDAs for power users
20 GiB capacity must be guaranteed at the storage container level for all power user VDAs The power user container should not be able to use more than 100 GiB Storage capacity should be optimized for each desktop pool.
Configure the storage to meet these requirements. Any new object created should include the name of the pool(s) (MCS and/or Persist) that will use the object.
Do not include the pool name if the object will not be used by that pool.
Any additional licenses required by the solution will be added later.
答案:
解題說明:
See the Explanation for step by step solution
Explanation:
To configure the storage for the Citrix-based VDI, you can follow these steps:
Log in to Prism Central using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as VDI_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for optimal performance, you may prefer to use more SSDs than HDDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container for the non-persistent pool, such as MCS_Pool_Container, and select the storage pool that you just created, VDI_Storage_Pool, as the source.
Under Advanced Settings, enable Deduplication and Compression to reduce the storage footprint of the non-persistent desktops. You can also enable Erasure Coding if you have enough nodes in your cluster and want to save more space. These settings will help you optimize the storage capacity for the non-persistent pool.
Click Save to create the container.
Go to Storage > Containers and click on Create Container again.
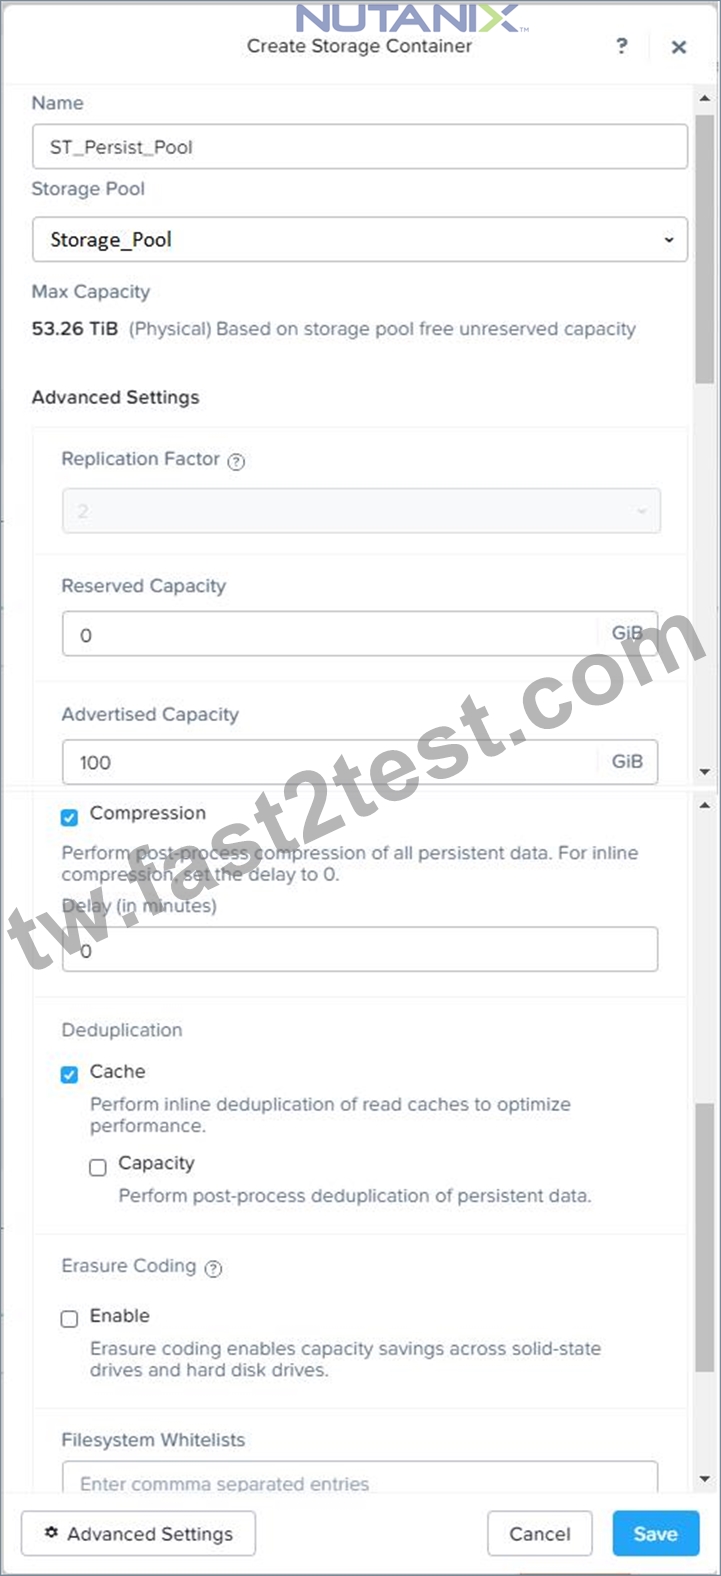
Enter a name for the new container for the persistent pool, such as Persist_Pool_Container, and select the same storage pool, VDI_Storage_Pool, as the source.
Under Advanced Settings, enable Capacity Reservation and enter 20 GiB as the reserved capacity. This will guarantee that 20 GiB of space is always available for the persistent desktops. You can also enter 100 GiB as the advertised capacity to limit the maximum space that this container can use. These settings will help you control the storage allocation for the persistent pool.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore for the non-persistent pool, such as MCS_Pool_Datastore, and select NFS as the datastore type. Select the container that you just created, MCS_Pool_Container, as the source.
Click Save to create the datastore.
Go to Storage > Datastores and click on Create Datastore again.
Enter a name for the new datastore for the persistent pool, such as Persist_Pool_Datastore, and select NFS as the datastore type. Select the container that you just created, Persist_Pool_Container, as the source.
Click Save to create the datastore.
The datastores will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on each datastore. You should see all nodes listed under Hosts.
You can now use Citrix Studio to create your VDI pools using MCS or full clones on these datastores. For more information on how to use Citrix Studio with Nutanix Acropolis, see Citrix Virtual Apps and Desktops on Nutanix or Nutanix virtualization environments.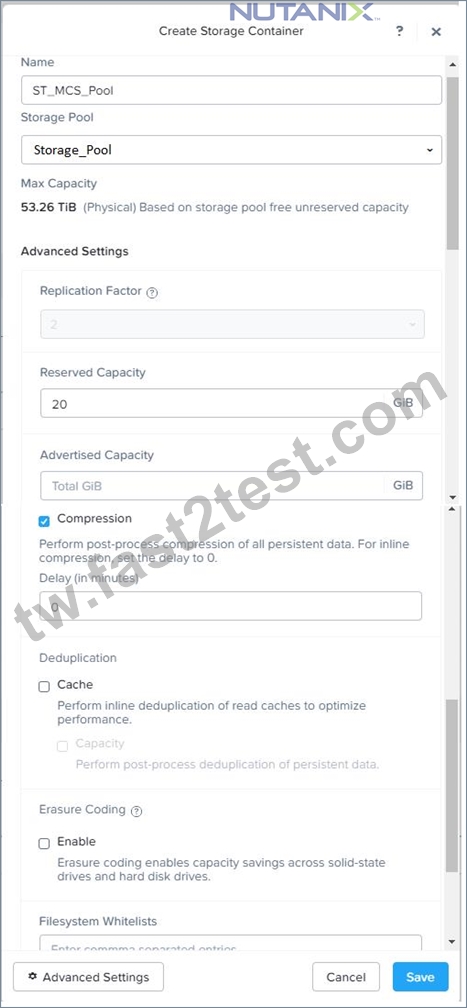
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2079-Citrix-Virtual-Apps-and-Desktops:bp-nutanix-storage-configuration.html
問題 #13
Task 12
An administrator needs to create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month.
No other entities should be included in the report.
The report should run monthly and should send an email to admin@syberdyne.net when it runs.
Generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip Note: Make sure the report and zip file are named correctly. The SMTP server will not be configured.
答案:
解題說明:
See the Explanation for step by step solution
Explanation:
To create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter VMs_Power_State as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, Cluster Name, vCPUs, Memory, Power State. Click Next.
Under the Time Period option, select Last Month. Click Next.
Under the Report Settings option, select Monthly from the Schedule drop-down menu. Enter admin@syberdyne.net as the Email Recipient. Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.
To generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip, you can follow these steps:
Log in to Prism Central and click on Operations on the left menu.
Select Reports from the drop-down menu and find the VMs_Power_State report from the list. Click on Run Now.
Wait for the report to be generated and click on Download Report. Save the file as Desktop\Files\VMs_Power_state.zip.
1. Open the Report section on Prism Central (Operations > Reports)
2. Click on the New Report button to start the creation of your custom report
3. Under the Custom Views section, select Data Table
4. Provide a title to your custom report, as well as a description if required.
5. Under the Entity Type option, select VM
6. This report can include all as well as a selection of the VMs
7. Click on the Custom Columns option and add the below variables:
a. Name - Name of the listed Virtual Machine
b. vCPUs - A combination of the vCores and vCPU's assigned to the Virtual Machine c. Memory - Amount of memory assigned to the Virtual Machine d. Disk Capacity - The total amount of assigned virtual disk capacity e. Disk Usage - The total used virtual disk capacity f. Snapshot Usage - The total amount of capacity used by snapshots (Excluding Protection Domain snapshots)
8. Under the Aggregation option for Memory and Disk Usage accept the default Average option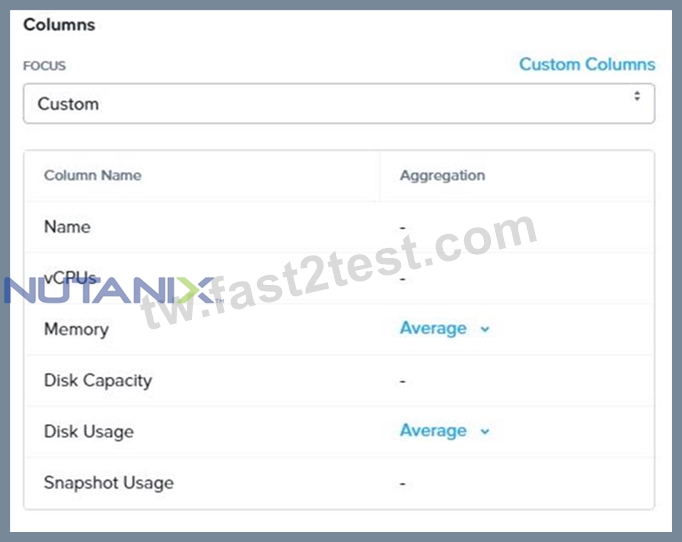
9. Click on the Add button to add this custom selection to your report
10. Next click on the Save and Run Now button on the bottom right of the screen
11. Provide the relevant details on this screen for your custom report: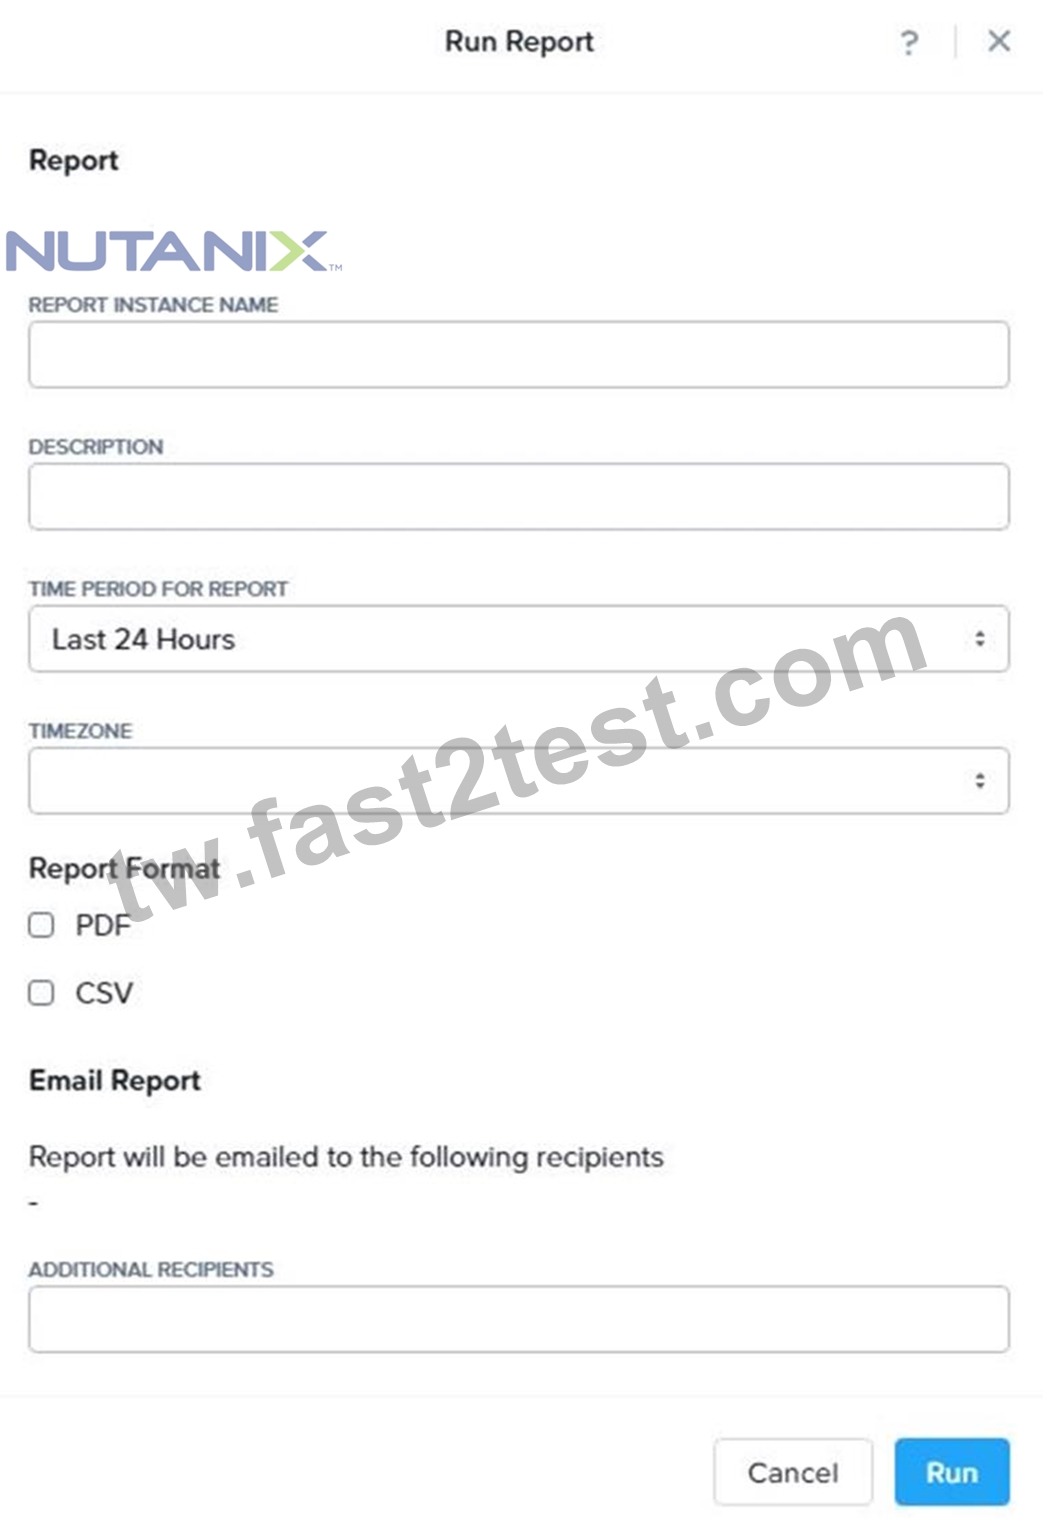
12. You can leave the Time Period For Report variable at the default of Last 24 Hours
13. Specify a report output of preference (PDF or CSV) and if required Additional Recipients for this report to be mailed to. The report can also simply be downloaded after this creation and initial run if required
14. Below is an example of this report in a CSV format:
問題 #14
Task 15
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
答案:
解題說明:
See the Explanation for step by step solution
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
問題 #15
Task 11
An administrator has noticed that after a host failure, the SQL03 VM was not powered back on from another host within the cluster. The Other SQL VMs (SQL01, SQL02) have recovered properly in the past.
Resolve the issue and configure the environment to ensure any single host failure affects a minimal number os SQL VMs.
Note: Do not power on any VMs
答案:
解題說明:
See the Explanation for step by step solution
Explanation:
One possible reason why the SQL03 VM was not powered back on after a host failure is that the cluster was configured with the default (best effort) VM high availability mode, which does not guarantee the availability of VMs in case of insufficient resources on the remaining hosts. To resolve this issue, I suggest changing the VM high availability mode to guarantee (reserved segments), which reserves some memory on each host for failover of VMs from a failed host. This way, the SQL03 VM will have a higher chance of being restarted on another host in case of a host failure.
To change the VM high availability mode to guarantee (reserved segments), you can follow these steps:
Log in to Prism Central and select the cluster where the SQL VMs are running.
Click on the gear icon on the top right corner and select Cluster Settings.
Under Cluster Services, click on Virtual Machine High Availability.
Select Guarantee (Reserved Segments) from the drop-down menu and click Save.
To configure the environment to ensure any single host failure affects a minimal number of SQL VMs, I suggest using anti-affinity rules, which prevent VMs that belong to the same group from running on the same host. This way, if one host fails, only one SQL VM will be affected and the other SQL VMs will continue running on different hosts.
To create an anti-affinity rule for the SQL VMs, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Group.
Enter a name for the group, such as SQL Group, and click Next.
Select the SQL VMs (SQL01, SQL02, SQL03) from the list and click Next.
Select Anti-Affinity from the drop-down menu and click Next.
Review the group details and click Finish.
I hope this helps. How else can I help?
https://portal.nutanix.com/page/documents/details?targetId=AHV-Admin-Guide-v6_5:ahv-affinity-policies-c.html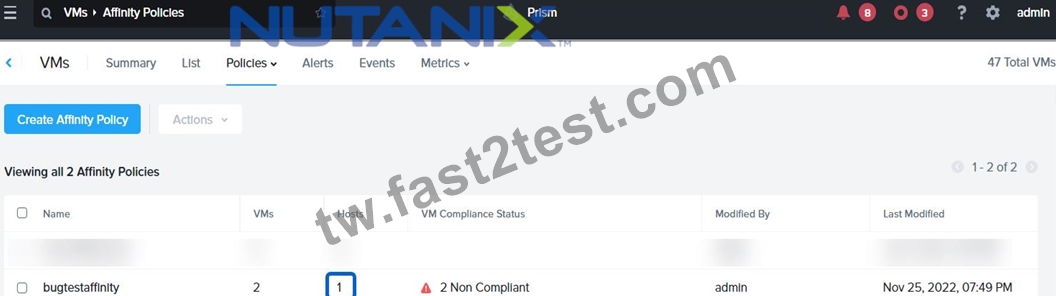
問題 #16
......
NCM-MCI考試重點: https://tw.fast2test.com/NCM-MCI-premium-file.html
順便提一下,可以從雲存儲中下載Fast2test NCM-MCI考試題庫的完整版:https://drive.google.com/open?id=1V79W_dNQfW8pdm0weQsLPKF060Sl7gu-