Certified-Data-Engineer-Professional PDF,Certified-Data-Engineer-Professional認證考試解析

我們的NewDumps是一個為多種IT認證考試的人提供準確的考試材料的專業網站。我們的NewDumps是一個可以為很多IT人士提升自己的職業目標。我們的IT精英團隊的力量會讓你難以置信。你可以先嘗試我們NewDumps為你們提供的免費下載關於Databricks Certified-Data-Engineer-Professional認證考試的部分考題及答案來測我們的可靠性。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Topic 2: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Compare streaming tables and materialized views
- 3. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 6. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 7. Develop unit and integration tests for data processing code
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 3: Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 4: Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Use row filters and column masks for sensitive data
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Topic 5: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 6: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Topic 7: Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 8: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 9: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 10: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use system tables for resource, cost, audit, and workload monitoring
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
>> Certified-Data-Engineer-Professional PDF <<
Certified-Data-Engineer-Professional認證考試解析 - Certified-Data-Engineer-Professional软件版
期待成為擁有Certified-Data-Engineer-Professional認證的專業人士嗎?想減少您的認證成本嗎?想通過Certified-Data-Engineer-Professional考試嗎?如果你回答“是”,那趕緊來參加考試吧,我們為您提供涵蓋真實測試的題目和答案的試題。Databricks的Certified-Data-Engineer-Professional考古題覆蓋率高,可以順利通過認證考試,從而獲得證書。經過考試認證數據中心顯示,NewDumps提供最準確和最新的IT考試資料,幾乎包括所有的知識點,是最好的自學練習題,幫助您快速通過Certified-Data-Engineer-Professional考試。
最新的 Databricks Certification Certified-Data-Engineer-Professional 免費考試真題 (Q28-Q33):
問題 #28
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays.
Which limitation will the team face while diagnosing this problem?
- A. Updating the table schema will invalidate the Delta transaction log metadata.
- B. Spark cannot capture the topic partition fields from the kafka source.
- C. New fields will not be computed for historic records.
- D. New fields cannot be added to a production Delta table.
- E. Updating the table schema requires a default value provided for each file added.
答案:C
解題說明:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
問題 #29
Which statement characterizes the general programming model used by Spark Structured Streaming?
- A. Structured Streaming leverages the parallel processing of GPUs to achieve highly parallel data throughput.
- B. Structured Streaming uses specialized hardware and I/O streams to achieve sub-second latency for data transfer.
- C. Structured Streaming relies on a distributed network of nodes that hold incremental state values for cached stages.
- D. Structured Streaming is implemented as a messaging bus and is derived from Apache Kafka.
- E. Structured Streaming models new data arriving in a data stream as new rows appended to an unbounded table.
答案:E
解題說明:
The key idea in Structured Streaming is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model. You will express your streaming computation as standard batch-like query as on a static table, and Spark runs it as an incremental query on the unbounded input table. Let's understand this model in more detail.
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html
問題 #30
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
- A. Overwrite the account current table with each batch using the results of a query against the account history table grouping by user id and filtering for the max value of last updated.
- B. Use Delta Lake version history to get the difference between the latest version of account history and one version prior, then write these records to account current.
- C. Use Auto Loader to subscribe to new files in the account history directory; configure a Structured Streaminq trigger once job to batch update newly detected files into the account current table.
- D. Filter records in account history using the last updated field and the most recent hour processed, making sure to deduplicate on username; write a merge statement to update or insert the most recent value for each username.
- E. Filter records in account history using the last updated field and the most recent hour processed, as well as the max last iogin by user id write a merge statement to update or insert the most recent value for each user id.
答案:E
解題說明:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column.
問題 #31
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
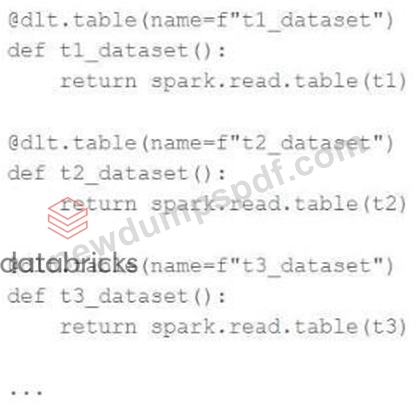
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
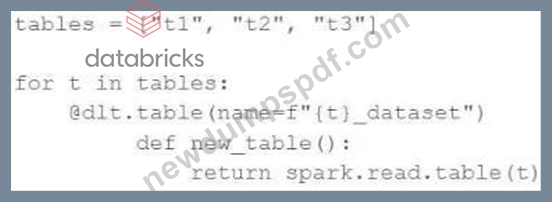
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
- B. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
答案:A
解題說明:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
問題 #32
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
- A. By default, both the DBFS root and mounted data sources are only accessible to workspace administrators.
- B. The DBFS root stores files in ephemeral block volumes attached to the driver, while mounted directories will always persist saved data to external storage between sessions.
- C. The DBFS root is the most secure location to store data, because mounted storage volumes must have full public read and write permissions.
- D. DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems.
- E. Neither the DBFS root nor mounted storage can be accessed when using %sh in a Databricks notebook.
答案:D
解題說明:
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted.
問題 #33
......
如今在IT業裏面臨著激烈的競爭,你會感到力不從心,這是必然的。你要做的是為你的事業保駕護航,當然,你有很多選擇,我推薦NewDumps Databricks的Certified-Data-Engineer-Professional的考試試題及答案,它是幫助你成功獲得IT認證的好幫手,所以你還在等什麼呢,去獲得新的NewDumps Databricks的Certified-Data-Engineer-Professional的考試培訓資料吧。
Certified-Data-Engineer-Professional認證考試解析: https://www.newdumpspdf.com/Certified-Data-Engineer-Professional-exam-new-dumps.html
- 可靠的Databricks Certified-Data-Engineer-Professional PDF和最佳的www.newdumpspdf.com - 資格考試的領先提供商 🙍 在【 www.newdumpspdf.com 】上搜索⮆ Certified-Data-Engineer-Professional ⮄並獲取免費下載Certified-Data-Engineer-Professional在線考題
- Certified-Data-Engineer-Professional最新試題 🎻 Certified-Data-Engineer-Professional软件版 💖 最新Certified-Data-Engineer-Professional題庫資源 🦍 免費下載▷ Certified-Data-Engineer-Professional ◁只需在▛ www.newdumpspdf.com ▟上搜索Certified-Data-Engineer-Professional在線考題
- Certified-Data-Engineer-Professional软件版 😀 Certified-Data-Engineer-Professional熱門證照 🐔 Certified-Data-Engineer-Professional題庫資料 🔵 立即到⇛ www.pdfexamdumps.com ⇚上搜索⇛ Certified-Data-Engineer-Professional ⇚以獲取免費下載Certified-Data-Engineer-Professional資訊
- Certified-Data-Engineer-Professional題庫資料 💕 Certified-Data-Engineer-Professional考古題 👩 Certified-Data-Engineer-Professional最新考證 📀 立即到【 www.newdumpspdf.com 】上搜索☀ Certified-Data-Engineer-Professional ️☀️以獲取免費下載Certified-Data-Engineer-Professional考古題
- Certified-Data-Engineer-Professional考試證照綜述 🐚 Certified-Data-Engineer-Professional软件版 🟨 免費下載Certified-Data-Engineer-Professional考題 🐉 打開▷ www.newdumpspdf.com ◁搜尋➤ Certified-Data-Engineer-Professional ⮘以免費下載考試資料Certified-Data-Engineer-Professional最新試題
- 最優秀的Certified-Data-Engineer-Professional PDF和資格考試的領導者和保證通過Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional考試 🦽 透過➤ www.newdumpspdf.com ⮘搜索➥ Certified-Data-Engineer-Professional 🡄免費下載考試資料免費下載Certified-Data-Engineer-Professional考題
- Certified-Data-Engineer-Professional考題套裝 👒 Certified-Data-Engineer-Professional更新 🏟 Certified-Data-Engineer-Professional最新考證 🦈 立即在▷ www.kaoguti.com ◁上搜尋▛ Certified-Data-Engineer-Professional ▟並免費下載最新Certified-Data-Engineer-Professional題庫資源
- 信任授權Certified-Data-Engineer-Professional PDF是最快的通過途徑Databricks Certified Data Engineer Professional 🧈 在➽ www.newdumpspdf.com 🢪網站上查找⮆ Certified-Data-Engineer-Professional ⮄的最新題庫Certified-Data-Engineer-Professional最新考證
- Certified-Data-Engineer-Professional考試證照綜述 🟪 Certified-Data-Engineer-Professional在線考題 ✈ Certified-Data-Engineer-Professional資訊 🛀 請在【 tw.fast2test.com 】網站上免費下載{ Certified-Data-Engineer-Professional }題庫Certified-Data-Engineer-Professional考試內容
- 已驗證的Databricks Certified-Data-Engineer-Professional PDF和授權的Newdumpspdf - 資格考試中的領先供應商 ⏳ 打開網站[ www.newdumpspdf.com ]搜索➡ Certified-Data-Engineer-Professional ️⬅️免費下載Certified-Data-Engineer-Professional題庫資料
- 高通過率Certified-Data-Engineer-Professional PDF和資格考試中的領先提供者和最新更新Databricks Databricks Certified Data Engineer Professional 🌠 在▛ www.vcesoft.com ▟網站上查找➽ Certified-Data-Engineer-Professional 🢪的最新題庫Certified-Data-Engineer-Professional最新考古題
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, telegra.ph, www.stes.tyc.edu.tw, Disposable vapes