BTW, DOWNLOAD part of PrepPDF Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1tFJ-nuP4BBwBrFMEcQjkp7iZJsnjCJQL
In the 21 Century, the {Examcode} certification became more and more recognized in the society because it represented the certain ability of examinees. However, in order to obtain {Examcode} certification, you have to spend a lot of time preparing for the Databricks-Certified-Professional-Data-Engineer exam. Many people gave up because of all kinds of difficulties before the examination, and finally lost the opportunity to enhance their self-worth. As a thriving multinational company, we are always committed to solving this problem. For example, the Databricks-Certified-Professional-Data-Engineer Learning Engine we developed can make the Databricks-Certified-Professional-Data-Engineer exam easy and easy, and we can confidently say that we did this.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Integration with Databricks APIs and tools - Data transformation and aggregation |
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs |
| Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Data validation and quality checks - Standardization and normalization |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
>> Top Databricks-Certified-Professional-Data-Engineer Dumps <<
Our Databricks-Certified-Professional-Data-Engineer exam braindumps are set high standards for your experience. That is the reason why our Databricks-Certified-Professional-Data-Engineer training questions gain well brand recognition and get attached with customers all these years around the world. Besides, our Databricks-Certified-Professional-Data-Engineer learning questions are not only high effective but priced reasonably. Their prices are acceptable for everyone and help you qualify yourself as and benefit your whole life.
NEW QUESTION # 58
The following table consists of items found in user carts within an e-commerce website.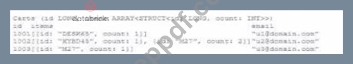
The following MERGE statement is used to update this table using an updates view, with schema evaluation enabled on this table.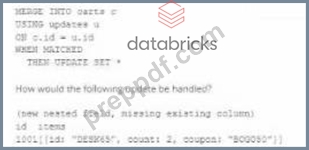
How would the following update be handled?
Answer: C
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
:
Databricks documentation on schema evolution in Delta Lake: https://docs.databricks.com/delta/delta-batch.
html#schema-evolution
NEW QUESTION # 59
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays:
Which limitation will the team face while diagnosing this problem?
Answer: D
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
Reference:
Databricks documentation on Delta Lake schema management: https://docs.databricks.com/delta/delta-batch.html#schema-management
NEW QUESTION # 60
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.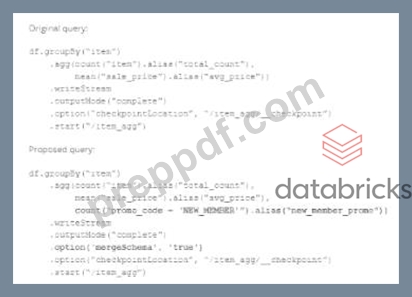
Which step must also be completed to put the proposed query into production?
Answer: C
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
References:
* Databricks documentation on Structured Streaming:
https://docs.databricks.com/spark/latest/structured-streaming/index.html
* Databricks documentation on streaming checkpoints:
https://docs.databricks.com/spark/latest/structured-streaming/production.html#checkpointing
NEW QUESTION # 61
You had worked with the Data analysts team to set up a SQL Endpoint(SQL warehouse) point so they can easily query and analyze data in the gold layer, but once they started consuming the SQL Endpoint(SQL warehouse) you noticed that during the peak hours as the number of users increase you are seeing queries taking longer to finish, which of the following steps can be taken to resolve the issue?
*Please note Databricks recently renamed SQL endpoint to SQL warehouse.
Answer: C
Explanation:
Explanation
the answer is,
They can increase the maximum bound of the SQL endpoint's scaling range, when you increase the maximum bound you can add more clusters to the warehouse which can then run additional queries that are waiting in the queue to run, focus on the below explanation that talks about Scale-out.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, example if a query runs for 1 minute in a 2X-Small warehouse size, it may run in 30 Seconds if we change the warehouse size to X-Small.
this is due to 2X-Small has 1 worker node and X-Small has 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale out. If a warehouse is con-figured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts: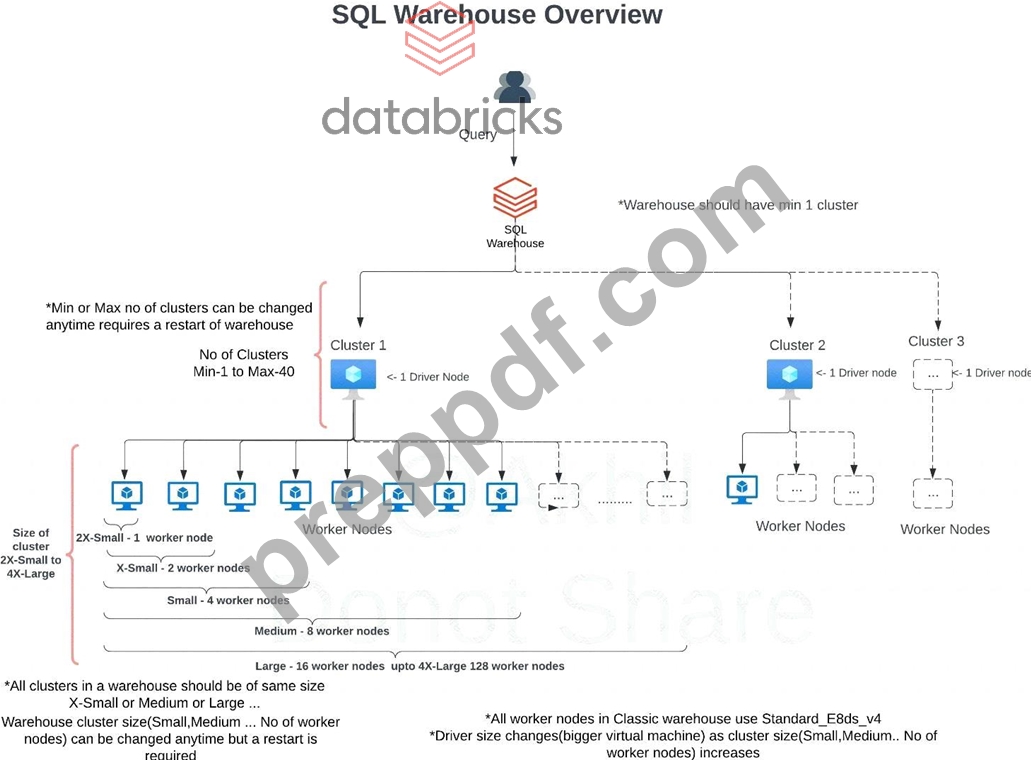
SQL endpoint(SQL Warehouse) scales horizontally(scale-out) and vertical (scale-up), you have to understand when to use what.
Scale-out -> to add more clusters for a SQL endpoint, change max number of clusters If you are trying to improve the throughput, being able to run as many queries as possible then having an additional cluster(s) will improve the performance.
Databricks SQL automatically scales as soon as it detects queries are in queuing state, in this example scaling is set for min 1 and max 3 which means the warehouse can add three clusters if it detects queries are waiting.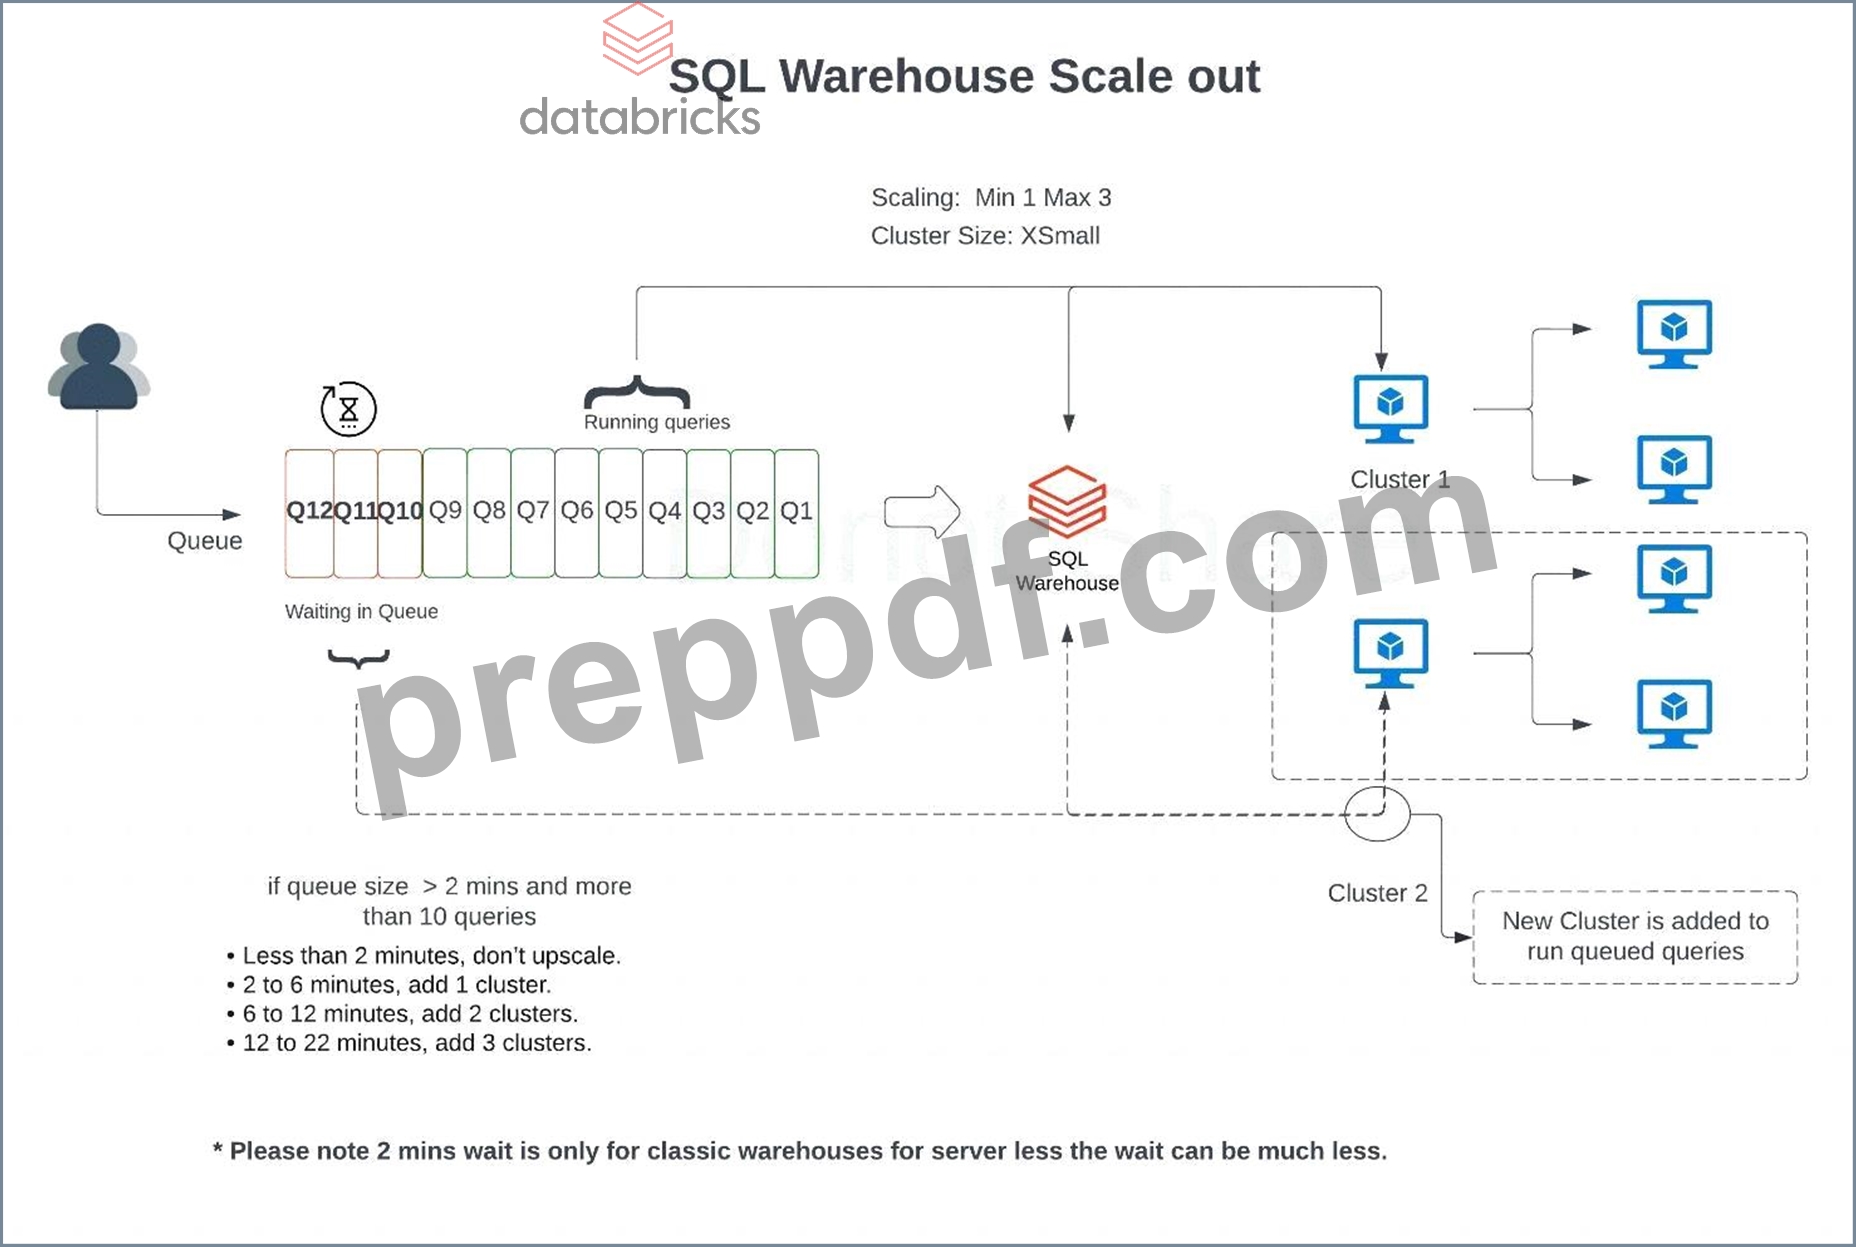
During the warehouse creation or after you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out, if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.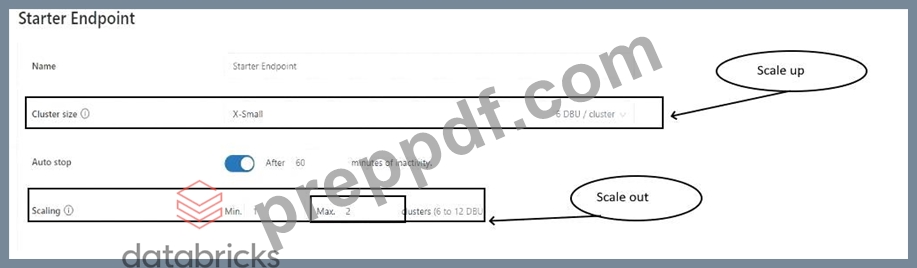
How do you know how many clusters you need(How to set Max cluster size)?
When you click on an existing warehouse and select the monitoring tab, you can see warehouse utilization information(see below), there are two graphs that provide important information on how the warehouse is being utilized, if you see queries are being queued that means your warehouse can benefit from additional clusters. Please review the additional DBU cost associated with adding clusters so you can take a well balanced decision between cost and performance.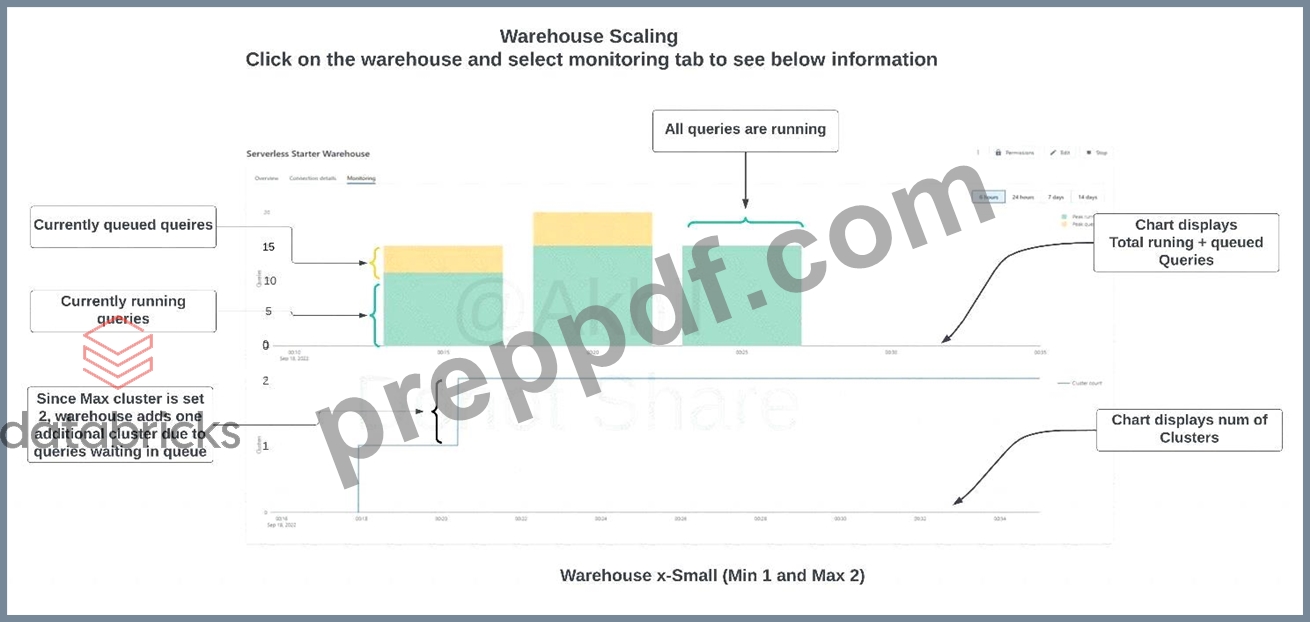
NEW QUESTION # 62
A healthcare analytics team is implementing a dimensional model in Delta Lake for patient care analysis. They have a date dimension table and are evaluating design options to ensure it supports a wide range of time-based analyses.
Which design approach for the date dimension will support efficient time-based querying and aggregation?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
In dimensional modeling, Databricks recommends denormalized, attribute-rich dimension tables for performance and usability. A date dimension should include all commonly used derived time attributes such as fiscal period, quarter, month, weekday, and holiday flags. Precomputing these attributes ensures consistent business logic, eliminates repeated calculations during query time, and enables efficient filtering and aggregation. The documentation for Delta Lake and Lakehouse design explicitly advises precomputing these attributes for analytical workloads that depend heavily on time-based slicing. Options A and C degrade performance and consistency, while maintaining multiple calendar-specific dimension tables (B) complicates the model unnecessarily.
NEW QUESTION # 63
......
Our Databricks-Certified-Professional-Data-Engineer learning prep is definitely the latest information on the market. As you know, the contents of many exams are constantly being updated, so you must choose the latest Databricks-Certified-Professional-Data-Engineer practice quiz that can keep up with the times and ensure that the information you obtain is up-to-date. The staff really paid a lot of time and effort to ensure this. Of course, your ability to make a difference is our best reward with the help of the Databricks-Certified-Professional-Data-Engineer Exam Questions.
Databricks-Certified-Professional-Data-Engineer Test Dumps: https://www.preppdf.com/Databricks/Databricks-Certified-Professional-Data-Engineer-prepaway-exam-dumps.html
BONUS!!! Download part of PrepPDF Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1tFJ-nuP4BBwBrFMEcQjkp7iZJsnjCJQL