P.S.JPTestKingがGoogle Driveで共有している無料の2026 Snowflake SPS-C01ダンプ:https://drive.google.com/open?id=1Lb-wSiJhA8rlS3tU1Wca7xM_d2sq8X6r
あらゆる種類の問題に取り組まれる可能性があります。時には、何かを下に置いて他の問題に対処する必要があります。後者はより緊急であり、すぐに実行する必要があります。 SPS-C01トレーニングガイドの助けを借りて、あなたの夢がもう遅れることはありません。なぜなら、私たちはクライアントがよりゆっくりと勉強するのを支援するインテリジェントなアプリケーションと高効率のメリットを持っているからです。 SPS-C01の実際の試験で20〜30時間準備する場合、SPS-C01試験はあなたの前で簡単になります。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Performance Optimization and Best Practices | 20% | - Caching strategies - Query pushdown and optimization - Debugging and explain plans - Warehouse sizing for Snowpark - Vectorized UDFs - Minimizing data transfer |
| Topic 2: Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Window functions - Persisting transformed data - Complex data pipelines - Filtering, Aggregating, and Joining DataFrames |
| Topic 3: Snowpark Concepts | 15% | - Transformations vs. Actions - Snowpark DataFrames and query plans - Snowpark Sessions and connection management - Stored procedures and conditional logic - Snowpark architecture and core concepts - Client-side vs. Server-side execution |
| Topic 4: Snowpark API for Python | 30% | - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Establishing connections and session management - DataFrame creation and manipulation |
SPS-C01ガイド資料は、ユーザーの関心を本当に重視しています。開発プロセスでは、ユーザーのさまざまなニーズも常に考慮します。お客様の状況に応じて、当社のSPS-C01学習資料は、さまざまな資料をお客様に合わせて調整します。あなたに最適なSPS-C01練習問題は、間違いなく短時間でより効果的に感じられるようにします。 SPS-C01学習教材を選択することは間違いなくあなたの正しい決断です。もちろん、試用版を使用した後に決定することもできます。 SPS-C01の実際の試験で、あなたの参加を楽しみにしています。
質問 # 195
You are developing a data pipeline using Snowpark and want to optimize the execution of multiple DataFrame transformations. Which of the following strategies or techniques can you employ to improve performance and reduce execution time? (Select all that apply)
正解:C、D
解説:
Options C and E are correct. Option C, pushdown optimization by ensuring filter operations are applied as early as possible, is a key optimization technique. UDFs written in Scala can also be optimized by the compiler and Snowflake's engine. Option E, using , is the correct way to cache intermediate DataFrames for reuse, preventing redundant computations. Option A is incorrect; eagerly evaluating DataFrames with 'collect()' defeats the purpose of lazy evaluation and can significantly degrade performance. Option B is not directly applicable to Snowpark DataFrame transformations; 'CACHE RESULT is primarily for SQL queries executed outside of Snowpark DataFrame operations. Option D, is not a valid function in Snowpark API.
質問 # 196
Consider a DataFrame 'products df loaded from a SnoMlake table. It contains a 'features' column of type VARIANT, where each row contains a JSON object representing product features. Your task is to create a new DataFrame where each feature becomes a separate column. You need to dynamically extract these features without knowing the specific feature names in advance. Which of the following approaches could achieve this using Snowpark, and what considerations are important? Choose all that apply:
正解:C、E
解説:
Options B and C are viable approaches. Option B: You can use the native function on the VARIANT column to extract the keys, then iterate over the returned array to dynamically create new columns. This relies on knowing the structure of the data at runtime, but doesn't require a UDE Option C: FLATTEN' offers a SQL-centric way to achieve this, which might be preferable for performance and maintainability. After flattening, you would typically pivot the data. Option A is possible with IJDFs, but might be less performant than using native functions or FLATTEN. Option D is incorrect; dynamic column creation is possible. While OBJECT_CONSTRUCT() can construct JSON objects, it's not directly helpful for dynamically extracting JSON properties into separate columns in this scenario (Option E).
質問 # 197
You have a Snowpark DataFrame named 'employee_df with columns 'employee_id', 'department', and 'salary'. You want to calculate the average salary for each department and add it as a new column named 'avg_department_salary' to the original DataFrame. Additionally, you want to sort the resulting DataFrame by department and then by salary in descending order. Which of the following Snowpark code snippets correctly implements this requirement?





正解:A、B
解説:
Option D and E are correct. Both implement the window function correctly to add the average salary per department as a new column and then sort the DataFrame as required. Option E is very close and just has the window partition defined with 'col('department')'. Option A is correct but uses sort. Option B is incorrect because it does not include the original columns other than department when grouping so will loose important data, and attempts to sort on a column that no longer exists.Option C uses 'avg('salary')' instead of avg(col('salary'))
質問 # 198
A Snowpark developer is using to create a Snowpark session. They want to ensure that the session uses a specific role and warehouse, but only if those parameters are not already defined in the Snowflake CLI configuration. Which of the following code snippets correctly implements this behavior?





正解:E
解説:
Option D offers a concise method where role and warehouse specified in the 'Session.builder' are only used if they aren't already defined in the environment or Snowflake CLI configurations. Snowflake gives precedence to the environment over the code when using the session builder. Options A does not take into account how Session.builder.configs would work in order to read the current CLI configurations. Option B overwrites even though the question state that if these parameters are already defined in Snowflake CLI configurations they should NOT be changed. Option C does not have complete Code. Option E is overly complicated.
質問 # 199
You are developing a Snowpark Python application and want to write unit tests for your custom UDFs using pytest. Consider the following UDF: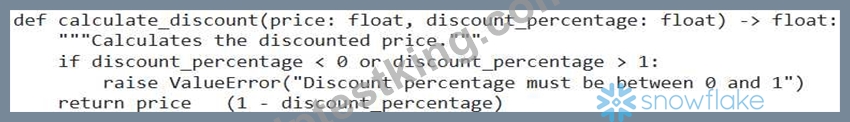
Which of the following pytest tests are correctly written and effectively test the UDF, including handling potential exceptions? (Select all that apply)
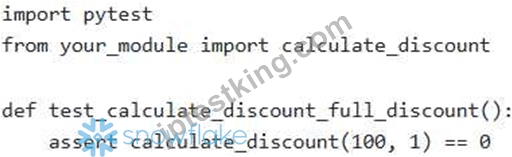
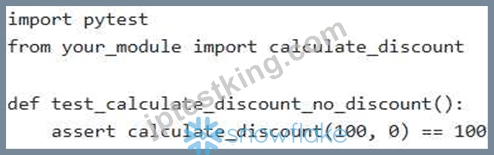
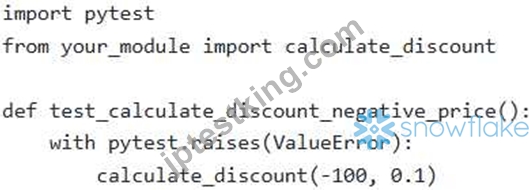
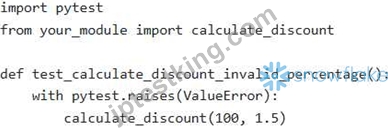
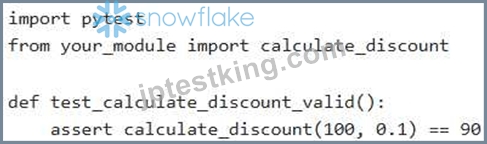
正解:A、B、D、E
解説:
Options A, B, C, and D represent correctly written pytest tests. A tests a valid discount, B tests the exception handling for an invalid percentage, C tests the case with no discount, and D tests a full discount. E is incorrect because the calculate_discount function does not explicitly check for negative prices, therefore 'pytest.raises(ValueErrorV will cause a failed test since no ValueError is raised.
質問 # 200
......
お客様のさまざまなニーズを満たすために、当社の専門家と教授は、PDFバージョン、オンラインバージョン、ソフトウェアバージョンなど、お客様が選択できるSPS-C01試験問題の3つの異なるバージョンを設計しました。次に、SPS-C01学習ガイドのオンラインバージョンを紹介します。オンライン版の最大の利点は、このバージョンがすべてのエレクトロニカ機器をサポートできることです。 SPS-C01学習教材のオンラインバージョンを選択した場合、エレクトロニカ機器で当社の製品を使用できます。
SPS-C01無料試験: https://www.jptestking.com/SPS-C01-exam.html
2026年JPTestKingの最新SPS-C01 PDFダンプおよびSPS-C01試験エンジンの無料共有:https://drive.google.com/open?id=1Lb-wSiJhA8rlS3tU1Wca7xM_d2sq8X6r