BTW, DOWNLOAD part of ExamsReviews AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1ueNInbQCbHYanfQli57Ctbd0dRew394a
ExamsReviews offers actual and updated Microsoft AI-300 Dumps after seeing the students struggling to prepare quickly for the test. We have made this product after consulting with a lot of professionals so the students can be successful. ExamsReviews has hired a team of professionals who work on a daily basis without caring about themselves to update the Microsoft AI-300 practice material.
| Section | Objectives |
|---|---|
| Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Implement secure and scalable AI systems | - Security and governance
|
| Operationalizing machine learning solutions | - Deployment and monitoring
|
>> Real AI-300 Exam Answers <<
By updating the study system of the AI-300 study materials, we can guarantee that our company can provide the newest information about the exam for all people. We believe that getting the newest information about the exam will help all customers pass the AI-300 Exam easily. If you purchase our study materials, you will have the opportunity to get the newest information about the AI-300 exam. More importantly, the updating system of our company is free for all customers.
NEW QUESTION # 49
Hotspot Question
You manage a Retrieval-Augmented Generation (RAG) system that retrieves internal policy documents from a vector index.
Recent analysis shows that:
- Retrieved results frequently include duplicated content from the same document.
- Retrieved chunks sometimes span unrelated policy sections.
You review the following retrieval and ingestion configurations: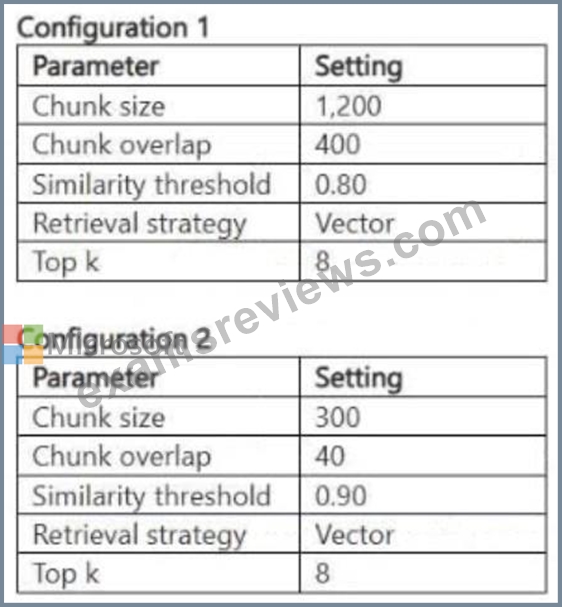
You need to reduce duplicated retrieval results and improve chunk relevance across policy sections. For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.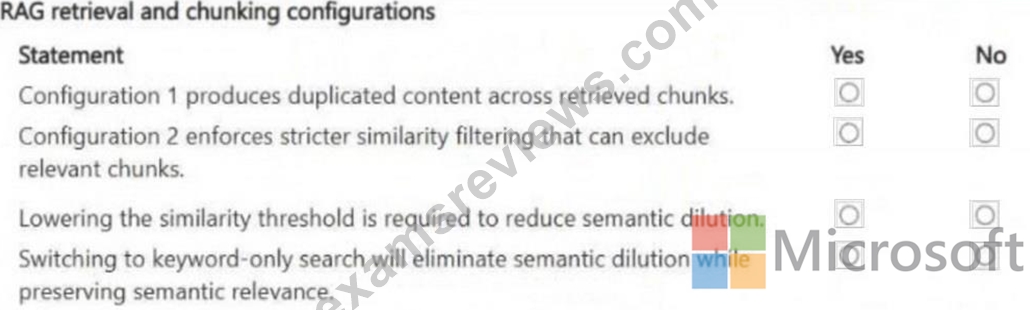
Answer:
Explanation: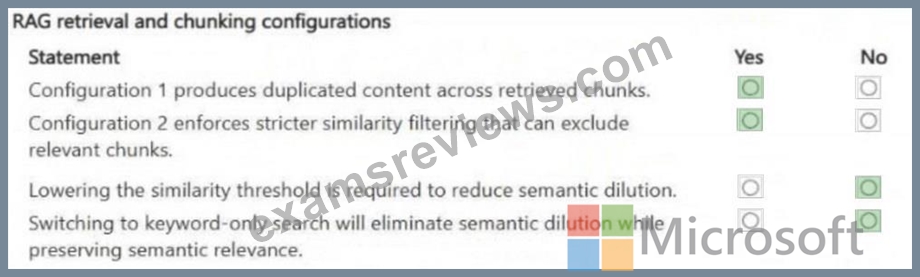
NEW QUESTION # 50
A company plans to deploy a foundation model in Microsoft Foundry.
The mode must support the following workloads:
A customer support workload used across multiple regions
A marketing workload that must remain within a specific region due to data residency requirements You need to select the deployment type.
Which deployment type should you use for each workload? To answer, move the appropriate deployment types to the correct requirements. You may use each deployment type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.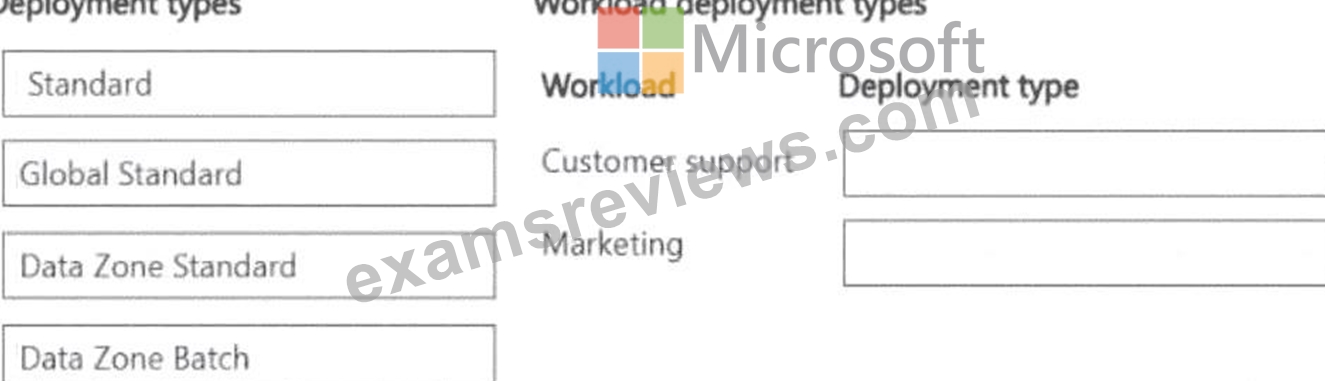
Answer:
Explanation: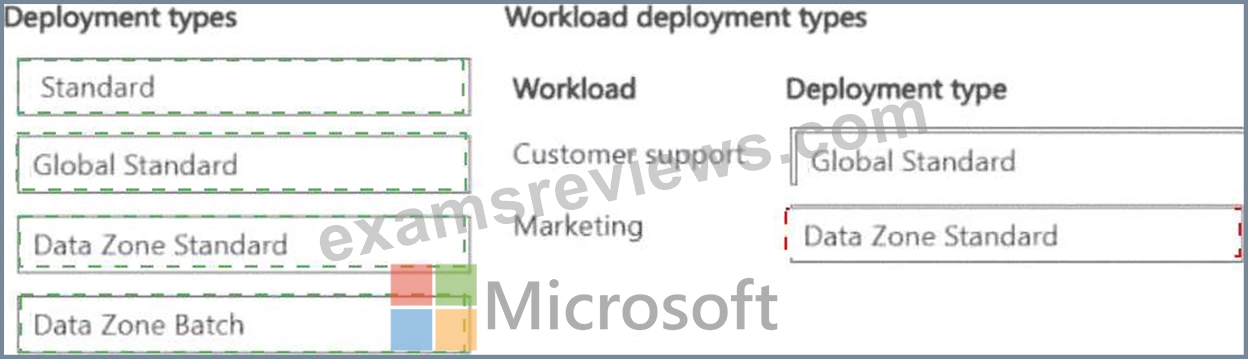
Explanation:
For a customer support workload used across multiple regions, Global Standard deployment is the right choice: it routes each request to the nearest available Azure region automatically, reducing latency globally and providing the highest throughput and availability. For a marketing workload that must remain within a specific region due to data residency requirements, a Data Zone Standard or single-region deployment ensures all compute and data processing occurs within a defined geographic boundary, satisfying GDPR and local data sovereignty rules. Microsoft Foundry ' s deployment types are designed around exactly this trade-off:
Global routing for performance-critical multi-region workloads, and Data Zone or Regional isolation for data- residency-constrained workloads. Choosing the wrong deployment type can result in either compliance violations or unnecessary latency.
Microsoft Learn Reference Topic: Model deployment options in Microsoft Foundry - Global, Data Zone, and Regional deployment types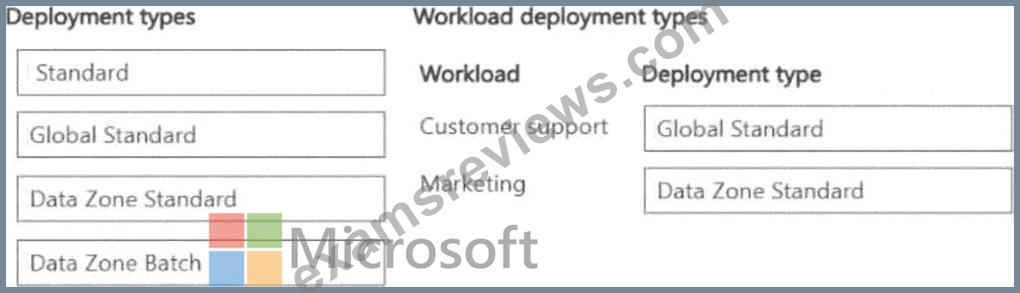
NEW QUESTION # 51
-
A team operates a generative AI-powered customer support assistant built on Microsoft Foundry. The application serves users globally and supports both real-time chat interactions and batch summarization jobs.
The team must ensure that the application continues to meet defined service-level objectives (SLO) as usage increases.
The team requires visibility into runtime behavior to identify performance regressions that affect the user experience and system capacity.
You need to select the performance metrics that meet the requirements.
Which performance metric should you monitor for each requirement? To answer, move the appropriate performance metrics to the correct requirements. You may use each performance metric once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.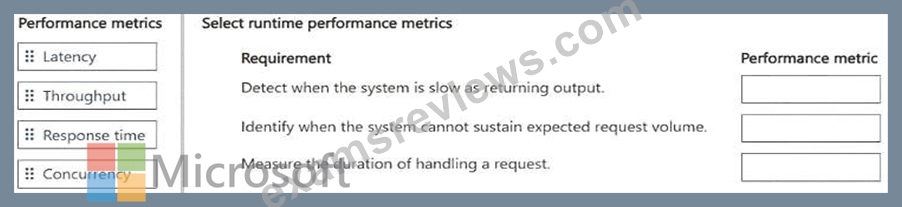
Answer:
Explanation: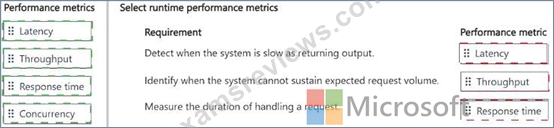
Explanation:
Detect when the system is slow at returning output: Latency
Identify when the system cannot sustain expected request volume: Throughput Measure the duration of handling a request: Response time Latency measures delay experienced while waiting for model output and is therefore the appropriate metric for identifying degradation in perceived responsiveness. Microsoft describes latency as the time required to obtain a response from the model and exposes metrics such as Time to Response/Time to First Token and Time Between Tokens for generative AI workloads. An increase indicates that users are waiting longer for output to begin or continue.
Throughput represents the amount of workload the system can process over a unit of time. Microsoft describes system-level throughput in terms such as requests per minute and tokens per minute. Consequently, throughput is the correct metric when determining whether a deployment can sustain the required request volume as demand increases.
Response time represents the overall duration required to handle an individual request. It is appropriate for measuring end-to-end request processing and validating request-duration SLOs. Microsoft specifically includes latency, throughput, and response times among the performance metrics candidates are expected to monitor for generative AI applications.
Concurrency measures simultaneous active requests and can influence capacity and latency, but none of these requirements directly asks for simultaneous-request count.
Study Guide Reference: Implement generative AI quality assurance and observability - continuous monitoring, latency, throughput, response times, production troubleshooting, and SLO monitoring.
NEW QUESTION # 52
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
Queries that include exact policy identifiers must return matching documents even when semantic similarity is low.
Natural-language questions must prioritize semantically relevant documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area . NOTE: Each correct selection is worth one point.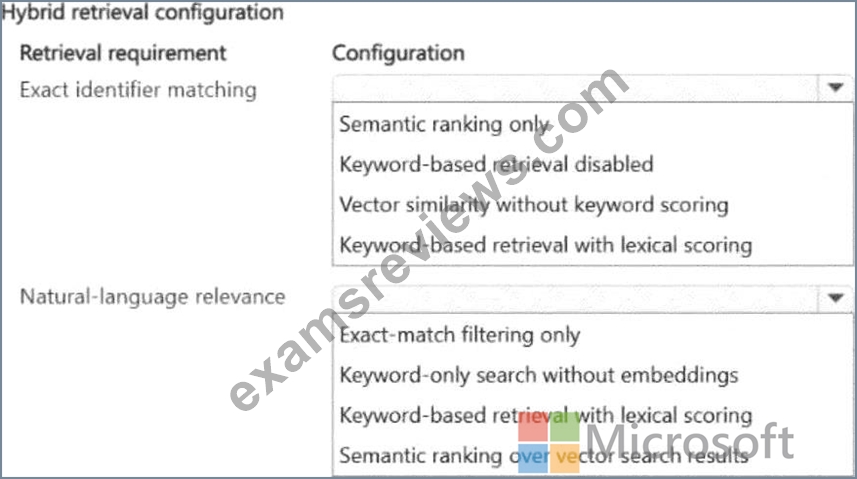
Answer:
Explanation: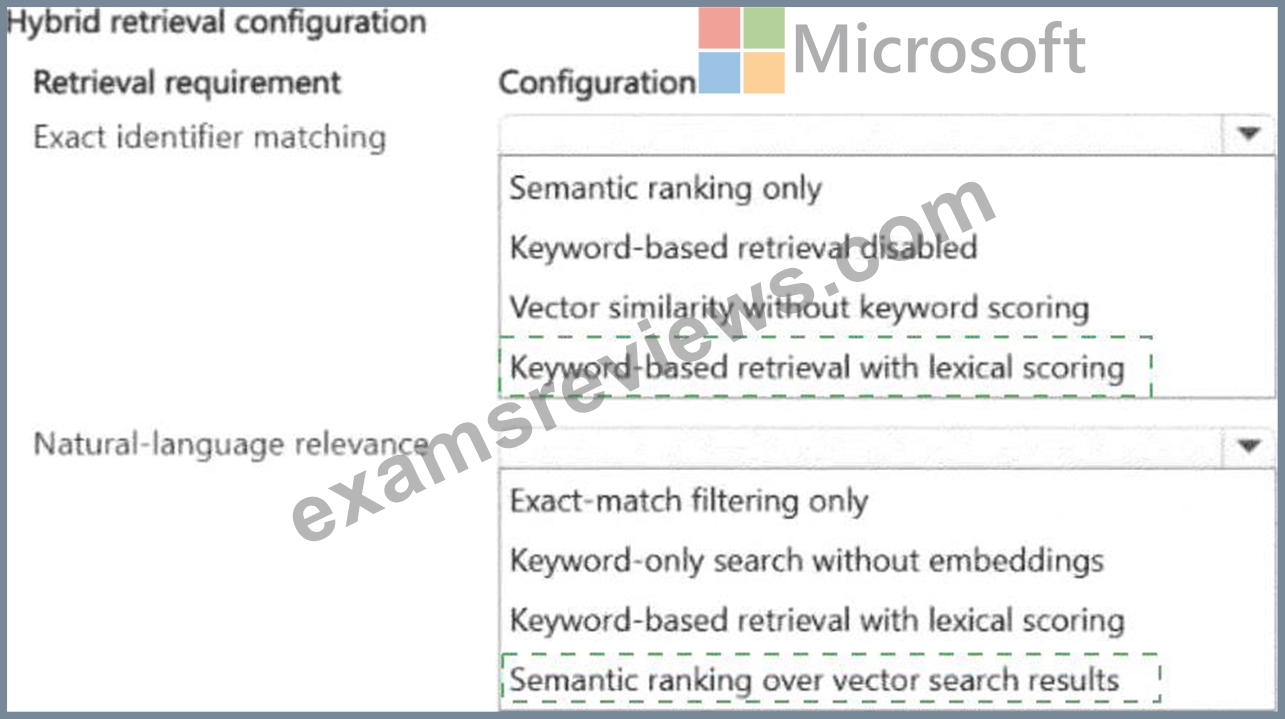
Explanation:
Different query types require fundamentally different retrieval algorithms. For queries that include exact policy identifiers, keyword or BM25 search is the correct choice because BM25 scores documents based on term frequency and inverse document frequency - an exact match on a specific policy identifier such as POL-
2024-HR-042 scores very highly regardless of semantic context. This is the right approach when semantic similarity is low but exact term matching is critical. For natural-language questions where keywords may not be an exact match, semantic or vector search is the correct choice because vector embeddings capture meaning rather than exact tokens, finding relevant documents even when the user ' s vocabulary differs from the document ' s terminology. Azure AI Search supports both modes through its hybrid search capability, and the correct configuration maps each query type to its optimal retrieval algorithm.
Microsoft Learn Reference Topic: Configure hybrid search in Azure AI Search - BM25 keyword search vs.
semantic vector search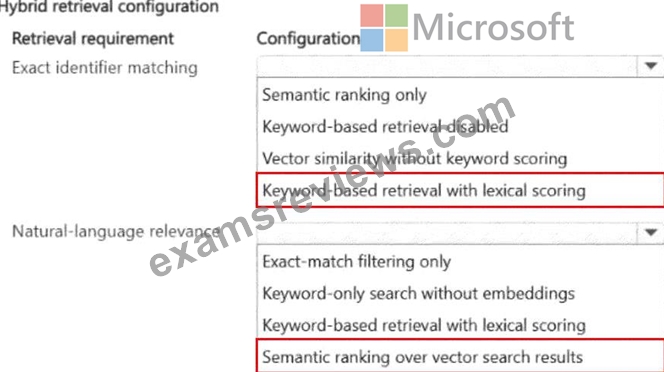
NEW QUESTION # 53
You have an Azure Machine Learning workspace named Workspace 1 Workspace! has a registered Mlflow model named model 1 with PyFunc flavor You plan to deploy model1 to an online endpoint named endpoint1 without egress connectivity by using Azure Machine learning Python SDK vl You have the following code: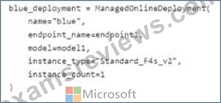
You need to add a parameter to the ManagedOnlineDeployment object to ensure the model deploys successfully Solution: Add the environment parameter.
Does the solution meet the goal?
Answer: B
NEW QUESTION # 54
......
It is very necessary for a lot of people to attach high importance to the AI-300 exam. It is also known to us that passing the exam is not an easy thing for many people, so a good study method is very important for a lot of people, in addition, a suitable study tool is equally important, because the good and suitable AI-300 reference guide can help people pass the exam in a relaxed state. We are glad to introduce the AI-300 certification study guide materials from our company to you. We believe our AI-300 study materials will be very useful and helpful for you to pass the AI-300 exam.
AI-300 Test Price: https://www.examsreviews.com/AI-300-pass4sure-exam-review.html
2026 Latest ExamsReviews AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1ueNInbQCbHYanfQli57Ctbd0dRew394a