HOT Databricks-Certified-Data-Engineer-Professional Practice Test Fee 100% Pass | Valid Databricks Certified Data Engineer Professional Exam Top Questions Pass for sure

The Databricks Databricks-Certified-Data-Engineer-Professional certification is on trending nowadays, and many Databricks aspirants are trying to get it. Success in the Databricks-Certified-Data-Engineer-Professional test helps you land well-paying jobs. Additionally, the Databricks-Certified-Data-Engineer-Professional certification exam is also beneficial to get promotions in your current company. But the main problem that every applicant faces while preparing for the Databricks-Certified-Data-Engineer-Professional Certification test is not finding updated Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice questions.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Quality and Governance | 12% | - Data Quality
- Data Lineage
- Governance
|
| Topic 2: Data Processing | 28% | - Structured Streaming
- ETL Pipelines
- Data Transformation
- Spark SQL
|
| Topic 3: Databricks Lakehouse Platform | 24% | - Unity Catalog
- Data Management
- Lakehouse Architecture
- Delta Lake
|
| Topic 4: Monitoring and Troubleshooting | 16% | - Performance Optimization
- Troubleshooting
- Monitoring
|
| Topic 5: Data Modeling and Storage | 20% | - File Formats
- Data Modeling
- Storage Optimization
|
>> Databricks-Certified-Data-Engineer-Professional Practice Test Fee <<
Databricks-Certified-Data-Engineer-Professional Top Questions & Reliable Databricks-Certified-Data-Engineer-Professional Test Pass4sure
VCETorrent is offering very reliable Databricks-Certified-Data-Engineer-Professional real questions answers. Our key advantages are that 1. We get first-hand information; 2. We provide one –year free updates; 3. We provide one-year customer service; 4. Pass guaranteed; 5. Money back guaranteed and so on. Purchasing our Databricks-Certified-Data-Engineer-Professional Real Questions answers will share worry-free shopping. If you fail exam with our exam questions, you just need to send your Databricks-Certified-Data-Engineer-Professional failure score scanned to our email address, we will full refund to you soon without any other doubt.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q177-Q182):
NEW QUESTION # 177
A data engineering team is configuring access controls in Databricks Unity Catalog. They grant the SELECT privilege on the sales catalog to the analyst_group, expecting that members of this group will automatically have SELECT access to all current and future schemas, tables, and views within the catalog. What describes the privilege inheritance behavior in Unity Catalog?
- A. Granting SELECT on a catalog automatically applies SELECT to all current and future schemas, tables, and views within that catalog.
- B. Granting SELECT at the catalog level applies to existing schemas and tables but not to those created in the future.
- C. Privileges granted at the schema level override any catalog-level privileges and prevent access unless explicitly revoked.
- D. Privileges in Unity Catalog do not cascade; SELECT must be explicitly granted on each schema and table, even if granted at the catalog level.
Answer: D
Explanation:
In Unity Catalog, privileges are non-cascading--meaning that granting a privilege (like SELECT) on a catalog does not automatically grant the same privilege on contained objects (schemas, tables, or views). Each object type has its own independent access control hierarchy.
According to the Databricks access control documentation: "Privileges do not automatically cascade from catalog to schema or table levels." Administrators must explicitly grant privileges on each level if users need access across objects. This design ensures tighter governance and least-privilege enforcement. Therefore, option B correctly describes Unity Catalog's privilege model, while A and D incorrectly imply automatic inheritance.
NEW QUESTION # 178
A Data engineer wants to run unit's tests using common Python testing frameworks on python functions defined across several Databricks notebooks currently used in production. How can the data engineer run unit tests against function that work with data in production?
- A. Define and unit test functions using Files in Repos
- B. Run unit tests against non-production data that closely mirrors production
- C. Define units test and functions within the same notebook
- D. Define and import unit test functions from a separate Databricks notebook
Answer: B
Explanation:
The best practice for running unit tests on functions that interact with data is to use a dataset that closely mirrors the production data. This approach allows data engineers to validate the logic of their functions without the risk of affecting the actual production data. It's important to have a representative sample of production data to catch edge cases and ensure the functions will work correctly when used in a production environment.
NEW QUESTION # 179
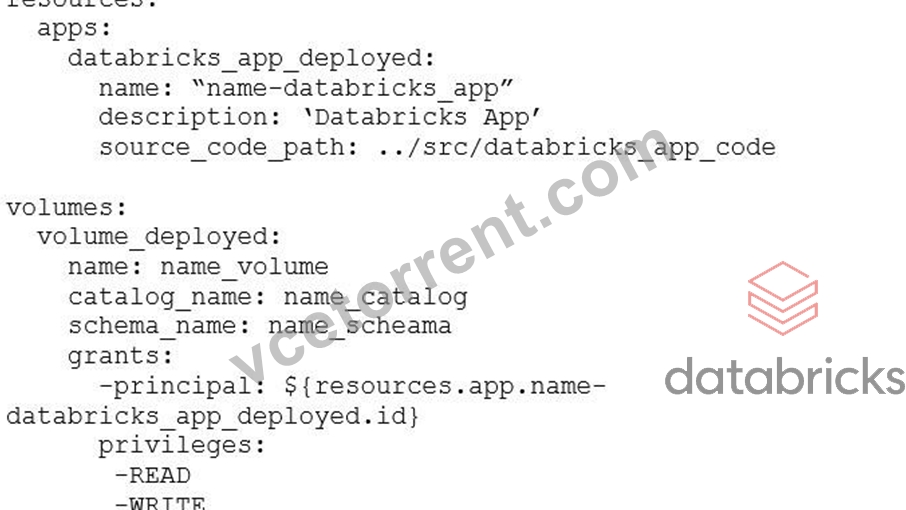
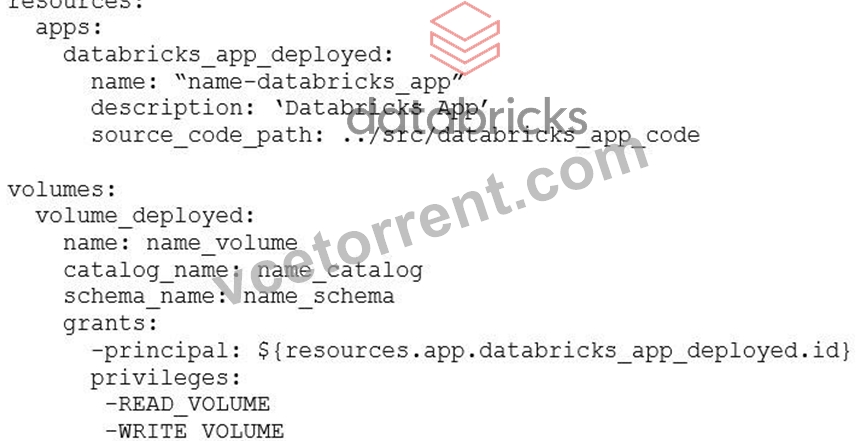
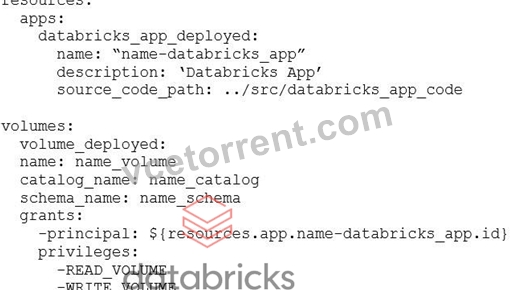
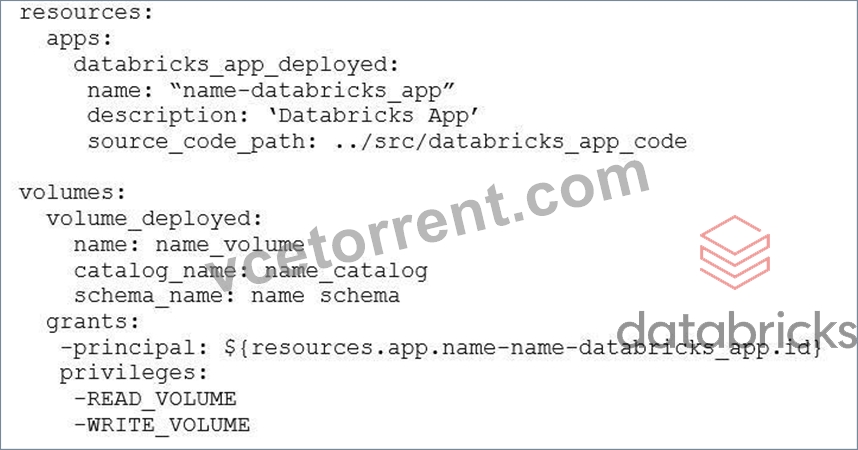
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Answer: B
Explanation:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
NEW QUESTION # 180
Which statement describes Delta Lake Auto Compaction?
- A. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- C. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- D. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- E. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
Answer: B
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
NEW QUESTION # 181
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control.
The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity. Which SQL query should the team run from the System catalog to achieve this?
- A. SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - B. SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - C. SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - D. SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10
Answer: D
Explanation:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non- existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 182
......
Our Databricks-Certified-Data-Engineer-Professional simulating exam is perfect for they come a long way on their quality. On one hand, we have engaged in this career for over ten years and have become the leader in this market. On the other hand, we never stop developing our Databricks-Certified-Data-Engineer-Professional study guide. And our Databricks-Certified-Data-Engineer-Professional Training Materials have the function to remember and correct your errors. If you commit any errors, Our Databricks-Certified-Data-Engineer-Professional learning questions can correct your errors with accuracy rate more than 98 percent.
Databricks-Certified-Data-Engineer-Professional Top Questions: https://www.vcetorrent.com/Databricks-Certified-Data-Engineer-Professional-valid-vce-torrent.html
- Real and Updated Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions 🚑 Search on 《 www.examcollectionpass.com 》 for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to obtain exam materials for free download 🏐Training Databricks-Certified-Data-Engineer-Professional Material
- Real and Updated Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions 🔩 Download ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ for free by simply searching on ➥ www.pdfvce.com 🡄 🌘Databricks-Certified-Data-Engineer-Professional Latest Exam Preparation
- Databricks-Certified-Data-Engineer-Professional Learning Mode 🍶 Databricks-Certified-Data-Engineer-Professional Test Preparation 🤐 Test Databricks-Certified-Data-Engineer-Professional Dumps Free 🎣 Open ⏩ www.vceengine.com ⏪ and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download exam materials for free 🧇Reliable Databricks-Certified-Data-Engineer-Professional Exam Materials
- Exam Databricks-Certified-Data-Engineer-Professional Cost ✡ New Databricks-Certified-Data-Engineer-Professional Exam Question 😍 Databricks-Certified-Data-Engineer-Professional Valid Exam Objectives 🖊 Easily obtain ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download through ▷ www.pdfvce.com ◁ 🎉Training Databricks-Certified-Data-Engineer-Professional Material
- Real and Updated Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions 🧙 Copy URL ➽ www.vceengine.com 🢪 open and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to download for free 🚟Vce Databricks-Certified-Data-Engineer-Professional Torrent
- Well-Prepared Databricks-Certified-Data-Engineer-Professional Practice Test Fee - Leading Offer in Qualification Exams - Accurate Databricks-Certified-Data-Engineer-Professional Top Questions 🏝 Open 《 www.pdfvce.com 》 and search for 【 Databricks-Certified-Data-Engineer-Professional 】 to download exam materials for free 🤭Latest Databricks-Certified-Data-Engineer-Professional Braindumps Sheet
- Databricks-Certified-Data-Engineer-Professional Latest Exam Preparation 📥 Databricks-Certified-Data-Engineer-Professional Books PDF 👏 Databricks-Certified-Data-Engineer-Professional Learning Mode ⛽ Search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ and download exam materials for free through ➥ www.verifieddumps.com 🡄 👋Latest Databricks-Certified-Data-Engineer-Professional Braindumps Sheet
- Test Databricks-Certified-Data-Engineer-Professional Dumps Free 🔽 Valid Databricks-Certified-Data-Engineer-Professional Practice Materials ⚽ Latest Databricks-Certified-Data-Engineer-Professional Braindumps Sheet 🥩 Immediately open ▷ www.pdfvce.com ◁ and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ to obtain a free download 📟New Databricks-Certified-Data-Engineer-Professional Exam Question
- Valid Braindumps Databricks-Certified-Data-Engineer-Professional Ppt 🧟 Reliable Databricks-Certified-Data-Engineer-Professional Exam Materials 🏬 Valid Test Databricks-Certified-Data-Engineer-Professional Tutorial ⌛ Open ⮆ www.easy4engine.com ⮄ enter ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and obtain a free download 🥎Databricks-Certified-Data-Engineer-Professional Books PDF
- Real and Updated Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions 🔖 Immediately open 《 www.pdfvce.com 》 and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to obtain a free download 🍍Vce Databricks-Certified-Data-Engineer-Professional Torrent
- Pass Guaranteed Quiz 2026 High Pass-Rate Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Practice Test Fee 🦁 Search on ➥ www.vce4dumps.com 🡄 for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to obtain exam materials for free download 🕓Exam Databricks-Certified-Data-Engineer-Professional Cost
- www.stes.tyc.edu.tw, www.twosapp.com, www.stes.tyc.edu.tw, www.impactio.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes