Study Databricks Certified-Data-Engineer-Professional Test, Certified-Data-Engineer-Professional Reliable Braindumps Questions

DOWNLOAD the newest PassReview Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1l6zbkU7jOaNzjsEUAdR9LtcK8541SCnr
Being scrupulous in this line over ten years, our experts are background heroes who made the high quality and high accuracy Certified-Data-Engineer-Professional study quiz. By abstracting most useful content into the Certified-Data-Engineer-Professional guide materials, they have helped former customers gain success easily and smoothly. We can claim that if you prapare with our Certified-Data-Engineer-Professional Exam Braindumps for 20 to 30 hours, then you will be confident to pass the exam.
| Section | Objectives |
|---|
| Topic 1: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 2: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
|
| Topic 3: Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Topic 4: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 5: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 7: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Topic 8: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 9: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 10: Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
>> Study Databricks Certified-Data-Engineer-Professional Test <<
Databricks Certified-Data-Engineer-Professional Reliable Braindumps Questions | Certified-Data-Engineer-Professional New Study Guide
We even guarantee our customers that they will pass Databricks Certified-Data-Engineer-Professional exam easily with our provided study material and if they failed to do it despite all their efforts they can claim a full refund of their money (terms and conditions apply). The third format is the desktop software format which can be accessed after installing the software on your Windows computer or laptop. The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) has three formats so that the students don't face any serious problems and prepare themselves with fully focused minds.
Databricks Certified Data Engineer Professional Sample Questions (Q224-Q229):
NEW QUESTION # 224
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
- A. Troubleshooting is easier since all steps are isolated and tested individually
- B. Yields faster deployment and execution times
- C. Improves the quality of your data
- D. Validates a complete use case of your application
- E. Ensures that all steps interact correctly to achieve the desired end result
Answer: A
NEW QUESTION # 225
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
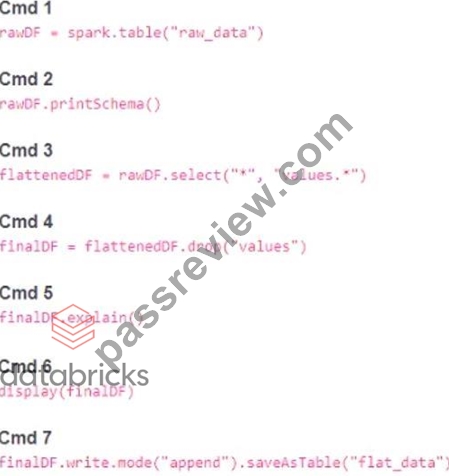
Which command should be removed from the notebook before scheduling it as a job?
- A. Cmd 4
- B. Cmd 3
- C. Cmd 2
- D. Cmd 5
- E. Cmd 6
Answer: E
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 226
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A. pyspsark.ml.feature
- B. Regex
- C. C++
- D. Scala Datasets
- E. Julia
Answer: B
Explanation:
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks.
NEW QUESTION # 227
A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high- cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time. Which command should the data engineer implement?
- A. Alter the table to use Liquid Clustering and implement a periodic OPTIMIZE command.
- B. Alter the table to use Hive-Style Partitions + Z-ORDER and implement a periodic OPTIMIZE command.
- C. Alter the table to use Z-ORDER and implement a periodic OPTIMIZE command.
- D. Alter the table to use Hive-Style Partitions and implement a periodic OPTIMIZE command.
Answer: A
Explanation:
Databricks recommends Liquid Clustering for optimizing data layout in large Delta tables where query filters involve high-cardinality columns. Liquid Clustering automatically manages file organization and supports incremental maintenance without the need to rewrite data when clustering keys evolve. This is a key advantage over static partitioning or Z-ordering, which require costly file rewrites whenever optimization keys change. By combining Liquid Clustering with a periodic OPTIMIZE command, Databricks automatically compacts small files and maintains efficient data skipping performance. As stated in the Delta Lake optimization guide, Liquid Clustering is designed for scalability, minimal maintenance, and adaptability for analytical workloads with evolving query patterns--making B the correct answer.
NEW QUESTION # 228
A data team is working to optimize an existing large, fast-growing table 'orders' with high cardinality columns, which experiences significant data skew and requires frequent concurrent writes. The team notice that the columns 'user_id', 'event_timestamp' and 'product_id' are heavily used in analytical queries and filters, although those keys may be subject to change in the future due to different business requirements. Which partitioning strategy should the team choose to optimize the table for immediate data skipping, incremental management over time, and flexibility?
- A. Z-order the table with OPTIMIZE orders ZORDER BY (user_id, product_id, event_timestamp)
- B. Cluster the table with: ALTER TABLE orders CLUSTER BY user_id, product_id, event_timestamp
- C. Partition the table with: ALTER TABLE orders PARTITION BY user_id, product_id, event_timestamp
- D. Use z-order after partitiing the table: OPTIMIZE orders ZORDER BY (user_id, product_id) WHERE event_timestamp = current date () - 1 DAY
Answer: A
Explanation:
Z-ordering optimizes data skipping for selective queries on high-cardinality columns without physically repartitioning the table, making it flexible if query patterns change. Using OPTIMIZE ...
ZORDER BY (user_id, product_id, event_timestamp) improves query performance for filters and joins while allowing incremental writes, avoiding the data skew and maintenance overhead that explicit partitioning or clustering could introduce.
NEW QUESTION # 229
......
In peacetime, you may take months or even a year to review a professional exam, but with Certified-Data-Engineer-Professional exam guide, you only need to spend 20-30 hours to review before the exam, and with our Certified-Data-Engineer-Professional study materials, you will no longer need any other review materials, because our Certified-Data-Engineer-Professional study materials has already included all the important test points. At the same time, Certified-Data-Engineer-Professional Study Materials will give you a brand-new learning method to review - let you master the knowledge in the course of the doing exercise. You will pass the Certified-Data-Engineer-Professional exam easily and leisurely.
Certified-Data-Engineer-Professional Reliable Braindumps Questions: https://www.passreview.com/Certified-Data-Engineer-Professional_exam-braindumps.html
- Certified-Data-Engineer-Professional Valid Cram Materials 🚼 Certified-Data-Engineer-Professional Reliable Test Sims 🔽 Certified-Data-Engineer-Professional Pdf Version 👋 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download exam materials for free through ✔ www.pass4test.com ️✔️ 🦡Certified-Data-Engineer-Professional Premium Exam
- Certified-Data-Engineer-Professional Valid Exam Test 📐 Certified-Data-Engineer-Professional Actualtest 🎐 Certified-Data-Engineer-Professional Valid Test Blueprint 🧤 Search for ▷ Certified-Data-Engineer-Professional ◁ and download exam materials for free through ( www.pdfvce.com ) 🍯New Certified-Data-Engineer-Professional Mock Test
- Certified-Data-Engineer-Professional Test Dumps Free 🏺 Certified-Data-Engineer-Professional Valid Exam Cost 🔶 Certified-Data-Engineer-Professional Latest Exam Notes 🤾 Enter 「 www.prep4sures.top 」 and search for ▷ Certified-Data-Engineer-Professional ◁ to download for free 🤷Certified-Data-Engineer-Professional Actualtest
- Take Your Exam Preparations Anywhere with Portable Certified-Data-Engineer-Professional PDF Questions from Pdfvce 🧛 Open ➡ www.pdfvce.com ️⬅️ enter ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download 🕗Certified-Data-Engineer-Professional Reliable Test Sims
- Test Certified-Data-Engineer-Professional Registration 🥒 Certified-Data-Engineer-Professional Trustworthy Pdf 🏗 Certified-Data-Engineer-Professional Valid Exam Test 📽 Search for ( Certified-Data-Engineer-Professional ) and download it for free on ⇛ www.prepawaypdf.com ⇚ website 🍟Test Certified-Data-Engineer-Professional Registration
- Certified-Data-Engineer-Professional Valid Cram Materials 😅 Certified-Data-Engineer-Professional Pdf Version 🪓 Test Certified-Data-Engineer-Professional Registration 👄 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply searching on ➠ www.pdfvce.com 🠰 🔸Certified-Data-Engineer-Professional Premium Exam
- Certified-Data-Engineer-Professional Valid Exam Test 🏌 Test Certified-Data-Engineer-Professional Registration 🎊 New Certified-Data-Engineer-Professional Test Review 🥧 Search for [ Certified-Data-Engineer-Professional ] and download it for free on ➽ www.troytecdumps.com 🢪 website 🍇Certified-Data-Engineer-Professional Actualtest
- Get Real Databricks Certified-Data-Engineer-Professional Exam Experience with Desktop-Practice Test Software 🧺 Download ➽ Certified-Data-Engineer-Professional 🢪 for free by simply entering { www.pdfvce.com } website 🤖Certified-Data-Engineer-Professional Pdf Version
- Certified-Data-Engineer-Professional Valid Exam Cost 🕸 Instant Certified-Data-Engineer-Professional Download ♿ Reliable Certified-Data-Engineer-Professional Exam Questions 🦐 Download ➤ Certified-Data-Engineer-Professional ⮘ for free by simply searching on ▷ www.vce4dumps.com ◁ 🐍New Certified-Data-Engineer-Professional Test Review
- New Certified-Data-Engineer-Professional Mock Test 🧎 New Certified-Data-Engineer-Professional Mock Test 📝 Certified-Data-Engineer-Professional Valid Exam Cost 🐧 Search on 【 www.pdfvce.com 】 for ➽ Certified-Data-Engineer-Professional 🢪 to obtain exam materials for free download 🍽Certified-Data-Engineer-Professional Test Dumps Free
- Reliable Certified-Data-Engineer-Professional Exam Questions 📝 Certified-Data-Engineer-Professional Reliable Practice Materials 🏗 Certified-Data-Engineer-Professional Reliable Practice Materials 😻 Simply search for ⮆ Certified-Data-Engineer-Professional ⮄ for free download on 「 www.troytecdumps.com 」 🚐Certified-Data-Engineer-Professional Valid Exam Cost
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 Databricks Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1l6zbkU7jOaNzjsEUAdR9LtcK8541SCnr