P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=11EVjZ9ONF4Rh0aWti6tdfiPG5yC4g_Ag
The Developing AI Apps and Agents on Azure (AI-103) actual questions we sell also come with a free demo. Spend no time, otherwise, you will pass on these fantastic opportunities. Start preparing for the Developing AI Apps and Agents on Azure (AI-103) exam by purchasing the most recent Microsoft AI-103 exam dumps. You must improve your skills and knowledge to stay current and competitive. You merely need to obtain the AI-103 Certification Exam badge in order to achieve this. You must pass the Developing AI Apps and Agents on Azure exam to accomplish this, which can only be done with thorough exam preparation. Download the Developing AI Apps and Agents on Azure (AI-103) exam questions right away for immediate and thorough exam preparation.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement information extraction and knowledge mining | 10–15% | - Build knowledge bases and search solutions
|
| Topic 2: Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
| Topic 3: Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Topic 4: Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
| Topic 5: Implement text and speech analysis solutions | 10–15% | - Implement speech capabilities
|
Prep4King offers highly designed Microsoft AI-103 exam questions and online AI-103 practice test engine to help you successfully clear the Microsoft exam. Their study materials cover all the basic to advanced required AI-103 Exam Questions material that you need to know to pass the AI-103 Exam. These two simple, easy, and accessible learning formats will boost your confidence.
NEW QUESTION # 62
You have a Microsoft Foundry project that contains an agent.
You need to enable long-term memory to ensure that the agent can recall user preferences across separate conversations. Stored memories must be isolated per authenticated user without the client application manually generating user IDs.
How should you complete the Python code? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all.
NOTE: Each correct selection is worth one point.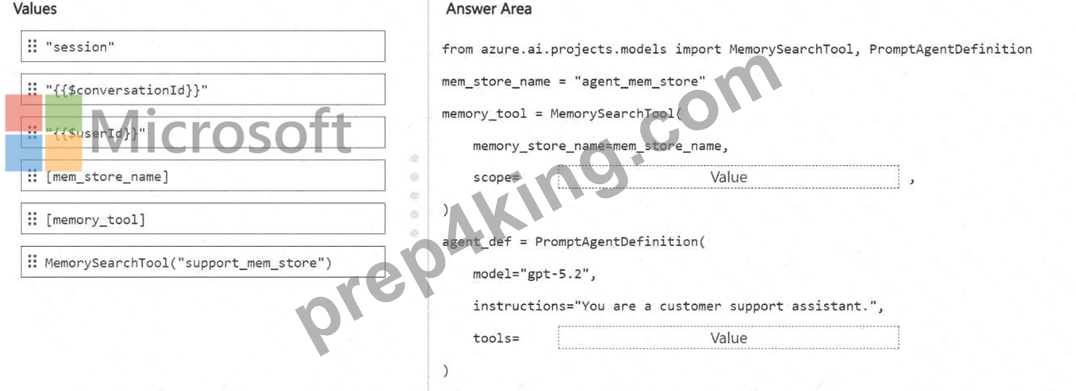
Answer:
Explanation: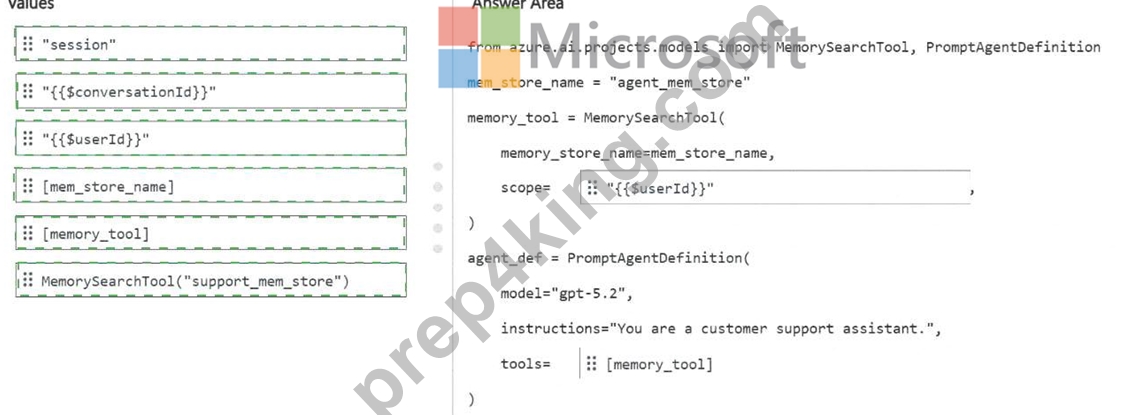
Explanation:
scope = " {{userId}} "
tools = [memory_tool]
The correct scope value is {{userId}} because the requirement is per-authenticated-user memory isolation without the client application manually generating user identifiers. In Microsoft Foundry Agent Service memory, the scope parameter partitions memory items inside the memory store. The official guidance states that when the memory search tool is attached to an agent, setting scope to the user identity template enables per-user memory isolation; the service resolves the end-user identity from the request header when provided, or falls back to the Microsoft Entra tenant ID and object ID of the caller. This matches the requirement to isolate stored preferences by authenticated user automatically.
The tools property must be [memory_tool] because the MemorySearchTool instance is created earlier and must be attached to the PromptAgentDefinition. Foundry guidance shows the memory search tool being passed in the agent definition as tools=[tool] , allowing the agent to read from and write to the configured memory store during conversations.
" session " and {{conversationId}} would limit continuity to a session or conversation instead of enabling long-term recall across separate conversations. [mem_store_name] is a list containing the store name, not a tool definition. Reference topics: Foundry Agent Service memory, memory stores, memory search tools, scope, and per-user isolation.
NEW QUESTION # 63
Hotspot Question
You develop a test method to verify the results retrieved from a call to the Azure Vision in Foundry Tools API. The call is used to analyze the existence of company logos in images. The call returns a collection of brands named brands.
You have the following code segment: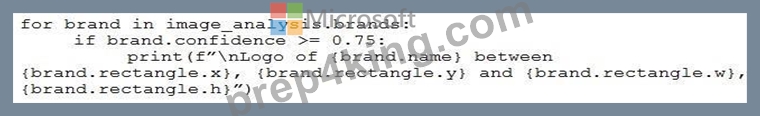
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.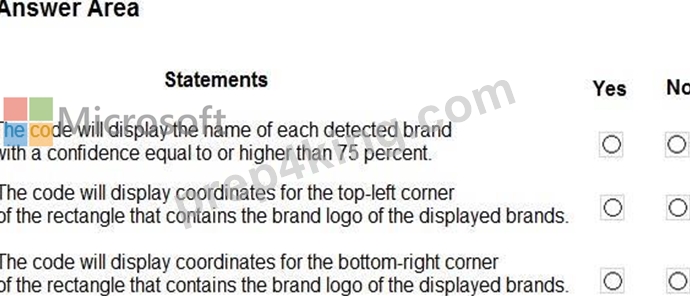
Answer:
Explanation: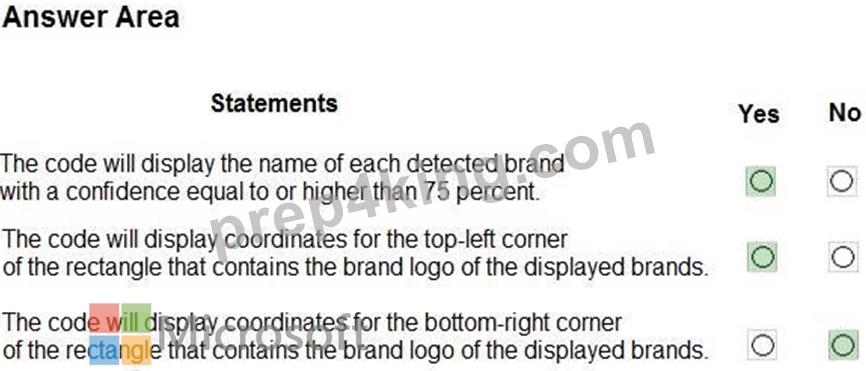
Explanation:
Box 1: Yes
The code segment correctly filters for and displays the name (and coordinates) of each detected brand only if the model's confidence score is 75 percent or higher.The expression if brand.confidence >= 0.75 guarantees that only brands meeting or exceeding this threshold are printed.
Box 2: Yes
The code segment will display the coordinates. Specifically, it prints the x and y values of the rectangle's top-left corner alongside its width (w) and height (h) for any detected brand with a confidence score equal to or greater than 0.75 (75%).
The provided code uses the properties directly to extract the bounding box:
brand.rectangle.x and brand.rectangle.y: The coordinates of the top-left corner of the bounding box.
brand.rectangle.w and brand.rectangle.h: The width and height of the bounding box.
Box 3: No
See Box 2 above.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/concept-brand-detection
NEW QUESTION # 64
You have a Microsoft Foundry project that processes procurement documents submitted by suppliers.
You need to implement two pipelines by using Azure Content Understanding in Foundry Tools. The solution must meet the following requirements:
* Include a pipeline named Pipeline1 that supports cost-effective, high-volume processing of standalone PDF invoices.
* Include a pipeline named Pipeline2 that supports cross-document validation by using multi-step reasoning and reference data.
How should you configure each pipeline? To answer, drag the appropriate configurations to the correct pipelines. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.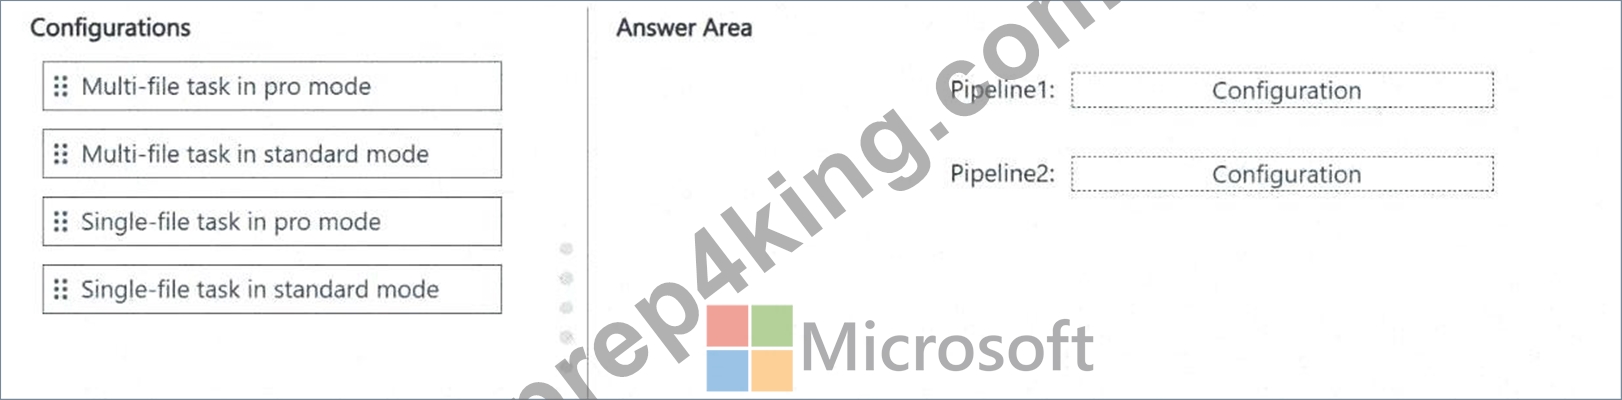
Answer:
Explanation: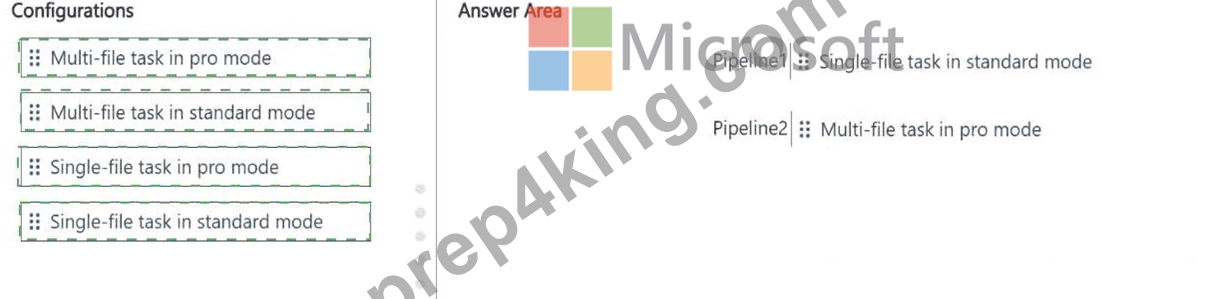
Explanation:
Pipeline1: Single-file task in standard mode
Pipeline2: Multi-file task in pro mode
Pipeline1 should use a single-file task in standard mode because the workload is high-volume processing of standalone PDF invoices. Azure Content Understanding standard mode is intended for individual files that require straightforward structured extraction, and Microsoft describes it as minimizing cost and latency for broad, data-centric processing scenarios. This makes it the best fit for cost-effective invoice extraction where each PDF can be processed independently.
Pipeline2 should use a multi-file task in pro mode because the requirement includes cross-document validation, multi-step reasoning, and reference data. Microsoft guidance states that pro mode is designed for advanced scenarios requiring multi-step reasoning and cross-file analysis, including processing multiple input files in a single request, validating or enriching data across documents, and using reference data to guide extraction and validation.
Single-file pro mode would add unnecessary capability for Pipeline1 and would not optimize for cost- effective high-volume standalone processing. Multi-file standard mode does not meet the pro-mode requirement for reference-data-based reasoning. Reference topics: Azure Content Understanding standard mode, pro mode, single-file tasks, multi-file tasks, field extraction, and procurement document validation.
NEW QUESTION # 65
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a Microsoft Foundry project that contains an agent. The agent generates summaries from retrieved policy documents.
Users report that some responses omit required regulatory clauses, even when the clauses are present in the retrieved content.
You need to improve response completeness.
Solution: You increase the value of the temperatureparameter.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You add a reflection pass that regenerates the response if the required clauses are missing.
This is Self-Correction Strategy: A reflection pass allows an agent to evaluate its own initial output against specified constraints (e.g., checking for the presence of mandatory regulatory clauses). If the required text is missing, the agent triggers a programmatic self-correction or regeneration loop to include them before final delivery.
Incorrect:
* You increase the value of the max_tokens parameter.
Increasing the max_tokens parameter prevents the response from being cut off mid-sentence due to length constraints. However, it does not force the model's logic to explicitly include missing information that it chose to leave out earlier in the text.
* You increase the value of the temperature parameter.
Raising the temperature parameter increases randomness and creativity. For rigid compliance tasks like summarizing regulatory documents, higher temperature actually increases the risk of hallucination and omission.
* You run an evaluation flow that scores responses for completeness and blocks responses that fall below a defined threshold.
Evaluation Flow Block: Running an evaluation flow to score completeness and blocking bad responses identifies and stops low-quality outputs, but it does not fix or actively improve the response completeness. It simply filters failures out of the system.
Reference:
https://pub.towardsai.net/reflection-with-llm-how-to-make-ai-review-its-own-work-2db122fca1d8
NEW QUESTION # 66
Hotspot Question
Your company is piloting a customer support agent in a Microsoft Foundry project name Project1.
Project1 is connected to an existing Application Insights resource, and the company's support team reviews runs in the Traces tab.
The Foundry Agent Service is configured to perform the following actions:
- Retrieve the Application Insights connection string by calling
project_client.telemetry.get_application_insights_connection_string().
- Call configure_azure_monitor(connection_string=...) to enable
telemetry.
A separate LangChain service is configured to use OpenTelemetry and has the following configurations:
- Uses AzureAIOpenTelemetryTracer(connection_string=...,
enable_content_recording=False)
- Passes the tracer by using config={"callbacks":[azure_tracer]}
Company policy has the following requirements:
- Telemetry from LangChain and OpenTelemetry must be distinguishable
within the same Application Insights resource.
- Secrets and credentials must NOT be stored in prompts, tool
arguments, or span attributes.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.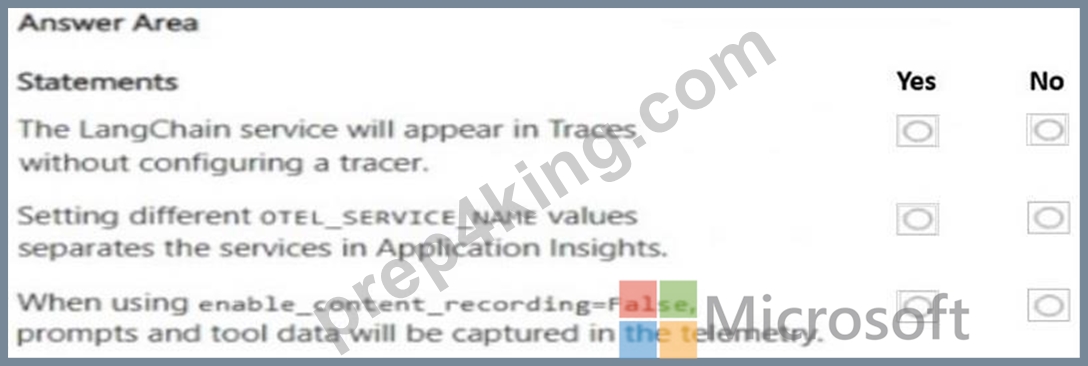
Answer:
Explanation: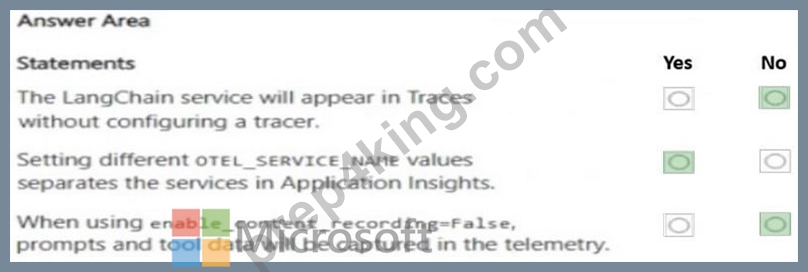
NEW QUESTION # 67
......
In the process of preparing the passing test, our AI-103 guide materials and service will give you the oriented assistance. We can save your time and energy to arrange time schedule, search relevant books and document, ask the authorized person. As our AI-103 Study Materials are surely valid and high-efficiency, you should select us if you really want to pass AI-103 exam one-shot. With so many advantages of our AI-103 training engine to help you enhance your strength, why not have a try?
AI-103 Test Prep: https://www.prep4king.com/AI-103-exam-prep-material.html
DOWNLOAD the newest Prep4King AI-103 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=11EVjZ9ONF4Rh0aWti6tdfiPG5yC4g_Ag