Work hard and practice with our Microsoft AI-200 dumps till you are confident to pass the Microsoft AI-200 exam. And that too with flying colors and achieving the Microsoft AI-200 Certification on the first attempt. You will identify both your strengths and shortcomings when you utilize Developing AI Cloud Solutions on Azure practice exam software.
| Section | Objectives |
|---|---|
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search |
| Plan and manage Azure AI solutions | - Monitor and optimize AI solutions - Select appropriate Azure AI services - Plan security and compliance requirements |
>> Sample AI-200 Questions Answers <<
As we all know, time and tide waits for no man. If you really want to pass the AI-200 exam, you should choose our first-class AI-200 study materials. And you cannot miss the opportunities this time for as the most important and indispensable practice materials in this line, we have confidence in the quality of our AI-200 practice materials, and offer all after-sales services for your consideration and acceptance.
NEW QUESTION # 65
An AI application uses a database. The database credential rotates every 30 days.
The application currently requires a manual update each time the credential rotates.
You need to ensure that the application always uses the latest secret version without manual updates.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Configure a Key Vault rotation policy to automate periodic credential generation and updates.
Retrieve secrets without a version identifier (versionless reference) so the app automatically resolves the newest active version.
Incorrect:
[Not B]
To stop manual updates, you should not retrieve secrets by specifying a version identifier, because locking in a version stops the application from seeing newer updates.
Reference:
https://learn.microsoft.com/en-us/azure/key-vault/secrets/secure-secrets
NEW QUESTION # 66
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.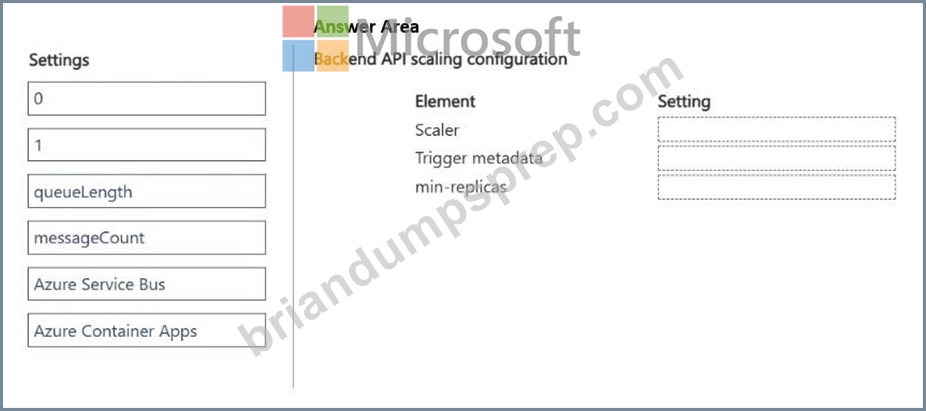
Answer:
Explanation: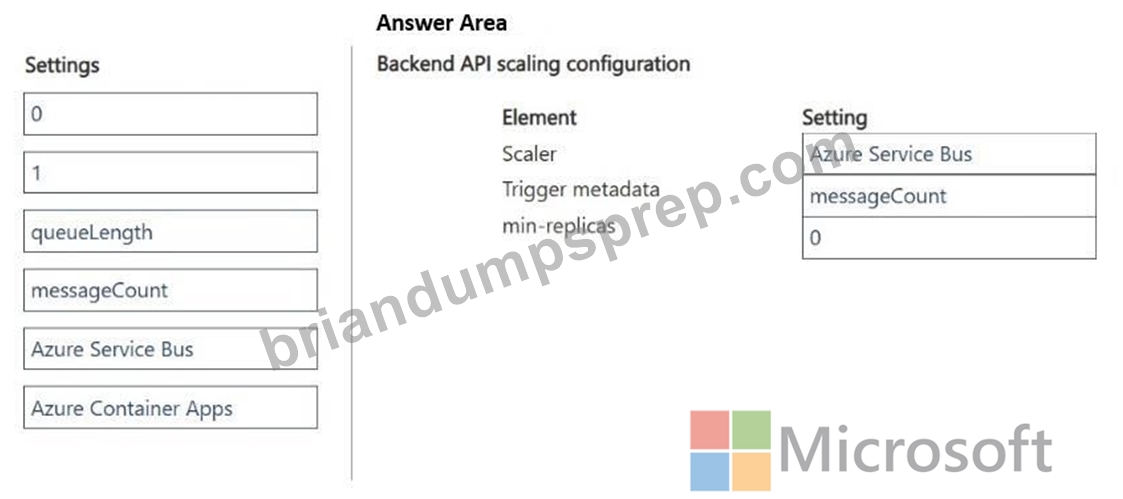
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 67
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The result codes are sorted alphabetically.
Does the solution meet the goal?
Answer: B
Explanation:
The solution does not meet the goal because the query does not sort by resultCode. The summarize operator groups request records by each distinct resultCode value and calculates the number of requests in each group by using count().
The resulting table contains a resultCode column and a calculated request_count column. The next statement:
| order by request_count desc
sorts the output by request_count in descending order , which places the most frequently occurring result code first and the least frequent last.
Therefore, the output is sorted by frequency , not alphabetically or numerically by the resultCode field.
If alphabetical sorting by result code were required, the query would instead use a statement such as:
| order by resultCode asc
That is not what the provided query does.
Because the Logs blade is already scoped to the Last 24 hours , the query operates over that selected time range unless additional time filtering is explicitly added.
Study Guide references: Azure Monitor Logs; Application Insights requests table; KQL summarize; count() aggregation; order by; descending sort semantics.
NEW QUESTION # 68
You need to configure image build automation based on the technical requirements.
Which settings should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.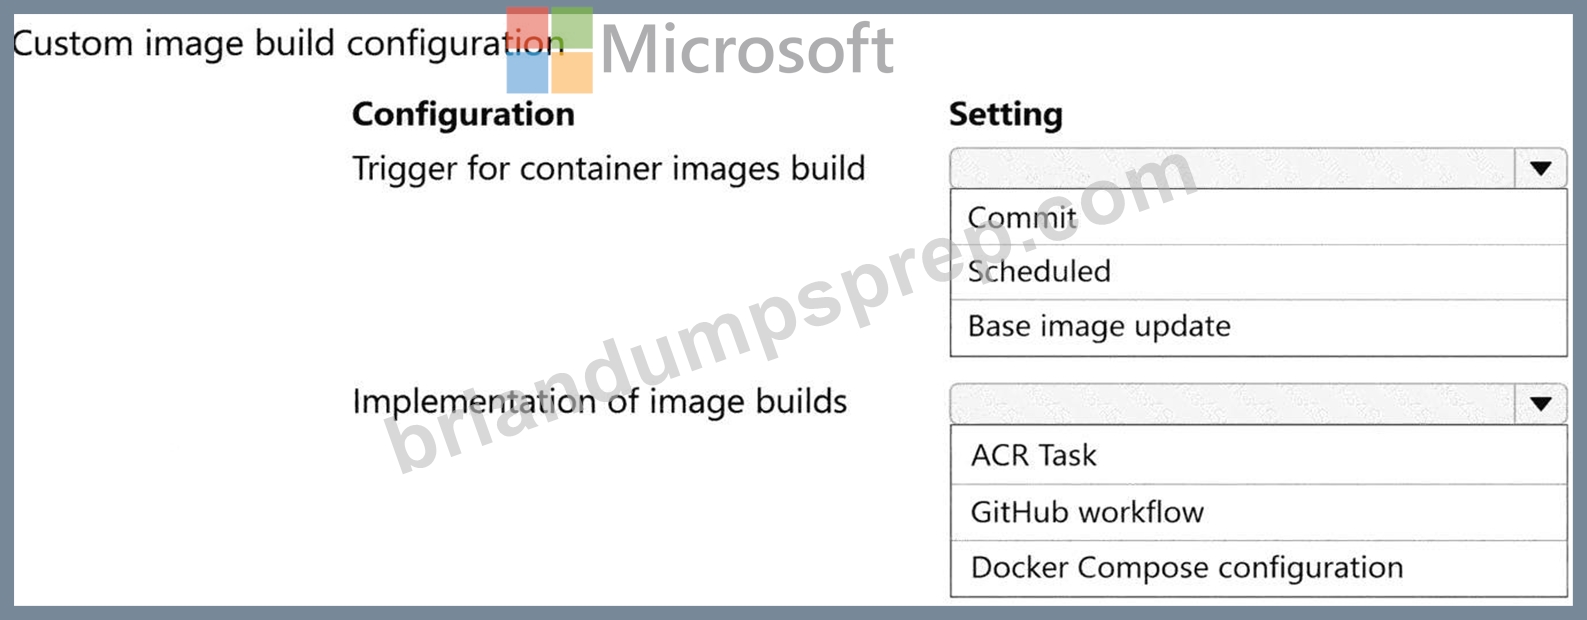
Answer:
Explanation: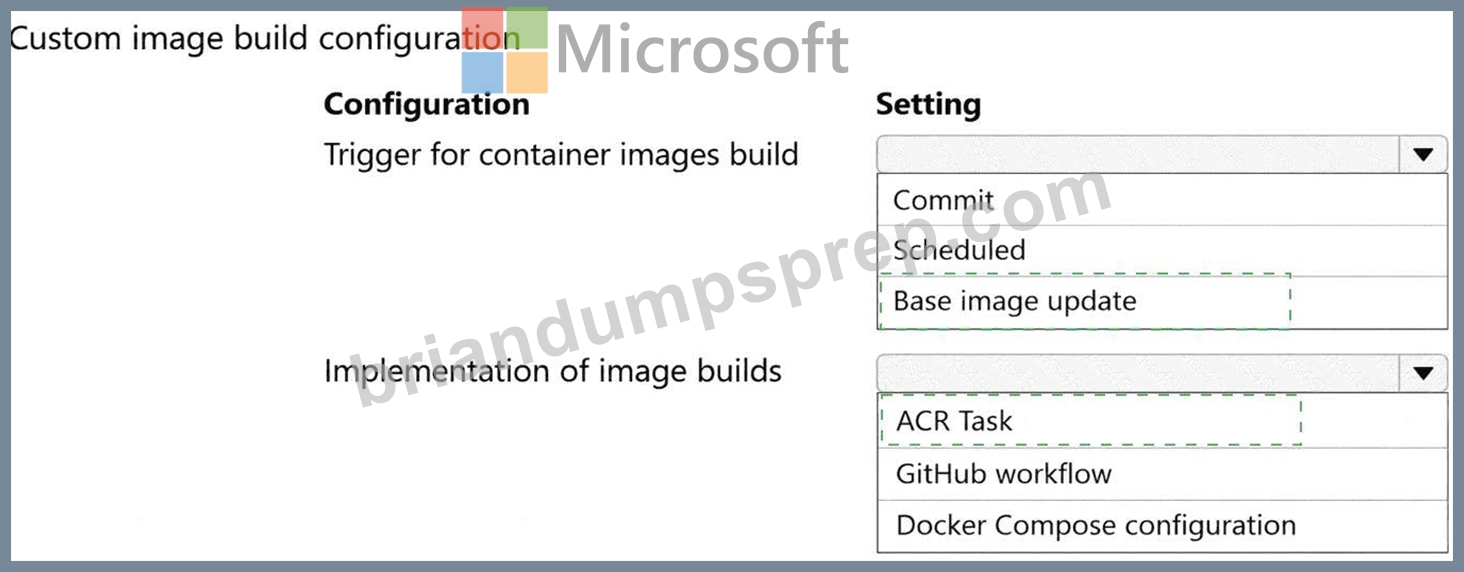
Explanation:
* Trigger for container images build: Base image update
* Implementation of image builds: ACR Task
The correct trigger is Base image update because Proseware requires every custom container image to be rebuilt automatically whenever its Docker Hub base image changes. Azure Container Registry Tasks can detect base-image dependencies from the Dockerfile FROM instruction and automatically trigger a rebuild when that base image is updated. Microsoft confirms that ACR Tasks can track base images in public repositories such as Docker Hub and Microsoft Container Registry, as well as images stored in Azure Container Registry.
The build implementation must be an ACR Task . This directly satisfies the technical requirement that image- build automation run inside Azure Container Registry , eliminating dependencies on local developer machines or separate external build services. ACR Tasks provides cloud-based container building and can automate builds based on source-code commits, base-image updates, or scheduled triggers.
A GitHub workflow could orchestrate CI/CD, but using it as the actual image-building implementation would conflict with the explicit requirement that builds execute inside ACR. Docker Compose defines multi- container applications; it is not the native ACR build automation mechanism. A Commit trigger addresses source changes rather than the stated base-image update requirement, while Scheduled builds would introduce unnecessary periodic execution.
Study Guide references: Azure Container Registry Tasks; base-image dependency tracking; automated rebuilds; Docker Hub base-image triggers; cloud-native container builds.
NEW QUESTION # 69
Hotspot Question
You have an Azure Functions app using the Consumption hosting plan for a company. The app contains the following functions: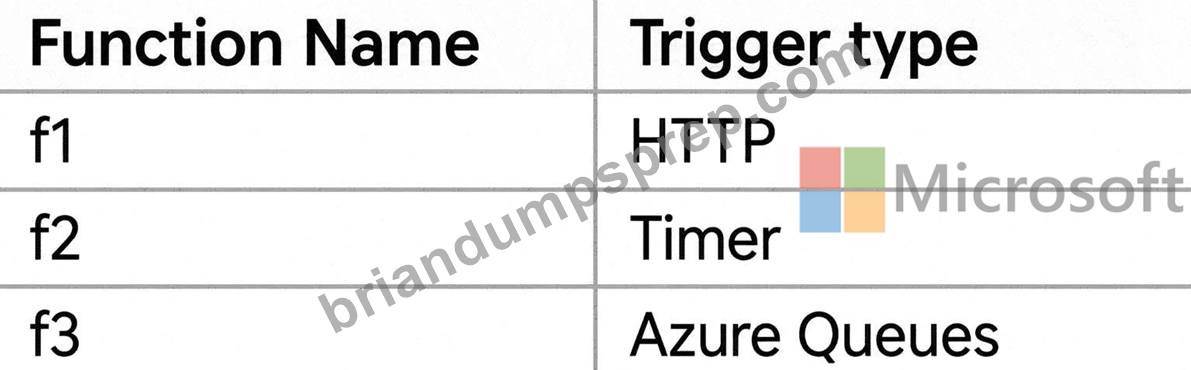
You plan to enable dynamic concurrency on the app. The company requires that each function has its concurrency level managed separately.
You need to configure the app for dynamic concurrency.
Which file or function names should you use? To answer, select the appropriate values in the answer area.
NOTE: Each correct selection is worth one point.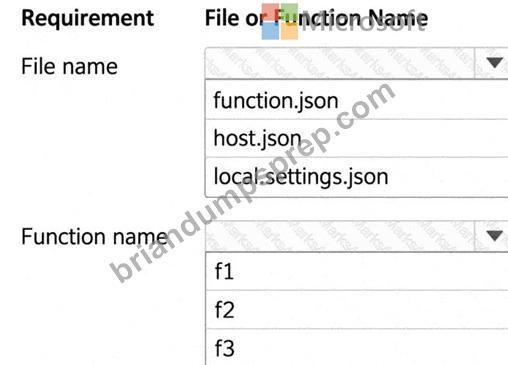
Answer:
Explanation: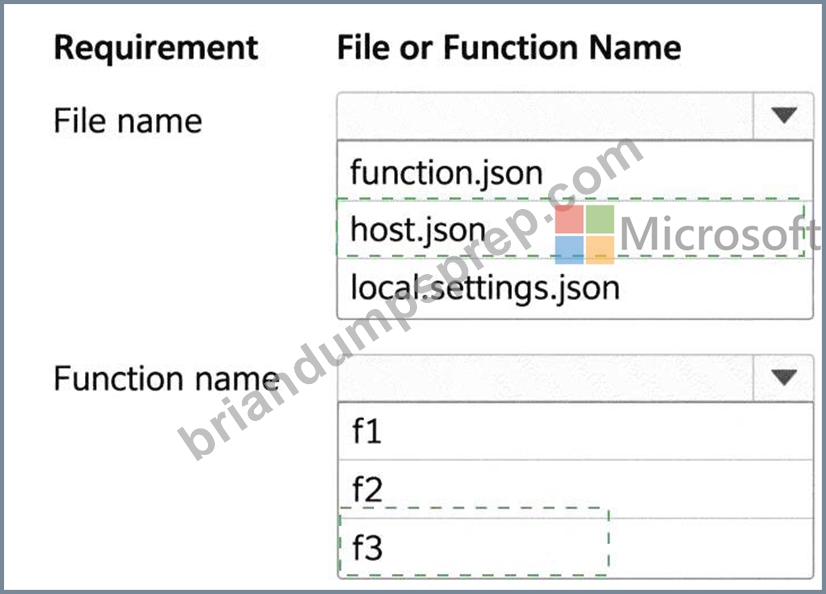
Explanation:
* File name: host.json
* Function name: f3
Azure Functions dynamic concurrency is enabled at the function-app host level in the host.json file . The concurrency configuration section contains the dynamicConcurrencyEnabled property. Setting this value to true enables the Functions host to dynamically learn and adjust concurrency levels for supported triggers rather than requiring fixed manual limits.
Although dynamic concurrency is enabled globally, Microsoft explicitly states that the learned concurrency level is managed independently for each individual function . This allows a resource-intensive function to operate at a lower concurrency level while a lightweight function in the same app can execute with greater concurrency, protecting host health while maximizing throughput.
Of the functions listed, f3 , which uses an Azure Queue Storage trigger , supports dynamic concurrency.
Microsoft currently documents dynamic concurrency support for Azure Queue Storage, Azure Blob Storage, and Azure Service Bus triggers , subject to the required extension versions. HTTP and Timer triggers do not participate in this dynamic-concurrency model.
Therefore, configure dynamic concurrency in host.json , and f3 is the function whose concurrency will be dynamically managed.
Study Guide references: Azure Functions # Concurrency; Dynamic concurrency; host.json; Queue Storage trigger concurrency.
NEW QUESTION # 70
......
If you do not have access to internet most of the time, if you need to go somewhere is in an offline state, but you want to learn for your AI-200 exam. Don not worry, our products will help you solve your problem. We deeply believe that our latest AI-200 Exam Torrent will be very useful for you to strength your ability, pass your exam and get your certification. Our study materials with high quality and high pass rate in order to help you get out of your harassment.
AI-200 Exam Dumps.zip: https://www.briandumpsprep.com/AI-200-prep-exam-braindumps.html