Pass Guaranteed DY0-001 - High Pass-Rate CompTIA DataAI Certification Exam Free Dumps

P.S. Free & New DY0-001 dumps are available on Google Drive shared by Easy4Engine: https://drive.google.com/open?id=1zv2h9rK1RqJFPK4lS8CY-c71BwNloVBr

In the information era, IT industry is catching more and more attention. In the society which has a galaxy of talents, there is still lack of IT talents. Many companies need IT talents, and generally, they investigate IT talents's ability in according to what IT related authentication certificate they have. So having some IT related authentication certificate is welcomed by many companies. But these authentication certificate are not very easy to get. CompTIA DY0-001 is a quite difficult certification exams. Although a lot of people participate in CompTIA DY0-001 exam, the pass rate is not very high.

CompTIA DY0-001 Exam Syllabus Topics:

SectionWeightObjectives
Modeling, Analysis, and Outcomes24%- Model Development
  • 1. Model selection, validation, evaluation
    - Data Issues and Preparation
    • 1. Feature engineering and transformation
      • 2. Missing data, outliers, sparsity
        - Exploratory Data Analysis (EDA)
        • 1. Univariate and multivariate analysis
          • 2. Feature identification and visualization
            - Communication of Results
            • 1. Avoiding misleading charts
              • 2. Visualization best practices
                Specialized Applications of Data Science13%- Other AI Applications
                • 1. Graph analysis and signal processing
                  • 2. Reinforcement learning, anomaly detection
                    - Natural Language Processing (NLP)
                    • 1. Tokenization, embeddings, TF-IDF
                      • 2. Topic modeling and applications
                        - Optimization and Advanced Methods
                        • 1. Constrained and unconstrained optimization
                          - Computer Vision
                          • 1. OCR, object detection, tracking
                            Mathematics and Statistics17%- Linear Algebra and Calculus
                            • 1. Derivatives, gradients, optimization basics
                              • 2. Matrix operations, eigenvalues, rank
                                - Statistical Methods
                                • 1. Hypothesis testing and regression metrics
                                  • 2. t-tests, chi-square tests, ANOVA
                                    • 3. ROC/AUC, AIC/BIC, confusion matrix
                                      - Probability and Modeling
                                      • 1. Distributions, skewness, kurtosis
                                        • 2. PDF, PMF, CDF, missing data handling
                                          - Time Series and Causal Models
                                          • 1. Forecasting and temporal modeling concepts
                                            Machine Learning24%- Unsupervised Learning
                                            • 1. Clustering and dimensionality reduction
                                              - Core ML Concepts
                                              • 1. Bias-variance tradeoff
                                                • 2. Cross-validation and regularization
                                                  - Supervised Learning
                                                  • 1. KNN and Naive Bayes
                                                    • 2. Linear and logistic regression
                                                      - Tree-Based Models
                                                      • 1. Decision trees, random forests, boosting
                                                        - Deep Learning
                                                        • 1. Neural networks and backpropagation
                                                          • 2. Dropout and batch normalization
                                                            Operations and Processes22%- Data Science Lifecycle
                                                            • 1. Workflow, version control, testing
                                                              - MLOps and Deployment
                                                              • 1. Model monitoring and deployment environments
                                                                • 2. CI/CD pipelines
                                                                  - Business Context
                                                                  • 1. KPIs and requirements gathering
                                                                    - Data Engineering Concepts
                                                                    • 1. Data ingestion, pipelines, streaming
                                                                      • 2. Data wrangling and cleaning

                                                                        >> DY0-001 Free Dumps <<

                                                                        Free PDF 2026 CompTIA DY0-001: CompTIA DataAI Certification Exam Newest Free Dumps

                                                                        Quality of DY0-001 practice materials you purchased is of prior importance for consumers. Our DY0-001 practice materials make it easier to prepare exam with a variety of high quality functions. Their quality function is observably clear once you download them. We have three kinds of DY0-001 practice materials moderately priced for your reference. All these three types of DY0-001 practice materials win great support around the world and all popular according to their availability of goods, prices and other term you can think of.

                                                                        CompTIA DataAI Certification Exam Sample Questions (Q18-Q23):

                                                                        NEW QUESTION # 18
                                                                        Which of the following is a key difference between KNN and k-means machine-learning techniques?

                                                                        Answer: D

                                                                        Explanation:
                                                                        # K-Nearest Neighbors (KNN) is a supervised machine learning algorithm used primarily for classification and regression. It labels a new instance by majority vote (or averaging, in regression) of its k-nearest labeled neighbors.
                                                                        # k-Means is an unsupervised learning algorithm used for clustering. It partitions unlabeled data into k groups based on feature similarity, using centroids.
                                                                        Thus, the key difference is in their purpose:
                                                                        * KNN # Classification (Supervised)
                                                                        * K-Means # Clustering (Unsupervised)
                                                                        Why the other options are incorrect:
                                                                        * A: Both can technically operate on continuous or categorical data (with preprocessing).
                                                                        * B: This is not a meaningful or standardized distinction.
                                                                        * C: This reverses the actual roles. k-means finds centroids; KNN finds nearest neighbors.
                                                                        Official References:
                                                                        * CompTIA DataX (DY0-001) Official Study Guide - Section 4.1 (Classification vs. Clustering):"KNN is a supervised learning algorithm for classification tasks. K-means is an unsupervised clustering technique that groups data by proximity to centroids."
                                                                        * Data Science Handbook, Chapter 5:"One key distinction: KNN uses labeled data to classify or regress; k-means uses unlabeled data to identify groupings."
                                                                        -


                                                                        NEW QUESTION # 19
                                                                        Which of the following types of machine learning is a GPU most commonly used for?

                                                                        Answer: C

                                                                        Explanation:
                                                                        # GPUs (Graphics Processing Units) are optimized for parallel computations, which are essential for training deep neural networks. These models involve massive matrix operations across multiple layers, making GPUs significantly faster than CPUs in deep learning tasks.
                                                                        Why the other options are incorrect:
                                                                        * B: Clustering (e.g., k-means) can benefit from acceleration but doesn't usually require GPU-level computation.
                                                                        * C: NLP tasks may use GPUs if they involve deep learning (e.g., transformers), but the correct choice is the model type.
                                                                        * D: Tree-based models (e.g., decision trees, random forests) typically run efficiently on CPUs.
                                                                        Official References:
                                                                        * CompTIA DataX (DY0-001) Study Guide - Section 4.3:"Deep learning models, such as neural networks, are computationally intensive and commonly require GPUs for efficient training."
                                                                        -


                                                                        NEW QUESTION # 20
                                                                        A data scientist receives an update on a business case about a machine that has thousands of error codes. The data scientist creates the following summary statistics profile while reviewing the logs for each machine:
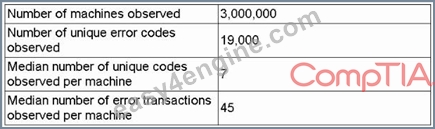
                                                                        | Number of machines observed | 3,000,000
                                                                        | Number of unique error codes observed | 19,000
                                                                        | Median number of unique codes per machine | 7
                                                                        | Median number of error transactions | 45
                                                                        Which of the following is the most likely concern with respect to data design for model ingestion?

                                                                        Answer: C

                                                                        Explanation:
                                                                        # With 19,000 unique error codes and only 7 codes per machine (on median), the data structure will likely consist of a very large number of binary features (e.g., one-hot encoded error codes), most of which will be 0 for any given machine. This leads to a sparse matrix-where the majority of elements are zero-which poses computational and modeling challenges.
                                                                        Why the other options are incorrect:
                                                                        * B: Granularity misalignment would mean mismatched levels (e.g., mixing daily and hourly data), which is not the issue here.
                                                                        * C: There are many features (error codes), not too few.
                                                                        * D: Multivariate outliers involve unusual combinations across features, not sparsity.
                                                                        Official References:
                                                                        * CompTIA DataX (DY0-001) Study Guide - Section 3.3:"High-cardinality categorical features can result in sparse matrices, especially when one-hot encoded for models."


                                                                        NEW QUESTION # 21
                                                                        Which of the following belong in a presentation to the senior management team and/or C-suite executives?
                                                                        (Choose two.)

                                                                        Answer: C,D

                                                                        Explanation:
                                                                        # Senior executives and the C-suite are primarily interested in decision-support insights rather than technical or academic depth. Thus, appropriate content includes:
                                                                        * C. Final recommendations: Executives need clear actions or decisions.
                                                                        * D. High-level results: Summarized performance, trends, or KPIs without technical jargon.
                                                                        Why the other options are incorrect:
                                                                        * A: Literature reviews are too detailed and academic.
                                                                        * B: Code is technical and not relevant to business strategy.
                                                                        * E: Statistical tests may overwhelm a non-technical audience.
                                                                        * F: Sharing security keys violates cybersecurity protocols.
                                                                        Official References:
                                                                        * CompTIA DataX (DY0-001) Official Study Guide - Section 5.5 (Communication & Visualization):
                                                                        "Executive presentations should include concise, actionable insights and high-level summaries to support strategic decision-making."
                                                                        * Harvard Business Review - Data Storytelling:"Executives value clear insights, visual summaries, and recommendations. Avoid technical deep dives unless specifically requested."
                                                                        -


                                                                        NEW QUESTION # 22
                                                                        A data scientist is building a model to predict customer credit scores based on information collected from reporting agencies. The model needs to automatically adjust its parameters to adapt to recent changes in the information collected. Which of the following is the best model to use?

                                                                        Answer: A

                                                                        Explanation:
                                                                        # XGBoost (Extreme Gradient Boosting) is a high-performance, scalable ensemble algorithm that builds decision trees in sequence and adjusts to errors iteratively. It also supports incremental training, making it adaptive to changing data patterns - ideal for dynamically updated credit information.
                                                                        Why the other options are incorrect:
                                                                        * A: Decision trees are static once trained and don't adapt unless retrained.
                                                                        * B: Random forest is an ensemble of trees but lacks the adaptive boosting component.
                                                                        * C: LDA is a linear classification technique - not suited for adapting to changing data distributions.
                                                                        Official References:
                                                                        * CompTIA DataX (DY0-001) Official Study Guide - Section 4.3:"XGBoost is highly efficient and supports iterative learning, making it well-suited for data environments that evolve over time."
                                                                        * Applied Machine Learning Guide, Chapter 8:"XGBoost adapts to changes by refining errors across iterations, providing robustness in dynamic systems."
                                                                        -


                                                                        NEW QUESTION # 23
                                                                        ......

                                                                        At the same time, DY0-001 study material also has a timekeeping function that allows you to be cautious and keep your own speed while you are practicing, so as to avoid the situation that you can't finish all the questions during the exam. With DY0-001 Learning Materials, you only need to spend half your money to get several times better service than others. And you can get the DY0-001 certification with little effort and money.

                                                                        Test DY0-001 Sample Online: https://www.easy4engine.com/DY0-001-test-engine.html

                                                                        BONUS!!! Download part of Easy4Engine DY0-001 dumps for free: https://drive.google.com/open?id=1zv2h9rK1RqJFPK4lS8CY-c71BwNloVBr