P.S. Free & New DP-750 dumps are available on Google Drive shared by EduDump: https://drive.google.com/open?id=11W4exuY6Bd4xkseyUmIIPCMX-AS085Nx
Generally speaking, a satisfactory practice material should include the following traits. High quality and accuracy rate with reliable services from beginning to end. As the most professional group to compile the content according to the newest information, our DP-750 practice materials contain them all, and in order to generate a concrete transaction between us we take pleasure in making you a detailed introduction of our DP-750 practice materials. We would like to take this opportunity and offer you a best DP-750 practice material as our strongest items as follows.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Prepare and process data | 30-35% | - Data quality and validation
|
>> Reliable DP-750 Braindumps <<
The DP-750 practice materials are a great beginning to prepare your exam. Actually, just think of our DP-750 practice materials as the best way to pass the exam is myopic. They can not only achieve this, but ingeniously help you remember more content at the same time. It is estimated conservatively that the passing rate of the exam is over 98 percent with our DP-750 Study Materials as well as considerate services. We not only provide all candidates with high pass rate study materials, but also provide them with good service.
NEW QUESTION # 26
What improves join performance for small lookup tables?
Answer: B
NEW QUESTION # 27
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
- Ensure that amount is always greater than 0.
- Prevent an update to Table1 from being committed when data that
violates rule1 is detected.
Which statement should you execute?
Answer: A
Explanation:
To ensure the data validation rule forces the pipeline update to abort and roll back transactions when data violates the condition, you must use a "fail" expectation operator. In Databricks Lakeflow Spark Declarative Pipelines (SDP), the command/syntax depends on whether your pipeline is written in Python or SQL.
Python Implementation
If your pipeline uses Python, apply the @dp.expect_or_fail decorator above your table definition (note: dp is the standard alias for the databricks.pipelines module in Lakeflow SDP):
dp.expect_or_fail("amount_greater_than_zero", "amount > 0")
Reference:
https://docs.databricks.com/aws/en/ldp/expectations
NEW QUESTION # 28
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group1.
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
- Can create tables in schema1
- Can modify and query tables
- Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.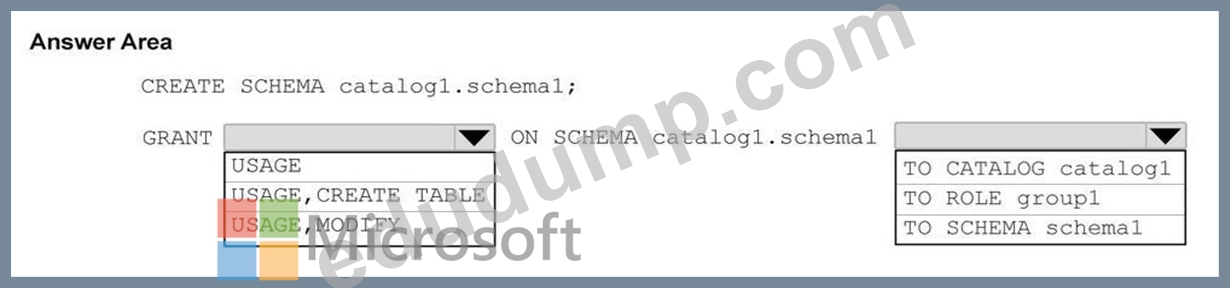
Answer:
Explanation: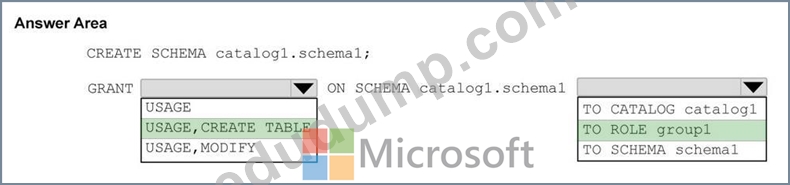
NEW QUESTION # 29
What improves join performance for small lookup tables?
Answer: B
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
- New data must be available in near-real-time (NRT).
- The data must be stored in managed Delta tables.
- The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: A
Explanation:
You should use Auto Loader with Delta Live Tables (DLT) or a streaming readStream using the cloudFiles format to load data into Unity Catalog managed tables.
To achieve the absolute lowest maintenance and custom code, Delta Live Tables with Auto Loader is the recommended choice.
Configure Cloud FilesFormat option: Set the source format to cloudFiles in your Spark stream.File detection: Auto Loader automatically tracks new files arriving in Azure Data Lake Storage (ADLS) Gen2.Schema evolution: It infers and adapts to schema changes without code updates.
Reference:
https://docs.databricks.com/aws/en/ingestion/cloud-object-storage/auto-loader/unity-catalog
NEW QUESTION # 31
......
In our software version of DP-750 exam questions the unique point is that you can take part in the DP-750 practice test before the real DP-750 exam. You never know what you can till you try. so that they can enrich their knowledge before the real DP-750 exam. However, confidence in yourself is the first step on the road to success. Our mock exam provided by us can help every candidate to get familiar with the Real DP-750 Exam, which is meaningful for you to take away the pressure and to build confidence in the approach.
Valid Dumps DP-750 Files: https://www.edudump.com/exams/Microsoft/DP-750/
2026 Latest EduDump DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=11W4exuY6Bd4xkseyUmIIPCMX-AS085Nx