2026年MogiExamの最新SPS-C01 PDFダンプおよびSPS-C01試験エンジンの無料共有:https://drive.google.com/open?id=1rx8-4ZC50ZPDJ0rlJVOKROZcwa29w7IG
SPS-C01試験の練習問題の核となる競争力は、ユーザーが見ることができるように、私たちには強力な専門家チームがあり、SPS-C01学習資料はリアルタイムで更新されています。ユーザーフィードバックの推奨事項により、SPS-C01ラーニングガイドには現在小さな問題があるという結論に達しました。残りの会社の開発計画では、サービスに対する認識を強化し、ユーザーがより満足できるようにします。 SPS-C01の学習教材は、短期間の高額販売ではなく、お客様と長期にわたって維持したいと考えています。
| Section | Objectives |
|---|---|
| Data Engineering with Snowpark | - Pipeline development
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Testing, Debugging, and Deployment | - Production readiness
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
Snowflakeは、短時間でSPS-C01認定を取得するために最善を尽くす必要があります。 認定資格を取得することが決まっている場合、SPS-C01質問トレントは喜んであなたに手を差し伸べます。 弊社のSPS-C01学習教材は、認定を取得するための最適な学習ツールになるためです。 ここで、SPS-C01試験問題を詳細に紹介します。紹介を注意深くお読みください。多くのメリットを得ることができます。 SPS-C01試験の資料に興味がある場合は、今すぐ購入できます。
質問 # 276
You are developing a Snowpark Python application that reads data from an external stage (AWS S3) and performs several transformations before loading it into a Snowflake table. During testing, you encounter the following error: net.snowflake.client.jdbc.SnowflakeSQLException: SQL compilation error: User does not have OWNERSHIP privilege on integration object 'YOUR INTEGRATION NAME". You have confirmed that the user has the 'USAGE privilege on the integration. Besides granting ownership, which of the following actions could resolve this issue in the MOST secure and efficient way?
正解:A
解説:
Option B is the MOST secure and efficient. The error indicates that the user lacks necessary privileges to utilize the integration for creating objects (in this case, likely an internal stage used during the transformation process). Granting a custom role with both 'USAGE on the integration and 'CREATE TABLE on the database adheres to the principle of least privilege. Option A grants broad privileges to the user, which is less secure. Option C involves complex integration setup and might not be necessary for a simple data loading scenario. Option D is related to reading data from the external stage, not using the integration for internal operations. Option E bypasses the error without addressing the underlying permission issue.
質問 # 277
You are working with Snowpark and a DataFrame named 'orders df that contains order data, including a column named 'items' which is a VARIANT type and holds an array of JSON objects, where each object represents an item in the order. You need to explode this array into separate rows, extracting the 'item_id' and 'quantity' for each item. Which of the following Snowpark snippets correctly performs this transformation AND handles potential NULL or empty arrays in the 'items' column?





正解:B
解説:
Option E is the most robust. It explicitly handles NULL or empty arrays in the 'items' column by replacing them with an empty array before exploding. This prevents errors during the explode operation. The other options will fail if the array is NULL because you cannot explode a NULL array. Additionally the items column need to be dropped after explode, so it won't be there in the last query. Column 'col' created by expload function must be used to extract the 'item_id' and 'quantity' values.
質問 # 278
You are developing a Snowpark application to load data into a Snowflake table named 'SALES DATA. The DataFrame 'sales_df contains new sales records. You need to insert these records into 'SALES DATA. Which of the following Snowpark DataFrame methods will efficiently perform this operation, considering potential data type mismatches between the DataFrame and the target table? Assume no explicit schema definition is necessary.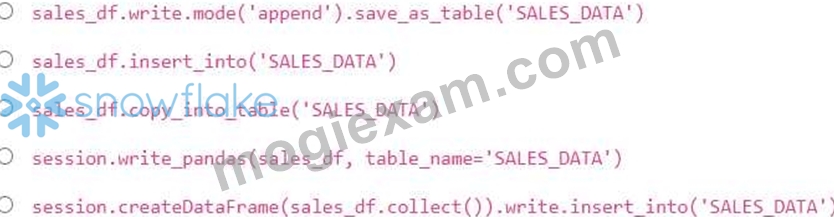
正解:C
解説:
The method directly inserts the DataFrame's data into the specified Snowflake table. Snowpark implicitly handles data type conversions where possible. is generally for creating new tables. is for loading data from files in stages, and 'write_pandas' method requires pandas DataFrame and session object. Using is inefficient as it collects all the data into the driver and then inserts and can cause memory issues.
質問 # 279
You are developing a Snowpark application that performs several complex transformations on a large DataFrame representing customer purchase history. This DataFrame is used multiple times in the application. You need to optimize the application's performance by caching the DataFrame. Which of the following approaches is the MOST efficient and memory-conscious way to cache the DataFrame in Snowpark?
正解:E
解説:
' df.cache_result()' is the recommended approach for caching DataFrames in Snowpark. It is designed to efficiently materialize the results of a DataFrame and store them in Snowflake's internal cache. This avoids recomputation in subsequent operations. brings the entire DataFrame into the client's memory, which is inefficient for large datasets. is not directly available in Snowpark like Spark. Creating a temporary table involves unnecessary I/O operations. Converting to Pandas and back introduces overhead and defeats the purpose of using Snowpark's optimized execution.
質問 # 280
You are developing a Snowpark application that requires calling a stored procedure. Which of the following approaches is the MOST secure and efficient way to call a stored procedure from your Snowpark Python code, assuming the stored procedure returns a single value?





正解:D
解説:
The 'session.call()' method (B) is the most direct and efficient way to call a stored procedure and retrieve its single return value from Snowpark Python. It handles the execution and data retrieval efficiently. Using 'session.sql()' (A and C) is less efficient as it requires parsing SQL and manual extraction of the result. 'session.sproc()' (D) is generally used to register Python functions as stored procedures and not for calling existing ones. is not valid, 'session.call()' is the right way to call procedure
質問 # 281
......
良い仕事を見つけることを選択した場合、できる限りSPS-C01認定を取得することが重要です。効率化を促すすばらしい製品があります。したがって、テストの準備をするためのすべての効果的かつ中心的なプラクティスがあります。専門的な能力を備えているため、SPS-C01試験問題を編集するために必要なテストポイントに合わせることができます。あなたの難しさを解決するために、試験の中心を指し示します。したがって、高品質の資料を使用すると、試験に効果的に合格し、安心して目標を達成できます。
SPS-C01復習時間: https://www.mogiexam.com/SPS-C01-exam.html
P.S. MogiExamがGoogle Driveで共有している無料かつ新しいSPS-C01ダンプ:https://drive.google.com/open?id=1rx8-4ZC50ZPDJ0rlJVOKROZcwa29w7IG