BTW, DOWNLOAD part of PassTorrent NCP-BC-7.5 dumps from Cloud Storage: https://drive.google.com/open?id=1gKnpr6Ru5dsZC5lCrhzvCoS0H7th7NQx
For starters and professionals Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 play a significant role to verify skills, experience, and knowledge in a specific technology. Enrollment in the Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 NCP-BC-7.5 is open to everyone. Upon completion of Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 NCP-BC-7.5 Exam Questions' particular criteria. Participants in the NCP-BC-7.5 Questions come from all over the world and receive the credentials for the Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 NCP-BC-7.5 Questions. They can quickly advance their careers in the fiercely competitive market and benefit from certification after earning the NCP-BC-7.5 Questions badge. However, passing the Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 NCP-BC-7.5 is the primary concern.
| Section | Weight | Objectives |
|---|---|---|
| Interpret and Configure BCDR Requirements | 30% | - Configure snapshot policies and retention - Create and configure recovery plans - Design secure BCDR environments: segmentation, RBAC, approval policies - Configure network and storage for BCDR - Select replication types: Async, NearSync, Synchronous, Metro - Translate business requirements into RPO/RTO objectives - Determine prerequisites for BCDR configuration |
| Test BCDR Solutions | 25% | - Perform disaster recovery validation procedures - Validate recovery plan execution and outcomes - Execute planned, unplanned, and test failovers - Verify site connectivity and replication throughput |
| Troubleshoot BCDR Failures | 20% | - Fix third-party backup integration problems - Diagnose network-related replication failures - Resolve storage and snapshot errors - Troubleshoot replication and protection policy issues - Resolve misconfigurations in DR environments |
| Perform BCDR Operational Tasks | 25% | - Execute failover and failback workflows - Self-service restore operations - Migrate legacy protection domains to modern policies - Post-failover cleanup and re-protection - Snapshot-based VM and volume recovery |
>> Reliable NCP-BC-7.5 Exam Labs <<
We can provide absolutely high quality guarantee for our NCP-BC-7.5 practice materials, for all of our Nutanix NCP-BC-7.5 learning materials are finalized after being approved by industry experts. Without doubt, you will get what you expect to achieve, no matter your satisfied scores or according NCP-BC-7.5certification file. As long as you choose our Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 exam questions, you will get the most awarded.
NEW QUESTION # 60
Which statement describes the most efficient and least disruptive method to achieve a file-level recovery without rolling back the entire VM?
Answer: D
Explanation:
Nutanix offers several data recovery methods, but the objective of " least disruptive " and " most efficient " is specifically addressed by the Self-Service Restore (SSR) feature. SSR is powered by Nutanix Guest Tools (NGT), which must be installed on the virtual machine. This functionality allows a user or an administrator to mount a disk from a historical recovery point directly to the active, running virtual machine as a temporary drive.
Once the snapshot is mounted, the guest operating system treats it as a standard local disk, allowing the user to browse the folder structure and perform a surgical restore of only the specific files that were deleted or corrupted. This process avoids the significant overhead and downtime associated with rolling back the entire VM (Option B) or cloning the VM to a new entity (Option C), which would consume additional compute and storage resources. Option A refers to Nutanix Files (NAS) functionality, which is separate from the block- level VM snapshot recovery discussed here. By using SSR/NGT, the production environment remains online and undisturbed, and the recovery process is delegated to the level of individual files, providing the highest level of granularity and efficiency in typical day-to-day data loss scenarios.
NEW QUESTION # 61
During routine monitoring, an administrator notices that replication from the primary Nutanix cluster to the recovery cluster has stopped. New recovery points are not being created, and the DR dashboard shows replication errors. Investigation reveals:
* The primary and recovery clusters are both online and healthy.
* Network segmentation was recently enabled to isolate replication traffic from other workloads.
* No recent changes were made to firewall rules, protection policies or RPO settings.
Which action should the administrator take first to investigate the replication failure?
Answer: C
Explanation:
In a Nutanix environment, replication health is heavily dependent on the available bandwidth and the consistency of the network path between the source and target sites. When replication fails following an infrastructure change like network segmentation, it often indicates that the system is unable to sustain the current data change rate over the new path. While verifying ports (Option C) is a logical infrastructure step, the provided answer emphasizes managing the replication load by increasing the Recovery Point Objective (RPO) interval. Increasing the RPO (e.g., from 1 hour to 4 hours) reduces the frequency of snapshot transfers, which can help determine if the replication engine (Cerebro) can successfully complete a transfer when given a longer window or reduced pressure. If increasing the RPO resolves the failure, the administrator can conclude that the network change introduced a bottleneck or limited throughput that is insufficient for the original " heavy " schedule. This diagnostic step helps differentiate between a total connectivity blackout and a performance-related failure caused by the newly implemented network segmentation. Once the baseline replication is restored at a higher RPO, the administrator can then proceed to optimize the network or firewall settings to support the more aggressive RPO requirements originally set by the business.
NEW QUESTION # 62
An administrator notices that VM replication from ClusterA to ClusterB fails consistently at the same point during the replication job. The following observations are noted by the administrator:
* The Prism dashboard shows the replication job failing during snapshot creation.
* ClusterB storage pool and container usage is under 80%, well below capacity.
* Network latency/Pings between ClusterA and ClusterB averages 3ms, with occasional spikes to 25ms.
* VM event logs indicate frequent I/O timeout errors during the replication window.
* Both clusters are running compatible AOS versions.
What is the most likely cause for the failing replications?
Answer: C
Explanation:
Troubleshooting replication failures requires analyzing the relationship between snapshot creation and data transfer. In this scenario, the failure occurs during the snapshot creation phase rather than during the transfer of data across the wire. While network spikes and I/O timeouts are noted (Option D), these are often symptoms rather than the root cause when the specific failure point is the snapshot itself .
If multiple replication jobs or protection policies are scheduled to run at the exact same time, the cluster may experience " snapshot contention " or metadata locks. When schedules overlap significantly, the overhead on the Controller VMs (CVMs) can lead to the observed I/O timeout errors in the guest OS as the system struggles to quiesce applications and freeze the filesystem multiple times in quick succession. This is particularly common in environments with high data change rates where the previous replication cycle has not finished before the next one begins. Since storage is sufficient (Option B) and the clusters are compatible (Option E), the most logical cause is schedule misconfiguration. To resolve this, the administrator should stagger the start times of protection policies or combine multiple VMs into a single, unified policy to ensure that the Nutanix snapshot engine can process the requests sequentially without causing the resource exhaustion that leads to job failure.
NEW QUESTION # 63
A sudden and unrecoverable hardware failure occurs at the primary site, making the Prism Element console for that cluster inaccessible. The secondary site is healthy and contains the latest replicated snapshots. Which action must the administrator take on the secondary cluster to restore the VMs?
Answer: A
Explanation:
When a primary Nutanix site suffers a catastrophic failure, the disaster recovery plan must be executed from the recovery (secondary) site . In a legacy Protection Domain-based environment, the secondary site is in a " passive " or " standby " mode, receiving snapshots but not actively running the workloads. The traditional method to failover is using the " Activate " command (Option A), which promotes the PD and registers the VMs. However, in certain specific failure scenarios or older software versions, the secondary cluster may require a service-level reset to recognize its new role as the active master for those specific workloads.
The Cerebro service is the core component responsible for managing Protection Domains and replication metadata. If the primary site is completely inaccessible and the secondary site ' s metadata state needs refreshing to initiate recovery, restarting the Cerebro service on the secondary cluster CVMs can force a re- evaluation of all local snapshots and protection domain states. This action triggers the recovery logic, allowing the administrator to then see and activate the recovery points. While " Activate " is the goal, the first technical step in a situation where the cluster management plane is unstable or the primary is gone is ensuring the data protection services are aware of the current state. This allows the VMs to be restored from the latest snapshots, fulfilling the Recovery Time Objective (RTO) despite the complete loss of the source infrastructure.
NEW QUESTION # 64
Refer to Exhibit: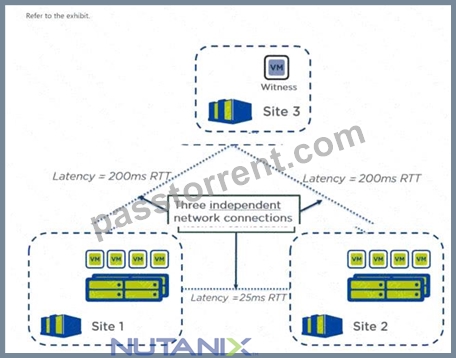
An administrator is configuring Metro Availability in their environment, as shown in the diagram. What issue in the configuration will prevent Metro from working correctly?
Answer: B
Explanation:
Nutanix Metro Availability and Synchronous Replication have very strict networking requirements to ensure that real-time data mirroring does not introduce unacceptable application latency. The industry-standard requirement for Nutanix synchronous operations is a maximum Round Trip Time (RTT) latency of 5ms between the two primary clusters (Site 1 and Site 2). According to the diagram provided in the question, the latency between Site 1 and Site 2 is 25ms RTT. This latency is significantly higher than the 5ms threshold and will prevent the Metro Availability configuration from functioning correctly. While the latency to the Witness VM (200ms RTT) is perfectly acceptable (Option D), and having a Witness at a third site (Option A) is a best practice, the " data path " between the storage clusters is the bottleneck here. If an administrator attempts to enable Metro with 25ms of latency, the guest VMs would experience severe performance degradation because every write would be delayed by the 25ms it takes to receive an acknowledgment from the remote site.
Therefore, the high latency between the data-serving sites is the primary configuration issue that must be resolved, typically by moving the clusters closer together or upgrading the inter-site fiber connection.
NEW QUESTION # 65
......
NCP-BC-7.5 study engine is very attentive to provide a demo for all customers who concerned about our products, whose purpose is to allow customers to understand our product content before purchase. Many students suspect that if NCP-BC-7.5 learning material is really so magical? Does it really take only 20-30 hours to pass such a difficult certification exam successfully? It is no exaggeration to say that you will be able to successfully pass the exam with our NCP-BC-7.5 Exam Questions.
Flexible NCP-BC-7.5 Testing Engine: https://www.passtorrent.com/NCP-BC-7.5-latest-torrent.html
P.S. Free 2026 Nutanix NCP-BC-7.5 dumps are available on Google Drive shared by PassTorrent: https://drive.google.com/open?id=1gKnpr6Ru5dsZC5lCrhzvCoS0H7th7NQx