BTW, DOWNLOAD part of PDFDumps NCM-MCI-6.10 dumps from Cloud Storage: https://drive.google.com/open?id=1Z7v6eoCVwOtpacWtBDC5LLRl11sFOFb5
The Nutanix NCM-MCI-6.10 certification exam always gives a tough time to their candidates. So you have to plan well and prepare yourself as per the recommended Nutanix NCM-MCI-6.10 exam study material. For the quick and complete NCM-MCI-6.10 exam preparation the PDFDumps Nutanix NCM-MCI-6.10 Practice Test questions are the ideal selection. With the PDFDumps Nutanix NCM-MCI-6.10 PDF Questions and practice test software, you will get everything that you need to learn, prepare and pass the difficult NCM-MCI-6.10 exam with good scores.
| Section | Weight | Objectives |
|---|---|---|
| Analyze and Optimize Storage Performance | 20% | - Evaluate and resolve competing workload requirements - Troubleshoot storage performance bottlenecks - Optimize storage configuration and settings - Understand storage internals and I/O patterns |
| Monitoring, Automation and Operational Efficiency | 5% | - Automation workflows and tools - Monitoring and alerting configuration - Operational process optimization |
| Business Continuity and Disaster Recovery | 15% | - Disaster recovery strategy implementation - Failover and failback operations - BCDR testing and validation - Replication and recovery configuration |
| Advanced Platform Configuration and Troubleshooting | 25% | - API and CLI-based operations - Prism Central and Prism Element configuration - Integration with third-party systems - Cluster management, expansion and maintenance - Security configuration and compliance |
| Network Performance and Security | 20% | - Implement and analyze Flow security policies - Tune overlay networking and traffic flow - Network troubleshooting and optimization - Optimize physical and virtual network configurations |
| Virtualization and VM Performance Optimization | 15% | - AHV administration and workload management - Performance metrics analysis and tuning - High availability and migration management - VM resource adjustment and optimization |
To pass the Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) (NCM-MCI-6.10) certification exam you need to prepare well with the help of top-notch NCM-MCI-6.10 exam questions which you can download from PDFDumps platform. On this platform, you will get valid, updated, and real PDFDumps NCM-MCI-6.10 Dumps for quick exam preparation.
NEW QUESTION # 12
TASK 1
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to
"SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named MonitorSQL02 and send the report as a PDF on a daily basis to perf_group@ACME.org. Reports should not be retained. If any new objects need to be created, use monitovm2 in the name.
Finally, correct the issue within "SQL02".
Notes:
* Do not power on the VMs.
* While you will be creating a session, you will need to examine the VM configurations to determine the issue.
* Do not delete the VM to resolve the issue, any other destructive change is acceptable.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to all three tasks, performed within the Nutanix Prism interface.
Task 1: Create Monitoring Session & Save Metrics
* From the Prism Central dashboard, navigate to Operations > Analysis.
* Click the + New Session button.
* Name the session Monitor SQL02.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart.
* Title: Storage IOPS
* Metric: Storage Controller IOPS
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Latency
* Metric: Storage Controller Latency
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Bandwidth
* Metric: Storage Controller Bandwidth
* Click Add.
* Click Save Session.
* With the "Monitor SQL02" session open, right-click anywhere on the page and click Select All.
* Right-click again and select Copy.
* Open Notepad, paste the content, and save the file to the desktop as Task 1.txt.
(The content pasted into Task 1.txt would be the session's chart configurations, showing metrics for SQL01 and SQL02.)
Task 2: Create and Schedule the Report
* While still in the "Monitor SQL02" analysis session, click the Save as Report button (it looks like a bookmark icon).
* Name the report MonitorSQL02 and click Save.
* Navigate to Operations > Reports.
* Find the MonitorSQL02 report in the list. Select its checkbox.
* Click the Actions dropdown and select Schedule.
* Configure the schedule with the following settings:
* Schedule Name: monitovm2_daily_report
* Recurrence: Daily
* Start Time: (Set to a time, e.g., 8:00 AM)
* Repeat every: 1 day(s)
* Retention Policy: Uncheck the "Retain a copy of the report" box. (This ensures reports are not retained).
* Email Report: Check this box.
* Format: PDF
* Recipients: perf_group@ACME.org
* Click Save.
Task 3: Identify and Correct the Performance Issue
This task is performed without powering on the VMs, indicating a configuration error.
Investigation
* Navigate to VMs > Table view.
* Click on the SQL01 (the good VM) and select the Configuration tab.
* Expand the Disks section. Observe that the primary disk is attached to a SCSI bus (e.g., scsi.0). This is the high-performance standard.
* Return to the VM list and click on SQL02 (the problem VM).
* Expand the Disks section.
Root Cause
You discover that the primary disk for SQL02 is attached to an IDE bus. The IDE bus has significant performance limitations and is not suitable for a database server, causing the poor storage performance.
Correction
* With the SQL02 VM selected, click the Update button.
* In the "Update VM" dialog, scroll down to the Disks section.
* Find the disk attached to the IDE bus. Click the Edit (pencil) icon for that disk.
* Change the Bus Type dropdown from IDE to SCSI.
* The Device Index will automatically populate (e.g., scsi.0).
* Click Save in the "Update Disk" dialog.
* (Note: A "VirtIO SCSI Controller" will be automatically added to the VM configuration if one was not already present.)
* Click Save in the "Update VM" dialog.
The VM SQL02 is now configured to use the high-performance VirtIO-SCSI controller, which will resolve the storage performance discrepancy once the VM is powered on.
NEW QUESTION # 13
The Database team is reporting performance degradation for a business-critical application on Saturdays.
The team is requesting monitoring of processor, memory and storage utilization for the cluster for the application: SQL01, SQL02.
The report should contain views for the following:
* At the cluster level, only for the Cluster 1: The maximum percentage of CPU used
* At the VM level, including any future VM with the prefix SQL: The maximum time taken, maximum percentage of time a VM waits to use the physical CPU, out of the total CPU The report should run on Sundays at 12:00 AM for the previous 7 days. The report should show when completed.
Create a report named SQL_Batch_Saturday that meets these requirements.
Generate an instance of the report named SQL_Batch_Saturday as a CSV and save the file.
Note: You must name the report SQL_Batch_Saturday to receive any credit. Any other name will not be accepted. SMTP is not configured.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and run the report, performed entirely within Prism Central.
1. Create the Analysis Session
First, we will build the charts and entities for the report using the Analysis tool.
* From the Prism Central main menu, navigate to Operations > Analysis.
* Click the + New Session button.
* Add the required entities:
* In the "Entities" search box, type Cluster 1 and select Cluster: Cluster 1.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart to add the Cluster CPU chart:
* Title: Cluster 1 Max CPU Usage
* Entity Type: Cluster
* Metric: Cluster CPU Usage %
* Aggregation: Select Maximum.
* Click Add.
* Click Add Charts > New Chart to add the VM CPU Ready Time chart:
* Title: VM Max CPU Ready Time
* Entity Type: VM
* Metric: CPU Ready Time %
* Aggregation: Select Maximum.
* Click Add.
2. Save and Configure the Report
Now, save the session as a report and configure it to dynamically include all VMs with the SQL prefix.
* Click the Save as Report icon (the bookmark icon in the upper right).
* Name the report SQL_Batch_Saturday and click Save.
* Navigate to Operations > Reports.
* Find the SQL_Batch_Saturday report you just created and click its name to open the report editor.
* In the Entities tile, click the Edit (pencil) icon.
* By default, it will list "Cluster 1", "SQL01", and "SQL02".
* Change the VM selection:
* Select the radio button for All VMs prefixed with.
* In the text box, enter SQL.
* Ensure "Cluster 1" is still listed under "Clusters".
* Click Save.
3. Schedule the Report
* While still in the report editor for SQL_Batch_Saturday, click the Schedule button.
* Configure the schedule:
* Recurrence: Weekly
* Repeat on: Sunday
* Start Time: 12:00 AM
* Time Range: Previous 7 Days
* Configure the notification (as SMTP is not available):
* Expand the Notification Settings section.
* Check the box for Notify when ready (this enables the bell icon notification).
* Ensure "Email Report" is not checked.
* Click Save.
4. Generate and Save the CSV Instance
Finally, run the report now and download the CSV as requested.
* Navigate back to the main Operations > Reports list.
* Select the checkbox next to SQL_Batch_Saturday.
* Click the Actions dropdown and select Run Now.
* In the dialog, confirm the time range (e.g., "Last 7 Days") and click Run.
* Click the Report Instances tab.
* Wait for the report instance "SQL_Batch_Saturday" to finish running (the status will change from
"Running" to Succeeded).
* Once it has succeeded, click the Download (arrow) icon for that instance.
* Select the CSV format.
* Save the file to the desktop.
NEW QUESTION # 14
Task 11
Running NCC on a cluster prior to an upgrade results in the following output FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%) Identify the CVM with the issue, remove the fil causing the storage bloat, and check the health again by running the individual disk usage health check only on the problematic CVM do not run NCC health check Note: Make sure only the individual health check is executed from the affected node
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To identify the CVM with the issue, remove the file causing the storage bloat, and check the health again, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and find the NCC health check output file from the list.
You can use the date and time information to locate the file. The file name should be something like ncc- output-YYYY-MM-DD-HH-MM-SS.log.
Open the file and look for the line that says FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%). Note down the IP address of the CVM that has this issue. It should be something like X.X.X.
X.
Log in to the CVM using SSH or console with the username and password provided.
Run the command du -sh /home/* to see the disk usage of each file and directory under /home. Identify the file that is taking up most of the space. It could be a log file, a backup file, or a temporary file. Make sure it is not a system file or a configuration file that is needed by the CVM.
Run the command rm -f /home/<filename> to remove the file causing the storage bloat. Replace <filename> with the actual name of the file.
Run the command ncc health_checks hardware_checks disk_checks disk_usage_check --cvm_list=X.X.X.
X to check the health again by running the individual disk usage health check only on the problematic CVM.
Replace X.X.X.X with the IP address of the CVM that you noted down earlier.
Verify that the output shows PASS: CVM System Partition /home usage at XX% (less than threshold, 90%).
This means that the issue has been resolved.
#access to CVM IP by Putty
allssh df -h #look for the path /dev/sdb3 and select the IP of the CVM
ssh CVM_IP
ls
cd software_downloads
ls
cd nos
ls -l -h
rm files_name
df -h
ncc health_checks hardware_checks disk_checks disk_usage_check
NEW QUESTION # 15
Task 14
An administrator has been asked to configure a storage for a distributed application which uses large data sets across multiple worker VMs.
The worker VMs must run on every node. Data resilience is provided at the application level and low cost per GB is a Key Requirement.
Configure the storage on the cluster to meet these requirements. Any new object created should include the phrase Distributed_App in the name.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure the storage on the cluster for the distributed application, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as Distributed_App_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for low cost per GB, you may prefer to use more HDDs than SSDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container, such as Distributed_App_Container, and select the storage pool that you just created, Distributed_App_Storage_Pool, as the source.
Under Advanced Settings, enable Erasure Coding and Compression to reduce the storage footprint of the data.
You can also disable Replication Factor since data resilience is provided at the application level. These settings will help you achieve low cost per GB for the container.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore, such as Distributed_App_Datastore, and select NFS as the datastore type.
Select the container that you just created, Distributed_App_Container, as the source.
Click Save to create the datastore.
The datastore will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on Distributed_App_Datastore. You should see all nodes listed under Hosts.
You can now create or migrate your worker VMs to this datastore and run them on any node in the cluster.
The datastore will provide low cost per GB and high performance for your distributed application.
NEW QUESTION # 16
Task 9
The application team has requested several mission-critical VMs to be configured for disaster recovery. The remote site (when added) will not be managed by Prism Central. As such, this solution should be built using the Web Console.
Disaster Recovery requirements per VM:
Mkt01
RPO: 2 hours
Retention: 5 snapshots
Fin01
RPO: 15 minutes
Retention: 7 days
Dev01
RPO: 1 day
Retention: 2 snapshots
Configure a DR solution that meets the stated requirements.
Any objects created in this item must start with the name of the VM being protected.
Note: the remote site will be added later
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure a DR solution that meets the stated requirements, you can follow these steps:
Log in to the Web Console of the source cluster where the VMs are running.
Click on Protection Domains on the left menu and click on Create Protection Domain.
Enter a name for the protection domain, such as PD_Mkt01, and a description if required. Click Next.
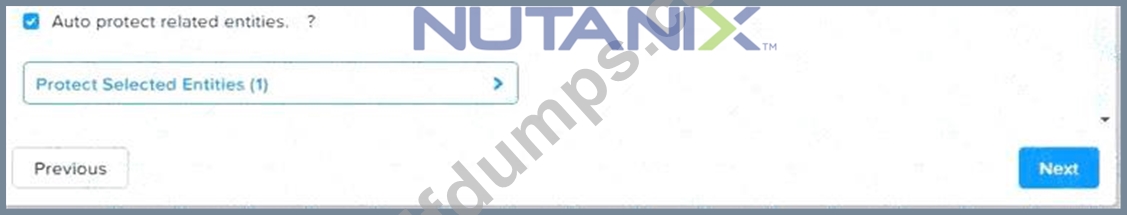
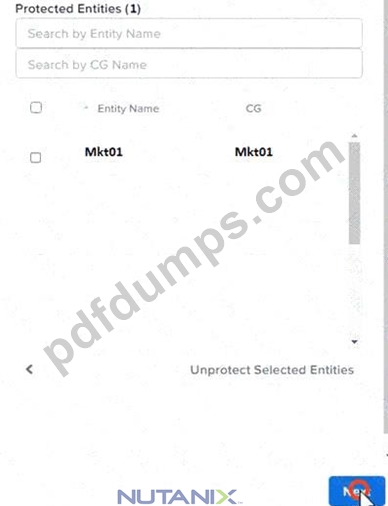
Select Mkt01 from the list of VMs and click Next.
Select Schedule Based from the drop-down menu and enter 2 hours as the interval. Click Next.
Select Remote Site from the drop-down menu and choose the remote site where you want to replicate the VM.
Click Next.
Enter 5 as the number of snapshots to retain on both local and remote sites. Click Next.
Review the protection domain details and click Finish.
Repeat the same steps for Fin01 and Dev01, using PD_Fin01 and PD_Dev01 as the protection domain names, and adjusting the interval and retention values according to the requirements.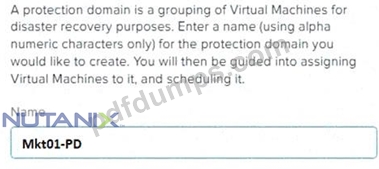
NEW QUESTION # 17
......
NCM-MCI-6.10 Soft test engine can stimulate the real exam environment, so that you can know the procedures of the exam, and your nerves can be relieved. This version can also build up your confidence for the exam. In addition, NCM-MCI-6.10 exam dumps contain most of knowledge points for the exam, and you can master them as well as improve your ability in the process learning. We also pass guarantee and money back guarantee if you fail to pass the exam, we will return your money if you fail to pass the exam. Free update for NCM-MCI-6.10 Training Materials is also available, and our system will send you the latest version to your email automatically.
NCM-MCI-6.10 Reliable Braindumps Files: https://www.pdfdumps.com/NCM-MCI-6.10-valid-exam.html
P.S. Free 2026 Nutanix NCM-MCI-6.10 dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=1Z7v6eoCVwOtpacWtBDC5LLRl11sFOFb5