2026年Fast2testの最新DP-600 PDFダンプおよびDP-600試験エンジンの無料共有:https://drive.google.com/open?id=172pxN2fw8KsWKiHmSqiwbnYkseJNege0
Fast2testのDP-600問題集はあなたの一発合格を保証できる資料です。問題集の的中率はとても高いですから、この問題集だけで試験に合格することができます。信じられなら利用してみてください。不合格になればFast2testは全額返金のことができますから、絶対損にならないです。利用したらDP-600問題集の品質がわかるようになるので、まず問題集の無料なサンプルを試しましょう。問題集のdemoが無料で提供されますから、Fast2testのサイトをクリックしてダウンロードしてください。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
DP-600認定を取得することは多くの人にとって簡単ではないことがわかっていますが、良いニュースをお伝えできることを嬉しく思います。当社の教材は、短時間でDP-600認定を取得するのに役立ちます。 DP-600練習問題を詳細にご紹介します。貴重な時間を割いてDP-600試験の質問をご覧ください。私たちはあなたを失望させないと信じてください。ウェブ上のDP-600トレーニングガイドのデモを無料でダウンロードして、優れた品質を知ることができます。
質問 # 128
You have a Fabric tenant that contains a semantic model. The model contains data about retail stores.
You need to write a DAX query that will be executed by using the XMLA endpoint The query must return a table of stores that have opened since December 1,2023.
How should you complete the DAX expression? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.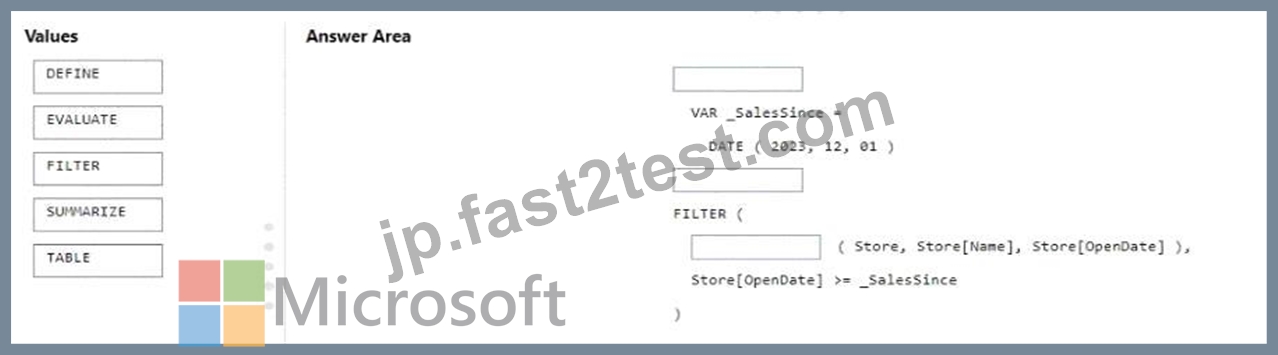
正解:
解説: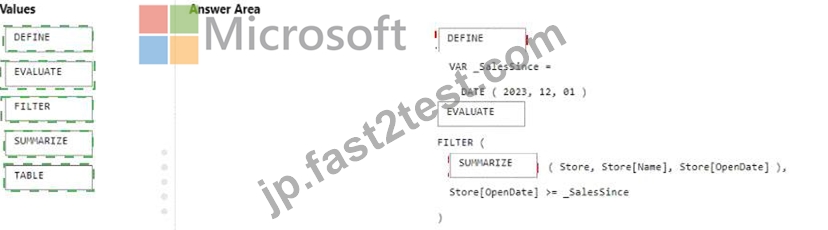
Explanation:
The correct order for the DAX expression would be:
* DEFINE VAR _SalesSince = DATE ( 2023, 12, 01 )
* EVALUATE
* FILTER (
* SUMMARIZE ( Store, Store[Name], Store[OpenDate] ),
* Store[OpenDate] >= _SalesSince )
In this DAX query, you're defining a variable _SalesSince to hold the date from which you want to filter the stores. EVALUATE starts the definition of the query. The FILTER function is used to return a table that filters another table or expression. SUMMARIZE creates a summary table for the stores, including the Store[Name] and Store[OpenDate] columns, and the filter expression Store[OpenDate] >= _SalesSince ensures only stores opened on or after December 1, 2023, are included in the results.
References =
* DAX FILTER Function
* DAX SUMMARIZE Function
質問 # 129
You are implementing two dimension tables named Customers and Products in a Fabric warehouse.
You need to use slowly changing dimension (SCO) to manage the versioning of data. The solution must meet the requirements shown in the following table.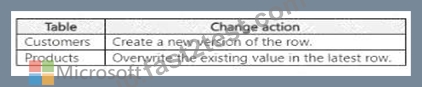
Which type of SCD should you use for each table? To answer, drag the appropriate SCD types to the correct tables. Each SCD type may be used once, more than once, or not at all. You may need to drag the split bar between panes o r scroll to view content.
NOTE: Each correct selection is worth one point.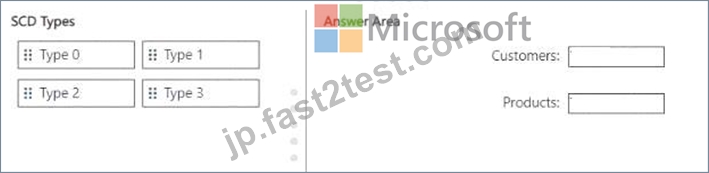
正解:
解説: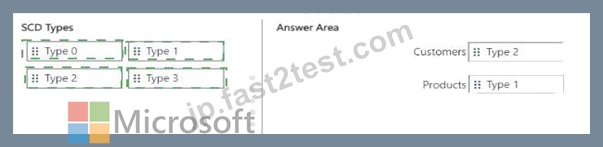
Explanation: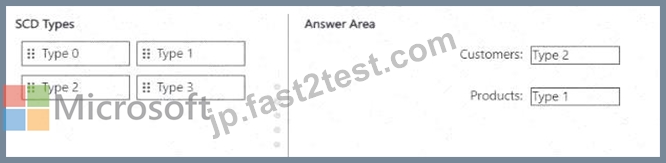
For the Customers table, where the requirement is to create a new version of the row, you would use:
* Type 2 SCD: This type allows for the creation of a new record each time a change occurs, preserving the history of changes over time.
For the Products table, where the requirement is to overwrite the existing value in the latest row, you would use:
* Type 1 SCD: This type updates the record directly, without preserving historical data.
質問 # 130
You need to implement the date dimension in the data store. The solution must meet the technical requirements.
What are two ways to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
正解:B、C
解説:
Both a dataflow (A) and a Stored procedure activity in a pipeline (B) are capable of creating and populating a date dimension table. A dataflow can perform the transformation needed to create the date dimension, and it aligns with the preference for using low-code tools for data ingestion when possible. A Stored procedure could be written to generate the necessary date dimension data and executed within a pipeline, which also adheres to the technical requirements for the PoC.
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.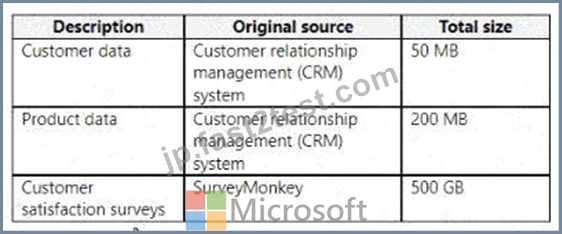
The Product data contains a single table and the following columns.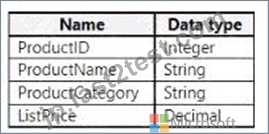
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers ' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
質問 # 131
Drag and Drop Question
You have a Fabric tenant that contains a data warehouse named DW1. DW1 contains a table named DimCustomer. DimCustomer contains the fields shown in the following table.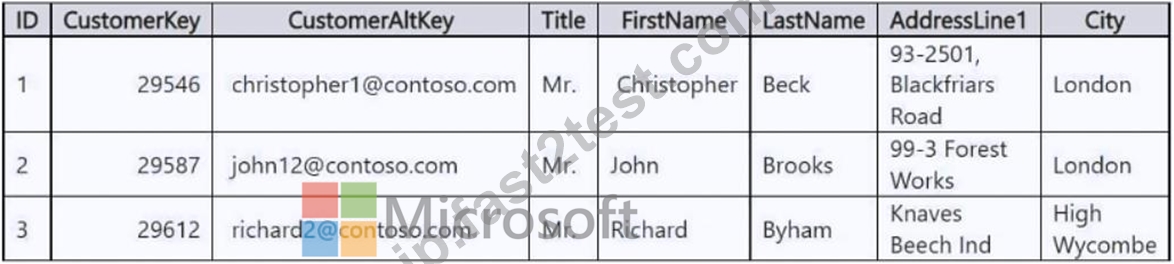
You need to identify duplicate email addresses in DimCustomer. The solution must return a maximum of 1,000 records.
Which four T-SQL statements should you run in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.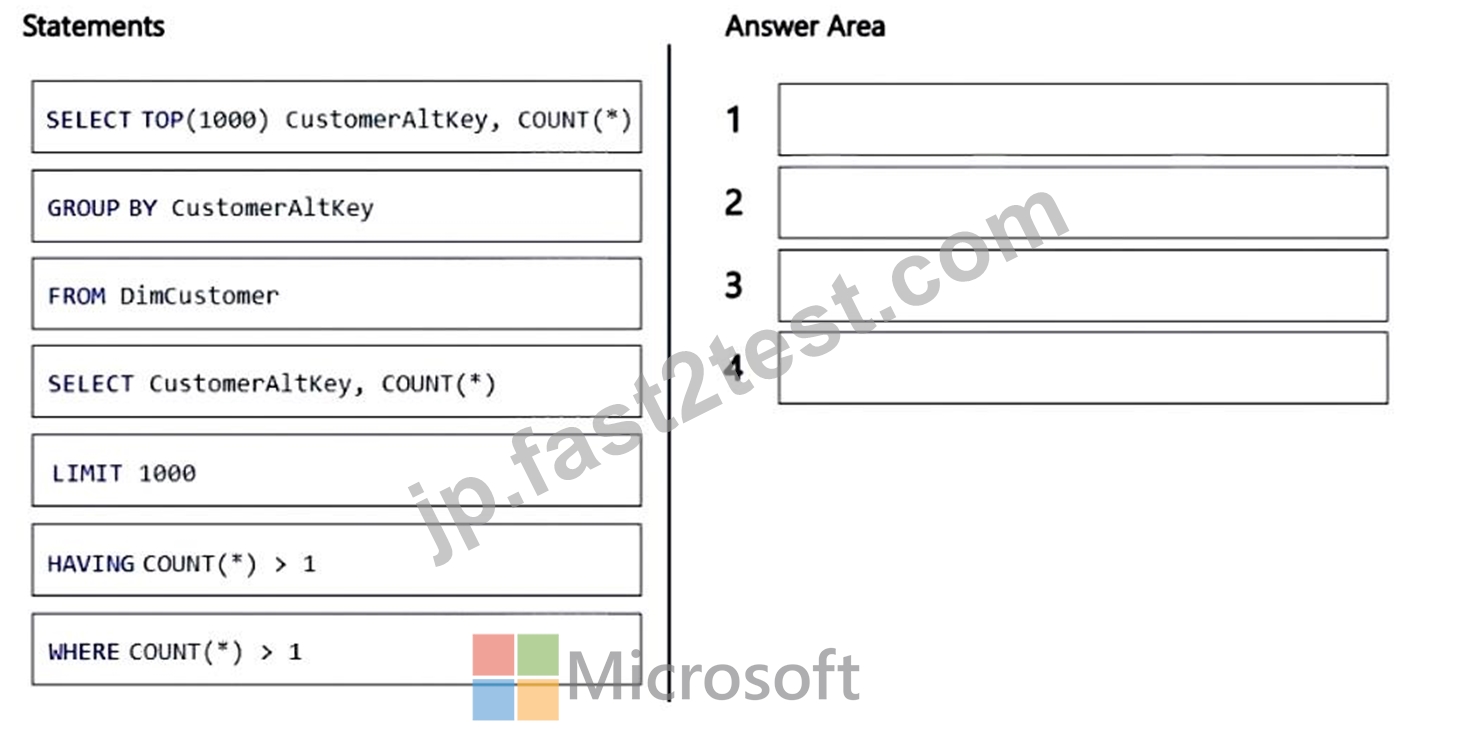
正解:
解説: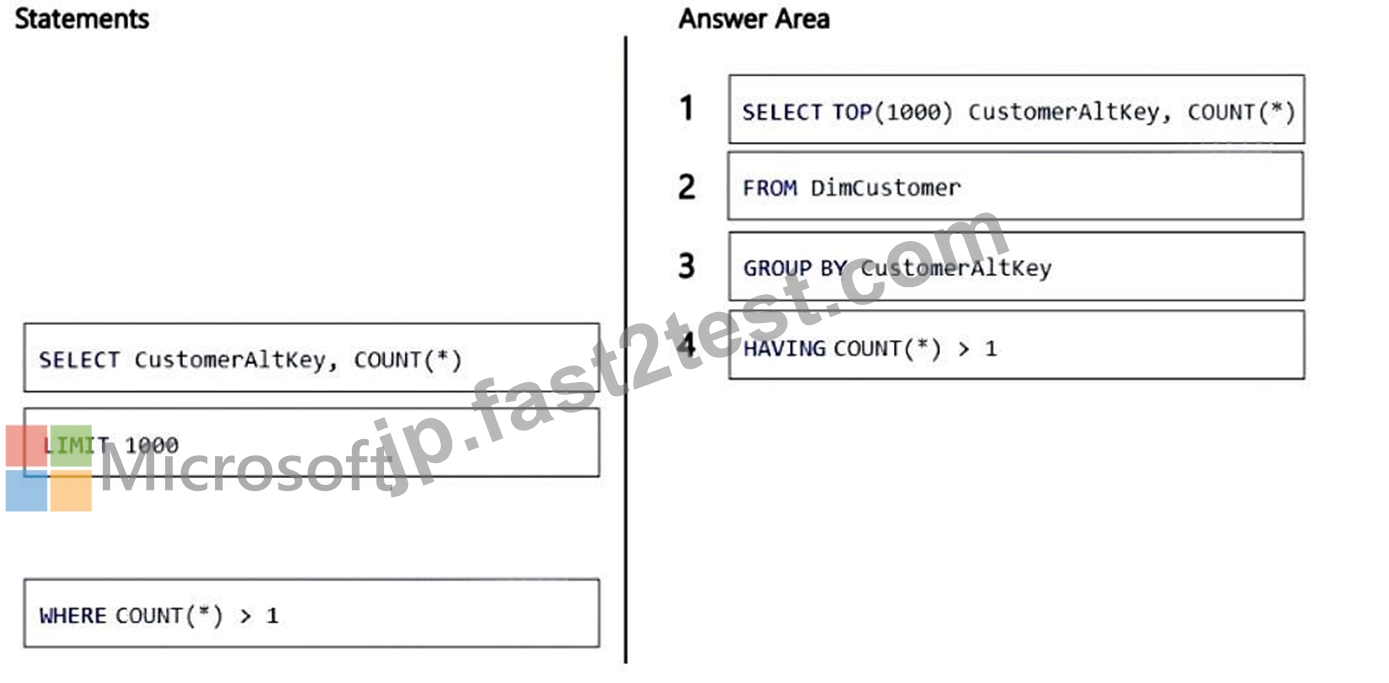
質問 # 132
You have a KQL database that contains a table named Readings.
You need to query Readings and return the results shown in the following table.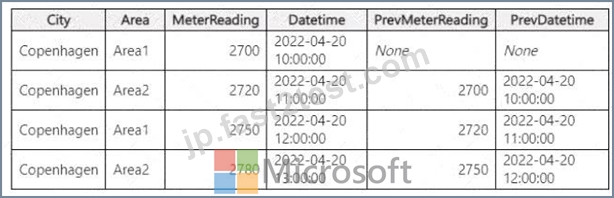
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.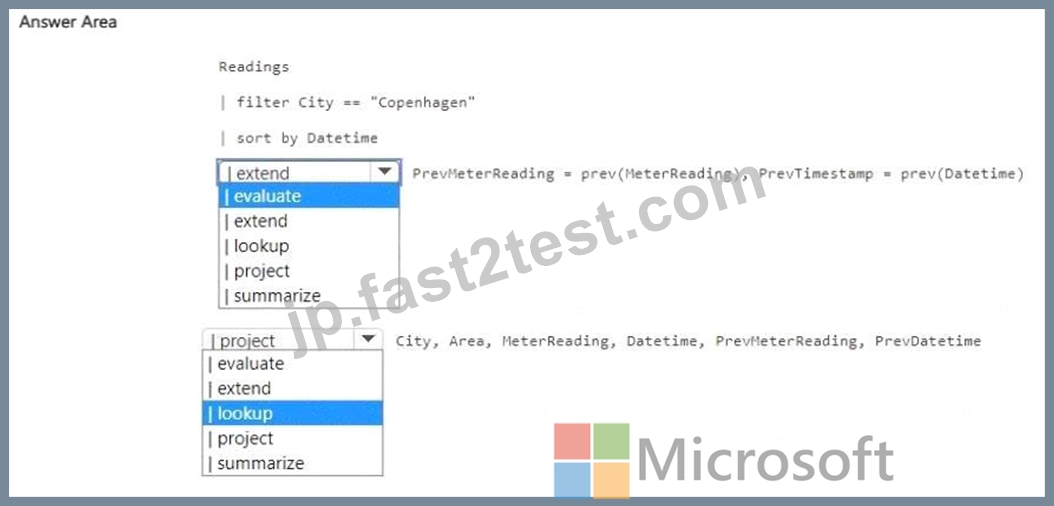
正解:
解説:
Explanation: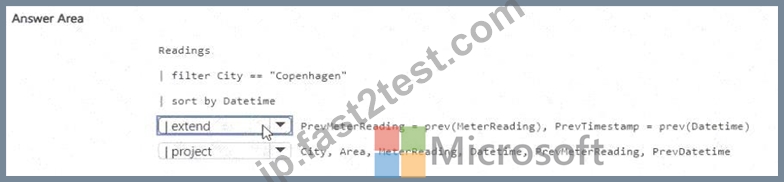
Comprehensive Detailed Explanation
We need to query a KQL database table named Readings to generate output that includes both the current reading and the previous reading values and datetime for each row.
Step 1: Understanding Requirements
The output table shows:
City, Area, MeterReading, Datetime
PrevMeterReading, PrevDatetime
The prev() function in KQL is used to access the value of a column from the previous row (based on order).
Step 2: Query Construction
We start with filtering:
Readings
| where City == " Copenhagen "
| sort by Datetime
To add columns that calculate the previous reading and previous datetime, we use extend:
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime) extend creates new columns.
prev() pulls the previous row's values.
Finally, we only want specific columns in the output. For this, we use project:
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Step 3: Completed Query Readings
| where City == " Copenhagen "
| sort by Datetime
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime)
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Why This is Correct extend adds calculated columns.
prev() gives access to the previous row.
project selects only the required columns.
This matches exactly the table shown in the question.
References
Kusto Query Language - extend operator
Kusto Query Language - project operator
prev() function in KQL
質問 # 133
......
トレントのDP-600ガイドは、これらすべての質問を解決してDP-600試験に合格するのに役立ちます。 弊社Fast2testのDP-600学習資料は、暦年の試験概要と業界動向に従って、長年にわたって多くの専門家によって簡素化され、まとめられています。 したがって、DP-600学習教材は理解しやすく、把握しやすいです。 人生には、自分の業界を変えたい人もたくさんいます。 彼らはしばしば、業界に参入するための足がかりとして専門的なDP-600資格試験を受けます。 あなたがこれらの人々の1人である場合、MicrosoftのDP-600試験エンジンが最良の選択となります。
DP-600最新問題: https://jp.fast2test.com/DP-600-premium-file.html
さらに、Fast2test DP-600ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=172pxN2fw8KsWKiHmSqiwbnYkseJNege0