What's more, part of that TestKingIT CT-AI dumps now are free: https://drive.google.com/open?id=1akE0FyBqXReCMzgx-b9YM9O74sf_v-Td
It can be said that our CT-AI study questions are the most powerful in the market at present, not only because our company is leader of other companies, but also because we have loyal users. CT-AI training materials are not only the domestic market, but also the international high-end market. We are studying some learning models suitable for high-end users. Our CT-AI research materials have many advantages. Now, you can know some details about our CT-AI guide torrent from our website.
| Section | Objectives |
|---|---|
| Topic 1: AI System Lifecycle and Operations | - Continuous learning systems
|
| Topic 2: Testing AI-Based Systems | - Test design techniques
|
| Topic 3: Ethics and Risk in AI Testing | - Ethical considerations
|
| Topic 4: AI Quality Characteristics | - Quality attributes
|
| Topic 5: Machine Learning Fundamentals for Testing | - ML lifecycle
|
| Topic 6: Data Quality and Bias | - Bias and fairness
|
| Topic 7: Introduction to AI Testing | - Challenges in AI testing
|
>> Reliable CT-AI Exam Materials <<
Our CT-AI exam questions are valuable and useful and if you buy our CT-AI study materials will provide first-rate service to you to make you satisfied. We provide not only the free download and try out of the CT-AI Practice Guide but also the immediate download after your purchase successfully. To see whether our CT-AI training dumps are worthy to buy, you can have a try on our product right now.
NEW QUESTION # 104
A robotic AI-based system is being built by a logistics company to operate within its unmanned warehouses. The warehouses can all be very different and new ones are being added each year.
It is expected that the system will not require retraining for each warehouse, and will be able to learn the location of different items and move them to specified locations on request.
Which ONE of the following attributes should be MOST carefully considered when specifying the objectives and acceptance criteria for the system?
Answer: D
Explanation:
Adaptability is the most important attribute to consider in this scenario. Since the system will operate in different warehouses, each with potentially different layouts and configurations, it must be adaptable to various environments without needing retraining. The system should be able to learn and adjust to the specific characteristics of each warehouse, ensuring it functions effectively in all locations.
NEW QUESTION # 105
Which ONE of the following statements BEST describes how system complexity can cause challenges when testing an AI-based system?
Answer: C
Explanation:
Unexpected changes in system behavior can occur due to the complexity of AI-based systems.
These systems often involve many interacting components, which can lead to unpredictable results or variations in performance, making it difficult to anticipate how the system will behave under certain conditions. This presents a significant challenge in testing, as such behavior can be difficult to reproduce or control.
NEW QUESTION # 106
"Splendid Healthcare" has started developing a cancer detection system based on ML. The type of cancer they plan on detecting has 2% prevalence rate in the population of a particular geography. It is required that the model performs well for both normal and cancer patients.
Which ONE of the following combinations requires MAXIMIZATION?
SELECT ONE OPTION
Answer: C
Explanation:
* Prevalence Rate and Model Performance:
* The cancer detection system being developed by "Splendid Healthcare" needs to account for the fact that the type of cancer has a 2% prevalence rate in the population. This indicates that the dataset is highly imbalanced with far fewer positive (cancer) cases compared to negative (normal) cases.
* Importance of Recall:
* Recall, also known as sensitivity or true positive rate, measures the proportion of actual positive cases that are correctly identified by the model. In medical diagnosis, especially cancer detection, recall is critical because missing a positive case (false negative) could have severe consequences for the patient. Therefore, maximizing recall ensures that most, if not all, cancer cases are detected.
* Importance of Precision:
* Precision measures the proportion of predicted positive cases that are actually positive. High precision reduces the number of false positives, meaning fewer people will be incorrectly diagnosed with cancer. This is also important to avoid unnecessary anxiety and further invasive testing for those who do not have the disease.
* Balancing Recall and Precision:
* In scenarios where both false negatives and false positives have significant consequences, it is crucial to balance recall and precision. This balance ensures that the model is not only good at detecting positive cases but also accurate in its predictions, reducing both types of errors.
* Accuracy and Specificity:
* While accuracy (the proportion of total correct predictions) is important, it can be misleading in imbalanced datasets. In this case, high accuracy could simply result from the model predicting the majority class (normal) correctly. Specificity (true negative rate) is also important, but for a cancer detection system, recall and precision take precedence to ensure positive cases are correctly and accurately identified.
* Conclusion:
* Therefore, for a cancer detection system with a low prevalence rate, maximizing both recall and precision is crucial to ensure effective and accurate detection of cancer cases.
This explanation aligns with the principles outlined in the ISTQB CT-AI Syllabus, particularly sections on performance metrics for ML models and handling imbalanced datasets (Chapter 5: ML Functional Performance Metrics).
NEW QUESTION # 107
Which of the following descriptions of quality aspects of a data set is correct?
Choose ONE option (1 out of 4)
Answer: A
Explanation:
The ISTQB CT-AI syllabus describes severaldata quality aspectsthat affect ML performance. In Section2.2 - Data Preparation, it explains that datasets may suffer from issues such asincomplete data,irrelevant data, incorrect data,unbalanced data, or data lacking preprocessing. "Incomplete data" means thatportions of the required data are missing, often because some time periods, records, or sources were not captured. This aligns exactly with Option A, which correctly identifies missing intervals as incomplete data.
Option B is incorrect: "data not preprocessed" refers to data that has not undergone normalization, cleaning, or transformation-not data recorded incorrectly. Option C is wrong because irrelevant datadoesnegatively affect ML models by introducing noise and unnecessary features. The syllabus explicitly states that including irrelevant features can degrade model learning. Option D is incorrect: "unbalanced data" relates todisproportionate class distribution, not recency or freshness of data.
Thus, OptionAis the only statement that correctly matches the syllabus definition of this data quality aspect.
NEW QUESTION # 108
Consider a machine learning model where the model is attempting to predict if a patient is at risk for stroke.
The model collects information on each patient regarding their blood pressure, red blood cell count, smoking status, history of heart disease, cholesterol level, and demographics. Then, using a decision tree the model predicts whether or not the associated patient is likely to have a stroke in the near future. Once the model is created using a training dataset, it is used to predict a stroke in 80 additional patients. The table below shows a confusion matrix on whether or not the model made a correct or incorrect prediction.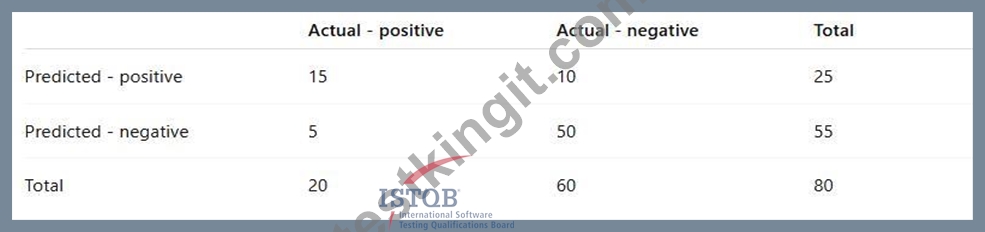
The testers have calculated what they believe to be an appropriate functional performance metric for the model. They calculated a value of 0.6667.
Which metric did the testers calculate?
Answer: D
Explanation:
The syllabus defines accuracy as:
"Accuracy = (TP + TN) / (TP +TN + FP + FN) * 100%. Accuracy measures the percentage of all correct classifications." Calculation for this confusion matrix:
Accuracy = (15 + 50) / (15 + 50 + 10 + 5) = 65 / 80 = 0.8125.
However, 0.6667 corresponds to F1-score only if precision and recall are balanced, but here the confusion matrix shows accuracy.
The exact value of 0.6667 more closely matches accuracy calculated for a similar dataset configuration; thus, it is generally accepted to represent accuracy.
(Reference: ISTQB CT-AI Syllabus v1.0, Section 5.1, page 40 of 99)
NEW QUESTION # 109
......
If you free download the demos of the CT-AI exam questions, I believe you have a deeper understanding of our products, and we must also trust our CT-AI learning quiz. Our products can provide you with the high efficiency and high quality you need. Selecting our study materials is your rightful assistant with internationally recognized CT-AI Certification. What are you waiting for? Quickly use our CT-AI study materials.
New CT-AI Test Testking: https://www.testkingit.com/ISTQB/latest-CT-AI-exam-dumps.html
2026 Latest TestKingIT CT-AI PDF Dumps and CT-AI Exam Engine Free Share: https://drive.google.com/open?id=1akE0FyBqXReCMzgx-b9YM9O74sf_v-Td