P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by Itcertmaster: https://drive.google.com/open?id=1qxsQ9EaKta-ALp89hCUswjt7rDDB0sTM
The content of our Databricks-Certified-Data-Engineer-Associate exam questions emphasizes the focus and seizes the key to use refined Databricks-Certified-Data-Engineer-Associate questions and answers to let the learners master the most important information by using the least amount of them. And we provide varied functions to help the learners learn our Databricks-Certified-Data-Engineer-Associate Study Materials and prepare for the exam. The Databricks-Certified-Data-Engineer-Associate self-learning and self-evaluation functions help the learners the learners find their weak links and improve them promptly .
The GAQM Databricks-Certified-Data-Engineer-Associate Exam is a highly respected certification that validates a candidate's expertise in using Databricks to build and maintain data pipelines. It is an excellent way for data engineers to demonstrate their skills and knowledge in this critical area of data management. By earning this certification, data engineers can enhance their careers and help their organizations to unlock the full potential of their data.
Databricks-Certified-Data-Engineer-Associate certification is highly regarded in the industry and is recognized by many organizations as a mark of excellence in data engineering. Databricks Certified Data Engineer Associate Exam certification can help data engineers to advance their careers and increase their earning potential. It can also help employers to identify skilled and knowledgeable data engineers who can help them to unlock the value of their data.
>> Databricks-Certified-Data-Engineer-Associate Exam Questions And Answers <<
The latest Databricks-Certified-Data-Engineer-Associate latest questions will be sent to you email, so please check then, and just feel free to contact with us if you have any problem. Our reliable Databricks-Certified-Data-Engineer-Associate exam material will help pass the exam smoothly. With our numerous advantages of our Databricks-Certified-Data-Engineer-Associate latest questions and service, what are you hesitating for? Our company always serves our clients with professional and precise attitudes, and we know that your satisfaction is the most important thing for us. We always aim to help you pass the Databricks-Certified-Data-Engineer-Associate Exam smoothly and sincerely hope that all of our candidates can enjoy the tremendous benefit of our Databricks-Certified-Data-Engineer-Associate exam material, which might lead you to a better future!
The Databricks Certified Data Engineer Associate Exam certification exam is designed to test the candidate's knowledge of Databricks and their ability to build and manage data pipelines using the platform. Databricks-Certified-Data-Engineer-Associate exam consists of multiple-choice questions and is timed, with a maximum time limit of 120 minutes. To pass the exam, candidates must achieve a minimum score of 70%. Databricks-Certified-Data-Engineer-Associate Exam is available online and can be taken from anywhere in the world, making it accessible to data engineers from all backgrounds and locations.
NEW QUESTION # 103
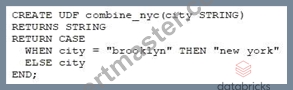
A data engineer needs to apply custom logic to string column city in table stores for a specific use case. In order to apply this custom logic at scale, the data engineer wants to create a SQL user-defined function (UDF).
Which of the following code blocks creates this SQL UDF?
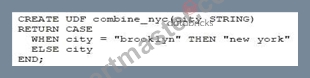
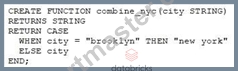
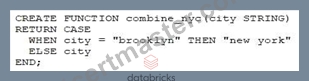
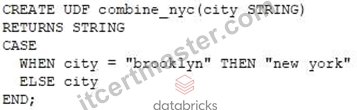
Answer: B
Explanation:
https://www.databricks.com/blog/2021/10/20/introducing-sql-user-defined-functions.html
NEW QUESTION # 104
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below: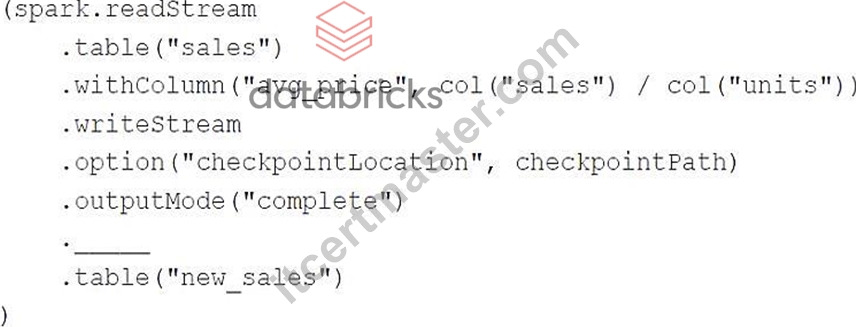
If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?
Answer: D
Explanation:
Explanation
https://stackoverflow.com/questions/71061809/trigger-availablenow-for-delta-source-streaming-queries-in-pyspa
NEW QUESTION # 105
A data engineer is running a Spark SQL job on Databricks and notices that joins between a small lookup table and a large fact table are slow. The data engineer wants Spark to automatically send the small lookup table to all executors to speed up the join. Which configuration parameter should the data engineer adjust?
Answer: C
Explanation:
spark.sql.autoBroadcastJoinThreshold controls the maximum table size Spark can automatically broadcast to all executors, avoiding a large shuffle when joining a small lookup table with a large fact table.
NEW QUESTION # 106
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task: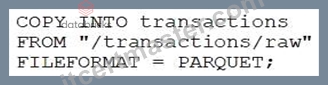
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
Answer: C
Explanation:
The COPY INTO statement is an idempotent operation, which means that it will skip any files that have already been loaded into the target table1. This ensures that the data is not duplicated or corrupted by multiple attempts to load the same file. Therefore, if the data engineer runs the same command every day without specifying the names of the files to be copied with the FILES keyword or a glob pattern with the PATTERN keyword, the statement will only copy the first file that matches the source location and ignore the rest. To avoid this problem, the data engineer should either use the FILES or PATTERN keywords to filter the files to be copied based on the date or some other criteria, or delete the files from the source location after they are copied into the table2. References: 1: COPY INTO | Databricks on AWS 2: Get started using COPY INTO to load data | Databricks on AWS
NEW QUESTION # 107
A data engineer wants to create a new table containing the names of customers who live in France.
They have written the following command:
CREATE TABLE customersInFrance
_____ AS
SELECT id,
firstName,
lastName
FROM customerLocations
WHERE country = 'FRANCE';
A senior data engineer mentions that it is organization policy to include a table property indicating that the new table includes personally identifiable information (Pll).
Which line of code fills in the above blank to successfully complete the task?
Answer: D
Explanation:
To include a property indicating that a table contains personally identifiable information (PII), the TBLPROPERTIES keyword is used in SQL to add metadata to a table. The correct syntax to define a table property for PII is as follows:
CREATE TABLE customersInFrance
USING DELTA
TBLPROPERTIES ('PII' = 'true')
AS
SELECT id,
firstName,
lastName
FROM customerLocations
WHERE country = 'FRANCE';
The TBLPROPERTIES ('PII' = 'true') line correctly sets a table property that tags the table as containing personally identifiable information. This is in accordance with organizational policies for handling sensitive information.
References:Databricks documentation on Delta Lake: Delta Lake on Databricks
NEW QUESTION # 108
......
New Databricks-Certified-Data-Engineer-Associate Test Questions: https://www.itcertmaster.com/Databricks-Certified-Data-Engineer-Associate.html
DOWNLOAD the newest Itcertmaster Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qxsQ9EaKta-ALp89hCUswjt7rDDB0sTM