BONUS!!! Download part of BraindumpQuiz DP-800 dumps for free: https://drive.google.com/open?id=1AXesGWTpZweZOhJehgOyIDTMB4cQUCri
The pass rate of the DP-800 exam braindumps is 98.75%, and pass guarantee and money back guarantee, if you indeed fail in the exam by using DP-800 exam dumps of us , we will refund your money or if you need to attend other exam, we will replace other 2 valid exam dumps for free. Besides, the DP-800 Exam Dumps contain both quality and certain quantity, it is good for you to practice and pass the exam successfully.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable DP-800 Exam Price <<
BraindumpQuiz is a website provide you with the best and valid DP-800 exam questions that elaborately compiled and highly efficiently, studying with our DP-800 study guide will cost you less time and energy, because we shouldn't waste our money on some unless things. The passing rate and the hit rate of our DP-800 Training Material are also very high, there are thousands of candidates choose to trust our website and they have passed the DP-800 exam. We provide with candidate so many guarantees that they can purchase our DP-800 study materials no worries.
NEW QUESTION # 86
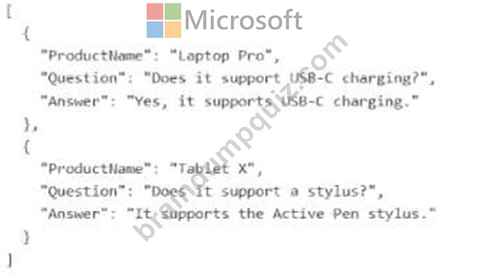
You have an Azure SQL table that contains the following data.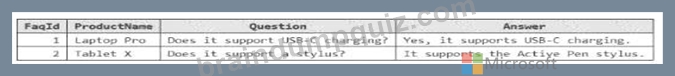
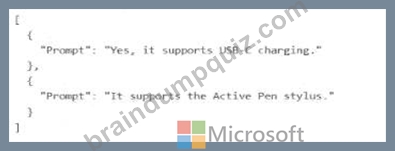
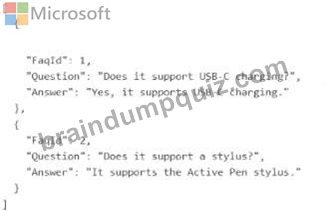
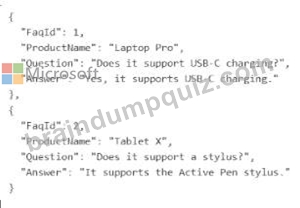
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
Answer: D
Explanation:
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
NEW QUESTION # 87
Drag and Drop Question
You have an Azure AI Search service and an index named hotels that includes a vector field named DescriptionVector.
You query hotels by using the Search Documents REST API.
You need to implement a hybrid search query that uses DescriptionVector and includes captions.
How should you complete the REST request body? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.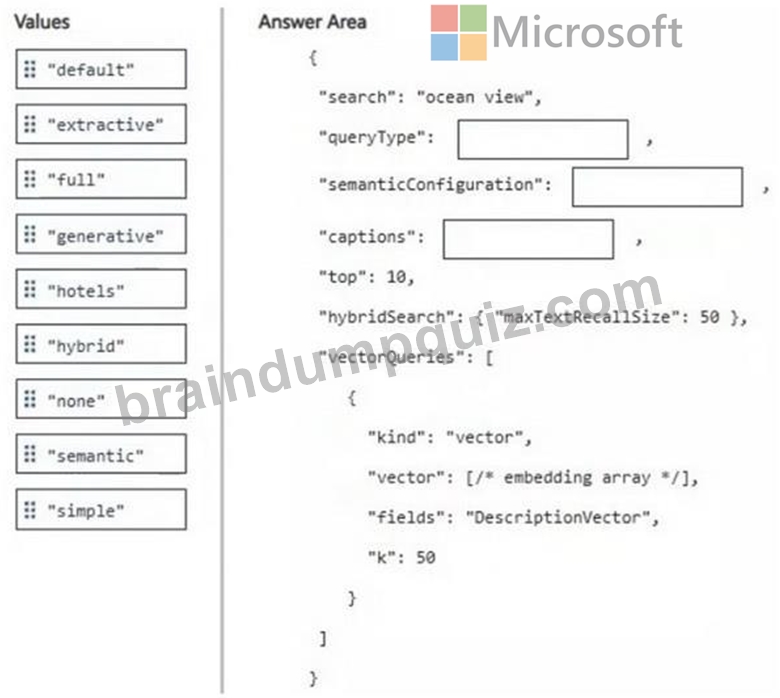
Answer:
Explanation: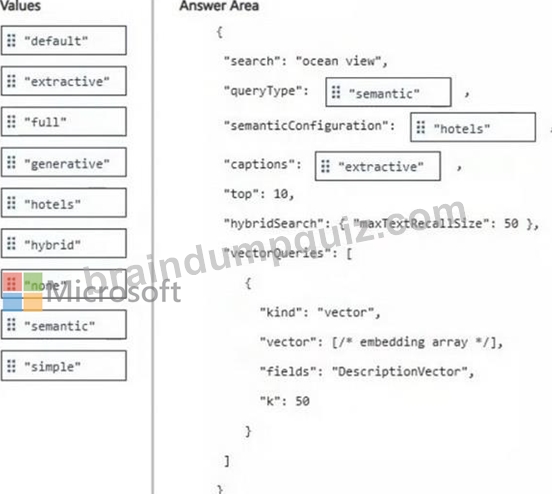
NEW QUESTION # 88
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to disable the GitHub Copilot repository-level instructions for yourself without affecting other users.
What should you do?
Answer: B
Explanation:
To disable GitHub Copilot repository-level instructions for yourself without affecting others, you can modify your User Settings in Visual Studio Code. This allows you to override or ignore specific repository-wide configurations like copilot-instructions.md at a personal level.
How to Disable Repository-Level Instructions
1. Open User Settings: Press Ctrl+, (Windows/Linux) or Cmd+, (macOS) to open the VS Code Settings editor.
2. Search for Copilot Chat: In the search bar, type github.copilot.chat.customInstructions.
3. Configure Custom Instructions:
Find the setting for Github > Copilot > Chat: Custom Instructions.
Ensure the User tab is selected at the top to apply changes only to your account and not the shared workspace.
4. Toggle via Chat UI:
Open the Chat view (Ctrl+Alt+I or Cmd+Shift+L).
Click the Configure Chat (gear icon) at the bottom of the chat panel.
Select the Instructions tab and uncheck or remove any active repository-level files to disable their influence on your session.
Reference:
https://code.visualstudio.com/docs/copilot/customization/custom-instructions
NEW QUESTION # 89
You have an Azure SQL database that contains a table named Table1. Table1 contains 25,000,000 rows of data and a datetime2 column named DateKey. The data in Table1 spans the years 2020 through 2021.
You need to partition the data in Table1 by year. The solution must minimize how long it takes to rebuild or reindex the table.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.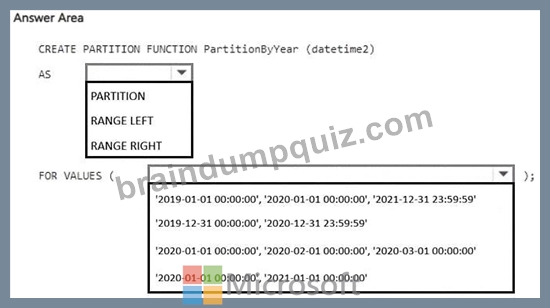
Answer:
Explanation: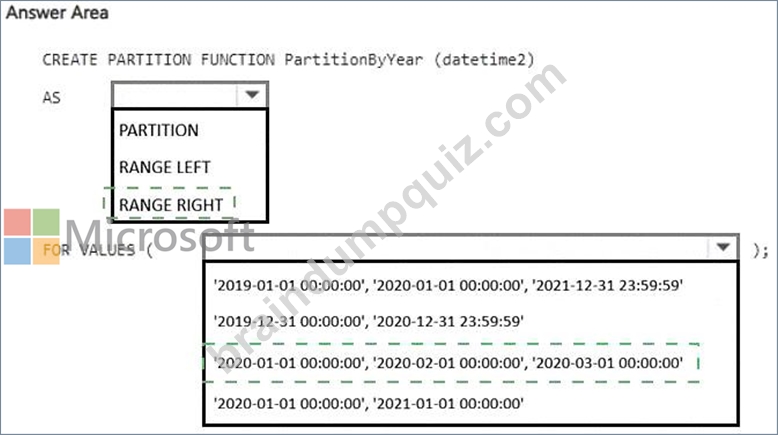
Explanation:
* Partition range # RANGE RIGHT
* Boundary values # ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The correct configuration is to use RANGE RIGHT with boundary values at the start of each year :
CREATE PARTITION FUNCTION PartitionByYear (datetime2)
AS RANGE RIGHT
FOR VALUES (
' 2020-01-01 00:00:00 ' ,
' 2021-01-01 00:00:00 '
);
Microsoft documents that with RANGE RIGHT , each boundary value belongs to the partition on its right .
For date-based partitioning, this is the natural pattern because a boundary such as 2021-01-01 becomes the lower boundary of the 2021 partition.
With these boundaries, the resulting ranges are effectively:
* Partition 1: dates before 2020-01-01
* Partition 2: 2020-01-01 through before 2021-01-01
* Partition 3: 2021-01-01 and later
This cleanly separates the 2020 and 2021 data into year-aligned partitions. Microsoft specifically recommends RANGE RIGHT for date-based boundaries because the first day of a period remains in the same partition as the rest of that period.
The other boundary choices are incorrect or less appropriate:
* Using year-end timestamps with RANGE LEFT is more cumbersome and can be sensitive to datetime2 precision.
* Monthly boundaries would partition by month, not year.
* Including 2019 and a 2021-12-31 23:59:59 boundary creates unnecessary partitions and is not the cleanest year-based design.
Therefore:
* First dropdown: RANGE RIGHT
* Second dropdown: ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
NEW QUESTION # 90
You have an SDK-style SQL database project named MyDatabaseProject.sqlproj stored in a private GitHub repository. The repository contains the following GitHub Actions workflow:
YAML
name: Build and Deploy SQL Project
on:
push:
branches:
- main
workflow_dispatch:
jobs:
build-and-deploy:
runs-on: ubuntu-latest
permissions:
id-token: write
contents: read
steps:
- uses: actions/checkout@v4
- name: Build SQL project
run: dotnet build MyDatabaseProject.sqlproj
- name: Publish DACPAC
uses: azure/sql-action@v2
Answer:
Explanation: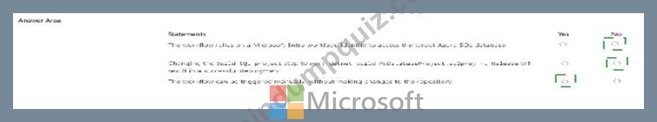
Explanation: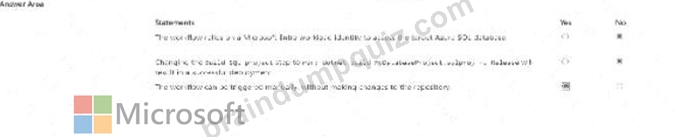
NEW QUESTION # 91
......
If you are willing to buy our DP-800 dumps pdf, I will recommend you to download the free dumps demo first and check the accuracy of our DP-800 practice questions. Maybe there are no complete DP-800 study materials in our trial, but it contains the latest questions enough to let you understand the content of our DP-800 Braindumps. Please try to instantly download the free demo in our exam page.
Real DP-800 Dumps Free: https://www.braindumpquiz.com/DP-800-exam-material.html
2026 Latest BraindumpQuiz DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1AXesGWTpZweZOhJehgOyIDTMB4cQUCri