P.S. PDFExamDumps在Google Drive上分享了免費的2026 CompTIA DY0-001考試題庫:https://drive.google.com/open?id=1hsSAbGGdXDepg-rHPN_yB2G-SZ011Ei-
在現在這個競爭激烈的社會裏,有一技之長是可以占很大優勢的。尤其在IT行業中.。獲到一些IT認證證書是非常有用的。 CompTIA DY0-001 是一個檢驗IT專業知識水準認證考試,在IT行業中也是一個分量相當重的認證考試。因為CompTIA DY0-001考試難度也比較大,所以很多為了通過CompTIA DY0-001 認證考試的人花費了大量的時間和精力學習考試相關知識,但是到最後卻沒有成功。PDFExamDumps為此分析了他們失敗的原因,我們得出的結論是他們沒有經過針對性的培訓。 現在PDFExamDumps的專家們為CompTIA DY0-001 認證考試研究出了針對性的訓練項目,可以幫你花少量時間和金錢卻可以100%通過考試。
| Section | Weight | Objectives |
|---|---|---|
| Machine Learning | 24% | - Algorithm selection and implementation - Hyperparameter tuning and optimization - Ethics and bias in machine learning - Deep learning fundamentals - Supervised, unsupervised, and reinforcement learning |
| Operations and Processes | 22% | - Data pipeline design and maintenance - Data governance and quality management - Model deployment and monitoring - Security and compliance in data operations - Version control and reproducibility |
| Mathematics and Statistics | 17% | - Statistical inference and hypothesis testing - Linear algebra fundamentals - Calculus and optimization concepts - Bayesian reasoning and modeling - Probability theory and distributions |
| Modeling, Analysis, and Outcomes | 24% | - Result interpretation and business communication - Predictive and prescriptive analytics - Data preparation and exploratory data analysis - Model selection and evaluation metrics - Feature engineering and selection |
| Specialized Applications of Data Science | 13% | - Time-series analysis - Anomaly detection and signal processing - Computer Vision - Natural Language Processing (NLP) - Industry-specific analytics use cases |
我們PDFExamDumps CompTIA的DY0-001考試的做法是最徹底的,以及最準確及時的最新的實踐檢驗,你會發現目前市場上的唯一可以有讓你第一次嘗試通過困難的信心。CompTIA的DY0-001考試認證在世界上任何一個國家將會得到承認,所有的國家將會一視同仁,PDFExamDumps CompTIA的DY0-001認證證書不僅有助於提高你的知識和技能,也有助於你的職業生涯在不同的條件下多出一個可能性,我們PDFExamDumps CompTIA的DY0-001考試認證合格使用。
問題 #44
A data scientist receives an update on a business case about a machine that has thousands of error codes. The data scientist creates the following summary statistics profile while reviewing the logs for each machine: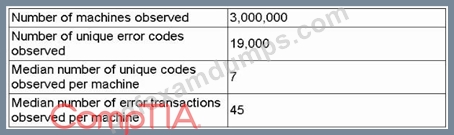
| Number of machines observed | 3,000,000
| Number of unique error codes observed | 19,000
| Median number of unique codes per machine | 7
| Median number of error transactions | 45
Which of the following is the most likely concern with respect to data design for model ingestion?
答案:C
解題說明:
# With 19,000 unique error codes and only 7 codes per machine (on median), the data structure will likely consist of a very large number of binary features (e.g., one-hot encoded error codes), most of which will be 0 for any given machine. This leads to a sparse matrix-where the majority of elements are zero-which poses computational and modeling challenges.
Why the other options are incorrect:
* B: Granularity misalignment would mean mismatched levels (e.g., mixing daily and hourly data), which is not the issue here.
* C: There are many features (error codes), not too few.
* D: Multivariate outliers involve unusual combinations across features, not sparsity.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"High-cardinality categorical features can result in sparse matrices, especially when one-hot encoded for models."
問題 #45
A data analyst wants to generate the most data using tables from a database. Which of the following is the best way to accomplish this objective?
答案:D
解題說明:
# FULL OUTER JOIN returns all rows from both tables, inserting NULLs where no match exists. This join includes the maximum possible number of records - all matches, plus all unmatched records from both sides.
Why the other options are incorrect:
* A: INNER JOIN returns only matching rows - less total data.
* B & C: LEFT/RIGHT JOIN include all rows from one table only.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 5.2:"A FULL OUTER JOIN maximizes data volume by including all matched and unmatched records from both tables."
* SQL for Data Science, Chapter 4:"Use FULL OUTER JOIN when the goal is to preserve every record from both datasets regardless of match."
-
問題 #46
Which of the following problem-solving approaches is a set of guidelines to handle highly variable and not fully apparent situations?
答案:C
解題說明:
Heuristics are rule-of-thumb strategies that guide problem solving in complex, uncertain situations where a fixed algorithm or plan isn't feasible.
問題 #47
Which of the following distributions would be best to use for hypothesis testing on a data set with 20 observations?
答案:D
解題說明:
With only 20 observations and an unknown population variance, the t-distribution (with 𝑛 - 1 degrees of freedom) properly accounts for the extra uncertainty in the standard error when performing hypothesis tests.
問題 #48
A data scientist would like to model a complex phenomenon using a large data set composed of categorical, discrete, and continuous variables. After completing exploratory data analysis, the data scientist is reasonably certain that no linear relationship exists between the predictors and the target. Although the phenomenon is complex, the data scientist still wants to maintain the highest possible degree of interpretability in the final model. Which of the following algorithms best meets this objective?
答案:C
解題說明:
# Decision trees offer excellent interpretability while handling complex, non-linear relationships and multiple variable types (categorical, discrete, continuous). They provide easy-to-understand visualizations and logic- based rules, making them ideal when transparency and insight are priorities.
Why other options are incorrect:
* A: Neural networks are powerful but are considered "black box" models, with low interpretability.
* C: Linear regression assumes a linear relationship, which contradicts the scenario.
* D: Random forests are ensembles of trees - more accurate, but less interpretable.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.2:"Decision trees are interpretable models that support non-linear, multi-type data with logical branching."
-
問題 #49
......
對于DY0-001認證是評估職員在公司所具備的能力和知識,而如何獲得CompTIA DY0-001認證是大多數考生面臨的挑戰性的問題。現在的考試如DY0-001在經常的跟新,準備通過這個考試是一項艱巨的任務,CompTIA DY0-001考古題是一個能使您一次性通過該考試的題庫資料。一旦您通過考試,您將獲得不錯的工作機會,所以,選擇DY0-001題庫就是選擇成功,我們將保證您百分之百通過考試。
DY0-001學習指南: https://www.pdfexamdumps.com/DY0-001_valid-braindumps.html
P.S. PDFExamDumps在Google Drive上分享了免費的2026 CompTIA DY0-001考試題庫:https://drive.google.com/open?id=1hsSAbGGdXDepg-rHPN_yB2G-SZ011Ei-