Complete Certified-Data-Engineer-Professional Reliable Dumps Ebook & Leader in Qualification Exams & Newest Exam Certified-Data-Engineer-Professional Objectives Pdf

If you are preparing for the Certified-Data-Engineer-Professional Questions and answers, and like to practice it in your spare time, then you should conseder the Certified-Data-Engineer-Professional exam dumps of our company. Certified-Data-Engineer-Professional Online test engine is convenient and easy to study, it supports all web browsers. Besides you can practice online anytime. With all the benefits like this, you can choose us bravely. With this version, you can pass the exam easily, and you don’t need to spend the specific time for practicing, just your free time is ok.
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 2. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
>> Certified-Data-Engineer-Professional Reliable Dumps Ebook <<
Exam Certified-Data-Engineer-Professional Objectives Pdf, Study Certified-Data-Engineer-Professional Material
To learn more about our Certified-Data-Engineer-Professional exam braindumps, feel free to check our Certified-Data-Engineer-Professional Exams and Certifications pages. You can browse through our Certified-Data-Engineer-Professional certification test preparation materials that introduce real exam scenarios to build your confidence further. Choose from an extensive collection of products that suits every Certified-Data-Engineer-Professional Certification aspirant. You can also see for yourself how effective our methods are, by trying our free demo. So why choose other products that can’t assure your success? With Exam4Tests, you are guaranteed to pass Certified-Data-Engineer-Professional certification on your very first try.
Databricks Certified Data Engineer Professional Sample Questions (Q209-Q214):
NEW QUESTION # 209
What statement is true regarding the retention of job run history?
- A. It is retained for 90 days or until the run-id is re-used through custom run configuration
- B. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- C. It is retained for 60 days, during which you can export notebook run results to HTML
- D. It is retained for 60 days, after which logs are archived
- E. It is retained until you export or delete job run logs
Answer: C
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 210
Which statement regarding spark configuration on the Databricks platform is true?
- A. Spark configuration properties set for an interactive cluster with the Clusters UI will impact all notebooks attached to that cluster.
- B. Spark configuration properties can only be set for an interactive cluster by creating a global init script.
- C. The Databricks REST API can be used to modify the Spark configuration properties for an interactive cluster without interrupting jobs.
- D. Spark configuration set within an notebook will affect all SparkSession attached to the same interactive cluster
- E. When the same spar configuration property is set for an interactive to the same interactive cluster.
Answer: A
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
NEW QUESTION # 211
The following code has been migrated to a Databricks notebook from a legacy workload:
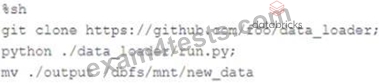
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- B. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- C. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- D. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- E. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
Answer: B
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 212
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:

The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
- A. Use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update.
- B. Implement the appropriate aggregate logic as a Structured Streaming read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- C. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and overwrite the store_sales_summary table with each Update.
- D. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and append new rows nightly to the store_sales_summary table.
- E. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
Answer: C
NEW QUESTION # 213
Which statement describes Delta Lake Auto Compaction?
- A. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- C. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- D. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- E. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
Answer: C
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
NEW QUESTION # 214
......
Here, we provide you with Certified-Data-Engineer-Professional accurate questions & answers which will be occurred in the actual test. About explanations, the difficult issues will be along with detail explanations, so that you can easy to get the content of our Databricks Certified-Data-Engineer-Professional pdf vce and have a basic knowledge of the key points. Besides, you can choose the Certified-Data-Engineer-Professional Vce Format files for simulation test. It can help you enhance your memory and consolidate the knowledge, thus the successful pass is no longer a difficult thing.
Exam Certified-Data-Engineer-Professional Objectives Pdf: https://www.exam4tests.com/Certified-Data-Engineer-Professional-valid-braindumps.html
- Free PDF Quiz 2026 Valid Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Reliable Dumps Ebook 🥠 Open ⇛ www.troytecdumps.com ⇚ and search for ( Certified-Data-Engineer-Professional ) to download exam materials for free 💠Certified-Data-Engineer-Professional Actual Exams
- Exam Certified-Data-Engineer-Professional Price 🌕 100% Certified-Data-Engineer-Professional Correct Answers 🧴 Valid Certified-Data-Engineer-Professional Exam Bootcamp 🏠 Search for ➤ Certified-Data-Engineer-Professional ⮘ and easily obtain a free download on 《 www.pdfvce.com 》 🌅Certified-Data-Engineer-Professional Authorized Test Dumps
- Valid Certified-Data-Engineer-Professional Exam Bootcamp 👣 Certified-Data-Engineer-Professional Certification Training 🎯 Vce Certified-Data-Engineer-Professional Free 🏝 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply searching on ➽ www.torrentvce.com 🢪 🐸Vce Certified-Data-Engineer-Professional Free
- Quiz 2026 Certified-Data-Engineer-Professional: Latest Databricks Certified Data Engineer Professional Reliable Dumps Ebook 🥬 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free on ➽ www.pdfvce.com 🢪 website 🐐Real Certified-Data-Engineer-Professional Exams
- Latest Certified-Data-Engineer-Professional Test Sample 🕚 Pdf Certified-Data-Engineer-Professional Format ⚫ Certified-Data-Engineer-Professional Exam Dumps Pdf 🎀 The page for free download of ➽ Certified-Data-Engineer-Professional 🢪 on 【 www.prepawaypdf.com 】 will open immediately 🛑Valid Certified-Data-Engineer-Professional Cram Materials
- Certified-Data-Engineer-Professional Authorized Test Dumps 🥍 Certified-Data-Engineer-Professional Dumps Torrent 🧰 New Certified-Data-Engineer-Professional Test Vce 🍇 Easily obtain free download of ⮆ Certified-Data-Engineer-Professional ⮄ by searching on [ www.pdfvce.com ] 🐔Certified-Data-Engineer-Professional Certification Training
- Vce Certified-Data-Engineer-Professional Free 😈 Certified-Data-Engineer-Professional Certification Training 🔗 Certified-Data-Engineer-Professional Actual Exams 🕷 Easily obtain “ Certified-Data-Engineer-Professional ” for free download through 「 www.dumpsmaterials.com 」 🕗New Certified-Data-Engineer-Professional Test Vce
- Pass Guaranteed Databricks Marvelous Certified-Data-Engineer-Professional Reliable Dumps Ebook 🌙 ➠ www.pdfvce.com 🠰 is best website to obtain ▷ Certified-Data-Engineer-Professional ◁ for free download 🖌Certified-Data-Engineer-Professional Valid Test Duration
- Valid Certified-Data-Engineer-Professional Cram Materials 🕔 Real Certified-Data-Engineer-Professional Exams 🦐 Pdf Certified-Data-Engineer-Professional Format 🎲 ➽ www.prepawayete.com 🢪 is best website to obtain 「 Certified-Data-Engineer-Professional 」 for free download 🕖Certified-Data-Engineer-Professional Dumps Torrent
- 2026 Certified-Data-Engineer-Professional Reliable Dumps Ebook | Reliable Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass 🏋 Copy URL 《 www.pdfvce.com 》 open and search for ▶ Certified-Data-Engineer-Professional ◀ to download for free 🚈100% Certified-Data-Engineer-Professional Correct Answers
- Vce Certified-Data-Engineer-Professional Free ⭐ 100% Certified-Data-Engineer-Professional Correct Answers 🥃 Valid Certified-Data-Engineer-Professional Cram Materials 🟠 Go to website ➤ www.pass4test.com ⮘ open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🍗Test Certified-Data-Engineer-Professional Pdf
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes