BONUS!!! Download part of VCE4Dumps DP-600 dumps for free: https://drive.google.com/open?id=1dzUxOMEjekAx_qxkPhdicc08ghdM9Tb0
VCE4Dumps Microsoft DP-600 exam information are cheap and fine. We use simulation questions and answers dedication to our candidates with ultra-low price and high quality. We sincerely hope that you can pass the exam. We provide you with a convenient online service to resolve any questions about Microsoft DP-600 Exam Questions for you.
| Section | Objectives |
|---|---|
| Topic 1: Implement data engineering solutions | - Lakehouse architecture
|
| Topic 2: Get data into Microsoft Fabric | - Data ingestion and integration
|
| Topic 3: Manage and secure Microsoft Fabric | - Governance and administration
|
| Topic 4: Real-time analytics | - Streaming and event processing
|
| Topic 5: Implement analytics solutions | - Data warehousing and modeling
|
>> DP-600 Valid Study Guide <<
VCE4Dumps is a website for Microsoft Certification DP-600 Exam to provide a short-term effective training. Microsoft DP-600 is a certification exam which is able to change your life. IT professionals who gain Microsoft DP-600 authentication certificate must have a higher salary than the ones who do not have the certificate and their position rising space is also very big, who will have a widely career development prospects in the IT industry in.
NEW QUESTION # 202
Which syntax should you use in a notebook to access the Research division data for Productlinel?



Answer: B
Explanation:
Comprehensive Detailed Explanation
The question asks: Which syntax should you use in a Fabric notebook to access the Research division data for Productline1?
Key Background from the Case
In Productline1ws, a lakehouse named Lakehouse1 is created.
In Lakehouse1, a shortcut is created to storage1, named ResearchProduct.
Storage1 contains the Research division data for Productline1 in Delta format.
Requirement: All data in lakehouses must be presented as managed tables in Lakehouse explorer.
Analyzing the Syntax Options
Option A:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
This syntax directly queries the ResearchProduct shortcut within Lakehouse1 using Spark SQL.
Since the shortcut points to Delta data, Spark can directly query it.
This is the correct way to retrieve Productline1 data from Lakehouse1.
Option B:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
This introduces an extra schema-like path (productline1) that is not part of the shortcut name.
Incorrect, because the shortcut was created as ResearchProduct inside Lakehouse1, not under another schema.
Option C:
external_table( ' Tables/ResearchProduct ' )
external_table is not the correct way to access a Lakehouse shortcut.
Shortcuts in Lakehouses appear as tables and can be queried using Spark SQL directly.
Option D:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
Same issue as Option B, includes a schema path that does not exist.
Correct Choice
Since the shortcut to ResearchProduct was created inside Lakehouse1, and Spark SQL can query it directly, the correct syntax is:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
That matches Option A.
References
Microsoft Fabric Lakehouse - Shortcuts
Query data in a lakehouse using Spark SQL
Delta format support in Microsoft Fabric
NEW QUESTION # 203
You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.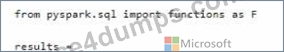
Which code should you run to populate the results DataFrame?




Answer: D
Explanation:
The correct code to populate the results DataFrame with minimal data shuffling is Option A. Using the broadcast function in PySpark is a way to minimize data movement by broadcasting the smaller DataFrame ( customers) to each node in the cluster. This is ideal when one DataFrame is much smaller than the other, as in this case with customers. References = You can refer to the official Apache Spark documentation for more details on joins and the broadcast hint.
NEW QUESTION # 204
You have a Fabric tenant that contains a workspace named Workspace1.
You plan to deploy a semantic model named Model1 by using the XMLA endpoint.
You need to optimize the deployment of Model1. The solution must minimize how long it takes to deploy Model1.
What should you do in Workspace1?
Answer: D
Explanation:
When using XMLA endpoint for deployment or processing, the semantic model storage format impacts deployment times.
Small storage format allows faster metadata operations and shorter deployment times.
Large semantic model storage format is only needed for extremely large models (> 10 GB dataset limit), and it increases deployment overhead.
The other options (B: service editing, C: cache for shortcuts) are unrelated to XMLA endpoint deployment performance.
Reference:
Power BI semantic model storage format
The Answer: Select Small semantic model storage format.
NEW QUESTION # 205
You have a Fabric workspace that uses the default Spark starter pool and runtime version 1,2.
You plan to read a CSV file named Sales.raw.csv in a lakehouse, select columns, and save the data as a Delta table to the managed area of the lakehouse. Sales_raw.csv contains 12 columns.
You have the following code.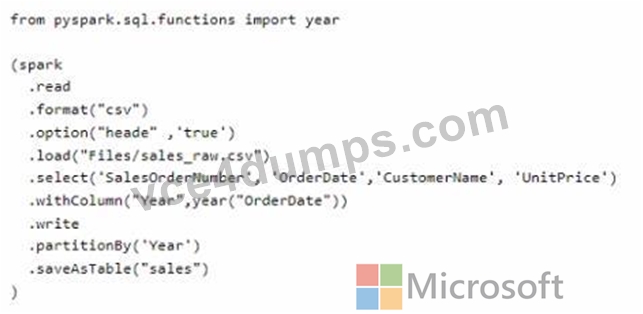
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.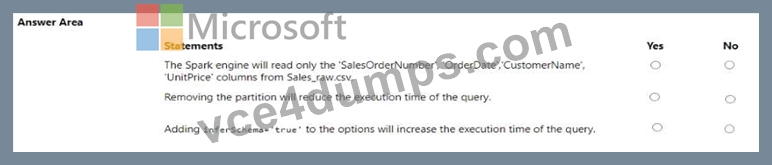
Answer:
Explanation: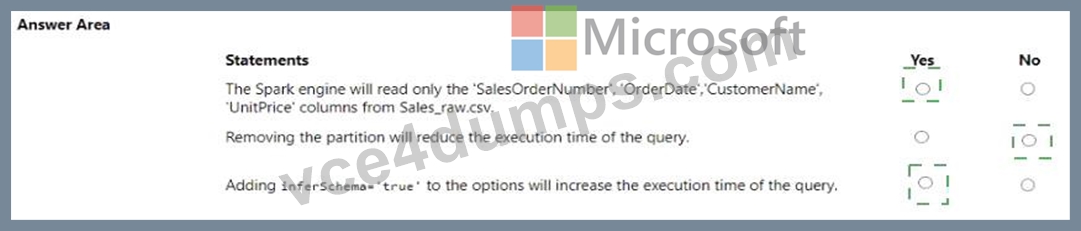
Explanation: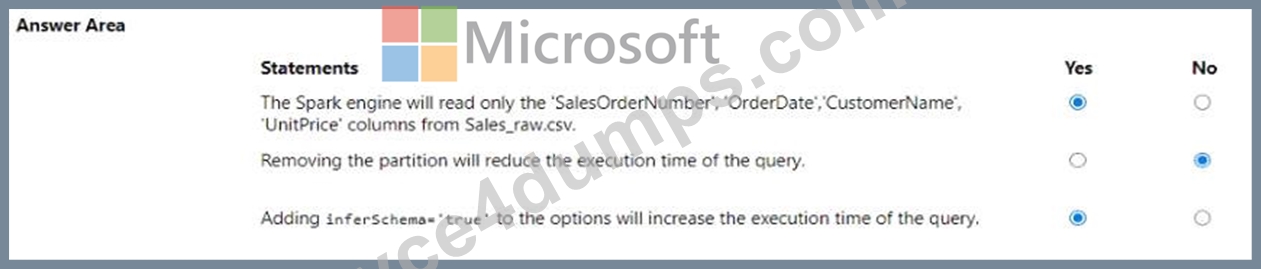
* The Spark engine will read only the 'SalesOrderNumber', 'OrderDate', 'CustomerName', 'UnitPrice' columns from Sales_raw.csv. - Yes
* Removing the partition will reduce the execution time of the query. - No
* Adding inferSchema='true' to the options will increase the execution time of the query. - Yes The code specifies the selection of certain columns, which means only those columns will be read into the DataFrame. Partitions in Spark are a way to optimize the execution of queries by organizing the data into parts that can be processed in parallel. Removing the partition could potentially increase the execution time because Spark would no longer be able to process the data in parallel efficiently. The inferSchema option allows Spark to automatically detect the column data types, which can increase the execution time of the initial read operation because it requires Spark to read through the data to infer the schema.
NEW QUESTION # 206
You are implementing a medallion architecture in a single Fabric workspace.
You have a lakehouse that contains the 8ronze and Silver layers and a warehouse that contains the Gold layer.
You create the items required to populate the layers as shown in the following table.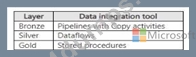
You need to ensure that the layers are populated daily in sequential order such that Silver is populated only after Bronze is complete, and Gold is populated only after Silver is complete. The solution must minimize development effort and complexity.
What should you use to execute each set of items? To answer, drag the appropriate options to the correct items. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.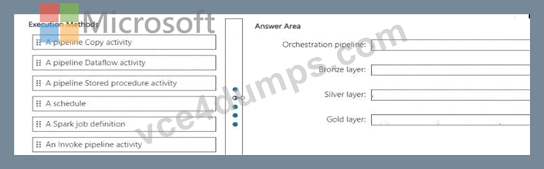
Answer:
Explanation: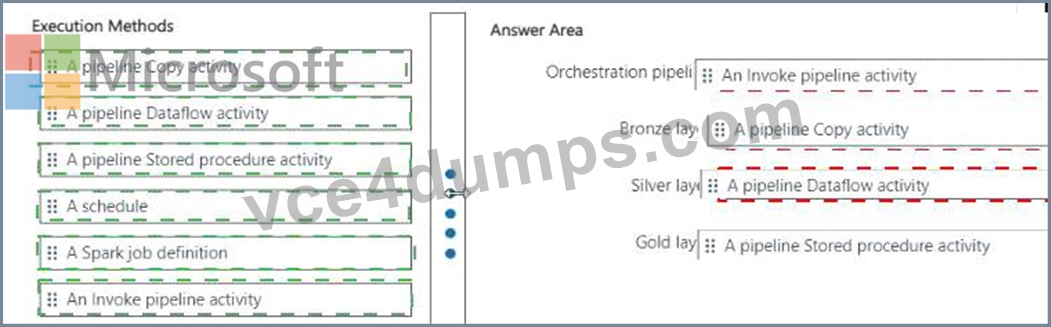
Explanation:
To execute each set of items in sequential order with minimized development effort and complexity, you should use the following options:
* Orchestration pipeline: Use a pipeline with an Invoke pipeline activity. This allows for orchestrating and scheduling the execution of other pipelines, ensuring they run in the correct sequence.
* Bronze layer: Implement a pipeline Copy activity. This aligns with the table indicating that the Bronze layer uses pipelines with Copy activities for data integration.
* Silver layer: Implement a pipeline Dataflow activity. The table specifies that Dataflows are used for the Silver layer.
* Gold layer: Implement a pipeline Stored procedure activity. Stored procedures are specified for the Gold layer according to the table.
NEW QUESTION # 207
......
From the moment you visit on our website, you are enjoying our excellent service on our DP-600 study guide. And no matter what kind of the problems you come to, we will solve it for you. We want to eliminate all unnecessary problems for you, and you can learn without any problems. You may have enjoyed many services, but the professionalism of our DP-600 simulating exam will conquer you. Our company has always upheld a professional attitude, which is reflected in our DP-600 exam braindumps, but also reflected in our services.
DP-600 Reliable Exam Questions: https://www.vce4dumps.com/DP-600-valid-torrent.html
P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by VCE4Dumps: https://drive.google.com/open?id=1dzUxOMEjekAx_qxkPhdicc08ghdM9Tb0