There are more opportunities for possessing with a certification, and our DP-750 study materials are the greatest resource to get a leg up on your competition, and stage yourself for promotion. When it comes to our time-tested DP-750 study materials, for one thing, we have a professional team contains a lot of experts who have devoted themselves to the research and development of our DP-750 Study Materials, thus we feel confident enough under the intensely competitive market. For another thing, conforming to the real exam our DP-750 study materials have the ability to catch the core knowledge.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 3: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
>> Pass4sure DP-750 Dumps Pdf <<
The Microsoft DP-750 Certification is a valuable credential in the modern world. The Microsoft DP-750 certification exam offers a great opportunity for beginners and experienced professionals to validate their skills and knowledge level. With the one certification Implementing Data Engineering Solutions Using Azure Databricks exam you can upgrade your expertise and knowledge.
NEW QUESTION # 74
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group1.
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
- Can create tables in schema1
- Can modify and query tables
- Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.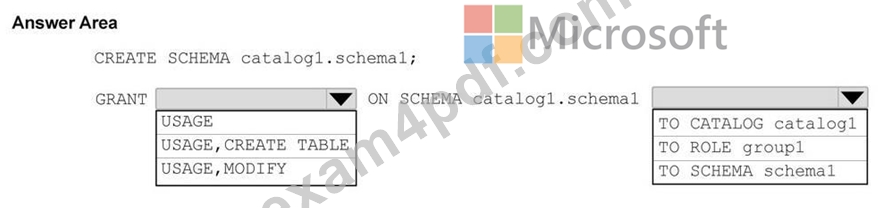
Answer:
Explanation: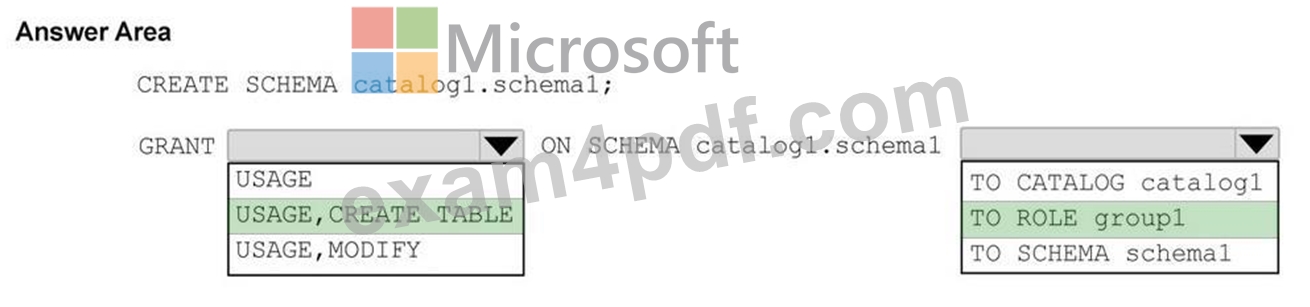
NEW QUESTION # 75
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders. Sales.orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows You need to load the daily data into Sales.orders. The solution must meet the following requirements:
* Preserve the existing data.
* Add only the new records.
* Minimize processing effort.
Which command should include in the loading strategy?
Answer: C
Explanation:
The correct answer is C - INSERT INTO.
The scenario is clear: the daily file contains only new records, no updates to existing rows. INSERT INTO is the right command because it appends the new rows to Sales.orders without touching the existing historical data. All three requirements are satisfied: existing data is preserved, only new records are added, and the loading strategy is as simple as it gets.
Option A (INSERT OVERWRITE) replaces the existing data with just today's file. After the first day you'd have only 24 hours of history - all prior sales records would be gone. Option B (UPDATE) modifies specific existing rows based on a match condition; it doesn't load new records at all.
Because the source file is guaranteed to contain only new records and no duplicates of existing rows, a full MERGE is unnecessary overhead. Simple INSERT INTO is both correct and the most efficient approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 76
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
- Deploy the app to both environments.
- Deploy only one job to development.
- Minimize administrative effort.
What should you use?
Answer: A
Explanation:
To meet your deployment needs with minimal administrative overhead, you should use Databricks Asset Bundle (DAB) targets combined with resource overrides or conditional lookups using Go template syntax in your databricks.yml file.
Instead of creating separate bundles or complex CI/CD logic, you can declare both jobs and the app inside the main resources block, and then filter or modify them per target environment.
Implementation Options
Depending on your preference for keeping configuration declarative or fully conditional, choose one of the two standard patterns:
*-> Option 1: Resource Overrides via targets (Recommended)
Define all components globally, but use the targets block to remove or empty out the configuration of the job you want to skip in development.yamlbundle:
name: my-unified-bundle
apps:
my_app:
# App configurations go here...
jobs:
job_shared:
# Configurations for the job deployed to BOTH dev and prod...
job_prod_only:
name: Only for Production
# Production configurations...
targets:
dev:
mode: development
workspace:
host: https://dev-workspace.cloud.databricks.com
# Keep administrative work low by overriding the prod job to null/empty resources:
jobs:
job_prod_only: !null
prod:
mode: production
workspace:
host: https://prod-workspace.cloud.databricks.com
Option 2: Go Template Conditional LogicIf you prefer not to use !null overrides, you can evaluate the target environment dynamically at deployment time using standard Go templates.
Reference:
https://docs.databricks.com/aws/en/dev-tools/bundles/workspace-deploy
NEW QUESTION # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: D
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 78
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.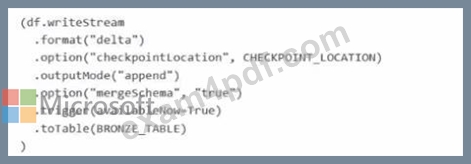
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.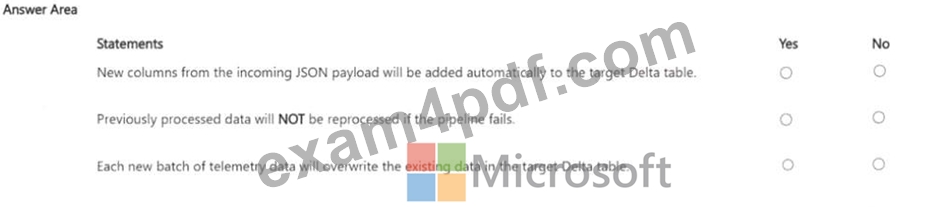
Answer:
Explanation: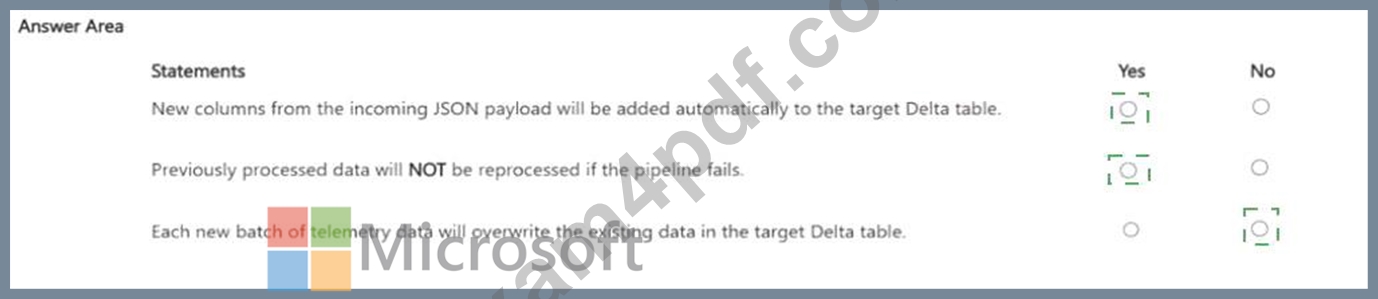
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 79
......
The pass rate is 98.65% for DP-750 learning materials, and we have gained popularity in the international market due to the high pass rate. We also pass guarantee and money back guarantee if you buy DP-750 exam dumps. We will give the refund to your payment account. What’s more, we use international recognition third party for the payment of DP-750 Learning Materials, therefore your money and account safety can be guaranteed, and you can just buying the DP-750 exam dumps with ease.
Valid DP-750 Exam Fee: https://www.exam4pdf.com/DP-750-dumps-torrent.html