2026 Latest Actual4test AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1Xmo_8sswrDk10VYxzRgQuupxh4euJO9K
Before starting the Microsoft AI-300 preparation, plan the amount of time you will allot to each topic, determine the topics that demand more effort and prioritize the components that possess more weightage in the Microsoft AI-300 Exam. This kind of polished approach is beneficial for a commendable grade in the Microsoft AI-300 Exam.
| Section | Weight | Objectives |
|---|---|---|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
There are too many variables and unknown temptation in life. So we should lay a solid foundation when we are still young. Are you ready? Working in the IT industry, do you feel a sense of urgency? Actual4test's Microsoft AI-300 Exam Training materials is the best training materials. Select the Actual4test, then you will open your door to success. Come on!
NEW QUESTION # 103
You are preparing training data for a fine-tuning job in Microsoft Foundry.
Real production conversations cannot be used due to compliance requirements.
You need to generate synthetic interaction data that can be used for fine-tuning a generative model.
What should you do?
Answer: B
Explanation:
The correct approach is to generate synthetic prompt-response interactions that reproduce the structure and behavioral patterns of the target task. Microsoft Foundry supports synthetic data generation specifically for cases where real production data is unavailable, scarce, sensitive, or subject to privacy and compliance restrictions. Generated examples can be converted into the structured conversational format required for fine- tuning, such as JSONL containing messages with system, user, and assistant roles.
A simulator or synthetic-data generator can construct representative conversations without exposing genuine customer interactions. This allows the team to create sufficient task-specific examples, review their quality, remove unsuitable samples, and then use the resulting dataset for supervised fine-tuning. Microsoft notes that synthetic data can preserve useful task structure while avoiding reliance on proprietary or sensitive production datasets.
Option A is incorrect because evaluation logs are primarily intended for assessment and observability and are not automatically suitable as training examples. Option C directly violates the requirement because it captures real production traffic. Option D confuses training data with observability artifacts: telemetry logs and traces describe execution behavior and diagnostics rather than producing the prompt-response examples required for fine-tuning.
Study Guide Reference: Optimize generative AI systems and model performance - synthetic data generation, supervised fine-tuning datasets, simulator-based interaction generation, privacy-preserving model customization, and training-data preparation.
NEW QUESTION # 104
You manage an Azure Machine learning workspace. You develop a machine learning model.
You must deploy the model to use a low-priority VM with a pricing discount.
You need to deploy the model.
Which compute target should you use?
Answer: A
Explanation:
The best compute target for deploying a model using low-priority VMs (or their modern successor, Spot VMs) is an Azure Machine Learning compute cluster.
Best Compute Target: AML Compute Cluster
For low-priority/Spot pricing, you should use an Azure Machine Learning compute cluster configured with the LowPriority tier.
Primary Use Case: This target is specifically recommended for batch deployments. Batch inference is ideal for low-priority VMs because these jobs are asynchronous and can tolerate the interruptions (preemptions) inherent to discounted capacity.
Pricing Advantage: Low-priority VMs offer significant discounts-often up to 80% off standard rates-by utilizing unused Azure capacity.
Automatic Handling: When a node is preempted during a batch job, Azure Machine Learning automatically attempts to replace the lost capacity and re-queues failed tasks to the cluster.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-low-priority-batch
NEW QUESTION # 105
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
Hotspot Question
You need to deploy the RAG-based chat application that meets Fabrikam Inc.'s business and technical requirements.
Which configuration should you use for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.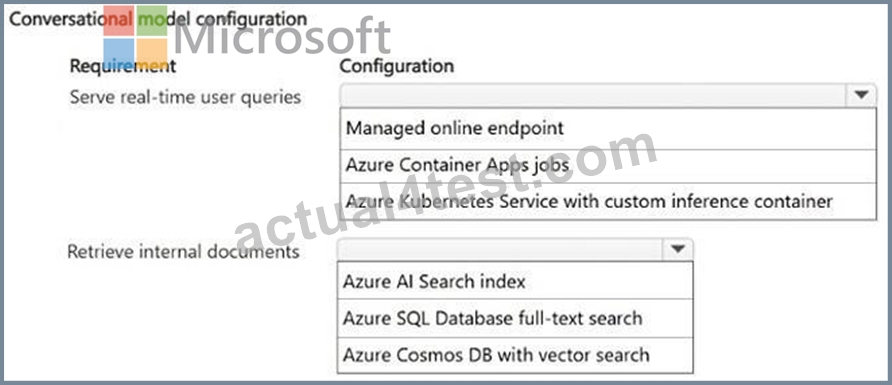
Answer:
Explanation: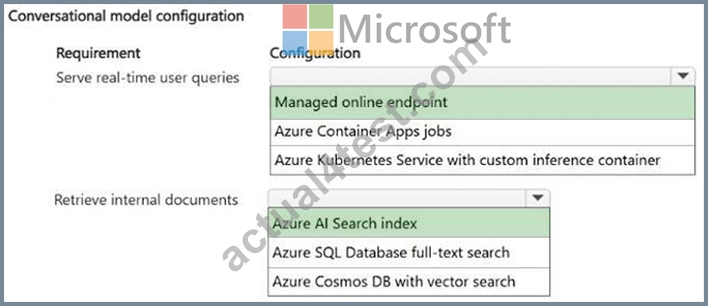
NEW QUESTION # 106
You manage an Azure Machine Learning workspace.
You train a model interactively with a Jupyter Notebook in the workspace During training, a dataset is created with accuiacy and loss metrics for each epoch.
You need to configure model tracking with MLflow to log the dataset created during the training.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.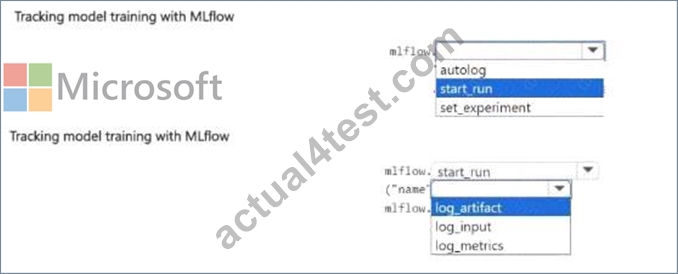
Answer:
Explanation: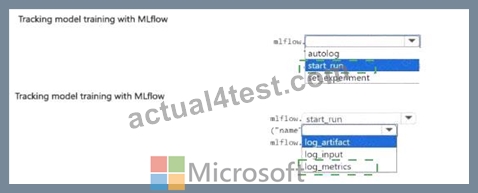
Explanation: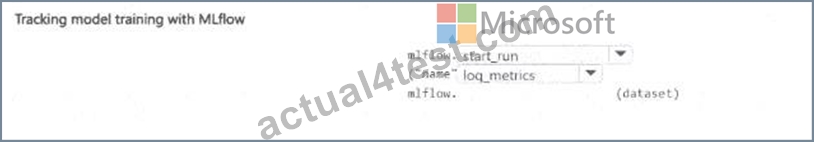
NEW QUESTION # 107
You create a workspace by using Azure Machine Learning Studio.
You must run a Python SDK v2 notebook in the workspace by using Azure Machine Learning Studio.
You need to reset the state of the notebook.
Which three actions should you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: B,C,D
Explanation:
To reset the state of a Python SDK v2 notebook in Azure Machine Learning Studio, you can perform any of the following three individual actions:
Stop the current kernel
Reset the compute instance
Change the current kernel
Each of these steps acts as a standalone solution to clear the current runtime memory, variables, and overall execution state of your notebook.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-run-jupyter-notebooks
NEW QUESTION # 108
......
Research indicates that the success of our highly-praised AI-300 test questions owes to our endless efforts for the easily operated practice system. With the latest AI-300 test questions, you can have a good experience in practicing the test. Moreover, you have no need to worry about the price, we provide free updating for one year and half price for further partnerships, which is really a big sale in this field. After your payment, we will send the updated AI-300 Exam to you immediately and if you have any question about updating, please leave us a message.
Accurate AI-300 Study Material: https://www.actual4test.com/AI-300_examcollection.html
BTW, DOWNLOAD part of Actual4test AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1Xmo_8sswrDk10VYxzRgQuupxh4euJO9K