Databricks-Certified-Professional-Data-Engineer practice materials are typically seen as the tools of reviving, practicing and remembering necessary exam questions for the exam, spending much time on them you may improve the chance of winning. However, our Databricks-Certified-Professional-Data-Engineer training materials can offer better condition than traditional practice materials and can be used effectively. We treat it as our major responsibility to offer help so our Databricks-Certified-Professional-Data-Engineer Practice Guide can provide so much help, the most typical one is their efficiency.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Pipeline observability and logging - Performance and health monitoring |
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Standardization and normalization - Handling missing or inconsistent data |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Auto Loader and streaming ingestion - Schema inference and evolution |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
| Data Governance | 7% | - Unity Catalog management - Policy enforcement - Data lineage and metadata tracking |
| Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Data Modelling | 6% | - Schema design and management - Delta Lake table design - Medallion Architecture implementation |
| Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
>> Databricks-Certified-Professional-Data-Engineer Latest Test Simulations <<
Will you feel nervous while facing a real exam environment? If you do choose us, we will provide you the most real environment through the Databricks-Certified-Professional-Data-Engineer exam dumps. Our soft online test version will stimulate the real environment, through this, you will know the process of the real exam. Databricks-Certified-Professional-Data-Engineer Exam Dumps will build up your confidence as well as reduce the mistakes. If you need the practice just like this, just contact us.
NEW QUESTION # 168
Which of the following scenarios is the best fit for AUTO LOADER?
Answer: D
Explanation:
Explanation
The answer is, Efficiently process new data incrementally from cloud object storage, AU-TO LOADER only supports ingesting files stored in a cloud object storage. Auto Loader cannot process streaming data sources like Kafka or Delta streams, use Structured streaming for these data sources.
Diagram Description automatically generated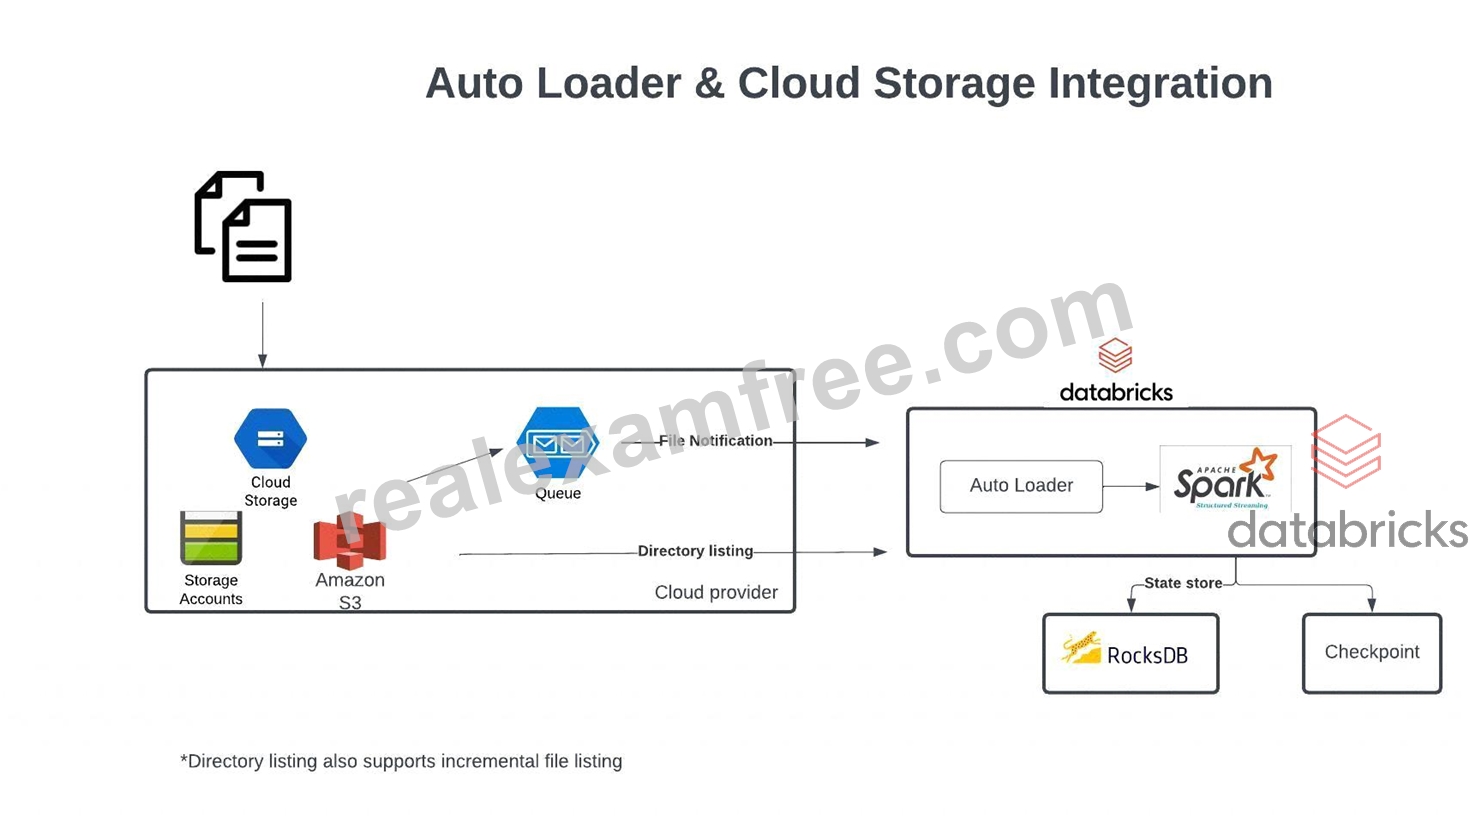
Auto Loader and Cloud Storage Integration
Auto Loader supports a couple of ways to ingest data incrementally
1.Directory listing - List Directory and maintain the state in RocksDB, supports incremental file listing
2.File notification - Uses a trigger+queue to store the file notification which can be later used to retrieve the file, unlike Directory listing File notification can scale up to millions of files per day.
[OPTIONAL]
Auto Loader vs COPY INTO?
Auto Loader
Auto Loader incrementally and efficiently processes new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a new Structured Streaming source called cloudFiles. Given an input directory path on the cloud file storage, the cloudFiles source automatically processes new files as they arrive, with the option of also processing existing files in that directory.
When to use Auto Loader instead of the COPY INTO?
*You want to load data from a file location that contains files in the order of millions or higher. Auto Loader can discover files more efficiently than the COPY INTO SQL command and can split file processing into multiple batches.
*You do not plan to load subsets of previously uploaded files. With Auto Loader, it can be more difficult to reprocess subsets of files. However, you can use the COPY INTO SQL command to reload subsets of files while an Auto Loader stream is simultaneously running.
NEW QUESTION # 169
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalidlatitudeandlongitudevalues in theactivity_detailstable have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to addCHECKconstraints to the Delta Lake table: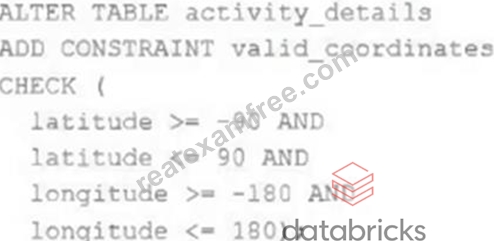
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: E
Explanation:
Explanation
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
NEW QUESTION # 170
Newly joined data analyst requested read-only access to tables, assuming you are owner/admin which section of Databricks platform is going to facilitate granting select access to the user
Answer: C
Explanation:
Explanation
Anser is Data Explorer
https://docs.databricks.com/sql/user/data/index.html
Data explorer lets you easily explore and manage permissions on databases and tables. Users can view schema details, preview sample data, and see table details and properties. Administrators can view and change owners, and admins and data object owners can grant and revoke permissions.
To open data explorer, click Data in the sidebar.
NEW QUESTION # 171
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table: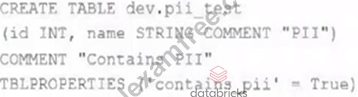
Which command allows manual confirmation that these three requirements have been met?
Answer: D
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "DESCRIBE EXTENDED" section.
NEW QUESTION # 172
Which of the following is true of Delta Lake and the Lakehouse?
Answer: C
Explanation:
https://docs.delta.io/2.0.0/table-properties.html
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters1. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer1. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan1. This can significantly improve the query performance and reduce the I/O cost.
The other options are false because:
Parquet compresses data column by column, not row by row2. This allows for better compression ratios, especially for repeated or similar values within a column2.
Views in the Lakehouse do not maintain a valid cache of the most recent versions of source tables at all times3. Views are logical constructs that are defined by a SQL query on one or more base tables3. Views are not materialized by default, which means they do not store any data, but only the query definition3. Therefore, views always reflect the latest state of the source tables when queried3. However, views can be cached manually using the CACHE TABLE or CREATE TABLE AS SELECT commands.
Primary and foreign key constraints can not be leveraged to ensure duplicate values are never entered into a dimension table. Delta Lake does not support enforcing primary and foreign key constraints on tables. Constraints are logical rules that define the integrity and validity of the data in a table. Delta Lake relies on the application logic or the user to ensure the data quality and consistency.
Z-order can be applied to any values stored in Delta Lake tables, not only numeric values. Z-order is a technique to optimize the layout of the data files by sorting them on one or more columns. Z-order can improve the query performance by clustering related values together and enabling more efficient data skipping. Z-order can be applied to any column that has a defined ordering, such as numeric, string, date, or boolean values.
NEW QUESTION # 173
......
The Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) actual questions we sell also come with a free demo. Spend no time, otherwise, you will pass on these fantastic opportunities. Start preparing for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam by purchasing the most recent Databricks Databricks-Certified-Professional-Data-Engineer exam dumps. You must improve your skills and knowledge to stay current and competitive. You merely need to obtain the Databricks-Certified-Professional-Data-Engineer Certification Exam badge in order to achieve this. You must pass the Databricks Certified Professional Data Engineer Exam exam to accomplish this, which can only be done with thorough exam preparation. Download the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions right away for immediate and thorough exam preparation.
Test Databricks-Certified-Professional-Data-Engineer Prep: https://www.realexamfree.com/Databricks-Certified-Professional-Data-Engineer-real-exam-dumps.html