As the authoritative provider of DP-750 guide training, we can guarantee a high pass rate compared with peers, which is also proved by practice. Our good reputation is your motivation to choose our learning materials. We guarantee that if you under the guidance of our DP-750 study tool step by step you will pass the exam without a doubt and get a certificate. Our DP-750 Learning Materials are carefully compiled over many years of practical effort and are adaptable to the needs of the DP-750 exam. We firmly believe that you cannot be an exception.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
Our DP-750 desktop practice test software works after installation on Windows computers. The Implementing Data Engineering Solutions Using Azure Databricks DP-750 web-based practice exam has all the features of the desktop software, but it requires an active internet connection. If you are busy in your daily routine and cant manage a proper time to sit and prepare for the DP-750 Certification test, our DP-750 PDF questions file is ideal for you. You can open and use the DP-750 Questions from any location at any time on your smartphones, tablets, and laptops. Questions in the Implementing Data Engineering Solutions Using Azure Databricks DP-750 PDF document are updated, and real.
NEW QUESTION # 36
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
* Ensure that authentication does NOT require storing credentials in Databricks
* Ensure that users can access the files, but NOT modify the files.
* Follow the principle of least privilege
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.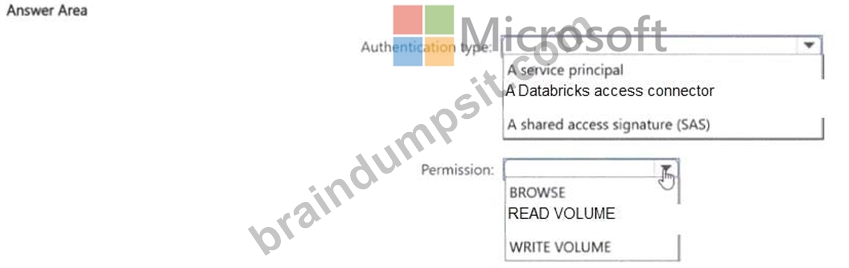
Answer:
Explanation: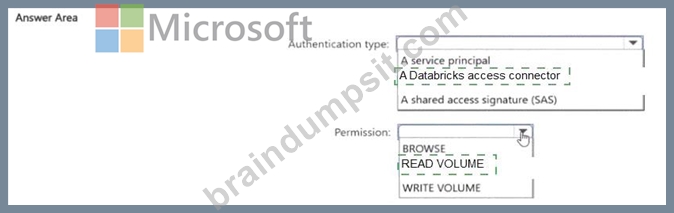
Explanation:
For authentication, a Managed Identity (via a Databricks Access Connector) is the right choice. The Access Connector wraps an Azure-managed identity so Databricks can authenticate to Azure Storage without any credentials being stored in the workspace. The cloud security team controls the identity through Azure RBAC
- there are no secrets to rotate or leak inside Databricks.
For the permission, READ FILES on the volume is exactly right. It allows users to read and list files through the volume path while blocking writes, deletes, and modifications. This is the minimum necessary access, honouring the principle of least privilege.
WRITE FILES would allow modifications, contradicting 'users can access but NOT modify.' ALL PRIVILEGES grants far more than needed. Service principals with stored client secrets would mean credentials inside Databricks, violating the 'does not require storing credentials' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/volumes
NEW QUESTION # 37
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table! is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table!
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: C
NEW QUESTION # 38
You have an Azure Databricks solution that was developed by multiple engineers and deployed to development, test, and production environments.
You need to implement an application lifecycle management (ALM) process that meets the following requirements:
* Deploys and provides source control for Databricks notebooks, workflows, and jobs in a consistent and repeatable way.
* Parameterizes the target deployment environment.
What should you include in the solution?
Answer: A
Explanation:
Declarative Automation Bundles provide an infrastructure-as-code approach for defining, deploying, and managing complete Azure Databricks projects. A bundle can contain notebooks and other source files together with resource definitions for Lakeflow Jobs, pipelines, dashboards, models, and related workspace resources. Storing the bundle in Git provides source control, collaboration, code review, and integration with automated CI/CD workflows.
Bundle targets can define environment-specific values and overrides for development, test, and production.
The same source-controlled project can therefore be deployed repeatedly to different environments without manually modifying its core definitions. This directly satisfies the requirement to parameterize the target deployment environment. Microsoft Learn Git folders provide source control but manual promotion is inconsistent and error-prone. Terraform is primarily intended for provisioning infrastructure and workspace resources rather than packaging the entire Databricks application lifecycle, including its source files. Exporting and importing workspaces is also a manual process that does not provide a reliable parameterized deployment model. Therefore, Declarative Automation Bundles stored in Git are the appropriate solution.
NEW QUESTION # 39
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: B
Explanation:
The correct answer is C - File Arrival trigger.
File Arrival monitors a specified Azure Storage path and fires a job run each time a new file lands there. This ticks both requirements: Job1 starts automatically in response to new data (no human involvement), and when no files arrive, no job runs - no cluster spins up, no compute cost is incurred.
Option A (scheduled) runs at fixed intervals regardless of whether files are waiting. A quiet weekend still kicks off hourly (or daily) runs, burning compute for nothing. Option B (continuous) keeps the job running perpetually, consuming resources even during long gaps between file arrivals - exactly what 'does NOT consume compute resources when no data is available' rules out. Option D (manual) requires a person to trigger every run, which is unsuitable for unpredictable arrival patterns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers#file-arrival-trigger
NEW QUESTION # 40
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a schema named Schema1 and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute-based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 41
......
Our Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam dumps give help to give you an idea about the actual Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam. You can attempt multiple Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions on the software to improve your performance. You have the option to change the topic and set the time according to the actual Microsoft DP-750 Exam.
Latest DP-750 Dumps Ebook: https://www.braindumpsit.com/DP-750_real-exam.html