高品質の製品に基づいて、当社のAB-620ガイドトレントは、98%〜100%を達成できるテスト合格率を保証する高品質です。 AB-620学習ツールは、経験豊富な専門家によってオンラインで更新され、ユーザーに送信されます。そのため、学習資料の更新に特別な注意を払う必要はありません。 AB-620試験トレントのデータは前向きであり、ユーザーが最新の知識を習得するのに役立つホットトピックを把握できます。和解しておらず、再度自分自身に挑戦したい場合は、特定の割引を提供します。
| Section | Objectives |
|---|---|
| Plan and Design Copilot Studio AI Agents | - Requirements analysis for AI agent solutions - Designing conversation flows and agent behavior - Selecting Copilot Studio capabilities and architecture approach |
| Deploy, Monitor, and Optimize AI Agents | - Iterative improvement and lifecycle management - Monitoring performance and analytics - Publishing and deploying copilots |
| Build and Configure AI Agents in Copilot Studio | - Configuring actions, plugins, and connectors - Creating and configuring copilots and topics - Using generative AI and prompt engineering in Copilot Studio |
| Governance, Security, and Compliance | - Data protection and responsible AI practices - Environment management in Power Platform - Managing access control and authentication |
| Integrate External Systems and Data Sources | - Connecting Azure services and APIs - Integrating Dataverse and Power Platform components - Using Power Automate for workflow orchestration |
世界は変化している、我々はできるだけそのペースを維持する必要があります。我々JPNTestはMicrosoftのAB-620試験の変化を注目しています。数年以来の試験問題集を研究しています。現在あなたに提供するのは大切なMicrosoftのAB-620資料です。あなたの購入してから、我々はあなたにMicrosoftのAB-620資料の更新情況をつど提供します。このサービスは無料なのです。あなたが我々の資料を購入するとき、あなたのMicrosoftのAB-620試験に関するすべてのヘルプを購入しました。
質問 # 50
Case Study 2 - Fabrikam Inc.
Background
Fabrikam Inc. is a Canada-based manufacturer with a growing service organization that supports field technicians and internal operations teams. Fabrikam Inc. plans to launch a new internal agent solution named Operations Concierge to reduce time spent searching policy content, retrieving operational metrics, and executing routine transactions.
The agent will be used by three groups:
- Service coordinators who triage incoming service requests
- Field technicians who need guided procedures and parts availability
- Operations managers who monitor KPIs and exceptions
The agent solution must work in real-world operational conditions. Users often ask questions mid- call with a customer or while coordinating parts shipments. The agents require quick, reliable outcomes. As a result, Fabrikam Inc. requires the solution to:
- Provide grounded answers with traceability when it provides guidance.
- Retrieve real-time metrics when users ask for operational status.
- Execute authenticated updates when users initiate a flow (such as creating a parts request).
Fabrikam Inc. also expects the solution to be maintained by multiple makers and developers across the year. The company has experienced duplicated logic and inconsistent behavior across different agents. This project emphasizes reuse, governance, and maintainability across teams.
Current environment
Fabrikam Inc. runs three Microsoft Power Platform environments for agent development and release: Dev, Test, and Prod.
The team plans to build the agent and validate it in Dev and Test, then promote to Prod by using a controlled release process that supports repeatable deployments.
Fabrikam Inc. already has two assets the team wants to reuse:
- A partially completed Copilot Studio agent named Service Desk Agent, used by IT to create internal tickets and route requests
- A Microsoft Foundry agent created by a central AI team that performs specialized summarization and classification for long-form text (for example, summarizing call transcripts into an incident narrative) Fabrikam Inc. also has operational and knowledge data sources:
- A curated policy library (internal SOPs, service warranty rules, escalation criteria, and standard operating procedures)
- A set of indexed documents and procedures in an Azure AI Search service that supports vector search for the policy library
- A Microsoft Fabric workspace that includes a semantic model used by operations leadership for reporting Business requirements Fabrikam Inc. requires Operations Concierge to meet the following business requirements:
- Traceability requirement: When the agent provides policy guidance or procedural recommendations, users must be able to see where the answer came from.
- Metrics requirement: When users ask about service performance (backlog, SLA risk, parts shortages, dispatch delays), the solution must return up-to-date metrics in a structured format that operations managers can use in weekly reviews.
- Transaction requirement: The solution must support authenticated updates initiated during conversations, including creating a parts request and updating a service case status.
In addition, Fabrikam Inc. wants to avoid duplicating common assets across agents:
- The team must reuse the same set of escalation topics, MCP tool definitions, and a standard safety disclaimer across three different agents.
- Only the platform engineering group as allowed to edit shared assets. However, all agent authors must be able to use them.
Technical requirements
The Fabrikam Inc. solution architecture uses a multi-agent approach so that specialist responsibilities are isolated and can evolve independently.
The Operations Concierge (primary agent) must coordinate the following specialist capabilities:
- Policy and procedure Q&A: Use an enterprise knowledge source that supports indexed retrieval across the curated policy library and service procedures.
- Operational metrics: Delegate metric queries to a Fabric Data Agent that reads governed business data through the Fabric semantic model.
- Authenticated updates: Use tools exposed by an existing internal Model Context Protocol (MCP) server that provides transactional operations for the service organization.
- Specialized processing: Delegate summarization and classification requests to an existing Microsoft Foundry agent.
Fabrikam Inc. will onboard two MCP servers as tools:
- PartsOps MCP server: exposes tools for parts availability checks and parts request creation.
The server requires per-user authentication because actions must be traceable to the requesting user.
- WarrantyRules MCP server: exposes a read-only tool for validating warranty coverage. The server uses an API key shared by the agent team.
Fabrikam Inc. has also defined a collaboration requirement with the existing Service Desk Agent:
- The primary agent must delegate IT-specific requests to the existing Service Desk Agent rather than reimplement ticket creation logic.
Finally, Fabrikarn Inc. plans to support a partner integration:
- For shipment tracking inquiries, Fabrikam Inc. will delegate to a partner-provided agent that is only available through a standardized agent-to-agent endpoint.
Issues and constraints
During early testing, Fabrikam Inc. found three recurring problems:
- Makers are copying and modifying the same components across agents, resulting in inconsistent disclaimers and duplicated tools.
- Users can obtain a correct answer, but the response is not consistently traceable to a source when the agent uses knowledge.
- The primary agent can route some requests, but specialist capabilities are not consistently delegated (for example, some metric questions are answered generatively instead of being routed to the Fabric Data Agent).
You are part of the engineering team responsible for correcting the design and configuration to meet the preceding requirements and constraints.
You need to configure Operations Concierge so that prompt-driven summarization behavior aligns with Fabrikam Inc.'s architectural requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:A、E
解説:
Scenario: Specialized processing: Delegate summarization and classification requests to an existing Microsoft Foundry agent.
[C] Model Selection: Choosing a specific model from the Foundry catalog ensures that your classification and summarization requests are routed directly to the correct, optimized LLM backend within the Microsoft Foundry ecosystem.
[E] Custom Prompt Templates: Creating and applying a reusable template ensures consistent formatting, tone, and logic across all areas where your agent handles summarization and classification tasks.
Reference:
https://learn.microsoft.com/en-us/microsoft-copilot-studio/bring-your-own-model-prompts
https://learn.microsoft.com/en-us/microsoft-copilot-studio/nlu-prompt-node
質問 # 51
Drag and Drop Question
You run the same fixed test set three times in Copilot Studio.
During evaluation, you observe the following:
- The same interaction fails in all three runs.
- Score values range from 0.58 to 0.61.
- The reasoning states that the response partially matches the expected answer.
- The knowledge source that is used is internal documentation.
- No tools are invoked.
You need to determine which conclusions are supported based on the evaluation results.
Which conclusions should you make? To answer, move the appropriate conclusions to the correct evaluation results. You may use each conclusion once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.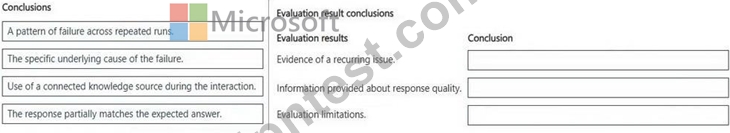
正解:
解説: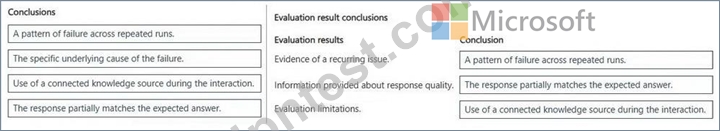
Explanation:
Box 1: A pattern failure across repeated runs.
The correct conclusion concerning evidence of a recurring issue is a) a pattern failure across repeated runs.
When the exact same interaction fails across three repeated runs, it establishes a systemic, predictable pattern rather than an isolated, one-time anomaly.
Box 2: The response partially matches the expected answer.
Based on the evaluation criteria in Microsoft Copilot Studio, the most definitive and direct conclusion that can be made concerning response quality is that the response partially matches the expected answer.
Direct Evidence: The evaluation results explicitly state in the reasoning that the "response partially matches the expected answer." This directly provides a qualitative conclusion regarding the quality of the generated response.
Score Alignment: The semantic similarity or quality score values ranging from 0.58 to 0.61 align with a partial match. In AI evaluation metrics, a perfect match is represented by 1.0, while values in the 0.6x range indicate that the core context was captured but lacked full completeness or exactness.
Box 3: Use of a connected knowledge source during the interaction
Because generative AI outputs are non-deterministic, running the same test set across a dynamic environment can yield varying scores. In Microsoft Copilot Studio, observing scores consistently between 0.58 and 0.61 points to a fundamental limitation with the underlying knowledge source.
The evaluation points to option use of a connected knowledge source during the interaction.
Because no tools are invoked, the agent heavily relies on generative search (retrieval-augmented generation) over internal documentation. The score range and reasoning indicate that the agent successfully retrieves a document but relies on a probabilistic model to paraphrase or assemble the response, which results in a "partial match" rather than an exact extraction.
Incorrect:
In contrast, specific underlying causes require explicit tool invocations or system error logs to diagnose, which are not present here.
Reference:
https://learn.microsoft.com/en-us/microsoft-copilot-studio/analytics-agent-evaluation-results
質問 # 52
Which two actions should you perform before making the agent available on both channels? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
正解:A、B
解説:
* A. Configure prompt modifications at the system level. Centralized instructions enforce the required tone, disclaimers, response boundaries, and refusal behavior consistently across generative responses.
Microsoft documents that prompt modification can define an agent's personality, response format, permitted subjects, and behavior when an answer is unavailable. This avoids inconsistent manual changes across individual topics. Microsoft: Prompt modification
* D. Configure Power Platform DLP policies. DLP policies govern which connectors, knowledge sources, HTTP endpoints, and channels the agent may use. They should be configured and validated before publication because a policy violation can prevent the agent from being published. DLP also protects against unauthorized data movement between business and non-business connectors.
Microsoft: Data policies for agents
Why the others are incorrect: B creates duplicated, inconsistent disclaimers. C incorrectly treats moderation as a web-channel setting; moderation is configured for generative behavior rather than enforced only by embedding settings. E applies safeguards after publication and assumes filters must be configured separately for every channel, which would not provide the required centralized governance.
質問 # 53
A company has an approved custom connector that uses a REST API for an internal system.
An agent in Copilot Studio must call this connector during conversations to retrieve or update data.
To meet the business needs, the solution must meet the following requirements:
Make the connector actions available for the agent to invoke.
Ensure authentication is handled at the service level, not per user.
Pass conversation context into the connector when it is called.
Surface the returned data of the connector to the user in the conversation.
You need to configure the agent and the connector action to meet the requirements.
What should you configure for each requirement? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.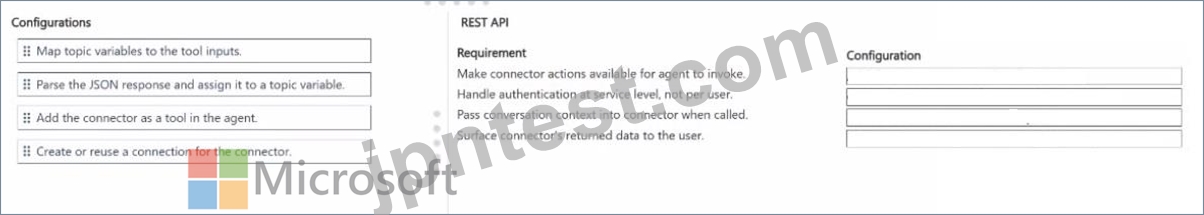
正解:
解説: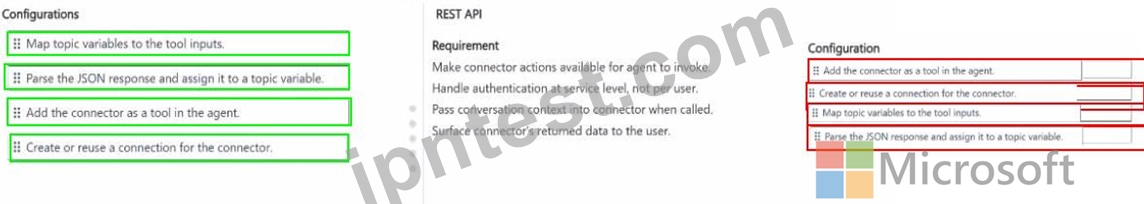
質問 # 54
Drag and Drop Question
A company is building an agent in Copilot Studio topic that must retrieve real-time status information from an external REST API using a Send HTTP request node.
To meet the business needs, the topic must meet the following requirements:
- The request must include the required authentication header.
- The request must call the endpoint using the correct HTTP method.
- The response must be configured with an appropriate response data
type based on a schema and saved so the topic can reuse the returned
values.
You need to configure the Send HTTP request node.
Which configuration should you use for each requirement? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.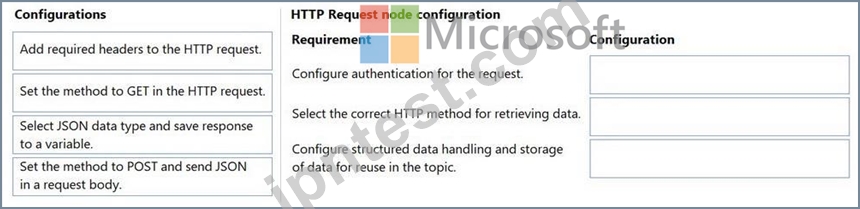
正解:
解説: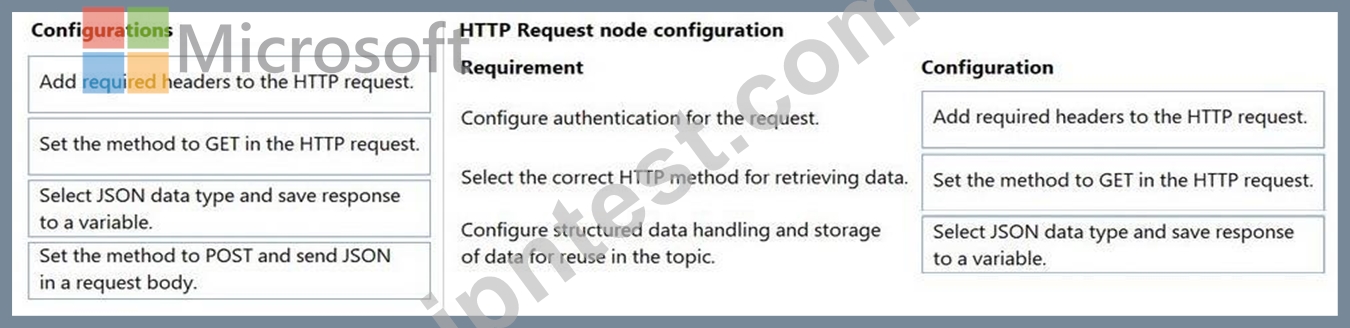
Explanation:
Box 1: Add required headers to the HTTP request
To configure the Send HTTP request node to include the required authentication header, you should add required headers to the HTTP request.
Authentication details for external REST APIs (such as API keys or Bearer tokens) are almost universally passed inside the metadata of the call, which is managed in the Headers.
Box 2: Set the method to GET in the HTTP request.
To retrieve real-time status information from an external REST API using a Send HTTP request node in Copilot Studio, you should set the method to GET in the HTTP request.
The standard HTTP GET method is specifically designed to fetch or retrieve data from a server without modifying it.
Box 3: Select JSON data type and save response to a variable
When retrieving real-time data, the primary configuration requirement is telling Copilot Studio how to interpret the incoming data (JSON) and storing it in a custom variable so subsequent nodes in your topic can use it.
Reference:
https://learn.microsoft.com/en-us/microsoft-copilot-studio/authoring-http-node
質問 # 55
......
クライアントはAB-620試験問題を学習し、テストの準備をするのに20〜30時間しかかかりません。多くの人は、AB-620テストの準備が必要だと不満を言うかもしれませんが、一方でJPNTest、仕事、学習、家族などの最も重要なことにほとんどの時間を費やさなければなりません。ただし、AB-620学習ガイドを購入すると、テストの準備に時間と労力がほとんどかからないため、最も重要なことをうまくやり、AB-620テストに簡単に合格できます。
AB-620参考資料: https://www.jpntest.com/shiken/AB-620-mondaishu