Stop wasting time on meaningless things. There are a lot wonderful things waiting for you to do. You still have the opportunities to become successful and wealthy. The Databricks-Certified-Data-Engineer-Professional study materials is a kind of intelligent learning assistant, which is capable of aiding you pass the Databricks-Certified-Data-Engineer-Professional Exam easily. As long as you have the passion to become matter and take a challenge, you will find that our Databricks-Certified-Data-Engineer-Professional practice engine can lead you to a bighter future.
| Section | Weight | Objectives |
|---|---|---|
| Data Quality and Governance | 12% | - Data Quality - Data Lineage - Governance |
| Monitoring and Troubleshooting | 16% | - Performance Optimization - Troubleshooting - Monitoring |
| Data Processing | 28% | - ETL Pipelines - Data Transformation - Structured Streaming - Spark SQL |
| Databricks Lakehouse Platform | 24% | - Lakehouse Architecture - Delta Lake - Data Management - Unity Catalog |
| Data Modeling and Storage | 20% | - Data Modeling - Storage Optimization - File Formats |
>> Databricks-Certified-Data-Engineer-Professional Pass Guarantee <<
Learning at electronic devices does go against touching the actual study. Although our Databricks-Certified-Data-Engineer-Professional exam dumps have been known as one of the world’s leading providers of Databricks-Certified-Data-Engineer-Professional exam materials. For your convenience, we especially provide several demos for future reference and we promise not to charge you of any fee for those downloading. Therefore, we welcome you to download to try our Databricks-Certified-Data-Engineer-Professional Exam. Then you will know whether it is suitable for you to use our Databricks-Certified-Data-Engineer-Professional test questions. We are sure to be at your service if you have any downloading problems.
NEW QUESTION # 212
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table: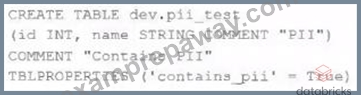
Which command allows manual confirmation that these three requirements have been met?
Answer: A
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 213
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
assert(myIntegrate(lambda x: x*x, 0, 3) [0] == 9)
Which kind of the test does the above line exemplify?
Answer: D
Explanation:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
NEW QUESTION # 214
Which statement describes the correct use of pyspark.sql.functions.broadcast?
Answer: A
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 215
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone. A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
Answer: A
Explanation:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
NEW QUESTION # 216
A data architect has heard about lake's built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.
The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability. Which piece of information is critical to this decision?
Answer: D
Explanation:
Delta Lake's time travel feature allows users to access previous versions of a table, providing a powerful tool for auditing and versioning. However, using time travel as a long-term versioning solution for auditing purposes can be less optimal in terms of cost and performance, especially as the volume of data and the number of versions grow. For maintaining a full history of valid street addresses as they appear in a customers table, using a Type 2 table (where each update creates a new record with versioning) might provide better scalability and performance by avoiding the overhead associated with accessing older versions of a large table. While Type 1 tables, where existing records are overwritten with new values, seem simpler and can leverage time travel for auditing, the critical piece of information is that time travel might not scale well in cost or latency for long-term versioning needs, making a Type 2 approach more viable for performance and scalability.
NEW QUESTION # 217
......
There has been fierce and intensified competition going on in the practice materials market. As the leading commodity of the exam, our Databricks-Certified-Data-Engineer-Professional training materials have get pressing requirements and steady demand from exam candidates all the time. So our Databricks-Certified-Data-Engineer-Professional Exam Questions have active demands than others with high passing rate of 98 to 100 percent. Don't doubt the pass rate, as long as you try our Databricks-Certified-Data-Engineer-Professional study questions, then you will find that pass the exam is as easy as pie.
Databricks-Certified-Data-Engineer-Professional Test Engine Version: https://www.examprepaway.com/Databricks/braindumps.Databricks-Certified-Data-Engineer-Professional.ete.file.html