P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by SurePassExams: https://drive.google.com/open?id=1eXYSN__GIRjYPOAaE_B8pG-yGiJm0zov
If you are still hesitating whether to select SurePassExams, you can free download part of our exam practice questions and answers from SurePassExams website to determine our reliability. If you choose to download all of our providing exam practice questions and answers, SurePassExams dare 100% guarantee that you can pass Snowflake Certification SPS-C01 Exam disposably with a high score.
| Section | Objectives |
|---|---|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Testing, Debugging, and Deployment | - Production readiness
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Data Engineering with Snowpark | - Pipeline development
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
There may be a lot of people feel that the preparation process for exams is hard and boring, and hard work does not necessarily mean good results, which is an important reason why many people are afraid of examinations. Today, our SPS-C01 exam materials will radically change this. High question hit rate makes you no longer aimless when preparing for the exam, so you just should review according to the content of our SPS-C01 Study Guide prepared for you. Instant answer feedback allows you to identify your vulnerabilities in a timely manner, so as to make up for your weaknesses. With our SPS-C01 practice quiz, you will find that the preparation process is not only relaxed and joyful, but also greatly improves the probability of passing the exam.
NEW QUESTION # 152
You are developing a Snowpark application that utilizes a UDF. You need to ensure that the UDF runs with the privileges of the caller (the user executing the query). Which of the following steps are necessary to accomplish this while creating the Snowpark session?
Answer: B
Explanation:
To ensure a UDF runs with the privileges of the caller, you need to explicitly specify the 'api_caller_identity=sf.Caller.CALLER when defining the UDF using Snowpark. This instructs Snowflake to execute the UDF with the caller's permissions. No special session configurations are needed. Option A is irrelevant for caller's identity. Option B is incorrect as it's not automatic. Option D does not exist. Option E is a valid SQL command but needs to be implemented in Python using 'session.sqr function
NEW QUESTION # 153
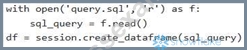
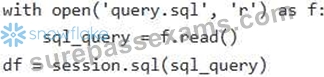
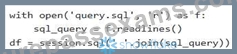
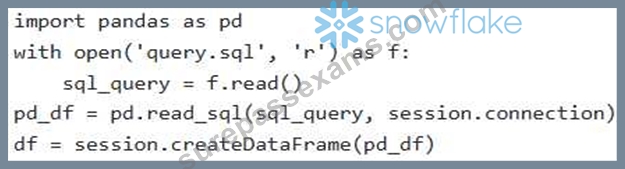
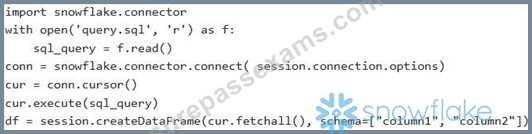
You have a SQL query stored in a file named 'query.sqr which contains several complex analytical calculations. The query depends on a Snowpark 'session' object already established. You want to create a Snowpark DataFrame from the result of this query. Which of the following code snippets achieves this with optimal performance and readability, assuming correct file access permissions?
Answer: B
Explanation:
Option A provides the most straightfomard and efficient approach. It reads the SQL query from the file and directly creates a Snowpark DataFrame using 'session.sql(sql_query)'. Option B introduces Pandas, which is unnecessary and less efficient. Option C uses the Snowflake Connector outside of Snowpark's API, which is generally not the preferred approach. Option D has a non-existent function create_dataframe' , and Option E reads lines separately requiring a join which might be erroneous.
NEW QUESTION # 154
Consider a DataFrame 'products df loaded from a SnoMlake table. It contains a 'features' column of type VARIANT, where each row contains a JSON object representing product features. Your task is to create a new DataFrame where each feature becomes a separate column. You need to dynamically extract these features without knowing the specific feature names in advance. Which of the following approaches could achieve this using Snowpark, and what considerations are important? Choose all that apply:
Answer: B,D
Explanation:
Options B and C are viable approaches. Option B: You can use the native function on the VARIANT column to extract the keys, then iterate over the returned array to dynamically create new columns. This relies on knowing the structure of the data at runtime, but doesn't require a UDE Option C: FLATTEN' offers a SQL-centric way to achieve this, which might be preferable for performance and maintainability. After flattening, you would typically pivot the data. Option A is possible with IJDFs, but might be less performant than using native functions or FLATTEN. Option D is incorrect; dynamic column creation is possible. While OBJECT_CONSTRUCT() can construct JSON objects, it's not directly helpful for dynamically extracting JSON properties into separate columns in this scenario (Option E).
NEW QUESTION # 155
You are developing a Snowpark stored procedure to process PDF files stored in a Snowflake stage. You need to extract text from these PDF files and store the extracted text in a Snowflake table. Due to security requirements, you cannot use any external packages that require internet access. Which of the following approaches can you use to accomplish this task securely and efficiently? (Select all that apply)
Answer: C,E
Explanation:
Options B and C are correct. Option B: Java UDFs allow you to leverage existing Java libraries (like PDFBox, which can be included in the UDF's JAR file) to parse PDFs securely within the Snowflake environment. Option C: Using and a pure-Python PDF parsing library (which doesn't require external network access) is another viable approach. The entire library's code must be embedded within the stored procedure. Option A is incorrect because Snowflake does not have built-in PDF parsing functions. Option D is not ideal as you are trying to avoid any external dependencies and internet access. Option E, although workable, adds an external preprocessing step which isn't the most efficient way.
NEW QUESTION # 156
You have a Snowpark DataFrame named with columns 'category', , and You want to perform the following transformations using Snowpark:





Answer: B
Explanation:
Option E is correct, because the 'pivot' operation needs to be inside 'groupBy' . It first groups the data by 'category', then pivots the data based on the 'date' column, aggregating the 'value' column using the sum function. Options A,B,C, and D, will cause a Snowflake error.
NEW QUESTION # 157
......
With the popularization of wireless network, those who are about to take part in the SPS-C01 exam guide to use APP on the mobile devices as their learning tool, because as long as entering into an online environment, they can instantly open the learning material from their appliances. Our SPS-C01 study materials provide such version for you. The online test engine is a kind of online learning, you can enjoy the advantages of APP version of our SPS-C01 Exam Guide freely. Moreover, you actually only need to download the APP online for the first time and then you can have free access to our SPS-C01 exam questions in the offline condition if you don’t clear cache.
Free SPS-C01 Download Pdf: https://www.surepassexams.com/SPS-C01-exam-bootcamp.html
What's more, part of that SurePassExams SPS-C01 dumps now are free: https://drive.google.com/open?id=1eXYSN__GIRjYPOAaE_B8pG-yGiJm0zov