2026 Latest PremiumVCEDump Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1vf6DH-ggT7Lw342OfsQCiflII7i2navC
In the complicated and changeable information age, have you ever been tried hard to find the right training materials of Professional-Machine-Learning-Engineer exam certification? We feel delighted for you to find PremiumVCEDump, and more delighted to find the reliable Professional-Machine-Learning-Engineer Exam Certification training materials. It will help you get your coveted Professional-Machine-Learning-Engineer exam certification.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Available Languages: | Japanese, English |
| Passing Score: | Not officially published, approximately 70% |
| Certificate Validity Period: | 2 years |
| Exam Price: | $200 USD (plus tax where applicable) |
| Exam Duration: | 120 minutes |
| Real Exam Qty: | 50-60 |
| Exam Format: | Multiple select, Multiple choice |
| Related Certifications: | Google Cloud Professional Cloud Architect Google Cloud Professional Data Engineer |
| Recommended Training: | Google Cloud Skills Boost - Professional Machine Learning Engineer Learning Path Official Exam Guide |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online-proctored remote exam or onsite-proctored exam at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience including 1+ year designing/managing Google Cloud solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Professional-Machine-Learning-Engineer Pdf Dumps <<
Our Professional-Machine-Learning-Engineer learning materials will help you circumvent those practice engine with low quality and help you redress the wrongs you may have and will have in the Professional-Machine-Learning-Engineer study quiz before heads. That is the reason why we make it without many sales tactics to promote our Professional-Machine-Learning-Engineer Exam Braindumps. And our Professional-Machine-Learning-Engineer training prep is regarded as the most pppular exam tool in the market and you can free download the demos to check the charming.
Google Professional Machine Learning Engineer Certification Exam is an important credential for professionals who want to demonstrate their expertise in machine learning. Professional-Machine-Learning-Engineer Exam covers a range of topics and requires significant preparation, but it is a valuable asset for professionals who want to advance their career in machine learning. With this certification, candidates can showcase their skills and knowledge to potential employers and demonstrate their ability to design and develop machine learning models on the Google Cloud Platform.
NEW QUESTION # 119
You have trained a model on a dataset that required computationally expensive preprocessing operations. You need to execute the same preprocessing at prediction time. You deployed the model on Al Platform for high-throughput online prediction. Which architecture should you use?
Answer: B
Explanation:
* Option A is incorrect because creating a new model that uses the raw data and is available in real time would require retraining the model and deploying it again, which is not efficient or scalable.
* Option B is incorrect because using a Dataflow job to transform the incoming data would introduce unnecessary latency and complexity for online prediction, which requires fast and simple processing.
* Option C is incorrect because using Cloud Spanner to stream and query the incoming data would incur high costs and overhead for online prediction, which does not need a relational database.
* Option D is correct because using a Cloud Function to preprocess the data and submit a prediction request to Al Platform is a simple and scalable solution for online prediction, which leverages the serverless and event-driven features of Cloud Functions.
NEW QUESTION # 120
You work for a rapidly growing social media company. Your team builds TensorFlow recommender models in an on-premises CPU cluster. The data contains billions of historical user events and 100 000 categorical features. You notice that as the data increases the model training time increases. You plan to move the models to Google Cloud You want to use the most scalable approach that also minimizes training time. What should you do?
Answer: C
Explanation:
TPU VMs with TPUv3 Pod slices are the most scalable and performant option for training large-scale recommender models on Google Cloud. TPUv3 Pods can provide up to 2048 cores and 32 TB of memory, and can process billions of examples and features in minutes. The TPUEmbedding API is designed to efficiently handle large-scale categorical features and embeddings, and can reduce the memory footprint and communication overhead of the model. The other options are either less scalable (B and C) or less efficient (D) for this use case.
NEW QUESTION # 121
You need to deploy a scikit-learn classification model to production. The model must be able to serve requests
24/7 and you expect millions of requests per second to the production application from 8 am to 7 pm. You need to minimize the cost of deployment What should you do?
Answer: C
Explanation:
The best option for deploying a scikit-learn classification model to production is to deploy an online Vertex AI prediction endpoint and set the max replica count to 100. This option allows you to leverage the power and scalability of Google Cloud to serve requests 24/7 and handle millions of requests per second. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained scikit-learn model to an online prediction endpoint, which can provide low-latency predictions for individual instances. An online prediction endpoint consists of one or more replicas, which are copies of the model that run on virtual machines. The max replica count is a parameter that determines the maximum number of replicas that can be created for the endpoint. By setting the max replica count to 100, you can enable the endpoint to scale up to 100 replicas when the traffic increases, and scale down to zero replicas when the traffic decreases. This can help minimize the cost of deployment, as you only pay for the resources that you use. Moreover, you can use the autoscaling algorithm option to optimize the scaling behavior of the endpoint based on the latency and utilization metrics1.
The other options are not as good as option B, for the following reasons:
* Option A: Deploying an online Vertex AI prediction endpoint and setting the max replica count to 1 would not be able to serve requests 24/7 and handle millions of requests per second. Setting the max replica count to 1 would limit the endpoint to only one replica, which can cause performance issues and service disruptions when the traffic increases. Moreover, setting the max replica count to 1 would prevent the endpoint from scaling down to zero replicas when the traffic decreases, which can increase the cost of deployment, as you pay for the resources that you do not use1.
* Option C: Deploying an online Vertex AI prediction endpoint with one GPU per replica and setting the max replica count to 1 would not be able to serve requests 24/7 and handle millions of requests per second, and would increase the cost of deployment. Adding a GPU to each replica would increase the computational power of the endpoint, but it would also increase the cost of deployment, as GPUs are more expensive than CPUs. Moreover, setting the max replica count to 1 would limit the endpoint to only one replica, which can cause performance issues and service disruptions when the traffic increases, and prevent the endpoint from scaling down to zero replicas when the traffic decreases1. Furthermore, scikit-learn models do not benefit from GPUs, as scikit-learn is not optimized for GPU acceleration2.
* Option D: Deploying an online Vertex AI prediction endpoint with one GPU per replica and setting the max replica count to 100 would be able to serve requests 24/7 and handle millions of requests per second, but it would increase the cost of deployment. Adding a GPU to each replica would increase the computational power of the endpoint, but it would also increase the cost of deployment, as GPUs are more expensive than CPUs. Setting the max replica count to 100 would enable the endpoint to scale up to 100 replicas when the traffic increases, and scale down to zero replicas when the traffic decreases, which can help minimize the cost of deployment. However, scikit-learn models do not benefit from GPUs, as scikit-learn is not optimized for GPU acceleration2. Therefore, using GPUs for scikit-learn models would be unnecessary and wasteful.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 2: Serving ML Predictions
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.1 Deploying ML models to production
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6:
Production ML Systems, Section 6.2: Serving ML Predictions
* Online prediction
* Scaling online prediction
* scikit-learn FAQ
NEW QUESTION # 122
Given the following confusion matrix for a movie classification model, what is the true class frequency for Romance and the predicted class frequency for Adventure?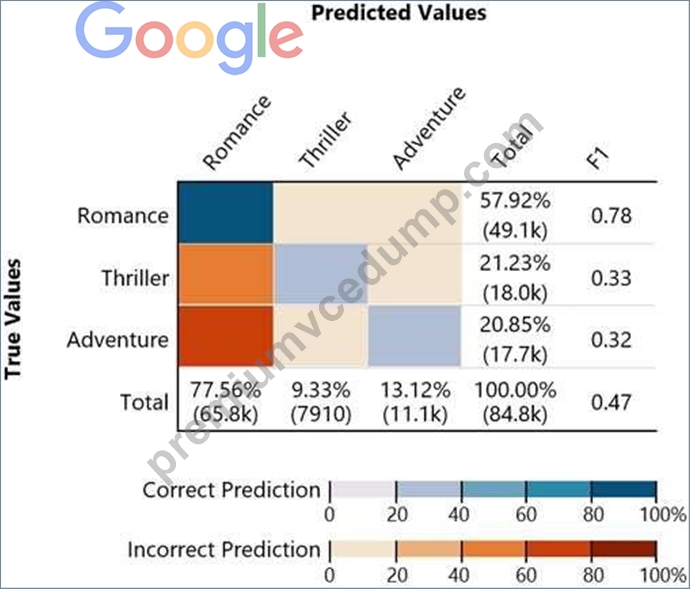
Answer: A
NEW QUESTION # 123
You are an ML engineer at an ecommerce company and have been tasked with building a model that predicts how much inventory the logistics team should order each month. Which approach should you take?
Answer: B
Explanation:
The best approach to build a model that predicts how much inventory the logistics team should order each month is to use a time series forecasting model to predict each item's monthly sales. This approach can capture the temporal patterns and trends in the sales data, such as seasonality, cyclicality, and autocorrelation.
It can also account for the variability and uncertainty in the demand, and provide confidence intervals and error metrics for the predictions. By using a time series forecasting model, you can provide the logistics team with accurate and reliable estimates of the future sales for each item, which can help them optimize the inventory levels and avoid overstocking or understocking. You can use various methods and tools to build a time series forecasting model, such as ARIMA, LSTM, Prophet, or BigQuery ML.
The other options are not optimal for the following reasons:
* A. Using a clustering algorithm to group popular items together is not a good approach, as it does not provide any quantitative or temporal information about the sales or the inventory. It only provides a qualitative and static categorization of the items based on their similarity or dissimilarity. Moreover, clustering is an unsupervised learning technique, which does not use any target variable or feedback to guide the learning process. This can result in arbitrary and inconsistent clusters, which may not reflect the true demand or preferences of the customers.
* B. Using a regression model to predict how much additional inventory should be purchased each month is not a good approach, as it does not account for the individual differences and dynamics of each item.
It only provides a single aggregated value for the whole inventory, which can be misleading and inaccurate. Moreover, a regression model is not well-suited for handling time series data, as it assumes that the data points are independent and identically distributed, which is not the case for sales data. A regression model can also suffer from overfitting or underfitting, depending on the choice and complexity of the features and the model.
* D. Using a classification model to classify inventory levels as UNDER_STOCKED, OVER_STOCKED, and CORRECTLY_STOCKED is not a good approach, as it does not provide any numerical or predictive information about the sales or the inventory. It only provides a discrete and subjective label for the inventory levels, which can be vague and ambiguous. Moreover, a classification model is not well-suited for handling time series data, as it assumes that the data points are independent and identically distributed, which is not the case for sales data. A classification model can also suffer from class imbalance, misclassification, or overfitting, depending on the choice and complexity of the features, the model, and the threshold.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Time Series Forecasting: Principles and Practice
* BigQuery ML: Time series analysis
NEW QUESTION # 124
......
Valid Professional-Machine-Learning-Engineer Exam Topics: https://www.premiumvcedump.com/Google/valid-Professional-Machine-Learning-Engineer-premium-vce-exam-dumps.html
P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by PremiumVCEDump: https://drive.google.com/open?id=1vf6DH-ggT7Lw342OfsQCiflII7i2navC