當你進入Testpdf網站,你看到每天進入Testpdf網站的人那麼多,不禁感到意外。其實這很正常的,我們Testpdf網站每天給不同的考生提供培訓資料數不勝數,他們都是利用了我們的培訓資料才順利通過考試的,說明我們的Microsoft的AI-300考試認證培訓資料真起到了作用,如果你也想購買,那就不要錯過我們Testpdf網站,你一定會非常滿意的。
| Section | Objectives |
|---|---|
| Topic 1: Design and implement an MLOps infrastructure | - Implement security, governance, and compliance for MLOps - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows |
| Topic 2: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases - Optimize inference performance, caching, and throughput |
| Topic 3: Implement generative AI quality assurance and observability | - Conduct red teaming, adversarial testing, and content filtering - Implement logging, tracing, and telemetry for GenAI applications - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates |
| Topic 4: Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks |
| Topic 5: Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Deploy models to real-time and batch endpoints - Retrain, update, and manage model versions in production - Train, register, and version models using Azure Machine Learning |
最新的Microsoft AI-300考試是最受歡迎的認證之一,很多考生都沒有信心來獲得此認證,Testpdf保證我們最新的AI-300考古題是最適合您需求和學習的題庫資料。無論您是工作比較忙的上班族,還是急需認證考試的求職者,我們的Microsoft AI-300考古題都適合您們使用,保證100%通過考試。我們還提供一年免費更新服務,一年之內,您可以獲得您所購買的AI-300更新后的新版本,這是不錯的選擇!
問題 #111
You train models on GPU-enabled clusters but deploy them on CPU-based endpoints. Recently, inference failures occur due to incompatible dependencies. What should you do to ensure consistency?
答案:D
問題 #112
An organization runs a customer-facing generative AI application built by using Microsoft Foundry. The application uses multiple prompts linked to multiple workflows to generate responses in production.
The application occasionally returns incomplete responses. The model call succeeds, but the final message sometimes stops early.
The issue cannot be reproduced reliably in development.
You need to identify where and why response generation is terminating early in production.
Which approach should you use?
答案:A
解題說明:
Enabling end-to-end tracing and logging is the most effective action to isolate this issue. Because the model call succeeds, the premature termination is likely caused by token limits, downstream application logic, or network timeouts rather than a failure in the LLM itself.
Here is how to isolate and fix the issue using tracing, along with the most likely culprits.
What to Log and Trace
To find the exact point of failure, your tracing system must capture specific metadata for every step of your production workflows:
Finish Reason: Check the finish_reason string returned in the API metadata. If it says length, the model hit a token limit. If it says stop, the model thinks it finished naturally.
Token Counts: Log completion_tokens, prompt_tokens, and total_tokens for every single prompt node.
Raw Prompt vs. Output: Capture the exact, fully rendered prompt string sent to the model, not just the template.
Workflow Node Timestamps: Log the exact entry and exit times for every workflow node to detect quiet timeouts.
Reference:
https://dev.to/utibe_okodi_339fb47a13ef5/your-ai-agent-just-failed-in-production-where-do-you-even-start-debugging-268
問題 #113
You manage an Azure Machine learning workspace. You develop a machine learning model.
You must deploy the model to use a low-priority VM with a pricing discount.
You need to deploy the model.
Which compute target should you use?
答案:A
解題說明:
The best compute target for deploying a model using low-priority VMs (or their modern successor, Spot VMs) is an Azure Machine Learning compute cluster.
Best Compute Target: AML Compute Cluster
For low-priority/Spot pricing, you should use an Azure Machine Learning compute cluster configured with the LowPriority tier.
Primary Use Case: This target is specifically recommended for batch deployments. Batch inference is ideal for low-priority VMs because these jobs are asynchronous and can tolerate the interruptions (preemptions) inherent to discounted capacity.
Pricing Advantage: Low-priority VMs offer significant discounts-often up to 80% off standard rates-by utilizing unused Azure capacity.
Automatic Handling: When a node is preempted during a batch job, Azure Machine Learning automatically attempts to replace the lost capacity and re-queues failed tasks to the cluster.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-low-priority-batch
問題 #114
Drag and Drop Question
You have a Microsoft Foundry project with a connected Azure OpenAI Service model.
You have a set of text files stored locally on your computer.
You must set up a flow that will generate responses based on the content of your local files.
You need to implement a solution.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.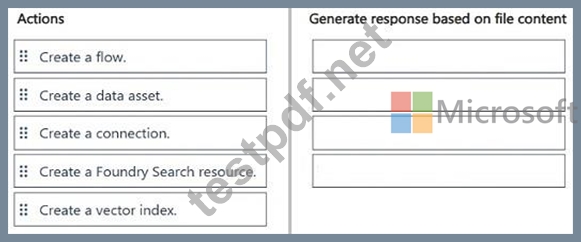
答案:
解題說明: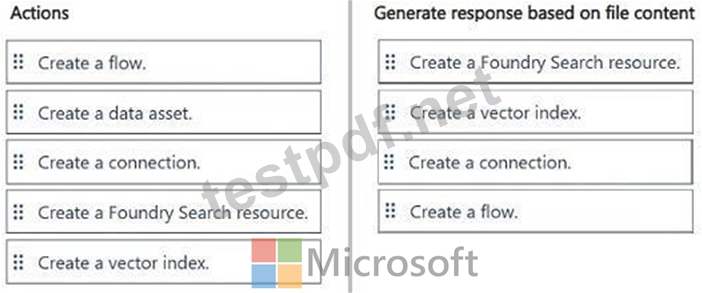
問題 #115
A team develops and manages a conversational assistant by using Microsoft Foundry.
The team must be able to validate that the assistant does not produce hateful responses before the application is exposed to any users.
You need to evaluate the model output for hateful responses as part of a repeatable validation process.
Which evaluator should you configure first?
答案:A
解題說明:
You should use the Hate and Unfairness Evaluator (a specific type of Content Safety Evaluator) in Microsoft Azure AI Foundry. This tool is designed to identify and measure the severity of hateful content toward protected groups, ensuring your assistant aligns with responsible AI standards.
Why Use the Content Safety Evaluator?
Targeted Detection: It identifies language attacking or discriminating against people based on race, religion, gender, and other identity factors.
Severity Scoring: It provides a numerical severity score (often 0-7) to help you understand the level of risk in a response.
Reasoning: It often includes a "reason" or "explanation" column that explains why a specific response was flagged.
Multilingual Support: These models are trained to work across multiple languages, including English, Spanish, French, and Japanese.
Reference:
https://arize.com/blog/evaluating-and-improving-ai-agents-at-scale-with-microsoft-foundry
問題 #116
......
想要通過AI-300認證考試並不是僅僅依靠與考試相關的書籍就可以辦到的。與其盲目地學習考試要求的相關知識,不如做一些有價值的試題。一本高效率的考古題是大家準備考試時必不可少的工具。所以,快點購買Testpdf的AI-300考古題吧。這是一本命中率很高的考古題,比其他任何學習方法都有效。这是可以保证你一次就成功的难得的资料。
最新AI-300題庫資源: https://www.testpdf.net/AI-300.html