DOWNLOAD the newest Pass4Leader DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1tzIbc0cvNPTRSiEsdn_QwzGponabVPPA
For most users, access to the relevant qualifying examinations may be the first, so many of the course content related to qualifying examinations are complex and arcane. According to these ignorant beginners, the DP-100 Exam Questions set up a series of basic course, by easy to read, with corresponding examples to explain at the same time, the Designing and Implementing a Data Science Solution on Azure study question let the user to be able to find in real life and corresponds to the actual use of learned knowledge, deepened the understanding of the users and memory. Because many users are first taking part in the exams, so for the exam and test time distribution of the above lack certain experience, and thus prone to the confusion in the examination place, time to grasp, eventually led to not finish the exam totally.
| Section | Weight | Objectives |
|---|---|---|
| Train and deploy models | 25-30% | - Monitor and maintain models
|
| Explore data and run experiments | 20-25% | - Explore and visualize data
|
| Design and prepare a machine learning solution | 20-25% | - Manage compute resources
|
| Optimize language models for AI applications | 25-30% | - Implement generative AI solutions
|
Life is short for each of us, and time is precious to us. Therefore, modern society is more and more pursuing efficient life, and our DP-100 exam materials are the product of this era, which conforms to the development trend of the whole era. It seems that we have been in a state of study and examination since we can remember, and we have experienced countless tests, including the qualification examinations we now face. In the process of job hunting, we are always asked what are the achievements and what certificates have we obtained? Therefore, we get the test Microsoft certification and obtain the qualification certificate to become a quantitative standard, and our DP-100 learning guide can help you to prove yourself the fastest in a very short period of time.
NEW QUESTION # 13
You are performing feature scaling by using the scikit-learn Python library for x.1 x2, and x3 features.
Original and scaled data is shown in the following image.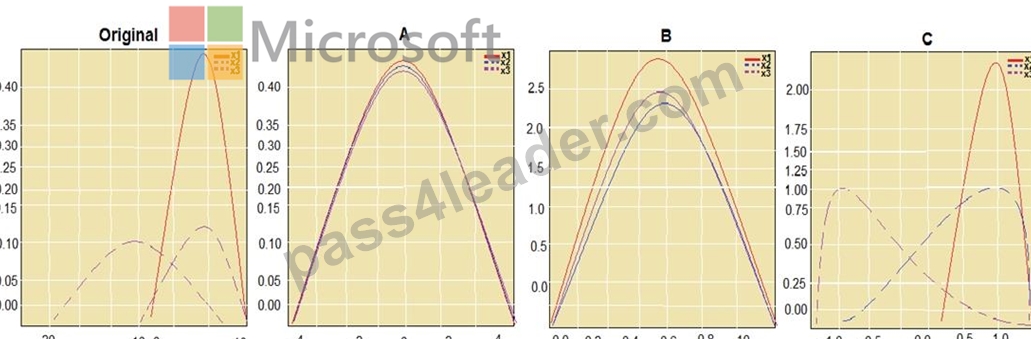
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.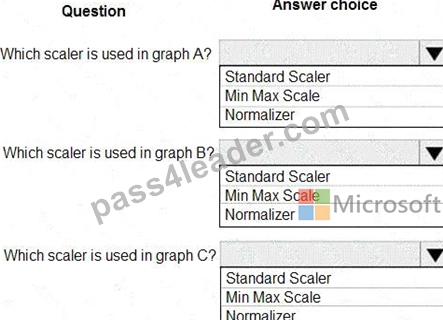
Answer:
Explanation: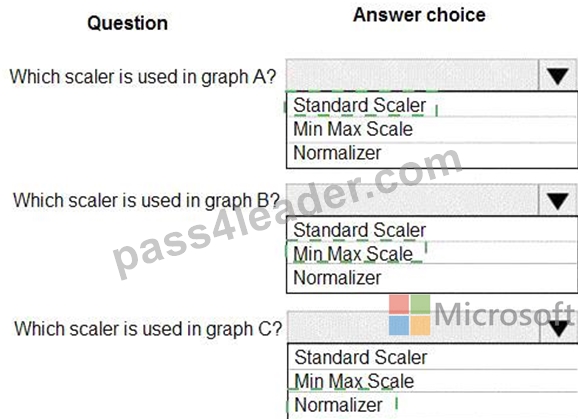
Explanation: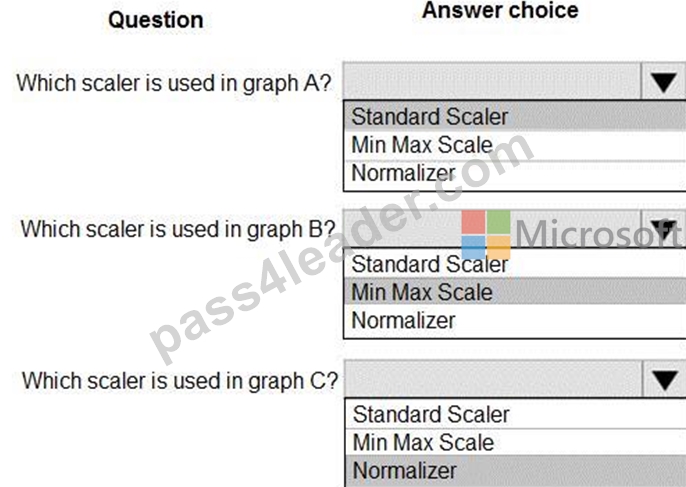
Box 1: StandardScaler
The StandardScaler assumes your data is normally distributed within each feature and will scale them such that the distribution is now centred around 0, with a standard deviation of 1.
Example: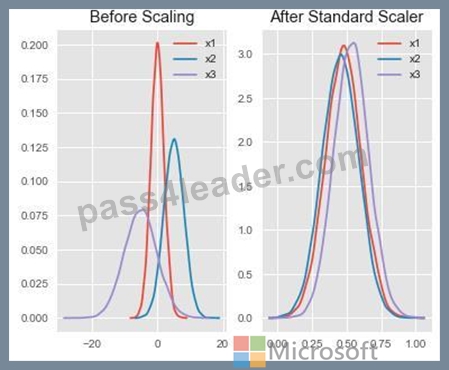
All features are now on the same scale relative to one another.
Box 2: Min Max Scaler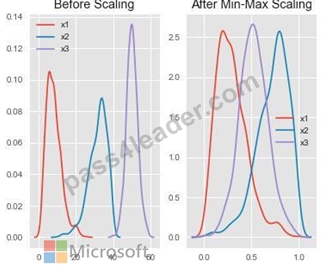
Notice that the skewness of the distribution is maintained but the 3 distributions are brought into the same scale so that they overlap.
Box 3: Normalizer
References:
http://benalexkeen.com/feature-scaling-with-scikit-learn/
NEW QUESTION # 14
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: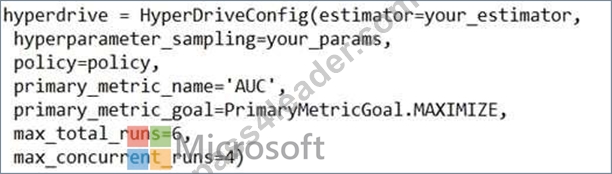
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric.
Solution: Run the following code: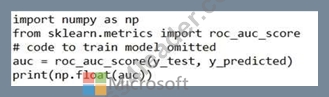
Does the solution meet the goal?
Answer: B
Explanation:
Explanation
Use a solution with logging.info(message) instead.
Note: Python printing/logging example:
logging.info(message)
Destination: Driver logs, Azure Machine Learning designer
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
NEW QUESTION # 15
You are using hyperparameter tuning in Azure Machine Learning Python SDK v2 to train a model. You configure the hyperparameter tuning experiment by running the following code: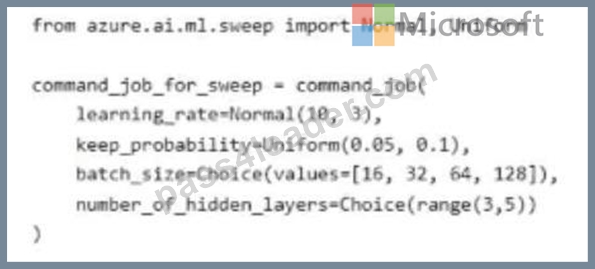
For each of the following statements select Yes if the statement is true. Otherwise, select No. NOTE: Fach correct selection is worth one paint.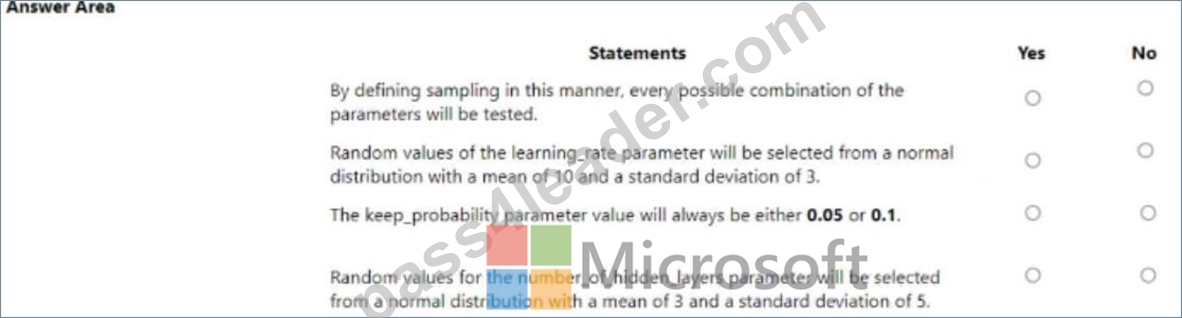
Answer:
Explanation: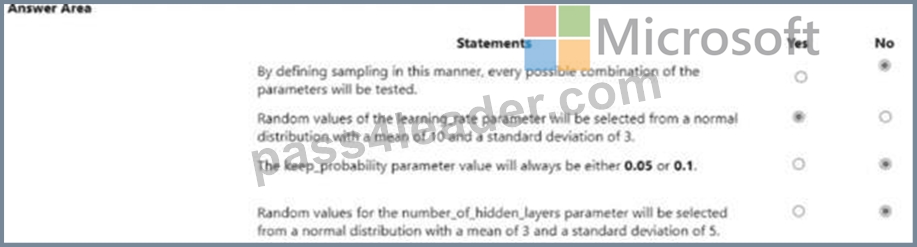
NEW QUESTION # 16
You create a binary classification model using Azure Machine Learning Studio.
You must use a Receiver Operating Characteristic (RO C) curve and an F1 score to evaluate the model.
You need to create the required business metrics.
How should you complete the experiment? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.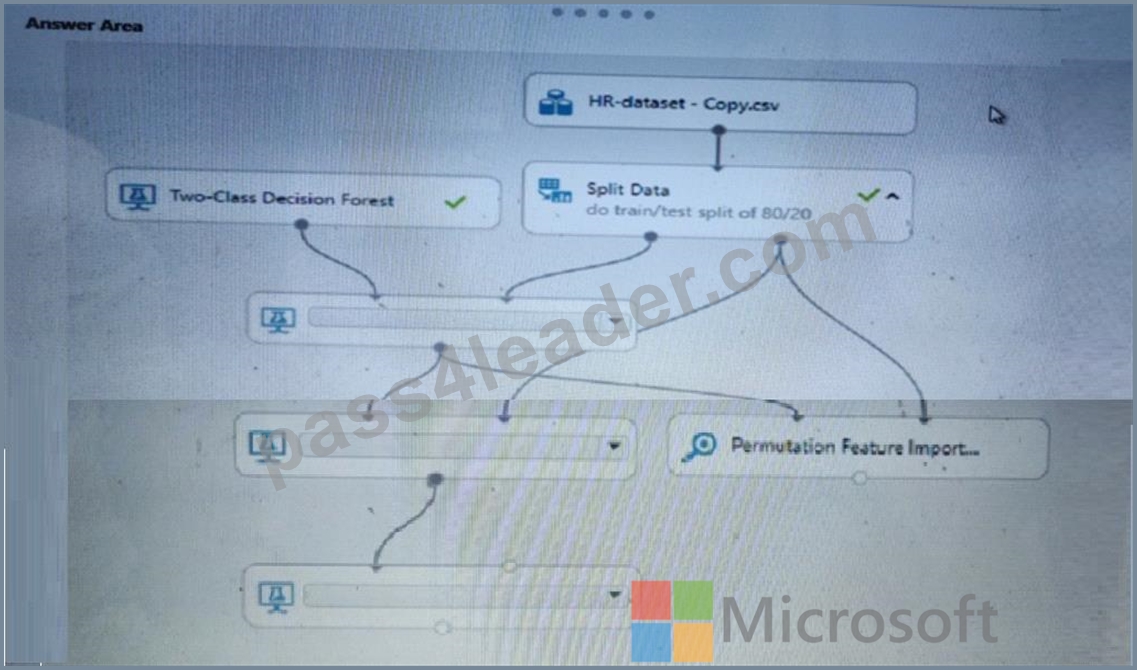
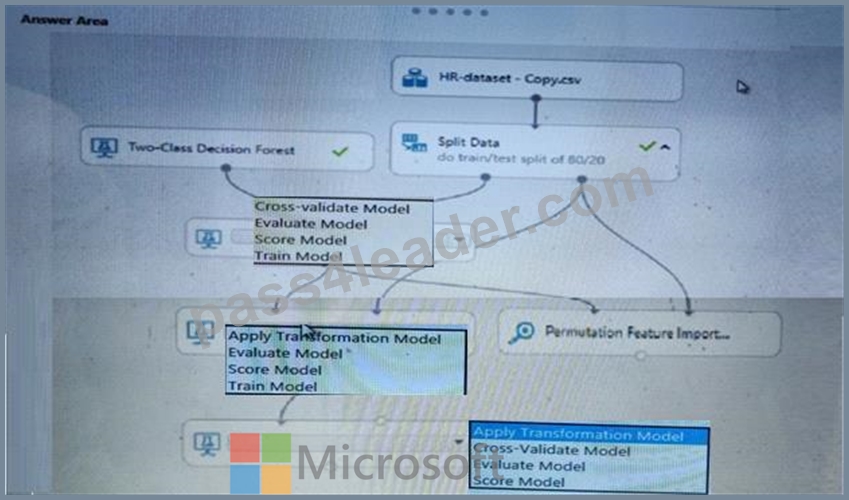
Answer:
Explanation: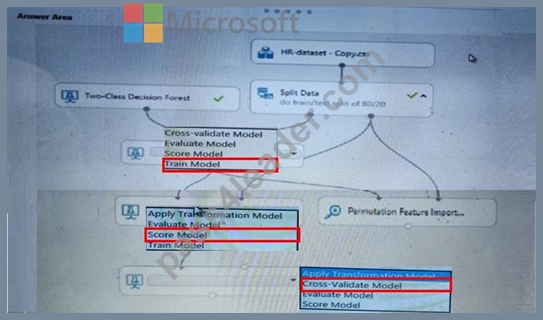
NEW QUESTION # 17
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a new experiment in Azure Machine Learning Studio.
One class has a much smaller number of observations than the other classes in the training set.
You need to select an appropriate data sampling strategy to compensate for the class imbalance.
Solution: You use the Synthetic Minority Oversampling Technique (SMOTE) sampling mode.
Does the solution meet the goal?
Answer: A
Explanation:
SMOTE is used to increase the number of underepresented cases in a dataset used for machine learning.
SMOTE is a better way of increasing the number of rare cases than simply duplicating existing cases.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
NEW QUESTION # 18
......
Through our investigation and analysis of the real problem over the years, our DP-100 learning materials can accurately predict the annual DP-100 exams. In the actual exam process, users will encounter almost half of the problem is similar in our products. Even if the syllabus is changing every year, the DP-100 Study Materials’ experts still have the ability to master propositional trends. Believe that such a high hit rate can better help users in the review process to build confidence, and finally help users through the qualification examination to obtain a certificate.
Reliable DP-100 Dumps Ebook: https://www.pass4leader.com/Microsoft/DP-100-exam.html
DOWNLOAD the newest Pass4Leader DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1tzIbc0cvNPTRSiEsdn_QwzGponabVPPA