DOWNLOAD the newest RealValidExam Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1yYi5UNOFjyWzNx2_zZ9ljbmO2_mKL5Fo
Everyone has different learning habits, Databricks-Certified-Data-Analyst-Associate exam simulation provide you with different system versions. Based on your specific situation, you can choose the version that is most suitable for you, or use multiple versions at the same time. After all, each version of Databricks-Certified-Data-Analyst-Associate Preparation questions have its own advantages. If you are very busy, you can only use some of the very fragmented time to use our Databricks-Certified-Data-Analyst-Associate study materials.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
| Exam Format: | Multiple Choice |
| Exam Price: | $200 USD |
| Real Exam Qty: | 45 |
| Exam Duration: | 90 minutes |
| Passing Score: | 70% |
| Available Languages: | English |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
| Exam Way: | Online proctored or test center proctored |
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
>> Databricks-Certified-Data-Analyst-Associate VCE Dumps <<
When you are struggling with those troublesome reference books; when you feel helpless to be productive during the process of preparing different exams (such as Databricks-Certified-Data-Analyst-Associate exam); when you have difficulty in making full use of your sporadic time and avoiding procrastination. It is time for you to realize the importance of our Databricks-Certified-Data-Analyst-Associate Test Prep, which can help you solve these annoyance and obtain a Databricks-Certified-Data-Analyst-Associate certificate in a more efficient and productive way. As long as you study with our Databricks-Certified-Data-Analyst-Associate exam questions for 20 to 30 hours, you will be confident to take and pass the Databricks-Certified-Data-Analyst-Associate exam for sure.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 11
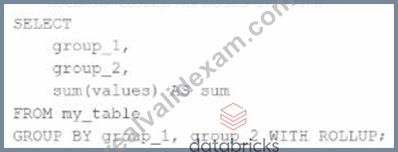
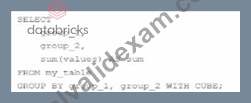
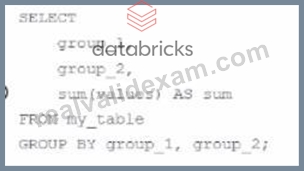
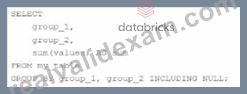
A data analyst is processing a complex aggregation on a table with zero null values and the query returns the following result:
Which query did the analyst execute in order to get this result?
Answer: D
NEW QUESTION # 12
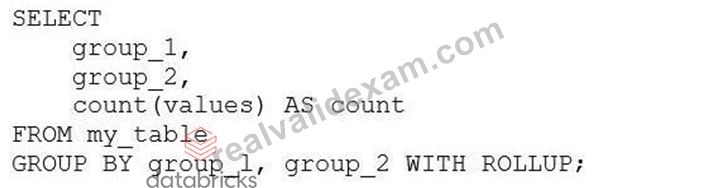
A data analyst is processing a complex aggregation on a table with zero null values and their query returns the following result:
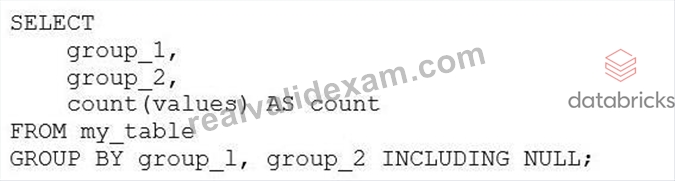
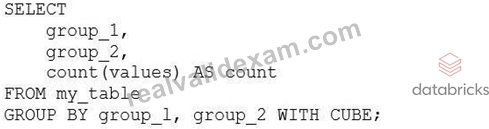
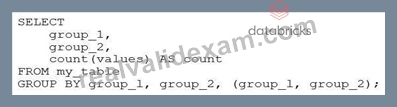
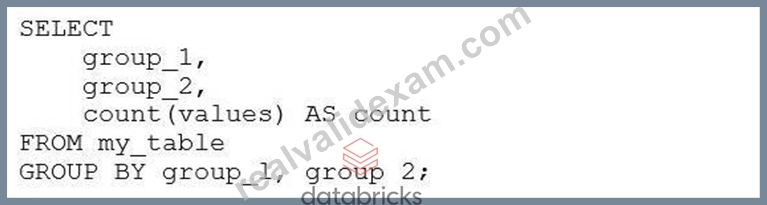
Which of the following queries did the analyst run to obtain the above result?
Answer: E
Explanation:
The result set provided shows a combination of grouping by two columns (group_1 and group_2) with subtotals for each level of grouping and a grand total. This pattern is typical of a GROUP BY ... WITH ROLLUP operation in SQL, which provides subtotal rows and a grand total row in the result set.
Considering the query options:
A) Option A: GROUP BY group_1, group_2 INCLUDING NULL - This is not a standard SQL clause and would not result in subtotals and a grand total.
B) Option B: GROUP BY group_1, group_2 WITH ROLLUP - This would create subtotals for each unique group_1, each combination of group_1 and group_2, and a grand total, which matches the result set provided.
C) Option C: GROUP BY group_1, group 2 - This is a simple GROUP BY and would not include subtotals or a grand total.
D) Option D: GROUP BY group_1, group_2, (group_1, group_2) - This syntax is not standard and would likely result in an error or be interpreted as a simple GROUP BY, not providing the subtotals and grand total.
E) Option E: GROUP BY group_1, group_2 WITH CUBE - The WITH CUBE operation produces subtotals for all combinations of the selected columns and a grand total, which is more than what is shown in the result set.
The correct answer is Option B, which uses WITH ROLLUP to generate the subtotals for each level of grouping as well as a grand total. This matches the result set where we have subtotals for each group_1, each combination of group_1 and group_2, and the grand total where both group_1 and group_2 are NULL.
NEW QUESTION # 13
A database was created in Databricks SQL using the following statement:
CREATE SCHEMA accounting LOCATION ' dbfs:/accounting/data ' ;
Where will data for this database be stored?
Answer: B
Explanation:
Option B is correct. The statement explicitly sets the schema/database location to dbfs:/accounting/data. In Databricks SQL, CREATE SCHEMA supports a LOCATION schema_directory, and the documentation explains that the schema directory is the filesystem path where the schema is created. Because the user supplied LOCATION ' dbfs:/accounting/data ' , Databricks uses that path instead of the default warehouse directory. Option D would apply only when no custom location is supplied. References: Databricks CREATE SCHEMA documentation.
NEW QUESTION # 14
In which of the following situations will the mean value and median value of variable be meaningfully different?
Answer: E
Explanation:
The mean value of a variable is the average of all the values in a data set, calculated by dividing the sum of the values by the number of values. The median value of a variable is the middle value of the ordered data set, or the average of the middle two values if the data set has an even number of values. The mean value is sensitive to outliers, which are values that are very different from the rest of the data. Outliers can skew the mean value and make it less representative of the central tendency of the data. The median value is more robust to outliers, as it only depends on the middle values of the data. Therefore, when the variable contains a lot of extreme outliers, the mean value and the median value will be meaningfully different, as the mean value will be pulled towards the outliers, while the median value will remain close to the majority of the data1. Reference: Difference Between Mean and Median in Statistics (With Example) - BYJU'S
NEW QUESTION # 15
In which of the following situations should a data analyst use higher-order functions?
Answer: E
Explanation:
Higher-order functions are a simple extension to SQL to manipulate nested data such as arrays. A higher- order function takes an array, implements how the array is processed, and what the result of the computation will be. It delegates to a lambda function how to process each item in the array. This allows you to define functions that manipulate arrays in SQL, without having to unpack and repack them, use UDFs, or rely on limited built-in functions. Higher-order functions provide a performance benefit over user defined functions. References: Higher-order functions | Databricks on AWS, Working with Nested Data Using Higher Order Functions in SQL on Databricks | Databricks Blog, Higher-order functions - Azure Databricks | Microsoft Learn, Optimization recommendations on Databricks | Databricks on AWS
NEW QUESTION # 16
......
Databricks-Certified-Data-Analyst-Associate Latest Exam Dumps: https://www.realvalidexam.com/Databricks-Certified-Data-Analyst-Associate-real-exam-dumps.html
DOWNLOAD the newest RealValidExam Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1yYi5UNOFjyWzNx2_zZ9ljbmO2_mKL5Fo