BONUS!!! PassTest dbt-Analytics-Engineeringダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1L0RPOvO2G9jEgyQIetnJnZPH6bhSi1Oq
IT業界の中でたくさんの野心的な専門家がいって、IT業界の中でより一層頂上まで一歩更に近く立ちたくてdbt Labsのdbt-Analytics-Engineering試験に参加して認可を得たくて、dbt Labs のdbt-Analytics-Engineering試験が難度の高いので合格率も比較的低いです。dbt Labsのdbt-Analytics-Engineering試験を申し込むのは賢明な選択で今のは競争の激しいIT業界では、絶えず自分を高めるべきです。しかし多くの選択肢があるので君はきっと悩んでいましょう。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: External Dependencies | 10% | - Using packages - External sources integration - Managing snapshots |
| Topic 2: Managing Data Pipelines | 15% | - CI/CD integration - Deployment strategies - Pipeline orchestration |
| Topic 3: Implementing dbt Tests | 10% | - Custom tests - Built-in tests - Test configuration and execution |
| Topic 4: Developing dbt Models | 20% | - Model optimization
|
| Topic 5: Debugging and Error Resolution | 15% | - Identifying modeling errors - Resolving data quality issues - Debugging techniques |
| Topic 6: dbt Models Governance | 15% | - Project organization and structure - Version control integration - Naming conventions and standards |
| Topic 7: Leveraging dbt State | 5% | - State management - State-aware operations |
| Topic 8: Creating and Maintaining Documentation | 10% | - Descriptions and metadata - Generating documentation - Documentation standards |
>> dbt-Analytics-Engineering日本語版問題集 <<
dbt-Analytics-Engineering試験に参加する前に、試験を知りたい場合、弊社の公式サイトを訪問できます。そして、弊社のdbt-Analytics-Engineering試験ガイドのデモをダウンロードすることは簡単で、便利です。クリックするだけ必要からです。後、弊社のdbt-Analytics-Engineering資料はすべてdbt-Analytics-Engineering試験に関わることがわかります。dbt-Analytics-Engineering資料の全てのページはdbt-Analytics-Engineering試験に関連しています。dbt-Analytics-Engineering資料は素晴らしいものです。
質問 # 58
A new dbt model is created directly in the development environment without a corresponding raw data source. Which of these can be potential ramifications of this approach?
正解:D
解説:
A: Direct development modeling risks bypassing important raw data checks. B: Data lineage becomes unclear and could lead to misinterpretations. C: Without a reliable source, fixing issues or adapting the model becomes harder
質問 # 59
You want to host your dbt project documentation on an internal company server that's behind a firewall. Which approach would be best suited for this scenario?
正解:C
解説:
Uploading the static files (HTML, CSS, JavaScript) to your internal server provides a straightforward way to host the documentation behind a firewall.
質問 # 60
Examine how freshness is defined at the database level:
- name: raw
database: raw
freshness: # default freshness
warn_after: {count: 12, period: hour}
error_after: {count: 24, period: hour}
loaded_at_field: _etl_loaded_at
How can one table from the source raw be excluded from source freshness?
正解:D
解説:
In dbt, source freshness can be defined at the source level (affecting all tables) or overridden at the individual table level. When freshness is declared at the source root, dbt applies the freshness policy to every table within that source unless a specific table opts out. The official dbt documentation states that setting:
freshness: null
at the table level disables freshness checks for that specific table, even when the source itself defines default freshness rules. This is the only documented way to exclude an individual table from a source freshness policy.
Option B is incorrect because tables can override and disable freshness even when the parent source defines it. dbt's configuration hierarchy supports overriding child-level settings on a per-resource basis.
Option C (loaded_at_field: null) does not disable freshness-it simply removes the loaded_at_field, which would cause dbt to error because a freshness check requires a timestamp field to operate.
Option D (error_after: null) only removes the error threshold but does not disable freshness. The table would still participate in freshness checks and could trigger warnings.
Thus, the correct and dbt-supported method to exclude a table from freshness is to explicitly set:
freshness: null
making A the correct answer.
質問 # 61
Choose a correct command for each statement.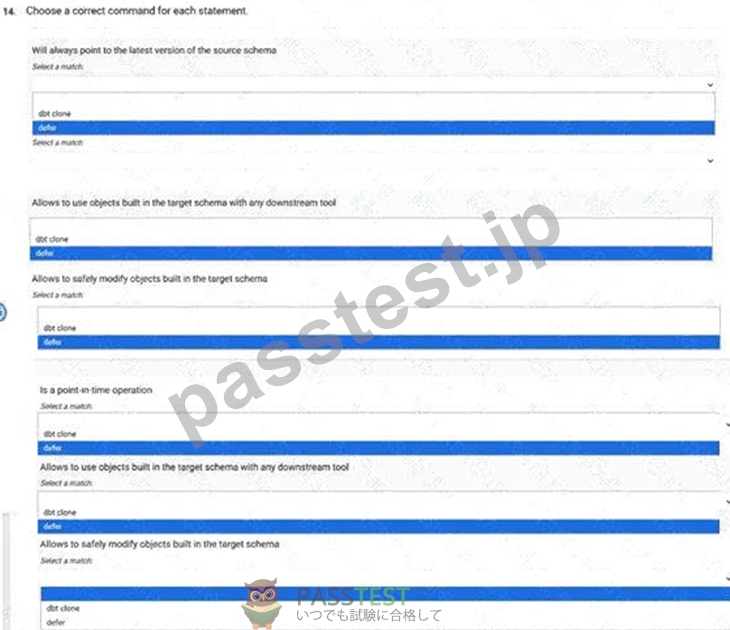
正解:
解説: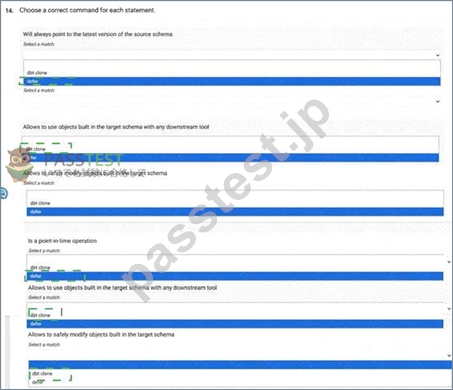
Explanation:
Will always point to the latest version of the source schema
Correct Match: # defer
Allows to use objects built in the target schema with any downstream tool Correct Match: # dbt clone
3## Allows to safely modify objects built in the target schema
Correct Match: # defer
4## Is a point-in-time operation
Correct Match: # dbt clone
defer and dbt clone serve very different purposes in dbt, and understanding their behavior is essential for choosing the right command.
The --defer flag tells dbt to use already-built objects from a previous environment (often production) instead of rebuilding them. Because it always references the existing target schema's most recent objects, it "always points to the latest version of the source schema." Since no objects are overwritten when using defer, it also
"allows safely modifying objects built in the target schema"-your development environment uses production objects without altering them.
By contrast, dbt clone creates a point-in-time copy of existing relations. This cloned schema is static; it does not auto-update when source data changes. Therefore, clone is classified as a "point-in-time operation." Since clone copies physical tables/views into a new schema, downstream tools (BI dashboards, ML pipelines) can safely query the cloned environment without affecting production, making "allows to use objects built in the target schema with any downstream tool" the correct match.
Thus, defer is used for logic substitution without copies, while clone is used for replicable, point-in-time snapshots.
質問 # 62
You want to write a custom test to check for potential anomalies in a time-series dataset. Which of the following would be the MOST important considerations when designing this test?
正解:B、C、D
解説:
The test logic itself depends on a deep understanding of your data and what 'unusual' behavior looks like. Integration with documentation (D) is secondary.
質問 # 63
......
当社PassTestのすべてのdbt-Analytics-Engineeringトレーニングファイルは、この分野の専門家と教授によって設計されています。教材の品質は保証されています。すべての顧客の実際の状況に応じて、すべての顧客に適した学習計画を作成します。当社からdbt-Analytics-Engineering学習教材を購入する場合、dbt-Analytics-Engineering試験に簡単に合格するための専門的なトレーニングを受けることをお約束します。専門的なトレーニングにより、dbt-Analytics-Engineering試験に合格し、関連する認定資格を最短で取得します。
dbt-Analytics-Engineering資格トレーリング: https://www.passtest.jp/dbt-Labs/dbt-Analytics-Engineering-shiken.html
P.S.PassTestがGoogle Driveで共有している無料の2026 dbt Labs dbt-Analytics-Engineeringダンプ:https://drive.google.com/open?id=1L0RPOvO2G9jEgyQIetnJnZPH6bhSi1Oq