BONUS!!! Download part of Pass4SureQuiz Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1aff6e9meRBcfxlssa35s1dVT4QnAeggG
When people take the subway staring blankly, you can use Pad or cell phone to see the PDF version of the Databricks-Generative-AI-Engineer-Associate study materials. While others are playing games online, you can do online Databricks-Generative-AI-Engineer-Associate exam questions. We are sure that as you hard as you are, you can Pass Databricks-Generative-AI-Engineer-Associate Exam easily in a very short time. While others are surprised at your achievement, you might have found a better job.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Exam Price: | USD 200 |
| Available Languages: | English |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 90 minutes |
| Real Exam Qty: | 45-60 |
| Exam Format: | Multiple select, Multiple choice |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Recommended Training: | Mosaic AI Documentation Databricks Academy - Generative AI Courses |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Latest Databricks-Generative-AI-Engineer-Associate Dumps Questions <<
Research indicates that the success of our highly-praised Databricks-Generative-AI-Engineer-Associate test questions owes to our endless efforts for the easily operated practice system. Most feedback received from our candidates tell the truth that our Databricks-Generative-AI-Engineer-Associate guide torrent implement good practices, systems as well as strengthen our ability to launch newer and more competitive products. Accompanying with our Databricks-Generative-AI-Engineer-Associate Exam Dumps, we educate our candidates with less complicated Q&A but more essential information, which in a way makes you acquire more knowledge and enhance your self-cultivation to pass the Databricks-Generative-AI-Engineer-Associate exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 88
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint's incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
Answer: C
Explanation:
Problem Context: The goal is to monitor theserving endpointfor incoming requests and outgoing responses in aprovisioned throughput model serving endpointwithin aRetrieval-Augmented Generation (RAG) application. The current approach involves using a microservice to log requests and responses to a remote server, but the Generative AI Engineer is looking for a more streamlined solution within Databricks.
Explanation of Options:
* Option A: Vector Search: This feature is used to perform similarity searches within vector databases.
It doesn't provide functionality for logging or monitoring requests and responses in a serving endpoint, so it's not applicable here.
* Option B: Lakeview: Lakeview is not a feature relevant to monitoring or logging request-response cycles for serving endpoints. It might be more related to viewing data in Databricks Lakehouse but doesn't fulfill the specific monitoring requirement.
* Option C: DBSQL: Databricks SQL (DBSQL) is used for running SQL queries on data stored in Databricks, primarily for analytics purposes. It doesn't provide the direct functionality needed to monitor requests and responses in real-time for an inference endpoint.
* Option D: Inference Tables: This is the correct answer.Inference Tablesin Databricks are designed to store the results and metadata of inference runs. This allows the system to logincoming requests and outgoing responsesdirectly within Databricks, making it an ideal choice for monitoring the behavior of a provisioned serving endpoint. Inference Tables can be queried and analyzed, enabling easier monitoring and debugging compared to a custom microservice.
Thus,Inference Tablesare the optimal feature for monitoring request and response logs within the Databricks infrastructure for a model serving endpoint.
NEW QUESTION # 89
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
Answer: D
Explanation:
Context: Deploying an application that uses an MLflow Pyfunc model involves managing sensitive information such as secrets and credentials securely.
Explanation of Options:
* Option A: Use spark.conf.set(): While this method can pass configurations within Spark jobs, using it for secrets is not recommended because it may expose them in logs or Spark UI.
* Option B: Pass variables using the Databricks Feature Store API: The Feature Store API is designed for managing features for machine learning, not for handling secrets or credentials.
* Option C: Add credentials using environment variables: This is a common practice for managing credentials in a secure manner, as environment variables can be accessed securely by applications without exposing them in the codebase.
* Option D: Pass the secrets in plain text: This is highly insecure and not recommended, as it exposes sensitive information directly in the code.
Therefore,Option Cis the best method for securely passing secrets and credentials to an application, protecting them from exposure.
NEW QUESTION # 90
A Generative AI Engineer I using the code below to test setting up a vector store: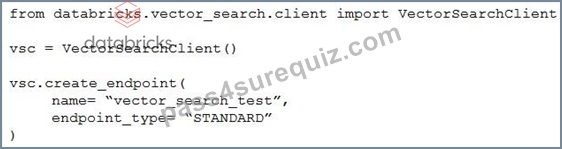
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: B
Explanation:
* Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
* Explanation of Options:
Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B.
NEW QUESTION # 91
A Generative Al Engineer is building a production-ready LLM system which replies directly to customers.
The solution makes use of the Foundation Model API via provisioned throughput. They are concerned that the LLM could potentially respond in a toxic or otherwise unsafe way. They also wish to perform this with the least amount of effort.
Which approach will do this?
Answer: A
Explanation:
The task is to prevent toxic or unsafe responses in an LLM system using the Foundation Model API with minimal effort. Let's assess the options.
* Option A: Host Llama Guard on Foundation Model API and use it to detect unsafe responses
* Llama Guard is a safety-focused model designed to detect toxic or unsafe content. Hosting it via the Foundation Model API (a Databricks service) integrates seamlessly with the existing system, requiring minimal setup (just deployment and a check step), and leverages provisioned throughput for performance.
* Databricks Reference:"Foundation Model API supports hosting safety models like Llama Guard to filter outputs efficiently"("Foundation Model API Documentation," 2023).
* Option B: Add some LLM calls to their chain to detect unsafe content before returning text
* Using additional LLM calls (e.g., prompting an LLM to classify toxicity) increases latency, complexity, and effort (crafting prompts, chaining logic), and lacks the specificity of a dedicated safety model.
* Databricks Reference:"Ad-hoc LLM checks are less efficient than purpose-built safety solutions" ("Building LLM Applications with Databricks").
* Option C: Add a regex expression on inputs and outputs to detect unsafe responses
* Regex can catch simple patterns (e.g., profanity) but fails for nuanced toxicity (e.g., sarcasm, context-dependent harm), requiring significant manual effort to maintain and update rules.
* Databricks Reference:"Regex-based filtering is limited for complex safety needs"("Generative AI Cookbook").
* Option D: Ask users to report unsafe responses
* User reporting is reactive, not preventive, and places burden on users rather than the system. It doesn't limit unsafe outputs proactively and requires additional effort for feedback handling.
* Databricks Reference:"Proactive guardrails are preferred over user-driven monitoring" ("Databricks Generative AI Engineer Guide").
Conclusion: Option A (Llama Guard on Foundation Model API) is the least-effort, most effective approach, leveraging Databricks' infrastructure for seamless safety integration.
NEW QUESTION # 92
A Generative Al Engineer is building a system which will answer questions on latest stock news articles.
Which will NOT help with ensuring the outputs are relevant to financial news?
Answer: B
Explanation:
In the context of ensuring that outputs are relevant to financial news, increasing compute power (option B) does not directly improve therelevanceof the LLM-generated outputs. Here's why:
* Compute Power and Relevancy:Increasing compute power can help the model process inputs faster, but it does not inherentlyimprove therelevanceof the answers. Relevancy depends on the data sources, the retrieval method, and the filtering mechanisms in place, not on how quickly the model processes the query.
* What Actually Helps with Relevance:Other methods, like content filtering, guardrails, or manual review, can directly impact the relevance of the model's responses by ensuring the model focuses on pertinent financial content. These methods help tailor the LLM's responses to the financial domain and avoid irrelevant or harmful outputs.
* Why Other Options Are More Relevant:
* A (Comprehensive Guardrail Framework): This will ensure that the model avoids generating content that is irrelevant or inappropriate in the finance sector.
* C (Profanity Filter): While not directly related to financial relevancy, ensuring the output is clean and professional is still important in maintaining the quality of responses.
* D (Manual Review): Incorporating human oversight to catch and correct issues with the LLM's output ensures the final answers are aligned with financial content expectations.
Thus, increasing compute power does not help with ensuring the outputs are more relevant to financial news, making option B the correct answer.
NEW QUESTION # 93
......
Databricks-Generative-AI-Engineer-Associate Exam Objectives Pdf: https://www.pass4surequiz.com/Databricks-Generative-AI-Engineer-Associate-exam-quiz.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Pass4SureQuiz: https://drive.google.com/open?id=1aff6e9meRBcfxlssa35s1dVT4QnAeggG