Passing the DP-750 exam is your best career opportunity. The rich experience with relevant certificates is important for enterprises to open up a series of professional vacancies for your choices. Our website's DP-750 learning quiz bank and learning materials look up the Latest DP-750 Questions and answers based on the topics you choose. This choice will serve as a breakthrough of your entire career, so prepared to be amazed by high quality and accuracy rate of our DP-750 study guide.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data ingestion
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
The experts in our company have been focusing on the DP-750 examination for a long time and they never overlook any new knowledge. The content of our DP-750 study materials has always been kept up to date. Don't worry if any new information comes out after your purchase of our DP-750 Study Guide. We will inform you by E-mail when we have a new version. We can ensure you a pass rate as high as 99%. If you don't pass the DP-750 exam, you will get a refund. Why not study and practice for just 20 to 30 hours and then pass the examination?
NEW QUESTION # 16
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: B
Explanation:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark's filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn't rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=['order_amount']) produce identical results.
The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 17
You need to recommend a compute type for the production ingestion workloads and BI workloads. The solution must meet the environment and compute requirements.
What should you recommend for each type of workload? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.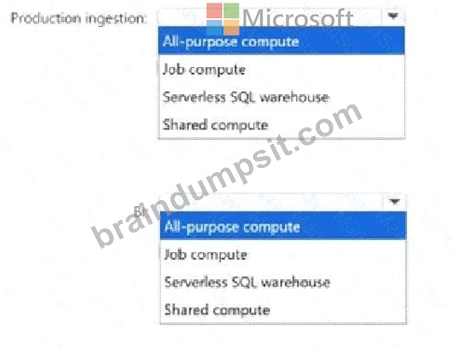
Answer:
Explanation: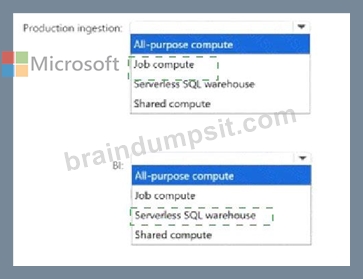
Explanation:
Production ingestion: Job compute
BI: Serverless SQL warehouse
Job compute is designed for automated production workloads executed through Lakeflow Jobs. Its lifecycle can be tied to the job run, providing workload isolation and avoiding the cost of maintaining an interactive all- purpose cluster continuously. It is therefore appropriate for scheduled ingestion and transformation processing. A serverless SQL warehouse is designed for BI and Databricks SQL workloads. It provides rapid startup, automatic infrastructure management, scaling, and optimized SQL-query execution for dashboards and reporting tools. All-purpose compute is intended primarily for interactive notebook development and exploration, while shared compute does not provide the same job-specific isolation or SQL-serving experience. Consequently, job compute should support production ingestion, and a serverless SQL warehouse should serve the BI workload.
NEW QUESTION # 18
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.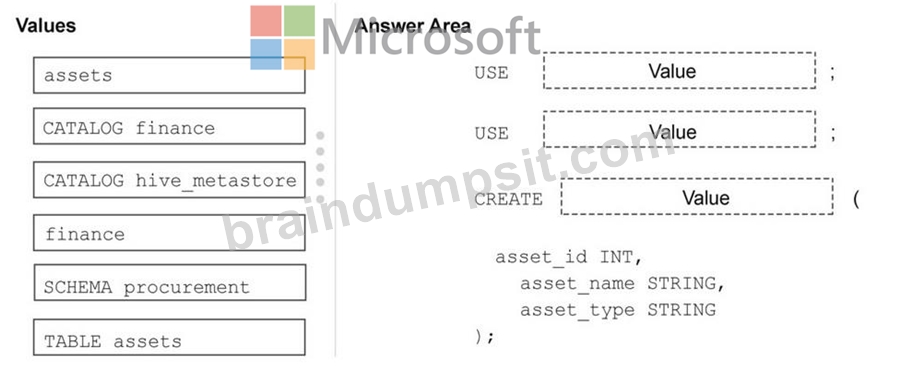
Answer:
Explanation: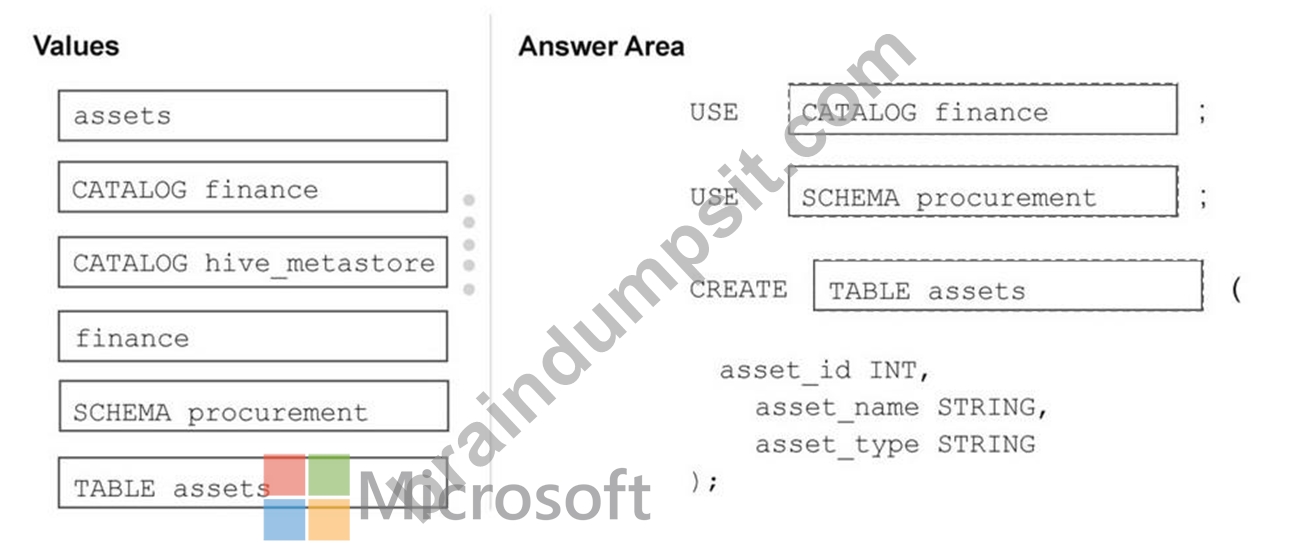
NEW QUESTION # 19
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
* Ensure that authentication does NOT require storing credentials in Databricks
* Ensure that users can access the files, but NOT modify the files.
* Follow the principle of least privilege
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.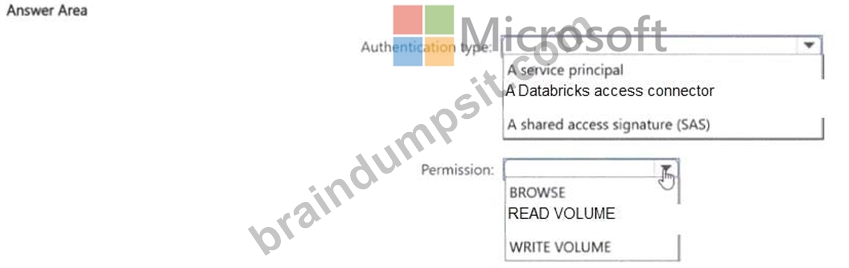
Answer:
Explanation: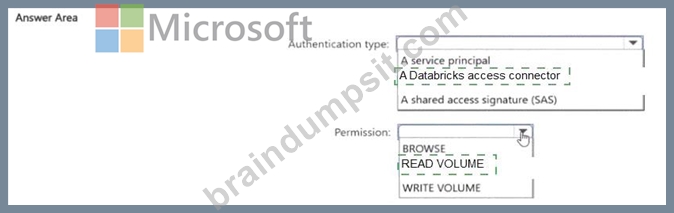
Explanation:
For authentication, a Managed Identity (via a Databricks Access Connector) is the right choice. The Access Connector wraps an Azure-managed identity so Databricks can authenticate to Azure Storage without any credentials being stored in the workspace. The cloud security team controls the identity through Azure RBAC
- there are no secrets to rotate or leak inside Databricks.
For the permission, READ FILES on the volume is exactly right. It allows users to read and list files through the volume path while blocking writes, deletes, and modifications. This is the minimum necessary access, honouring the principle of least privilege.
WRITE FILES would allow modifications, contradicting 'users can access but NOT modify.' ALL PRIVILEGES grants far more than needed. Service principals with stored client secrets would mean credentials inside Databricks, violating the 'does not require storing credentials' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/volumes
NEW QUESTION # 20
Hotspot Question
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out-of-memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.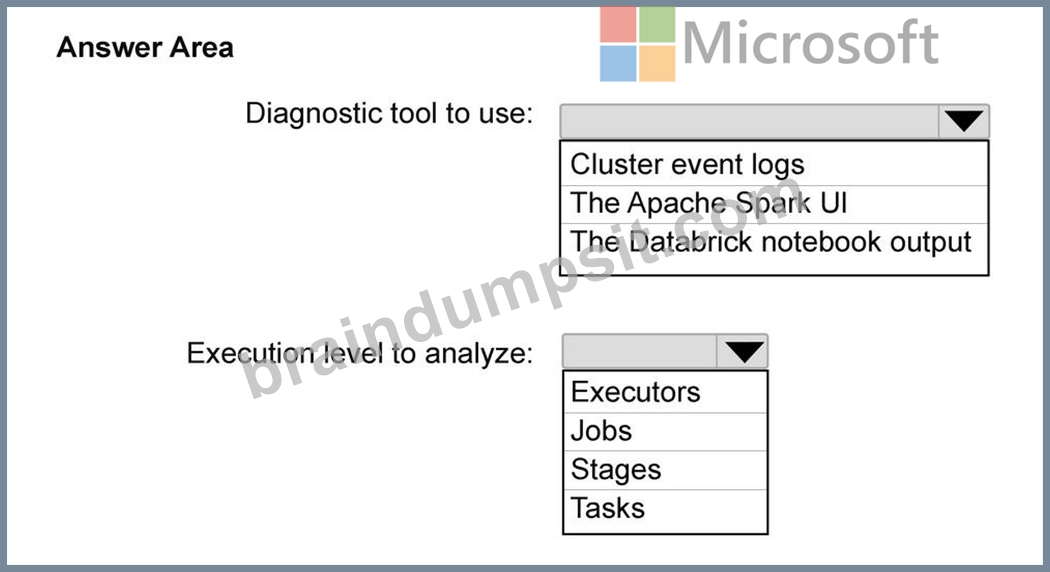
Answer:
Explanation: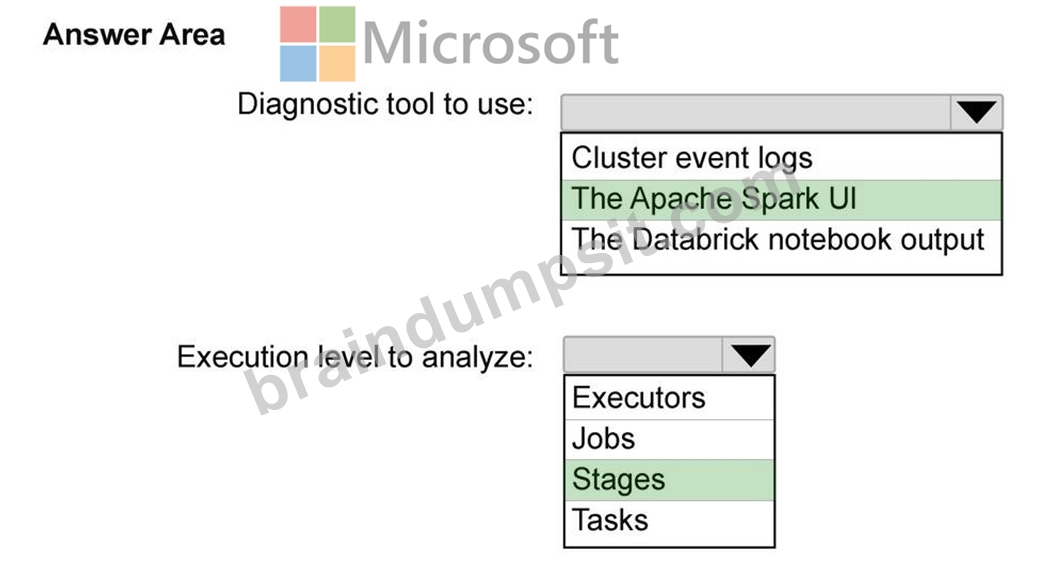
NEW QUESTION # 21
......
Differ as a result the DP-750 questions torrent geared to the needs of the user level, cultural level is uneven, have a plenty of college students in school, have a plenty of work for workers, and even some low education level of people laid off, so in order to adapt to different level differences in users, the DP-750 Exam Questions at the time of writing teaching materials with a special focus on the text information expression, so you can understand the content of the DP-750 learning guide and pass the DP-750 exam easily.
DP-750 Examcollection Free Dumps: https://www.braindumpsit.com/DP-750_real-exam.html