BTW, DOWNLOAD part of Real4dumps AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1diSSFovkBkr4h2jsHLLJj1sR6S7jNHML
Our AI-300 exam materials are famous among candidates. Once they need to prepare an exam, our AI-300 study materials are their first choice. As you know, it is troublesome to get the AI-300certificate. Now, you are fortunate enough to come across our AI-300 Exam Guide. We have free demos on the website for our customers to download if you still doubt our products, and you can check whether it is the right one for you before purchase as well.
| Section | Objectives |
|---|---|
| Topic 1: Implement generative AI quality assurance and observability | - Conduct red teaming, adversarial testing, and content filtering - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates - Implement logging, tracing, and telemetry for GenAI applications |
| Topic 2: Design and implement a GenAIOps infrastructure | - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Manage API keys, rate limits, and responsible AI guardrails |
| Topic 3: Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production |
| Topic 4: Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries |
| Topic 5: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Optimize inference performance, caching, and throughput - Fine-tune and distill models for specific use cases - Implement cost management and scaling strategies for GenAI workloads |
>> AI-300 Latest Braindumps Free <<
AI-300 practice materials can expedite your review process, inculcate your knowledge of the exam and last but not the least, speed up your pace of review dramatically. The finicky points can be solved effectively by using our AI-300 practice materials. Some practice materials keep droning on the useless points of knowledge. In contrast, being venerated for high quality and accuracy rate, our AI-300 practice materials received high reputation for their efficiency and accuracy rate originating from your interests, and the whole review process may cushier than you have imagined before.
NEW QUESTION # 104
A team is experimenting with traditional models for a classification workflow in Azure Machine Learning.
The team requires a consistent way to manage assets that are created during experimentation.
You need to ensure that artifacts can be reused and governed across projects.
Which asset should you register?
Answer: A
Explanation:
In an Azure Machine Learning classification workflow, you should register Models.
Registration creates a versioned asset in your workspace or a centralized registry, which is essential for ensuring that artifacts are reusable, governed, and trackable across different projects and environments.
Key Assets for Reuse and Governance
To maintain a consistent and governed workflow, you should focus on registering these specific assets:
Models: The primary artifact. Registering a model allows you to track its lineage (which experiment created it), version it, and deploy it consistently across environments.
Components: These are self-contained pieces of code that perform specific steps in a pipeline (e.g., data cleaning, training). Registering them allows different teams to reuse the same
"traditional" classification logic without rewriting code.
Environments: Encapsulates the software dependencies (Python packages, Docker images) required for your model to run. Registering these ensures reproducibility across different compute targets.
Data Assets: Registering your training and testing datasets as versioned assets ensures that you can always audit exactly what data was used to train a specific model version.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-azure-machine-learning-v2
NEW QUESTION # 105
Hotspot Question
You manage a Microsoft Foundry project. You build a solution that uses a set of PDF documents.
You require two large language models (LLMs):
- An embedding model must help categorize the documents.
- A general-purpose model must generate semantically and contextually
accurate output based on the documents.
You need to select benchmarks to observe the quality of the models.
Which metrics should you use for the benchmarks? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.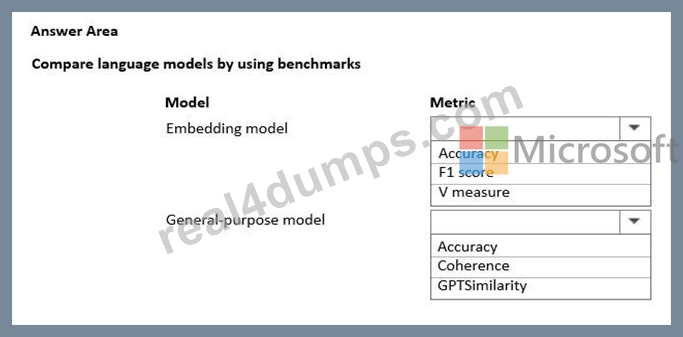
Answer:
Explanation: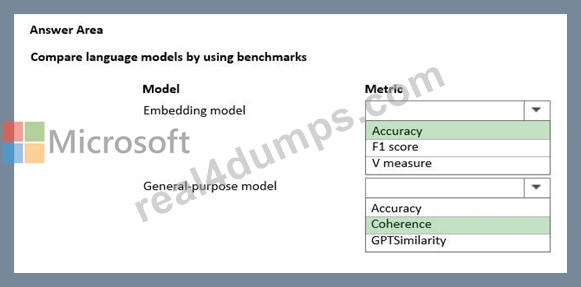
Explanation:
Box 1: Accuracy
Embedding model
An embedding model must help categorize the documents.
For an embedding model designed to categorize documents within Azure AI Foundry, cosine similarity is a crucial benchmark metric. It measures the semantic similarity between document embeddings, allowing you to assess how well the model groups related documents together.
Additionally, classification accuracy is important to evaluate how effectively the model assigns documents to predefined categories.
Classification Accuracy:
This metric measures the percentage of documents that are correctly categorized by the model. It directly reflects the model's ability to assign documents to the appropriate category based on their embeddings Box 2: Coherence General-purpose model A general-purpose model must generate semantically and contextually accurate output based on the documents.
Coherence evaluates how well the language model can produce output that flows smoothly, reads naturally, and resembles human-like language.
Incorrect:
* GPTsimilarity
GPT similarity refers to the ability of GPT models to assess and quantify the semantic similarity between pieces of text. This can be achieved by using the model to generate embeddings (numerical representations) of the text and then calculating the similarity (e.g., using cosine similarity) between these embeddings. Essentially, it allows you to determine how closely related two texts are in terms of their meaning.
Reference:
https://learn.microsoft.com/en-us/azure/ai-foundry/concepts/model-benchmarks
https://learn.microsoft.com/en-us/azure/machine-learning/prompt-flow/concept-model-monitoring-generative-ai-evaluation-metrics
NEW QUESTION # 106
During training, pipelines occasionally fail due to schema mismatch caused by upstream data changes. You need a robust and automated solution that prevents invalid data from reaching training steps. What is the BEST approach?
Answer: B
NEW QUESTION # 107
You create an Azure Machine Learning model to include model files and a scorning script. You must deploy the model. The deployment solution must meet the following requirements:
* Provide near real-time inferencing.
* Enable endpoint and deployment level cost estimates.
* Support logging to Azure Log Analytics.
You need to configure the deployment solution.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.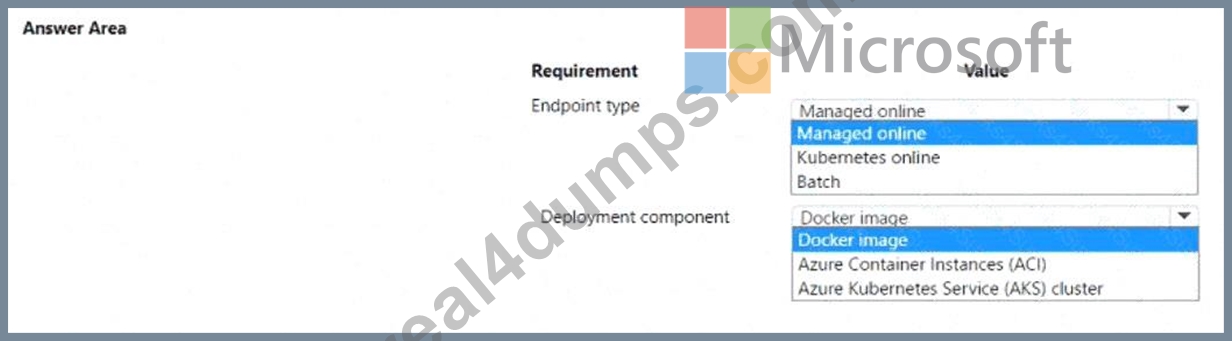
Answer:
Explanation: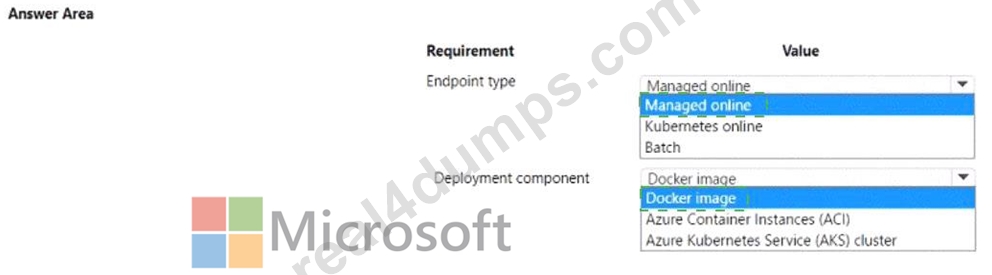
Explanation: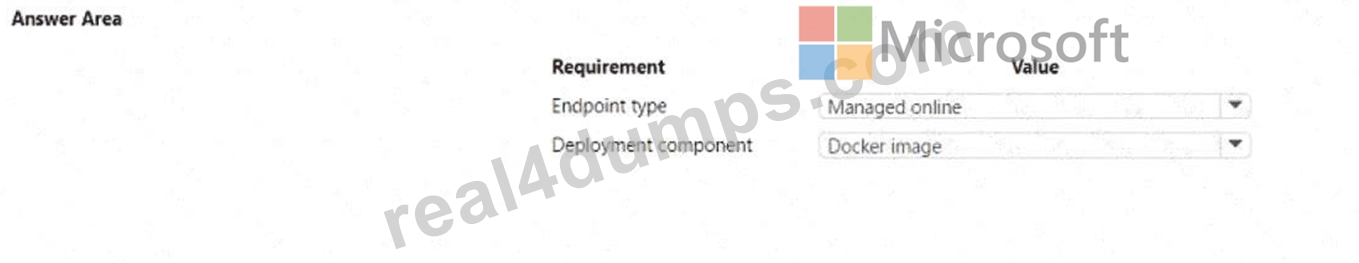
NEW QUESTION # 108
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
Hotspot Question
You need to configure an optimization method to meet Fabrikam Inc.'s technical requirements.
Which strategy should you apply first? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.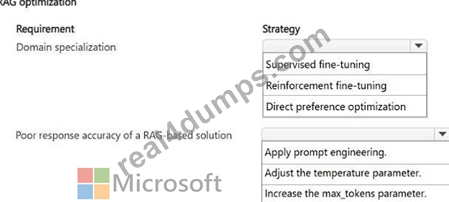
Answer:
Explanation: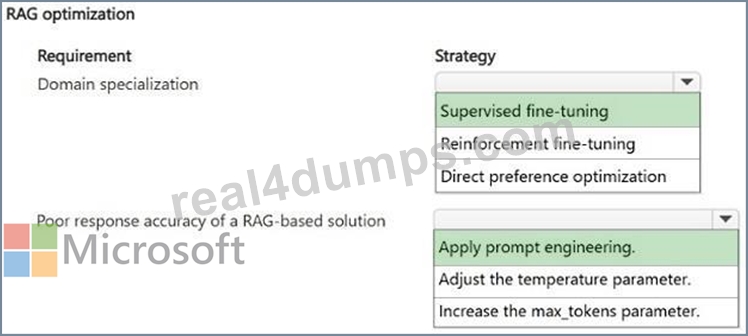
NEW QUESTION # 109
......
After taking a bird's eye view of applicants' issues, Real4dumps has decided to provide them with the Real AI-300 Questions. These Operationalizing Machine Learning and Generative AI Solutions (AI-300) dumps pdf is according to the new and updated syllabus so they can prepare for Microsoft certification anywhere, anytime, with ease. A team of professionals has made the product of Real4dumps after much hard work with their complete potential so the candidates can prepare for Microsoft practice test in a short time.
AI-300 Study Reference: https://www.real4dumps.com/AI-300_examcollection.html
P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by Real4dumps: https://drive.google.com/open?id=1diSSFovkBkr4h2jsHLLJj1sR6S7jNHML